Dynamics 365 and Power Platform Licensing Strategy: How Organizations Reduce Cloud Spend While Maintaining Governance

Microsoft’s cloud licensing model for Dynamics 365 and the Power Platform offers flexibility and scalability. It also offers considerable opportunity for waste. Most organizations discover this too late, after months of unexamined spending that could have been redirected to innovation or other priorities.

The core problem is straightforward: cloud platforms license by user capacity and feature tier, not by value delivered. A financial services firm might purchase user licenses for an entire department, only to find that 30 percent of users log in quarterly, if at all. An enterprise deploying Power Automate cloud flows for process automation realizes partway through implementation that unlimited flow runs are generating unexpected platform consumption spikes. A global manufacturing company manages Dynamics 365 Finance across multiple regional entities, each licensed independently, without a unified procurement strategy to drive volume discounts or identify redundant deployments.

These scenarios are not edge cases. They reflect the licensing blind spots that persist in organizations where cloud spending lacks a structured governance framework tied to business outcomes.

A disciplined approach to licensing strategy addresses three distinct challenges: procurement efficiency, deployment rationality, and ongoing cost governance. Each requires different tools and governance patterns.

Procurement Efficiency: Moving Beyond Per-Seat Thinking

Most organizations begin with a straightforward model: count the number of users who need access to a system, select an appropriate license tier, multiply, and budget accordingly. This approach treats licensing as a straightforward unit cost exercise. It misses critical opportunities.

First, understand your licensing levers. Dynamics 365 offers multiple user types with different cost profiles: Full Users (highest cost, full feature access), Limited Interaction Users (lower cost, designed for occasional system access), and Team Member licenses (lowest cost, focused on specific light-duty tasks like time entry or basic CRM). Similarly, Power Platform pricing reflects seat capacity, runtime API calls, and process mining usage. Every lever has a cost implication and a use-case justification.

The discipline begins with user profiling. Organizations that reduce their licensing costs most effectively start by mapping actual usage patterns against assigned licenses, not the other way around. A financial operations team discovers that 40 percent of assigned Finance users require quarterly access at most (for year-end close processes or one-time analyses). These are candidates for Limited Interaction or Team Member licenses rather than full seats. A sales organization deploying Dynamics 365 Customer Engagement realizes that 25 percent of their sales team are part-time contributors whose engagement is seasonal. Licensing them at full cost year-round is arithmetically wasteful.

This analysis must be data-driven. Extract login frequency, module usage, and feature consumption from your systems over a rolling 90-day period. Compare actual behavior to current licensing assignments. Document the gaps. A manufacturing company that conducted this exercise on a Dynamics 365 Finance deployment found that 60 of its 120 licensed users could be right-sized to lower tiers without compromising their job functions. The resulting annual savings exceeded 200,000 dollars. More importantly, future licensing decisions could be built on empirical data rather than assumptions.

Volume and term discounts follow from this foundation. Organizations with discipline in user alignment are in a strong position to negotiate volume commitments with their providers. A three-year commitment in exchange for tiered discounts on licensing volume is a common lever, provided your governance framework ensures you are not over-licensing to justify the commitment.

Deployment Rationality: Avoiding the Redundancy Trap

Licensing costs compound when organizations deploy overlapping instances of the same platform without unified governance.

Consider the multinational manufacturing example again. Each regional subsidiary operates its own Dynamics 365 Finance instance with independent licensing. No shared data architecture exists. No unified reporting sits above the instances. The result is six separate licensing bills, six separate maintenance teams, six versions of “the truth” when the CFO asks for consolidated results. The actual feature-richness and functionality footprint is similar across all six instances. The licensing cost, multiplied six times, is not.

A unified, federated licensing architecture addresses this. One primary Dynamics 365 Finance instance serves as the system of record for corporate consolidation, intercompany accounting, and group-wide analytics. Subsidiary instances operate for local operations, connected via robust API-layer integrations to the central instance, but licensed at lower tiers for regional operations only. Reporting and compliance roll up to the primary instance. Licensing cost drops when the subsidiary instances are right-sized for their actual workload rather than independently provisioned full-capability systems.

This rationality extends to platform choices. Organizations frequently deploy both Power Platform and third-party low-code tools side-by-side, each with its own licensing footprint and skill investment. A thoughtful governance question: which capabilities are you licensing twice, and which redundancy is genuinely necessary? A company that discovered it was paying for both a third-party RPA tool and Power Automate cloud flows, each processing overlapping process automation needs, consolidated on Power Automate and redirected the savings toward governance infrastructure and process mining analytics instead. The move was not cost-free in terms of implementation effort, but it eliminated wasteful dual-licensing and centralized process intelligence in one platform.

Ongoing Governance: The Measurement and Optimization Cycle

Initial cost reduction creates a baseline. Ongoing governance ensures that baseline does not drift.

Establish a quarterly licensing review cycle. This cycle includes three elements. First, measure actual consumption against budgeted capacity. Extract platform telemetry: login frequency by user, Power Automate flow execution volume, Power BI report refresh frequency, Power Pages traffic, and API call consumption. Document actual behavior. Compare to your licensing tier and user classification decisions. If flow execution volume has tripled, your unlimited flow licensing tier remains correct; if it has remained flat, you have no pressure to increase. If a specific user cohort’s login behavior has changed materially, reassess their license tier.

Second, review new user onboarding for alignment with your licensing strategy. It is easy for new hires to be licensed at the highest tier by default, with plans for right-sizing later. Later rarely comes. Implement a standard onboarding checklist that routes new users through your user profiling framework before a license is provisioned. Ask: What is the actual job function? What systems do they need access to? Which user tier supports that scope? Document the decision and the justification before provisioning.

Third, build cost accountability into your governance structure. Assign licensing cost ownership to a functional business owner—the Finance Director for Dynamics 365 Finance, the VP of Sales for Customer Engagement, the Chief Operating Officer for Power Platform process automation. Give them visibility into actual spend per system per tier, trends in user count and consumption, and the cost implications of new initiatives. Organizations that treat licensing cost as a shared responsibility, not a Procurement-only concern, consistently achieve lower spend over time because the cost trade-offs become visible to the people who can influence them.

Measuring Success: From Cost Reduction to Governance Maturity

Early cost reduction from right-sizing and consolidation often yields 15 to 25 percent savings. This is measurable and achievable within 90 days of a serious review. Ongoing governance prevents cost creep and captures incremental savings as your organization evolves.

The deeper win is governance maturity. Organizations that embed licensing discipline into their cloud governance frameworks build predictability and control into their technology spending. They can forecast cloud costs accurately, allocate budget to business units fairly, and make architecture decisions based on total cost of ownership rather than upfront licensing assumptions. They attract finance leadership buy-in to cloud initiatives because cloud is no longer a black-box spending category; it is a managed, rational, cost-accountable investment.

Dynamics 365 and the Power Platform are powerful tools. Their licensing flexibility is an asset and a liability. Organizations that treat licensing as a static decision point, made once at deployment, leave money on the table. Those that embed licensing into a broader governance framework—measuring actual usage, rationalizing deployments, and reviewing trends continuously—build sustainable cost discipline and position their technology investments as genuine business value drivers rather than necessary overhead.


#DynamicsLicensing #CloudCostOptimization #PowerPlatformGovernance #FinanceTransformation #EnterpriseCloudStrategy #CFODecisionMaking #MicrosoftCloudCosts

Data Loss Prevention Policy Implementation in the Microsoft Cloud: Balancing Security and Business Agility

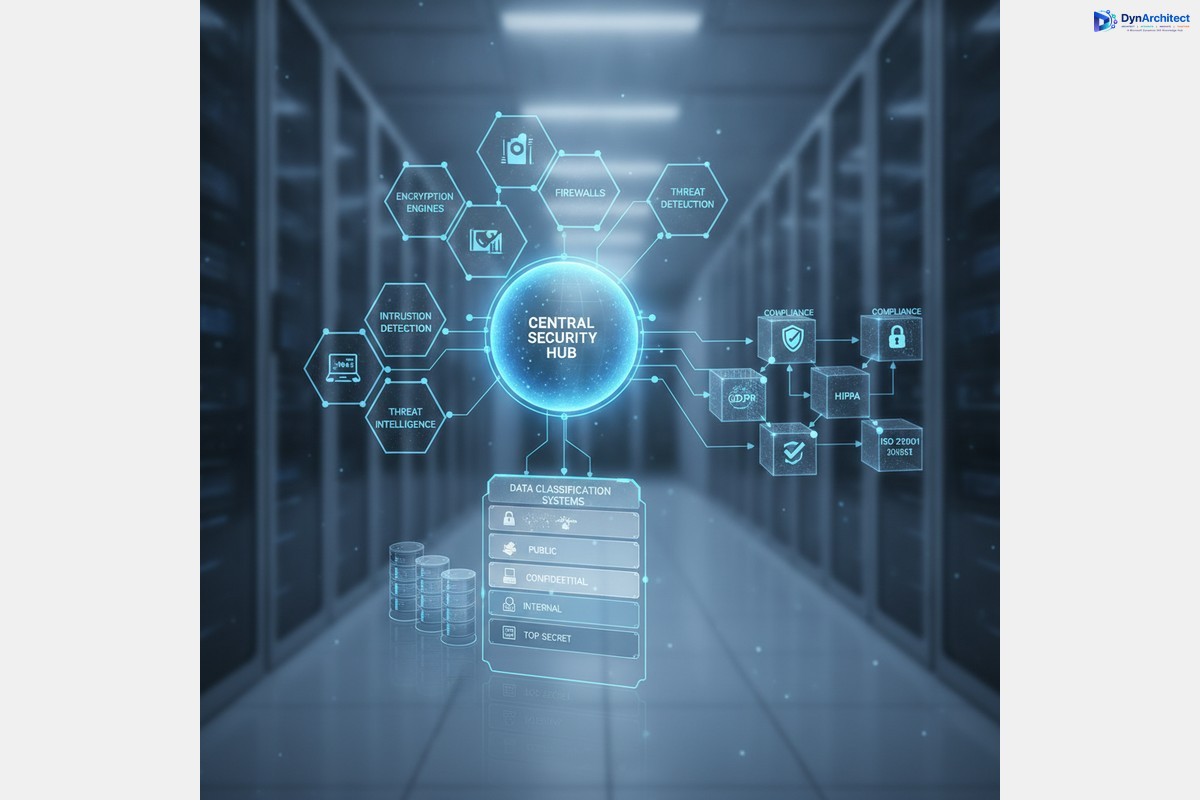
Enterprise data governance dashboard showing Data Loss Prevention policies and security classifications

Data Loss Prevention Policy Implementation in the Microsoft Cloud: Balancing Security and Business Agility

Most IT leaders inherit DLP implementations that operate as expensive friction generators—slow approval workflows, frustrated business units, widespread policy exceptions—rather than effective data protection. The challenge isn’t building DLP capability; it’s building DLP that actually works in practice without crippling business operations.

Dynamics 365, Power Platform, and the broader Microsoft cloud stack move data at volume and velocity that traditional perimeter security cannot monitor. Spreadsheets with customer data flow through Power Automate workflows. Finance teams share GL account details via Teams. Sales consultants upload competitor files to Power Apps. Without intentional DLP governance, sensitive information leaks become statistical inevitability. Yet overly rigid DLP policies drive shadow IT and workarounds that are far less controlled.

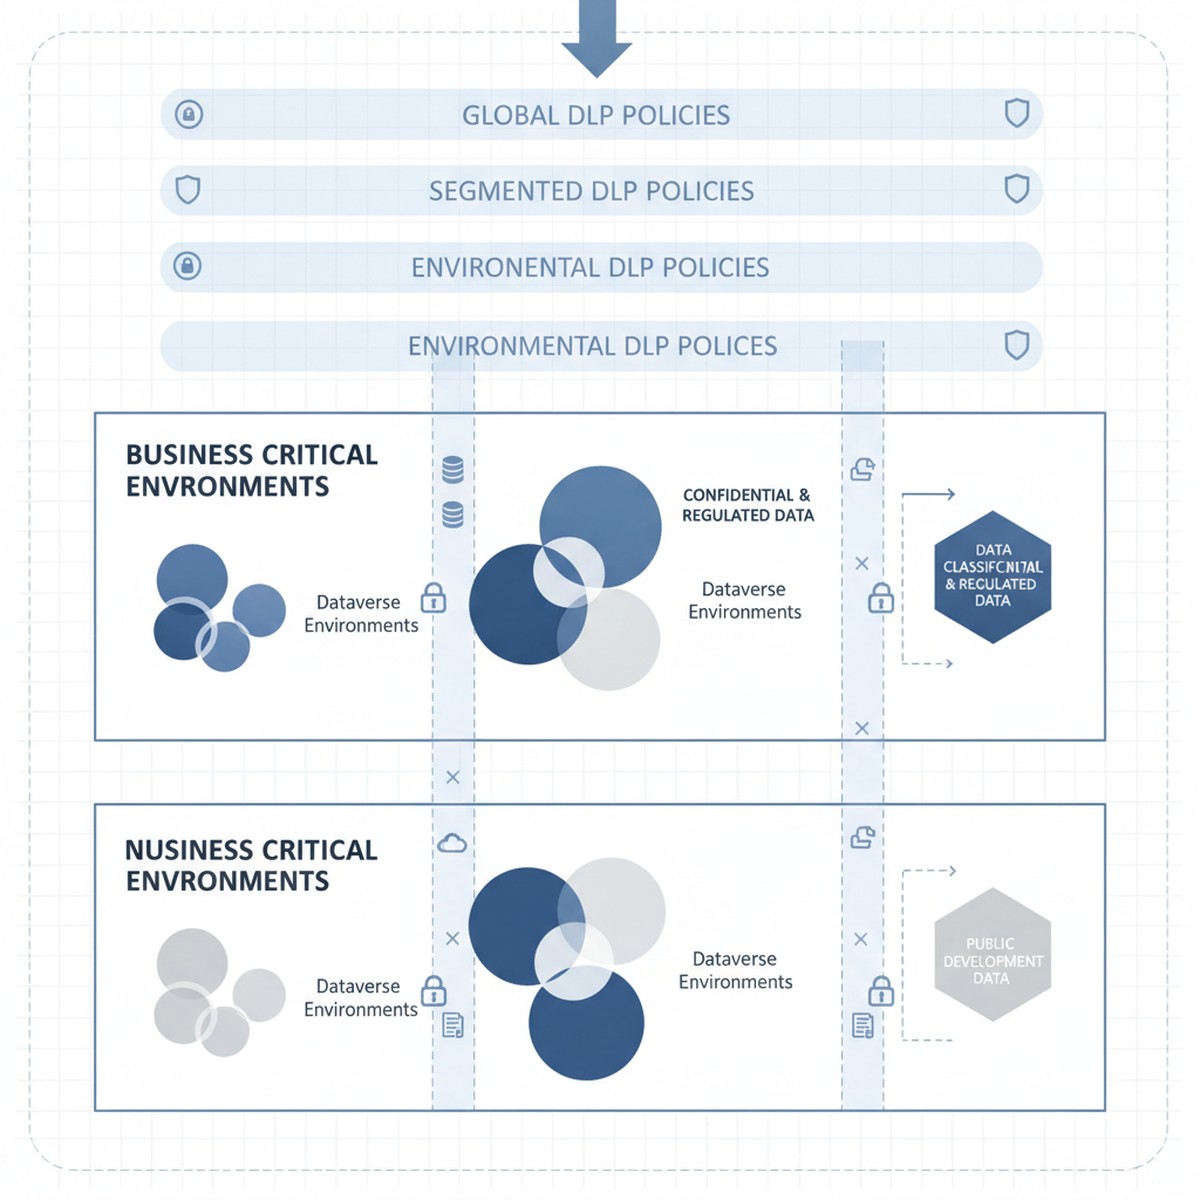
Microsoft cloud security architecture showing Dataverse environments with DLP policy layers and data classification zones

The tension is real: organizations need DLP policies that reduce breach risk and meet compliance requirements without triggering business user revolt. That balance comes from a three-layer approach starting with clear data classification, moving to segmented policy enforcement by workload, and ending with monitoring and exception workflows that catch real breaches without generating approval fatigue.

Understanding Microsoft Dataverse and Power Platform Data Classification

DLP in Microsoft Power Platform starts with a deceptively simple question: what data sensitivity level is stored in this Dataverse environment, and what external services should or should not have access to it?

Every Dataverse environment has an assigned DLP classification set by administrators. Out of the box, the options are “Business” (default), “Non-Business,” and “Unclassified,” each restricting which connectors can be used. An environment marked “Business” cannot call consumer-grade cloud services or public APIs by default. This classification system is the foundation of Power Platform DLP, and many organizations accept it unchanged. That is a mistake.

The actual tension surfaces immediately: a “Business” environment using default DLP classification prevents organizations from using essential connectors. A finance team might need to integrate Power Apps with Stripe for payment processing. A supply chain team needs logistics APIs to track shipments. A sales team needs to send customer records to third-party analytics services. These connectors fall outside default Business classification rules, but blocking them outright prevents legitimate business operations. Conversely, loosening policies to allow these services introduces real data exposure risk—customer payment details flowing to external processors without oversight.

Solving this tension requires abandoning the one-size-fits-all “Business” classification and instead segmenting Dataverse environments by actual data sensitivity and connector requirements. This segmentation becomes the policy framework that supports DLP without strangling innovation.

Segmenting Dataverse Environments by Sensitivity and Connector Requirement

Organizations that manage DLP effectively typically operate multiple Dataverse environments, each with a distinct DLP classification matched to the data sensitivity and connector requirements it actually holds.

Consider a typical enterprise structure: one environment holds Dynamics 365 Finance and Operations data (accounting records, GL accounts, intercompany transactions, supplier information). This is genuinely sensitive data subject to audit requirements and regulatory controls. This environment should be classified as “Business” under a restrictive DLP policy that prevents connectors to external consumer services, cloud file storage, or public APIs. Finance teams access this data through specifically designed Power Apps and Power Automate workflows within DLP constraints.

A second environment holds Power Apps and Power Automate flows that integrate Power Platform with external partner systems—logistics APIs, payment processors, analytics services, and public cloud connectors. This environment accepts connectors to these external services because data sensitivity and use case require it. However, no direct connection to the sensitive Finance and Operations environment is allowed. This environment operates under less restrictive DLP classification because data flowing through it is either lower sensitivity (customer feedback, survey responses, transaction history) or appropriately scoped to external partners.

A third environment is explicitly designated for proof-of-concept work and rapid prototyping. DLP is minimal here because solutions graduate to production environments with full governance only after validation and security review.

This segmentation approach solves the core tension: business users get connector freedom they need, but that freedom is appropriately scoped to environments holding data at the sensitivity level those connectors can safely access. A payment processor connector in the production environment holding Finance data would be irresponsible. The same connector in an e-commerce environment is reasonable.

Implementing Segmented DLP Without Over-provisioning

Segmentation only works when combined with clear governance over which data moves between environments and under what conditions. An organization running multiple Dataverse environments without data movement controls creates the worst outcome: complex DLP policies that block internal workflows and fail to prevent the very data exposure they were meant to restrict.

Governance begins with explicit data classification at the Dataverse table level. Every table in Finance and Operations environments should be tagged as “Highly Sensitive” (GL accounts, supplier data, payroll), “Internal” (historical transactions, internal metadata), or “Public” (product catalogs, customer-facing data). That classification becomes enforceable through data loss prevention rules: a table tagged “Highly Sensitive” cannot be queried by Power Automate flows in non-Business environments. This discipline prevents accidental sensitive data exposure through incorrectly scoped flows.

Second, organizations need exception workflows that actually work. Some business processes require sensitive data to flow to external systems. A customer requesting data export needs records to move outside the enterprise. A third-party audit requires financial table access. Building manual exception workflows—where business stakeholders request exceptions and security reviews them—turns DLP into a shared responsibility. Exception tracking also provides visibility into actual risk: organizations seeing hundreds of requests for sensitive data access learn something valuable about their risk profile.

Monitoring, Alerts, and Real-Time Response

DLP policy design matters, but enforcement and monitoring matter more. An organization with well-designed DLP policies but no monitoring ends up with policies that are either unenforced or inconsistently applied.

Microsoft Dataverse and Power Platform generate audit logs of DLP violations, but by default those logs are difficult to access in real time. Organizations that manage DLP effectively set up automated monitoring through Azure Monitor or Microsoft Sentinel, translating Dataverse audit logs into actionable alerts. A spike in violations from a specific user, a flow attempting repeated queries of sensitive tables, or patterns suggesting data exfiltration should generate alerts that security teams investigate within hours.

Real-time response capability is the difference between DLP as theoretical control and actual protection. When monitoring detects suspicious patterns, the ability to immediately disable Power Automate flows, revoke access to specific environments, or restrict Dataverse tables can interrupt a breach in progress. Without response capability, DLP monitoring is largely forensic—useful for understanding what happened after detection, not for preventing breaches.

Moving Forward: From DLP Compliance Theater to Actual Data Protection

DLP policy implementation is not a one-time project. Organizations that maintain effective data protection continuously adjust policies based on new business processes, security incidents that expose gaps, and platform evolution.

The organizations that manage this effectively treat DLP policy design as a shared responsibility across security, compliance, and business leadership. Policies are transparent—business stakeholders understand constraints and when exceptions can be requested. Exceptions are tracked regularly, signaling whether policies are appropriately calibrated. Monitoring is continuous and actionable, giving security teams real-time visibility into whether DLP policies actually protect data or just generate friction.

When these elements align, DLP stops being a security checkbox and becomes a capability that genuinely reduces sensitive data exposure risk without strangling business operations that depend on data movement and integration.

At Routeget Technologies, we have implemented data loss prevention governance across Dynamics 365 and Power Platform deployments in organizations ranging from mid-market to enterprise. Our approach begins with your current data sensitivity landscape and connector requirements, then builds segmented DLP policies and monitoring infrastructure that protect what matters most while enabling the business agility your teams need.

#DLPGovernance #DataLossPrevention #CloudSecurity #DynamicsCloudArchitecture #PowerPlatformGovernance #DataProtection #ComplianceAutomation #Dynamics365Security #MicrosoftDataverse #EnterpriseCloudGovernance

Dataverse Environment Strategy: Consolidation Versus Segregation

Dataverse consolidation vs segregation architecture comparison

When you first deploy Dataverse, the storage bill arrives as a small surprise. When you deploy your tenth instance, it arrives as a budget problem. This escalation is not accidental. It reflects a choice you likely did not consciously make: the decision to separate Dataverse environments.

Most organizations start with a single development environment, then add a staging environment for UAT, then a production environment for the main line of business. Six months later, there’s a second production environment for a parallel business unit. A year in, IT has provisioned separate Dataverse instances for finance, operations, customer service, and a pilot project that “just needed a sandbox space.” Each instance accrues storage costs, backup overhead, governance complexity, and security review burden. The organization paid for all of it. Few asked whether they needed to.

The question “Should we consolidate or segregate?” never came up because it felt obvious: production should be separate from development. But that clarity evaporates once you have multiple business units, overlapping data needs, and genuine compliance constraints. Consolidation looks cost-efficient until you calculate the management burden. Segregation looks secure until you realize your core customer data lives in four places and nobody knows which is authoritative.

The answer is neither pure consolidation nor pure segregation. It is strategy.

Understanding the Cost and Governance Tensions

Dataverse pricing ties directly to storage consumption and the number of instances you maintain. A 10 GB storage license costs roughly 100 USD per year. An organization with ten segregated Dataverse environments, even with light usage, pays backup, redundancy, and management overhead across each one. The cloud infrastructure beneath Dataverse (Azure) charges for compute, storage durability, and replication regardless of how full your instance is. A mostly empty Dataverse environment costs nearly as much as a full one.

Segregation creates what appears to be security clarity: production data stays in production, development in development, finance data in finance. This isolation has genuine value. A misconfigured Power Automate flow in a development sandbox cannot accidentally update live customer records. A security breach affecting one environment need not compromise all of them. But segregation imposes a hidden cost: data synchronization, duplicate records, inconsistent customer views, and reconciliation overhead. If customer records live in both a finance Dataverse and an operations Dataverse, which is the source of truth when they conflict? Who owns the resolution process?

Consolidation eliminates that duplication. A single Dataverse instance holding all enterprise data means one source of truth for customer records, one master file for products, one system of record for financial transactions. You skip the synchronization overhead, the reconciliation disputes, and the headache of knowing which Dataverse has the current information. The cost per record drops. But the security model becomes more complex. Consolidation means granting broader data access to more users and applications, requiring tighter role-based access control, field-level security rules, and auditing to prevent accidental or malicious data leakage. A single misconfigured permission model puts more data at risk than a segregated approach would.

Business team reviewing Dataverse environment strategy and cost metrics

When Segregation Makes Economic Sense

Segregation is the right strategy when regulatory compliance or data residency mandates isolation. A healthcare organization subject to HIPAA cannot store patient records alongside non-protected business data in the same system without additional access controls that approach the complexity of separate systems anyway. A financial services firm with customer data subject to SOX or PCI compliance, or an organization operating in multiple countries with GDPR or localization requirements, often finds segregation is mandated by policy rather than chosen for efficiency.

Segregation also makes sense when a subsidiary or business unit operates as a distinct legal entity with its own data ownership and governance. If your organization acquired a company and that company operates with its own finance department, separate Dataverse instances may be required during the integration phase and might remain appropriate long term to respect the subsidiary’s operational autonomy, even if they cost more.

Segregation further proves necessary when the organization lacks the governance maturity to enforce consistent security policies across shared data. If your Power Platform practice is young, permissioning discipline is inconsistent, and no one has ownership over a unified data governance framework, adding data to a consolidated Dataverse risks creating visibility into sensitive information that should remain restricted. In that case, segregation by business unit or application buys time for your governance practice to mature.

When Consolidation Reduces Total Cost of Ownership

Consolidation is strategically sound when you have multiple business units sharing core data, such as customers, products, and suppliers. The finance department’s customer master should be the same record your sales team references. The supply chain’s product master should be the source of truth for the pricing your finance team uses in invoicing. Consolidation eliminates the cost and risk of maintaining parallel records and reconciling discrepancies when they diverge.

Consolidation also makes sense when your organization has established governance discipline and a clear data stewardship model. If you have defined data ownership (finance owns the general ledger, supply chain owns inventory, sales owns opportunities), have role-based security groups mapped to those functional areas, and have audit mechanisms in place to catch permission violations, a consolidated Dataverse becomes a platform strength rather than a security risk. Your cost per record drops, your data consistency improves, and you simplify the user experience by giving people access to the unified information they need rather than requiring them to navigate to separate systems.

Consolidation further makes sense for organizations with mature ALM (application lifecycle management) practices. Consolidated Dataverse allows you to deploy solutions and flows to shared data layers without the release complexity of managing separate instances. Your development, staging, and production environments can all point to logically separated Dataverse spaces within a single instance, reducing provisioning overhead and backup complexity.

Hybrid Models and Environmental Separation Within a Single Instance

Many organizations land on a hybrid approach: one or two consolidated production Dataverse instances for the main business, with a separate development/test environment reserved for experimental solutions and non-production use.

This model recognizes that some segregation is necessary (development must be isolated from production), while consolidation of core business logic and shared data eliminates duplication and cost. Within a single Dataverse production instance, you use solution layers and environment variables to manage configuration differences for different business units or applications, avoiding the need for separate instances.

The Operational Complexity Multiplier

Many organizations underestimate the operational cost of managing multiple Dataverse instances. Each instance requires backup policies, disaster recovery testing, access control reviews, security patching coordination, and licensing reconciliation. Each instance needs monitoring for performance issues. Each introduces a potential point of data quality failure. If you have ten Dataverse environments with inconsistent master data definitions, ten different backup schedules, and ten separate access reviews, you have essentially maintained ten times the governance surface area compared to one consolidated instance.

Recommendations for Decision-Makers

Before you provision another Dataverse instance, ask whether the request stems from genuine compliance isolation or from organizational convenience. If it is convenience, consider whether investing in your governance model (clearer role definitions, field-level security policies, auditing) would be more cost-effective than the ongoing operational overhead of maintaining a separate instance.

If you already have multiple instances, analyze the actual data sharing patterns. Do core business entities (customers, products, suppliers) need to be synchronized across instances? If so, you are paying the cost of segregation while accepting the complexity of consolidation. A strategic consolidation project to merge those shared entities might cost less over three years than the recurring duplication and reconciliation overhead.

Document your environment strategy explicitly. Do not let instances accumulate by default. Routeget Technologies works with organizations to audit their existing Dataverse footprint, quantify the cost-benefit of consolidation versus continued segregation, and design transition plans that respect compliance constraints while reducing total cost of ownership. The difference between a well-planned environment architecture and an ad-hoc collection of instances often runs to hundreds of thousands of dollars annually for larger deployments.

Hashtags: #DataverseArchitecture #EnvironmentStrategy #PowerPlatformGovernance #EnterpriseDataManagement #DataverseCostOptimization #CloudGovernance #MicrosoftDataverse

Power Apps Business Alignment: When Custom Apps Get Built But Never Adopted

Your operations team just demoed a custom Power App to solve a recurring data-entry bottleneck. The app works technically. It’s deployed. Three months later, your finance team is still using the old spreadsheet-based process while the app sits idle.

This scenario repeats across hundreds of organizations building on the Power Platform. Power Apps makes it possible for business teams to build applications without professional developers, lowering the friction to create. But that low-friction building phase often masks a harder problem: getting the organization to actually use what gets built. The technology isn’t the constraint. The constraint is adoption, and most business decision-makers aren’t accounting for it when they greenlight Power Apps investments.

The challenge cuts both ways. CIOs and IT Directors approving Power Apps want to democratize application development and reduce dependency on professional development teams. Business leaders want faster solutions and quicker time-to-value. Power Apps delivers on those promises technically, but without clear ownership and user alignment from the start, projects that succeed in building often fail in landing.

The Two Adoption Failures Nobody Talks About

Most organizations that struggle with Power Apps adoption encounter one of two distinct failure modes, each rooted in different planning gaps.

The first failure is the misalignment project. A team builds a Power App to solve what they believe is a broadly understood problem, but the application’s workflows don’t match how the intended users actually work. A procurement team might design an approval-flow app optimized for the approval process as they understand it, but if field operators or managers submit requests in different ways depending on their context, the app creates extra friction instead of reducing it. The result: users abandon the app because working around it is faster than using it correctly. This isn’t a technical failure; the app functions as designed. It’s a design failure disguised as a user-adoption problem.

The second failure is the audience mismatch. A Power App gets built to serve a specific department or function, but the organization’s structure or priorities shift between when the project starts and when it launches. A regional operations app rolls out just as the company consolidates regions. A vendor-management app launches as procurement pivots to a new supplier strategy. The app was never designed for the new reality, and users inherit a tool that doesn’t match their actual needs. Again, adoption stalls because the tool doesn’t align with the current organizational context.

Both failures look the same from above: teams invest in building something, launch it, and watch adoption languish. But the root cause isn’t resistance to change or poor training; it’s a planning gap that existed before a single line of code was written. Business decision-makers sign off on Power Apps projects expecting fast iteration and rapid value, but many organizations treat the discovery and requirements phase as something to compress rather than something to do rigorously.

The Business Case for Upfront User Alignment

The power of Power Apps lies in its accessibility and speed of iteration. But that speed creates a hidden trap: it’s easy to start building without having actually nailed what you’re building or who will use it. Professional development teams can’t start building without requirements; users have to articulate what they need. Power Apps teams, by contrast, often start iterating with a looser sense of requirements, and the assumption is that feedback from users will shape the app as it grows.

That works if users are directly involved in the iteration cycle. It fails when the app is built inside a team and then handed to users for adoption without that collaborative refinement. The team that built it has ownership; the team that inherits it has skepticism.

The business decision-maker’s role is to enforce a prerequisite: before funding a Power App, clarify who will use it, how their day-to-day work will change, and whether those users are aligned on the change. This is not bureaucracy; this is preventing wasted investment.

Concretely, this means asking before the project starts:

Are the intended users aware this app is being built and involved in shaping it? If the answer is that an app is being built “for” a team rather than “with” a team, adoption risk is high. User involvement in requirements and design iteration is not optional; it’s a prerequisite for adoption.

Is the organizational context stable enough for this app to land? If the department is undergoing restructuring, if reporting lines are shifting, or if the function’s process is being redesigned separately from the app project, the app’s requirements are likely to change before it’s even finished. Aligning the app timeline with the organizational change timeline matters.

Does the app solve an actual pain point, or does it automate a process that’s working acceptably and just feels inefficient? The distinction matters for adoption. Users adopt apps that solve problems they feel acutely. They tolerate but don’t embrace apps that make acceptable processes slightly more efficient. If the value proposition is “this will save you a couple of hours per week,” adoption will be tepid. If it’s “this will eliminate a workflow that regularly delays your month-end close,” adoption will be stronger.

Are there informal workarounds or shadow IT systems already in place to solve this problem? If so, the app has to be meaningfully better than the existing solution, not just different. If a team has built a Access database that works for them, a Power App that does roughly the same thing won’t displace it just because it’s cloud-based or newer.

Governing Power Apps for Adoption, Not Just Speed

Business team collaborating on software design and user alignment

The shift from asking “Can we build this?” to “Will users actually use this?” requires a light governance layer that focuses on adoption rather than control. Most organizations approach Power Apps governance as a security and compliance exercise: which connectors are allowed, who can publish apps, what data can be accessed. Those questions matter, but they’re insufficient.

A business-focused governance approach adds a few adoption gates. Before a Power App is approved for organization-wide rollout or integration into critical processes, someone independent of the building team validates that users have been involved in design, that the app solves a felt pain point (not just an imagined one), and that the launch plan includes training and ongoing support. This sounds like bureaucracy, but done right it’s a 30-minute review conversation that prevents months of wasted effort from an app nobody will use.

The approver doesn’t need to be IT. An operations director, a functional manager, or someone from a Center of Excellence can conduct this review. The point is adding a voice that asks whether the app fits the users’ needs and context, not just whether the app is technically sound.

The Role of Ongoing Support in Sustaining Adoption

Building and launching an app is not the end of the adoption work; it’s the beginning. Yet many organizations treat the launch as a project end and shift resources away. A Power App that solves a pain point on day one needs to be refined as users work with it and discover edge cases. An app that isn’t updated or supported after launch will lose adoption as users encounter bugs, workarounds, or changes to the underlying process.

This isn’t an argument for endless feature building. It’s an argument for someone being accountable to users after the app is live: answering questions, capturing feedback, fixing bugs, and evolving the app as the business changes. If users submit a feature request and hear nothing for three months, they assume the app is abandoned and revert to the old way of working.

For business decision-makers, this means budgeting for post-launch support as part of the app investment, not as an afterthought. Whether that support comes from an in-house center of excellence, a dedicated team member, or a consulting partner, the accountability has to be clear.

A Realistic Path Forward

The organizations that succeed with Power Apps are not faster at building; they’re more deliberate about alignment before building and more committed to adoption after launch. They involve users from the start, validate that the app solves a real problem, ensure the organizational context is stable enough for the change, and commit resources to ongoing support.

This might feel like it slows down the promise of rapid low-code development. In a sense, it does. But it also prevents the false speed of building something nobody uses. A Power App that launches faster but is adopted by 30 percent of the intended users has a lower return on investment than an app that takes slightly longer to launch but is adopted by 80 percent of users.

Routeget Technologies has seen this pattern repeatedly across organizations building on the Power Platform: technical execution is almost never the constraint. Adoption is. We work with business leaders and IT teams to ensure Power Apps initiatives align users, stakeholders, and support structures before projects start, so the apps that get built are the apps that actually land.

The question is not whether your organization can build custom Power Apps. Modern platforms make that democratization real. The question is whether you can build apps that users will actually adopt. That requires thinking beyond the build and into the governance and support that follow.

—

#PowerAppsBusiness #UserAdoption #PowerPlatformGovernance #BusinessAlignment #CustomApplications #DigitalTransformation #OperationalExcellence

Preventing Unintended Blocks: Implementing Data Loss Prevention Policies Without Paralyzing Your Power Platform

Data Loss Prevention governance dashboard with security controls and policy checkpoints

Data Loss Prevention (DLP) policies in Power Platform sit at an uncomfortable intersection: they’re necessary for governance, but they’re easy to misconfigure so that your first draft breaks legitimate business workflows. Most organizations learn this the hard way, after a DLP policy ships and silently blocks connector calls in production automations. A finance team’s approval workflow mysteriously stops routing to Slack. A sales process can’t write leads to an external data warehouse. Nobody notices until something breaks on a Tuesday afternoon.

The challenge is structural. DLP policies operate at the connector level, not at the individual action level, so a single overly restrictive rule can disable entire classes of integrations across your tenant. The organizations that avoid catastrophic blocks are not the ones that build the most restrictive policies first. They’re the ones that start with a clear map of what data actually needs protection, then craft policies targeting that specific risk rather than trying to lock down anything that looks suspicious.


Understanding DLP in Practice

A Data Loss Prevention policy defines which connectors can share data with each other. You classify connectors as Restricted Data (like SQL Server, Dataverse, SharePoint), Limited Business Use (like Slack, Teams), or General. The policy enforces rules like “data from Restricted connectors cannot flow to Limited Business Use connectors.”

The critical point most organizations miss: these classifications are tenant-wide and apply to all environments unless you create specific overrides. A policy blocking Slack from receiving SQL Server data blocks it everywhere, for everyone. That sounds straightforward on paper, but most organizations have at least a dozen legitimate integrations that move data between categories that look “risky” in isolation. A financial reporting automation sending a Slack summary of daily sales. A customer service workflow pulling account data from Dataverse to an external ticketing system. A sales tool reading opportunities from Dynamics 365 for pipeline visibility.

None of these are data leaks. All would be blocked by an overly broad DLP policy.


Common DLP Mistakes

The first mistake is auditing too aggressively. Many organizations activate DLP in Audit mode to collect data on actual usage patterns without blocking anything. The theory is sound. The practice is crushing volumes of alerts, most false positives or unavoidable business integrations. Teams see 10,000 violations in a month with no systematic way to separate real concerns from critical workflows. They either give up on enforcement or ship a policy based on highest-volume alerts, which usually fails.

The second mistake is confusing audit alerts with actual risks. Not every data flow represents a security problem. A sales team’s external deal tracker is not a breach waiting to happen just because it reads from Dataverse. An approval workflow sending Teams notifications is not exposing proprietary information just because Teams is classified as Limited Business Use. Organizations conflate appearance of complexity with presence of risk, then tighten policies to zero out complexity. This transfers risk to shadow IT. People still move the data they need. If official integrations are blocked, they’ll build their own via Excel and manual uploads.

The third mistake is shipping policies without environment-level testing. DLP policies are tenant-scoped by default, so a broad policy breaks production systems across business units before validation in staging. The correct pattern is testing in specific environments, monitoring real workflow impact, then rolling out to the entire tenant. Executives want company-wide governance immediately, but breaking multiple workflows costs more than a phased rollout.


Building a Working DLP Policy

Enterprise security infrastructure showing data governance and compliance controls

Start with an actual inventory of your integrations, not a theoretical one. Go through your most business-critical Power Automate flows (approval automations, financial data movements, sales processes) and document which connectors they use and what data moves between them. Don’t ask business owners what they think is critical. Inspect the flows. You’ll find integrations that look risky but are actually essential. A manufacturing team’s work order system pulling from Dataverse and posting to an external MES system. A finance team’s journal import flow reading CSV from a web service and loading into Dynamics 365. These would fail under restrictive DLP, and stakeholders will fight when they break.

Second, classify connectors based on actual data sensitivity, not theoretical risk. Dataverse and SQL Server carry genuinely sensitive data and warrant strong controls. SharePoint carries mixed content and needs nuance. Slack and Teams are low-sensitivity by themselves but become sensitive only when receiving restricted data. The mistake is classifying Slack as Limited Business Use, then treating any flow from SQL Server to Slack as violation. That blocks the finance team’s daily sales summary, sales team’s pipeline snapshot, and customer service team’s alert automation. These aren’t leaks, they’re operations.

A better approach is classifying Slack as General for normal use, then building specific policy exceptions for flows that legitimately move summarized data from restricted systems. This requires identifying those flows in advance.

Third, build your initial policy at the environment level, not tenant-wide. Create a restrictive policy for sandbox and development environments. Test your business-critical flows in staging with your proposed tenant-level DLP policy before shipping. You will find your policy breaks something unexpected. Refine the policy, create flow-specific exceptions, or move that flow to a dedicated environment with looser rules. All beat discovering your policy broke production automations.

Fourth, document every policy exception and why. When carving out exceptions for flows moving data between connector categories, write down the business reason, data classification, and approval stakeholder. This prevents exceptions from becoming a free-for-all over time. Each exception should have a clear owner and documented security rationale. Quarterly audits will make sense of your policy instead of inheriting blackbox carve-outs.


Monitoring and Maintenance

Finally, review your DLP policy every quarter. Power Platform gets new connectors regularly. Integration patterns change as teams adopt new tools. A policy from Q1 might be outdated by Q3. Quarterly review catches new patterns, adjusts classifications as you learn more about actual data flow, and retires unnecessary exceptions. Organizations that ship a policy and never touch it end up either too restrictive (silently blocking workflows) or too permissive (defeating the point).

Set up Power BI reporting against Power Platform audit logs. Create dashboards showing DLP violations over time by connector pair, environment, and flow. Most organizations find 80 percent of violations come from a handful of flows or connector combinations. For each, decide: Is this legitimate and needs exception? Is it shadow IT to replace? Or is it misconfigured? Document the decision.

Engage with solution architects and flow owners before violations happen. After quarterly reviews, share audit logs with teams owning business-critical integrations. This conversation prevents surprises and keeps teams aligned rather than feeling DLP is something done to them.


DLP policies are not set-and-forget security controls. They’re part of ongoing governance between your security team, platform team, and business stakeholders. Organizations implementing DLP successfully are not enforcing maximum-security policies. They start with a clear picture of what they’re protecting, build policies addressing that specific risk, and refine them as their integration landscape evolves. That approach is slower than dropping maximum-security on the entire tenant, but it’s the only approach that works in organizations where Power Platform ties directly to business operations.


#PowerPlatformGovernance #DataLossPrevention #DLPPolicy #PowerAutomateIntegration #MicrosoftCloudSecurity #EnterpriseGovernance

The Power Apps Per-App Plan Is Retiring. It’s Forcing Overdue Power Platform License Optimization.

IT director and finance director reviewing a Power Platform license usage dashboard on a large office monitor

An IT director at a distribution company got her Power Platform renewal quote back in August and the per-app line item had a note attached: new purchases under that SKU were no longer available through her Enterprise Agreement’s normal channel. She had eleven apps running on per-app capacity packs, covering everything from a driver check-in tool to a rebate approval workflow, and nobody on her team had ever audited whether those apps still needed dedicated capacity or whether half their users had moved to other roles. The renewal conversation, which was supposed to be a formality, turned into a scramble to figure out what she was actually paying for, and into the kind of overdue Power Platform license optimization exercise most IT organizations keep putting off until a contract forces it.

IT director and finance director reviewing a Power Platform license usage dashboard on a large office monitor

That scramble is becoming common. Microsoft ended new sales of the Power Apps per-app plan on January 2, 2026, and the way that retirement plays out depends entirely on which purchasing channel an organization uses: Enterprise Agreement customers can keep renewing and adjusting counts through their normal true-up process, MPSA customers lose access to the SKU when their current agreement expires and get sixty days to move to something else, and CSP customers were largely unaffected, with the plan returning to availability there in early April. Three different outcomes for the same retirement, depending on how procurement happens to be structured, is exactly the kind of detail that gets missed until a renewal quote forces the question.

The timing matters because it coincides with something genuinely useful: Microsoft has finally shipped a way to see what a Power Platform license estate is actually being used for, instead of relying on procurement records and institutional memory. Getting that visibility in place before the next renewal cycle is the difference between a defensible Power Platform license optimization decision and another round of guessing.

Why Power Platform License Optimization Has Been Mostly Guesswork

Until recently, an organization trying to right-size Power Apps and Power Automate licensing had to stitch together the answer from several disconnected places: the Microsoft 365 admin center for what was purchased and assigned, PowerShell exports like Get-AdminPowerAppLicenses for a point-in-time snapshot, and whatever the CSP or EA reseller could pull from their own systems. None of those sources actually answered the question a CFO cares about, which is how many of the licenses being paid for are being used by someone doing real work in a given month.

The license consumption experience now available (in preview) inside the Power Platform admin center closes that gap. Under Licensing, administrators can pull up Power Apps and see, side by side, per-user licenses purchased against per-user licenses actually consumed by someone who launched an app in the last 90 days, per-app licenses allocated to environments against what was purchased, and any pay-as-you-go billing plans linked in the same view. It breaks down by environment as well as organization-wide, and it will export a CSV of active users, their last app launch, and which license type they used to get in. For an IT director trying to answer “do we actually need eleven per-app packs,” that is the first time the honest answer has been sitting in one screen rather than scattered across three systems and a spreadsheet someone built two years ago.

There is a companion version of this reporting for Dynamics 365 Finance and Operations environments connected through the Power Platform admin center, and it is worth calling out separately because F&O licensing carries its own compliance exposure that per-app and per-user Power Apps licensing does not. That report maps security roles to license requirements and flags users who are under-licensed for the roles they hold, over-licensed relative to what they actually use, or missing a license entirely despite having role access. For a finance organization worried about a true-up or compliance review turning up unlicensed F&O access, that role-to-license breakdown is arguably more valuable than the Power Apps consumption view, because F&O license gaps carry direct compliance risk rather than just wasted spend.

Two enterprise IT professionals reviewing a printed license usage report and laptop dashboard during a renewal discussion

What This Changes About the Renewal Conversation

None of this reporting makes the decision automatically. It gives a CIO or CFO the input needed to make a real one, and there are three moves worth having on the table before the next renewal.

The first is treating the per-app retirement as a forcing function to re-evaluate whether per-app capacity was ever the right model for those specific apps in the first place, rather than assuming the goal is simply to find a like-for-like replacement. An app used constantly by a stable group of forty employees usually still makes sense on a capacity or per-user model. An app used sporadically by three hundred people across the organization, the kind of low-frequency, wide-distribution use case Microsoft explicitly points pay-as-you-go at, is often cheaper and administratively simpler on a consumption model tied to an Azure subscription, where there is no license procurement cycle at all and the organization pays only for sessions that actually happen.

The second is using the consumption report before, not after, the renewal negotiation. A vendor conversation about right-sizing an estate is a different conversation when the buyer walks in with an export showing which per-app allocations have had zero active users in the trailing ninety days versus one built on assumptions. That data also gives Finance a defensible basis for the true-up number instead of an estimate carried forward from the prior year.

The third is recognizing that pay-as-you-go billing plans allow granular cost allocation that traditional licensing does not. Because a billing plan links specific environments to an Azure subscription, and because Azure’s own cost management and resource tagging can then split charges by team or department, an organization running Power Platform across multiple business units can get a real chargeback model instead of a Power Platform budget line that IT absorbs and never breaks down by consumer. That is a meaningfully different conversation for a CFO than “the Power Platform bill went up again this year.”

What to Do Before the Next Renewal

For an organization anywhere in the Power Platform per-app transition, the practical sequence is straightforward even if the underlying decisions are not. Pull the license consumption report for Power Apps and, if applicable, the F&O consumption report, before assuming a renewal quote reflects actual need. Segment the app portfolio by usage pattern rather than by however licenses happen to be allocated today, since a capacity pack purchased three years ago for a pilot may now be covering an app that either died quietly or scaled to a very different usage profile. Confirm which purchasing channel governs the organization’s contracts, since an EA customer facing no disruption and an MPSA customer facing a sixty-day migration window are working against very different timelines, and the MPSA customer in particular should not wait for the renewal notice to start that conversation. And treat pay-as-you-go as a genuine option for the specific subset of apps that fit its profile, rather than a fallback only considered after per-user and per-app options are exhausted.

None of this requires a platform migration or a change to how the apps themselves work. It requires pulling data that, for the first time, is actually sitting in one place, and using it to make a licensing decision on facts rather than habit. Organizations that have gone through a Power Platform license optimization exercise with us tend to find the same thing: the spend was rarely wildly wrong, but it was almost never right, and the gap between those two states is usually worth the afternoon it takes to run the report.


Routeget Technologies works with IT and finance teams on Power Platform governance and licensing reviews as part of broader Dynamics 365 and Power Platform engagements.


#PowerPlatformLicensing #LicenseOptimization #PowerAppsPerApp #PayAsYouGo #PowerPlatformGovernance #ITCostGovernance

Power Automate API Request Limits Are Losing Their Grace Period. Most Dynamics 365 Integrations Aren’t Ready.

IT solutions architect reviewing a Power Automate integration flow dashboard on a large screen in an enterprise operations center

A finance operations lead watching a month-end close dashboard notices something odd: a batch of vendor invoices has been sitting in “waiting” status for eleven minutes. No error message, no failed run in the flow history, just silence. The Power Automate flow pulling records from Dataverse and pushing them into a document management system hasn’t crashed. It has been throttled, and almost nobody on the team knows that’s a distinct condition from a broken flow, let alone what triggers it or how long it lasts.

That gap in understanding is about to matter a lot more. Microsoft has spent the better part of the last two years quietly running Power Automate’s API request limits in what it calls a transition period: real entitlements exist on paper, actual enforcement is loose, and most tenants are running well past their official limits without consequence. That period has a stated end point, tied to when Power Platform Request usage reporting in the admin center reaches general availability, plus roughly six months. Teams that built integration flows assuming today’s permissive behavior is permanent are going to have an uncomfortable conversation with their CIO when enforcement tightens.

What Actually Counts Against Your Limit

The mental model most consultants carry around, that a “request” means one API call your flow makes to an external system, undersells how quickly limits get consumed. Every action in a flow run generates a request, whether it succeeds or fails. An action sitting inside an Apply to Each loop generates one request per item processed, not one request for the loop as a whole. Pagination counts separately too, so a flow that queries a Dataverse table with 50,000 rows and pages through results in batches of 5,000 will burn ten requests just retrieving data it hasn’t done anything with yet.

This is where a lot of Dynamics 365 integration flows get into trouble without anyone noticing during development. A flow built and tested against a sandbox environment with a few hundred sales order records behaves completely differently once it hits production volume. The loop that ran fine at fifty iterations in UAT becomes five thousand iterations against the live sales order table, and each of those iterations might trigger two or three downstream actions: a lookup, a field update, a notification. What looked like a lightweight automation in testing turns into a five-figure daily request count in production.

Developer typing on a laptop with a blurred Power Automate cloud flow diagram visible on a monitor in the background

The Power Automate API Request Limits That Actually Matter

Most teams that have heard of Power Automate throttling think of it as a single ceiling. In practice there are three separate mechanisms stacked on top of each other, and hitting any one of them produces the same frustrating symptom: a flow that stops making forward progress without a clear error.

The first is the 24-hour rolling entitlement, calculated per user for licensed accounts and pooled at the tenant level for application users and service accounts. A user with a standard Power Automate per-user or Dynamics 365 base license carries a 40,000 request allowance in any trailing 24-hour window. That window doesn’t reset at midnight. It slides continuously, so a burst of activity at 9 a.m. today is still being counted against the limit at 9 a.m. tomorrow, and any requests left unused simply expire rather than carrying forward.

The second is a five-minute burst cap of 100,000 requests, which applies independently of how much daily entitlement remains. A flow with a per-flow Process license carrying 250,000 requests per day can still get throttled mid-run if it tries to push too many of those requests through in a short burst, which is exactly what happens when an integration flow processes a large batch without pacing itself.

The third, and the one with the sharpest teeth, is continuous throttling over time. A flow that stays in a throttled state for 14 consecutive days gets turned off automatically. It can be reactivated, but if the underlying request pattern hasn’t changed, it cycles back into the same state. For a scheduled integration that runs nightly, two weeks of silent throttling is enough time for a genuinely broken process to look, from the outside, like nothing more than a slow week.

Architecting Integrations to Survive Enforcement

None of this means Power Automate is a poor choice for high-volume Dynamics 365 integration work. It means the flows need to be built with request budgets in mind from the start rather than retrofitted after a production incident.

Batching is the highest-leverage change available to most teams. Dataverse supports native batch operations that bundle multiple create, update, or delete operations into a single request rather than issuing one request per record. A flow rewritten to batch 100 record updates into a handful of batch calls instead of 100 individual actions can cut its request footprint by well over ninety percent for that segment of the process. This is worth doing even on flows that aren’t currently near any limit, because the same restructuring also improves run time and reduces the blast radius of a partial failure.

Child flows deserve more architectural attention than they usually get. Breaking a single monolithic flow into a parent that orchestrates and several children that each handle a bounded chunk of work makes it possible to apply concurrency control and pacing at a granular level, rather than trying to throttle an entire end-to-end process as one unit. Concurrency control settings on the trigger, often left at their defaults, are one of the more overlooked levers here: capping how many instances of a flow can run in parallel directly controls how fast it can burn through the five-minute burst allowance.

Trigger conditions matter more than most teams treat them. A flow that fires on every Dataverse row update and then checks conditions inside the flow body has already consumed a trigger execution and started accumulating requests before it decides the record doesn’t actually need processing. Moving that filtering logic into the trigger condition itself, evaluated before the flow run even starts, is free request savings that costs nothing to implement.

For flows that are genuinely high-volume by design, such as a real-time integration syncing order status between D365 Finance and Operations and an external logistics platform, the right answer may simply be licensing rather than architecture. A per-flow Process license carries a 250,000 request daily allowance on its own, and multiple Process licenses can be stacked on a single flow inside a solution, each one adding another 250,000 to that flow’s dedicated entitlement. For tenants not ready to change licensing, the Power Platform Request Capacity add-on adds 50,000 requests per 24 hours per pack and can be layered onto existing entitlements as a stopgap.

Get Ahead of the Reporting Gap

The Power Platform admin center’s usage reports are still catching up to the complexity of the limits themselves. Current reporting covers Power Automate API requests reasonably well but doesn’t yet give a clean picture of Dataverse, Copilot Studio, or Power Apps consumption in the same view, which means a team relying solely on the admin center dashboard is working from an incomplete picture of its actual request footprint. Until that reporting matures, the more reliable approach is instrumenting flows directly: logging request counts per run, watching for 429 responses in run history, and treating a spike in run duration as an early warning sign rather than waiting for a flow to get switched off.

Organizations we’ve worked with on Dynamics 365 and Power Platform integration architecture are increasingly building request budgeting into the design review for any flow expected to process more than a few thousand records a day, the same way they’d review a database query plan before it goes to production. That habit is worth adopting now, while the transition period still offers room to fix a poorly architected flow before enforcement makes the fix urgent instead of optional.


#PowerAutomate #APIRequestLimits #DynamicsIntegration #PowerPlatformGovernance #IntegrationArchitecture #EnterpriseAutomation

The CoE Starter Kit Is Dead. Agentic Center of Enablement Isn’t the Full Replacement Yet.

IT governance director reviewing a Power Platform admin governance dashboard on a large office monitor

If your organization still runs the Power Platform Center of Excellence Starter Kit, you already know something changed this year. The monthly release cadence that used to ship new Power BI dashboards, governance flows, and inventory jobs went quiet in February. By May, Microsoft made it official: the kit is “no longer receiving ongoing feature investments or updates.” For a lot of IT Directors and Power Platform CoE leads, that left a real question sitting on the desk. The DIY governance stack your team spent two or three years building and patching now has no vendor behind it, and the natural next move, moving everything into the Power Platform admin center, only gets you partway there.

That gap just got a little smaller. In September 2026, Microsoft opened public preview on the Agentic Center of Enablement, a set of three AI agents built directly into the admin center that are meant to take over a chunk of what the CoE Starter Kit used to do by hand. It is a meaningful step. It is not, on its own, a like-for-like replacement, and understanding exactly where the line falls matters more than the headline announcement.

What Actually Happened to the CoE Starter Kit

The timeline is worth stating plainly, because a lot of the commentary around this has blurred it. Development on the CoE Starter Kit effectively stopped in February 2026. Microsoft’s public confirmation followed in the spring, framed not as an abandonment but as a redirection of engineering effort: governance capability was moving from a community-maintained accelerator into the product itself. That framing turned out to be accurate, just slower to materialize than the announcement implied. Between May and September, organizations that depended on the kit for environment inventory, maker identification, and license reclamation were largely left running an unsupported toolset with no clear native equivalent for several of its core jobs. The admin center had usage and licensing dashboards, but not the ownership tracking, lifecycle states, or cross-tenant rollups that a mature CoE program actually runs on day to day.

That is the backdrop the Agentic Center of Enablement is stepping into, and it explains why the reaction from practitioners has been cautiously interested rather than celebratory.

IT governance director reviewing a Power Platform admin governance dashboard on a large office monitor

Agentic Center of Enablement: Three Agents, One Governance Loop

The Agentic Center of Enablement is not a dashboard you configure. It is three purpose-built agents that run continuously against your tenant, and each one does a distinct job in what Microsoft is positioning as a closed governance loop.

The Highlights agent produces a daily snapshot of tenant activity with no setup required: new resource creation, capacity consumption shifts, and other changes an admin would otherwise have to go looking for. The Insights agent is the one doing the heavier analytical work. It scans the tenant continuously and surfaces governance issues, ownerless resources, activity happening in the default environment, and security, compliance, performance, and adoption problems, then ranks them by impact so an admin isn’t left triaging a flat list. The Action Plan agent takes whatever the Insights agent surfaces and turns it into a concrete remediation plan with defined steps, which an admin reviews and approves before anything actually executes. Every action any of the three agents takes is logged in a full audit trail, which matters for organizations that need to show a paper trail to internal audit or a regulator.

Access is straightforward by design. It requires at least one managed environment in the tenant and the Power Platform administrator role, and it activates automatically rather than needing a deployment project the way the old kit did. For a CIO comparing total cost of ownership, that alone is worth noting: there is no solution to import, no Power Automate flows to maintain, no Dataverse tables to keep patched against breaking API changes.

Solution architect typing at a keyboard with dual monitors showing governance and application inventory analytics

Picture the scenario the Insights agent is actually built for. A regional sales team spins up a canvas app in the default environment to solve an immediate problem, the maker moves teams six months later, and the app keeps running with nobody watching its connector permissions or its data exposure. Under the old model, that app surfaces only if someone happened to run the right CoE Starter Kit inventory flow and then manually reviewed the output. Under the new model, the Insights agent flags it as default-environment activity with an ownerless resource attached, ranks it against everything else it found that day, and the Action Plan agent proposes reassigning ownership or migrating it into a governed environment before anyone has to go looking. That is a genuine reduction in the manual triage work a CoE analyst used to own.

Where the Gap Still Sits

Here is where the caution comes in. Reviews of the preview from consultants who ran real CoE programs on the Starter Kit have flagged the same handful of missing pieces, and they are not minor ones. The admin center, even with the new agents layered on top, still does not give you shadow IT detection in the sense the kit’s telemetry did, since it inventories what exists inside the platform rather than surfacing unsanctioned use happening around its edges. Lifecycle management, the process of formally retiring an app or flow, reassigning ownership when someone leaves the company, or tracking an asset through draft, active, and deprecated states, is not something the Insights and Action Plan agents currently model. Cross-tenant visibility, relevant to any organization running multiple tenants after an acquisition or a regional split, also is not part of what shipped in September’s preview. And the business context that made the old kit useful to non-technical stakeholders, tagging an app as customer-facing, financially regulated, or tied to a specific business unit, still has to be built and maintained separately, because the agents currently work from platform telemetry rather than organizational metadata.

None of that makes the Agentic Center of Enablement a disappointment. It genuinely automates the parts of governance that used to eat the most analyst hours: finding orphaned resources, flagging default-environment sprawl, and building a first-draft remediation plan instead of starting from a blank spreadsheet. It just is not yet the full replacement that some of the messaging around the CoE Starter Kit’s retirement implied it would be.

What This Means for Your Governance Roadmap

For an organization still weighing what to do with its Starter Kit investment, the practical move right now is not to rip anything out. The kit’s dashboards and flows will keep functioning even without updates, and the specific gaps described above, ownership workflows, lifecycle tracking, cross-tenant reporting, are exactly the pieces worth keeping running in parallel while the native agents mature. Treat the preview period as a chance to pilot the Insights and Action Plan agents in a single managed environment, compare their findings against what your existing telemetry already tells you, and use the overlap to decide which manual processes can retire first. Ownerless resource detection and default-environment cleanup are reasonable early candidates, since those are exactly the categories the Insights agent targets today.

A workable sequence looks like this. Start by enabling the agents in whichever managed environment already has the most mature governance discipline, since that gives you a clean baseline to compare against rather than a noisy one. Spend two or three weeks letting the Highlights and Insights agents run before acting on anything, so you get a real read on how their findings line up with what your team already knew versus what genuinely surprises them. Then hand a small batch of the Action Plan agent’s proposed remediations to whoever currently owns that work by hand, and measure the time saved rather than assuming it. Only after that comparison holds up across a full reporting cycle does it make sense to talk about retiring pieces of the Starter Kit stack rather than just running both in parallel.

It is also worth flagging this to whoever owns license and compliance risk in your organization, since the daily snapshot and continuous scanning behavior changes what “governance coverage” means for audit purposes, even during preview. A feature that is not yet generally available can still become the thing an auditor asks about six months from now.

We have walked several clients through exactly this kind of platform transition at Routeget Technologies, and the pattern holds regardless of which specific tool Microsoft is retiring or introducing: the risk isn’t in adopting the new capability too early, it’s in assuming a preview feature already covers ground it hasn’t gotten to yet. Run the pilot, keep the documentation for what the old system covered that the new one doesn’t, and revisit the gap list when general availability lands, since that is typically when Microsoft fills in the pieces a preview release leaves out.


#AgenticGovernance #CoEStarterKit #PowerPlatformGovernance #ShadowITRisk #EnterpriseAI #LowCodeGovernance

Dataverse’s Recycle Bin Restore Reached GA. Your Business Logic Isn’t Included.

Solution architect reviewing a data recovery and system administration dashboard on a large monitor in a modern office

A bulk delete job runs at 2 a.m. against the wrong view filter. By the time anyone in operations notices, eleven thousand account records are gone, and the only recovery plan anyone can point to is a nightly export sitting in a storage account nobody has tested restoring from in two years. That scenario is why Microsoft spent nearly two years moving deleted record recovery in Dataverse from public preview to general availability in late April 2026. For solution architects and Dynamics 365 technical teams, a native Dataverse recycle bin restore capability closes a gap that has existed since the platform’s earliest days: there was never a supported, in-product way to undo a delete. Now there is one. The problem is that plenty of teams will configure it, assume it behaves like the Recycle Bin on a Windows desktop, and discover the gap between what it restores and what they actually needed restored only during a real incident.

The feature’s actual behavior is narrower and more procedural than its name suggests, and the places where it falls short map directly onto the customizations most F&O, Business Central, and Customer Engagement implementations already carry.

Solution architect reviewing a data recovery and system administration dashboard on a large monitor in a modern office

What the Dataverse Recycle Bin Restore Actually Covers

The capability itself is straightforward to enable. From the Power Platform admin center, under an environment’s Settings, Product, Features, there is a “Keep deleted Dataverse records” toggle with a retention window configurable from one to thirty days. Turn it on, and Dataverse begins tracking rows that get deleted so a System Administrator can view them under Data management, Deleted Records, and issue a Restore request against the ones worth recovering. The setting lives at the environment level, not the tenant level, so a sandbox and its corresponding production environment can carry entirely different retention windows, which matters if you’re testing destructive changes in a lower environment that doesn’t need the same thirty-day buffer production does.

The detail that trips up almost every team on first contact is that the feature is not retroactive. Only rows deleted after the setting is enabled and has finished propagating, which the documentation notes can take up to thirty minutes, become recoverable. A record deleted an hour before someone flips the toggle is gone exactly as it always was. If you’re reading this and haven’t enabled retention on a production environment yet, that thirty-minute propagation window is the argument for doing it now rather than after the incident that makes you wish you had.

Restoration happens through the Restore message, available in the SDK for both early-bound and late-bound entities, or as an action call through the Web API. The request takes a full target record rather than a bare reference, so you can override specific column values as part of the restore rather than being forced to bring back an exact snapshot. Deleted rows are also queryable directly: a FetchXml query with datasource='bin', or a QueryExpression with its DataSource property set the same way, returns rows sitting in the bin rather than the live table, which is enough to build a lightweight internal tool that surfaces what’s recoverable without routing every check through the admin UI.

The Tables That Never Show Up in the Bin

The exclusion list is where the feature’s real limits show up, and it is long enough that assuming universal coverage is a mistake worth catching before an incident rather than during one. Virtual tables are excluded entirely: if a record surfaced from an external system through a virtual table disappears, there was never anything in the bin to restore, since that row was never really “deleted” from Dataverse’s perspective so much as it stopped resolving. Elastic tables, increasingly common for high-volume telemetry, IoT-style logging, or activity history where standard table row limits become a constraint, are excluded as well. So are solution component tables, and so is any table that has grown past six hundred attributes, a ceiling that heavily customized standard entities in mature Dynamics 365 implementations can approach faster than teams expect.

Beyond those structural exclusions, Microsoft maintains a list of roughly two hundred and fifty system tables that don’t support deleted-record retention regardless of configuration: async operation records, background operation records, bulk delete failure logs, Power Automate flow run and flow log tables, solution and solution component tables, plugin assembly tables, and the full family of msdyn_ and mspp_ prefixed tables tied to first-party Dynamics 365 apps and Power Pages. None of that is arbitrary; those tables tend to be high-volume, system-managed, or tightly coupled to processes where a stale restored row could reintroduce more problems than it solves. But it does mean that if your disaster recovery narrative for a Power Pages portal assumes the recycle bin has you covered, it’s worth checking the actual exclusion list against your table inventory before that assumption ends up in a postmortem.

Abstract illustration of glowing data records being restored from an archive bin into an active data grid

Cascade Deletes Restore in Order. Custom Logic Doesn’t.

Where this feature gets genuinely interesting for anyone who has built out relationship cascading behavior is how it treats dependent records. Rows removed because of a configured cascade delete relationship, the kind set up through standard relationship behavior rather than custom code, are restorable, but not independently. You have to restore the parent record first; attempting to restore a cascaded child before its parent throws RefCannotBeRestoredRecycleBinNotFound, and the platform expects you to work back up the dependency chain in the correct order rather than picking records to restore arbitrarily.

Custom logic is a different story, and it’s the part of the feature architects need to internalize before promising anyone a one-click recovery story. If a plugin or a Power Automate flow deletes related records as a side effect of deleting the primary record, none of that custom-triggered deletion is automatically reversed by a Restore call. The recycle bin captures what Dataverse’s own relationship engine did, not what your business logic did on top of it. That means any implementation with plugins that clean up child records, cancel related cases, or cascade status changes on delete needs a mirrored restore path: a plugin registered against the Restore message, in the PostOperation stage specifically since the restored record isn’t available yet during PreOperation, that re-creates or re-links whatever the delete-time logic tore down. Skip this step and a team restores the parent record, then discovers days later that none of the related activity history, case associations, or downstream integration records came back with it, because nothing ever told them to.

A handful of other failure modes are worth knowing before you hit them live. Restoring a record whose ID has since been reused by a new record throws DuplicateExceptionRestoreRecycleBin, since Dataverse preserves the original primary key on restore rather than generating a new one. If a deleted record referenced an option set value that has since been removed from the choice definition, the restore fails with PicklistValueOutOfRangeRecycleBin. Both are recoverable situations, but only if whoever is running the recovery understands what the error is actually telling them instead of treating it as a generic restore failure and giving up.

Building the Restore Path for Real Incidents

None of this argues against enabling the feature. It argues for treating it as infrastructure that needs its own runbook rather than a switch you flip and forget. A reasonable rollout enables retention on every production environment now, sets the window to match your actual incident response SLA rather than defaulting to the maximum thirty days without weighing the storage tradeoff, and documents exactly which tables in your specific implementation fall outside the coverage: your virtual tables, any elastic tables you’ve adopted, and anything near the six-hundred-attribute ceiling.

The more valuable investment is building and testing the restore path before you need it: registering the mirrored Restore-stage plugin logic anywhere delete-time custom logic exists, confirming cascade restore order against your actual relationship map rather than assuming it will be intuitive mid-incident, and running a deliberate test delete-and-restore cycle in a sandbox so the first time anyone executes this procedure isn’t during a live outage. It’s also worth being explicit internally that this is record-level recovery, not a replacement for environment-level point-in-time restore, which remains the right tool for a broader corruption event or a bad deployment rather than a scoped accidental deletion. Teams that conflate the two end up with a false sense of coverage in exactly the scenario where they can least afford one.

The recycle bin is a genuinely useful addition, and it’s the kind of foundational reliability work that doesn’t generate much attention next to agent and Copilot announcements but matters more day to day for the teams operating these environments. Routeget has walked several clients through exactly this kind of gap analysis between what a new platform capability claims to cover and what a specific implementation’s customizations actually need, and the pattern holds here too: the feature is only as good as the runbook built around it. Treat this GA date as the trigger to write that runbook, not as the moment the problem quietly solves itself.


#Dataverse #DataverseRecycleBin #DataRecovery #PowerPlatformGovernance #ITDisasterRecovery #CloudArchitecture

Dataverse Audit Logs to Purview Now Redact Sensitive Fields. Your Incident Response Runbook Still Points There.

Compliance analyst reviewing a Dataverse audit log dashboard with some sensitive fields redacted before reaching Microsoft Purview

A security engineer investigating a compliance escalation pulls up Microsoft Purview’s unified audit log and searches for changes to a customer’s tax identification field in a Dynamics 365 Finance environment. The Dataverse audit configuration has been correctly enabled for years: environment-level auditing is on, the table is audited, the column is audited, and “Read logs” has been flowing activity to Purview since the tenant went live. Yet the search results show the record was updated, by whom, and when, but the actual before-and-after values for that field come back empty. Nothing is broken. Since June 26, 2026, Dataverse audit logs to Purview have deliberately worked this way for a defined set of sensitive columns, and most compliance and security teams have not yet updated their runbooks to account for it.

The feature responsible is a narrowly scoped but consequential change: Dataverse now strips certain categories of sensitive data, specifically financial information, health data, and personally identifiable information, out of audit events before they are transmitted to Purview’s activity logging pipeline. The values still exist. They are simply no longer making the trip to Purview, and that distinction has real operational consequences for anyone who built incident response, eDiscovery, or SIEM processes on the assumption that Purview’s audit log search was the complete picture.

What Actually Changed in Dataverse Audit Logs to Purview

Dataverse auditing has always captured create and update events at the column level, including the before-and-after value of every audited field, when environment, table, and column auditing are all enabled through the hierarchy Microsoft documents under Security, Compliance, and Auditing in the Power Platform admin center. Historically, if the environment’s “Read logs” setting was turned on, that entire audit record, field values and all, flowed to Purview’s unified audit log and became searchable at compliance.microsoft.com/auditlogsearch by anyone with the appropriate compliance role.

That behavior is what changed with general availability on June 26, 2026. Microsoft’s own release notes describe the mechanism plainly: create and update events, including a column’s before-and-after values, are still captured in Dataverse’s native audit store exactly as before. What changes is the copy sent onward to Purview. Financial data, health and medical information, and personally identifiable information are removed from that outbound payload before it leaves Dataverse. A change to a customer’s shipping address or a sales order’s discount percentage will still show full detail in Purview. A change to a national ID number, a diagnosis code stored in a custom health field, or a salary figure will not, even though every one of those changes is still fully visible inside Dataverse itself.

The rationale is straightforward: the unified audit log has a materially larger blast radius than Dataverse’s native audit history. Native audit history requires a Dataverse security role scoped to a single environment. The Purview unified audit log is a tenant-wide surface, reachable through eDiscovery cases and exportable by compliance investigators who may hold no Dynamics 365 role at all, retained under Microsoft 365 audit policy rather than Dataverse’s own retention settings. Sending unredacted salary or health data into that surface multiplied the number of people who could, deliberately or accidentally, end up looking at it.

Two Purview Pipelines That Behave Differently

Here is where the practical confusion tends to start. Dataverse actually feeds Purview through two distinct mechanisms, and they were never symmetrical even before this change. Classic Dataverse auditing, the one most organizations configured years ago through the environment’s “Log access” and “Read logs” toggles, is the pipeline this new redaction applies to. It is also the pipeline that historically sent complete field-level detail.

Separately, Dataverse’s comprehensive activity logging, the broader mechanism that captures nearly every SDK message an environment processes, including bulk exports, Advanced Find queries, and support engineer actions, has never sent column-level before-and-after values to Purview at all. Microsoft’s own documentation on comprehensive auditing states that column-level secured field values are sent to Purview as an asterisk rather than the underlying data, and that detailed field-level changes are withheld entirely from that pipeline specifically to prevent data leaks. That restriction predates the June 2026 change and applies regardless of whether a field touches financial, health, or PII data.

The practical upshot is that an organization relying primarily on comprehensive activity logging for its Purview visibility was already missing granular field values, and nothing changes for them. An organization that built its compliance program around classic Dataverse auditing with “Read logs” enabled, treating Purview’s audit log search as a faithful mirror of Dataverse’s own audit history, just lost a slice of that fidelity for exactly the categories of data most likely to matter in a regulatory inquiry.

Abstract illustration of a data grid with selectively redacted cells representing sensitive data masking

Where the Complete Record Still Lives

Nothing about this change reduces what Dataverse itself retains. The full before-and-after values for every audited column, sensitive or not, remain in Dataverse’s native audit store under whatever retention policy the environment has configured, which can run from a fixed number of days out to indefinite retention on production environments that support it. That data is accessible through the Power Platform admin center’s auditing summary view, through the classic audit history UI on individual records, and programmatically through the Dataverse Web API using the Audit entity or the RetrieveRecordChangeHistory message.

This is the detail worth building process around: if an investigation genuinely needs the value of a redacted sensitive field, the answer is not to escalate a Purview support ticket, it is to pivot the investigation to query Dataverse directly, using a role that has legitimate access to the Audit entity in that specific environment. That is a narrower, more auditable path than a tenant-wide Purview search, which is precisely the point of the change, but it means any documented incident response procedure that says “search Purview” as the first and only step now needs a second step for sensitive-field cases.

What to Check in Your Environment

Start by confirming which environments actually have “Read logs” enabled at the environment level, since that is the specific setting this change affects. Environments relying solely on comprehensive activity logging were never sending field-level detail to Purview and require no adjustment on this front, though it is still worth confirming which pipeline your compliance team believes it is querying, because in practice that assumption is not always accurate.

Next, inventory any downstream system that consumes Purview’s unified audit log for Dataverse activity: SIEM ingestion pipelines, Sentinel analytics rules built on audit log content, scheduled compliance reports, or custom Power BI dashboards pulling from the audit log search API. Any of these that parse or alert on specific before-and-after field values for financial, health, or PII columns will now see blank or null values where they previously saw data, which can silently break a detection rule that was matching on a specific value pattern rather than simply on the fact that a change occurred.

It is worth testing this directly rather than taking the documentation’s word for it, since Microsoft does not fully specify the exact classification logic used to flag a column as financial, health, or PII data. In a sandbox environment, make a controlled change to a column you believe falls into one of those categories, then compare what appears in Purview’s audit log search against what native Dataverse audit history shows for the same event, and repeat the test with a column outside those categories. The gap between documentation and observed behavior is where governance teams tend to get surprised months later.

A Compliance Improvement, Not a Complete DLP Control

It is tempting to read this feature as Microsoft having solved sensitive-data exposure in audit logging, and it has not, at least not entirely. It reduces exposure specifically on the path from Dataverse to Purview’s unified audit log for three defined data categories. It does nothing about sensitive data that lives in Dataverse’s own audit store, in exports, in Dataflows destinations, in Power BI datasets built on top of audited tables, or in any custom integration that pulls audit data directly from the Web API rather than through Purview. Organizations that treat this as a checkbox for their broader data loss prevention obligations under regulations like HIPAA or a state privacy law are conflating a narrow platform default with a program-level control, and an auditor will draw that distinction even if the platform release notes do not spell it out.

The more accurate framing is that Microsoft closed one specific, previously overlooked exposure path, and organizations now need to confirm their own audit consumption patterns still work correctly on the other side of that change. For teams running Dynamics 365 Finance and Operations or Customer Engagement with meaningful volumes of regulated data, that is a worthwhile few hours of validation, not a reason to assume the compliance posture improved on its own without anyone checking. Routeget Technologies has walked several clients through exactly this kind of audit configuration review after a platform-level change shifted what their existing monitoring actually captured, and the pattern is consistent: the environments that catch these gaps early are the ones that treat platform release notes as an input to a review, not as the review itself.


#DataverseAudit #MicrosoftPurview #PowerPlatformGovernance #DataLossPrevention #ComplianceMonitoring #EnterpriseSecurity