Real-time Power BI Refresh Strategies for Dynamics 365 Finance: Pushing Live Operational Data to Dashboards

When a finance director opens a dashboard to check month-end cash flow status, she expects current data, not a snapshot from six hours ago. Yet most Dynamics 365 Finance environments rely on scheduled, batch-mode Power BI refreshes that update on fixed cadence, creating a widening gap between reality and what appears on screen. For operational teams, this latency can mean stale forecasts, missed cost anomalies, and delayed responses to policy violations or supply disruptions. Real-time reporting demands a different approach than the refresh-on-schedule model most organizations default to.

The challenge is that pulling Finance data directly into Power BI via standard import connections can overwhelm the Finance database with read queries during peak hours. A poorly tuned refresh takes thirty minutes while creating production impact, leaving dashboards neither fast nor current. A credible real-time architecture requires rethinking the data pipeline: push relevant Finance events and balances to an intermediate store where Power BI can consume them with minimal latency and zero impact on production.

Understanding the Refresh Bottleneck

Power BI supports three refresh modes. Import mode caches data inside Power BI after refresh, enabling fast performance but requiring a refresh cycle to pull new data. DirectQuery runs queries live against the source database whenever a user interacts with a dashboard, ensuring freshness but imposing query load on Finance. Composite models blend both approaches.

For Dynamics 365 Finance, DirectQuery is operationally risky. A single dashboard with ten visuals can translate to dozens of live queries. During month-end close or go-live testing, when Finance is running heavy batch jobs, this query load noticeably degrades system responsiveness. A dashboard that appears instant to the user is actually a series of database queries, and if Finance tables are locked during depreciation calculations or reconciliations, the entire dashboard becomes unresponsive.

Import mode decouples reporting from operational workload, but standard refresh intervals—four hours, nightly, or weekly—are too stale for operational monitoring. The solution is a push architecture where Finance pushes relevant data to a staging layer that Power BI consumes, updated near-real-time while Finance operates independently.

Push-Mode Pipelines: Event-Driven and Incremental

The simplest push pattern uses Power Automate and Azure Synapse or Data Lake Storage. When a purchase order is approved, invoice posted, or cost variance detected, a Power Automate flow extracts the record and writes it to a staging table. Power BI then connects to this staging layer in import mode with a five to ten-minute refresh cycle, capturing near-real-time changes without querying Finance directly. Total latency: 1-2 minutes.

For broader financial reporting—GL balances, trial balance rollups, cash flow forecasts—pure event-driven loading is insufficient because you need current balances as of “right now,” not a history of updates. Incremental loading becomes essential.

Incremental loading uses a watermark pattern. When Power BI refreshes, it reads only records modified since the last refresh timestamp. Finance tracks modification dates, and each refresh pulls only deltas. This approach is far faster than full reloads and, combined with five-minute refresh cycles, delivers nearly-current balances while minimizing data volume transferred.

For Finance transactional tables, this is particularly effective. Load dimension tables (charts of accounts, vendors, cost centers) once or weekly, then refresh fact tables incrementally every five minutes. The first refresh includes all historical transactions; subsequent refreshes append only new and modified rows. The result is a Power BI model covering months of history but updating near-instantaneously for recent activity.

Staging Layer Architecture

The staging layer is critical. It must be performant, flexible, and autonomous from Finance operations.

Azure Synapse Dedicated SQL Pool is the enterprise standard. Synapse can load data from Finance and other sources and expose denormalized views optimized for BI queries. Power BI imports from Synapse rapidly due to columnar storage and indexing built for analytical workloads. Synapse supports incremental loading via change data capture that tracks Finance table modifications.

For cost-conscious implementations, Azure Data Lake Storage paired with Power Automate or Azure Data Factory works well. Export incremental Finance data to parquet files in Data Lake, partition by date, and Power BI reads directly. Modern Power BI queries parquet efficiently, with lower costs than running a dedicated SQL pool.

For organizations invested in Dataverse, it serves as the intermediate layer. Configure Power Automate or a custom plugin to sync Finance transactions and balances into Dataverse tables. Dataverse provides change tracking and native Power BI integration. The downside is that large-scale Finance data can strain Dataverse capacity.

Implementation Patterns and Performance Tuning

Latency depends on refresh frequency and the delay between Finance events and staging layer updates. Power Automate delivers updates within seconds. A posted invoice triggers a flow immediately, the flow writes to staging, and within a minute the Power BI refresh cycle captures it: total latency 1-2 minutes. Scheduled loads every five minutes mean transactions post by the end of the current refresh window.

Design for aggregation from the start. Instead of storing every GL entry detail, push daily balances at the account-cost center-department level. Store history in staging, but Power BI imports only recent months for interactive work; archival slices stay queryable via DirectQuery against staging for drill-down.

Use Power BI’s incremental refresh feature at the dataset level. Keep the last thirteen months in import mode refreshed daily, while older history remains available in DirectQuery for historical analysis. This keeps import datasets fast while preserving depth.

Once a push pipeline is live, operational excellence is non-optional. If a Power Automate flow fails silently, Finance changes don’t appear in dashboards. If a Data Factory job stalls, dashboards show stale data. Set up alerts for failed inserts and incomplete refreshes. Monitor Power BI refresh completion and alert if runtime exceeds expected duration. Build an audit table tracking the last refresh timestamp for each dataset, visible to operations.

Conclusion

Real-time Finance dashboards are achievable without overwhelming production systems. The key is moving from pull (Power BI queries Finance) to push (Finance updates stream to staging). Incremental loading and aggregation prevent staging from becoming a bottleneck. The result is dashboards updating every five to ten minutes with operational Finance data, accessible to CFOs and cost center managers, without degrading Finance responsiveness.

The investment is modest: a Synapse workspace or Data Lake container, a handful of Power Automate flows or a simple Data Factory pipeline, and careful data modeling. Over eighteen months, teams stop maintaining parallel reporting databases. Finance operations becomes proactive rather than reactive. The dashboard becomes the natural source of truth rather than a supplement to static reports.


Routeget Technologies helps mid-market and enterprise organizations design and implement real-time reporting architectures that balance responsiveness with operational integrity. Whether planning a Finance system implementation or modernizing an existing reporting layer, we align staging layer strategy with organizational maturity and cost constraints.


#PowerBIOptimization #DynamicsFinanceReporting #OperationalDashboards #RealTimeAnalytics #DataPipelines #PowerBIPerformance

Real-Time Dashboard Design in Power BI: When Live Connections Hurt Performance and What to Use Instead

Many organizations treat “real-time reporting” as a checkbox requirement rather than a technical decision. A director asks for a dashboard showing “live data” without specifying what live actually means, and teams immediately configure Direct Query connections to Dynamics 365 databases. Six months into production, those dashboards crawl under concurrent user load, and the director’s dashboard times out during CFO presentations.

The problem isn’t live data itself. It’s that live data in Power BI comes in distinct flavors, each with different performance trade-offs, and choosing the wrong flavor destroys performance at scale. This article shows which real-time architecture fits which scenario, and when you’re better off abandoning the real-time requirement altogether.

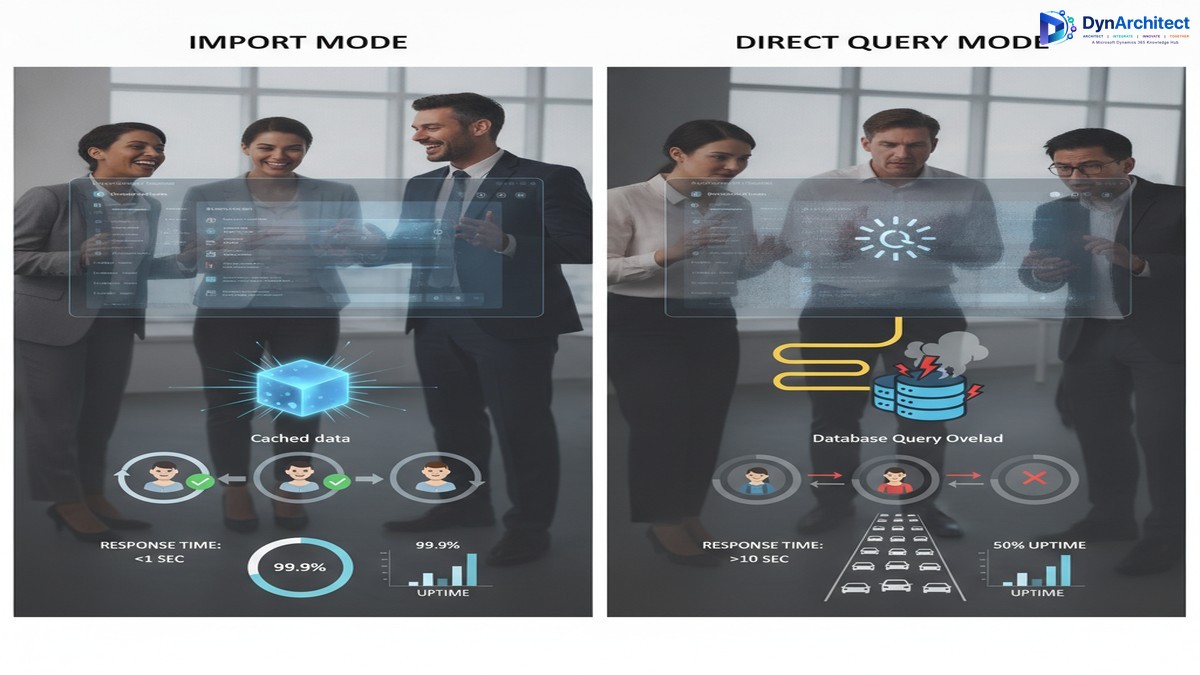
Power BI Import Mode vs Direct Query performance comparison dashboard

Understanding the Real-Time Spectrum

First, clarify what “real-time” means in your context. Most organizations conflate three different concepts: data freshness (how old is the data?), query latency (how fast does a dashboard query execute?), and update frequency (how often is new data available?). These are not the same.

A dashboard showing data refreshed every 15 minutes queries a cached aggregate table with instant response times. Alternatively, a dashboard querying a live Dynamics 365 database via Direct Query has zero latency from the database, but if 20 people open the dashboard simultaneously, queries become serialized and latency skyrockets. The “real-time” label obscures the actual performance characteristics.

Start by asking: How old can data be before a decision changes? A sales dashboard 10 minutes stale versus current-to-the-second rarely affects sales decisions. A finance dashboard showing expense reports can be 4 hours stale. A customer service dashboard showing ticket volume can be 30 minutes stale. Only a handful of use cases actually require sub-minute freshness.

Once you’ve anchored the actual freshness requirement, choosing an architecture becomes simpler.

Direct Query and Its Hidden Costs

Direct Query sends every user interaction as a live database query. No caching, no aggregation, just immediate translation of dashboard filters into T-SQL. On paper, this sounds ideal: always current, no data warehouse, minimal complexity.

In practice, Direct Query introduces three performance traps.

First, concurrent users crush database performance. When ten analysts open a Power BI dashboard simultaneously, Direct Query generates ten database queries in parallel. Add 15 more analysts, and suddenly transaction processing slows because the database is saturated with analytical queries. Power BI’s server-side caching helps only for identical queries. If each analyst filters by a different region, caching provides no benefit. You end up purchasing database resources purely for analytical load.

Second, complex calculations become prohibitively expensive. Direct Query works best for simple filtering and aggregation. The moment you need running totals, customer rankings, or month-over-month comparisons, you’re pushing calculations to the database or computing them in Power BI’s layer, both adding latency or complexity.

Most Dynamics 365 finance dashboards need these calculations. A cash flow dashboard ranking open invoices by days overdue, or a revenue dashboard showing year-to-date totals by region and product, requires a data warehouse layer or pre-computed calculations. With Direct Query, you can’t pre-compute anything because data always changes.

Third, network latency compounds with every filter. Each dashboard interaction triggers a new database query and network round-trip. In a data warehouse scenario, filtering might take microseconds (querying an in-memory cache). With Direct Query, it’s network latency plus database query time, often 2-5 seconds per interaction. A dashboard requiring five clicks to drill into detail takes 25+ seconds if each click pauses for network response. Users notice immediately.

Power BI analyst working with dashboards in modern office environment

Import Mode with Scheduled Refresh: The Workhorse

Import mode loads data into Power BI’s in-memory model, which you refresh on a schedule. For most enterprise dashboards, this is correct.

A finance dashboard might refresh every 4 hours. A sales dashboard every 30 minutes. A customer service dashboard every 15 minutes. Those intervals sound stale, but usually align with actual business decision cycles. A finance controller doesn’t make working capital decisions every 15 minutes; 4-hour refresh is sufficient. A sales manager checks pipeline daily, not per minute; hourly refresh is adequate.

Import mode’s advantage is simplicity at scale. Load data once, then serve the cached model to hundreds of concurrent users with zero database load. Your Dynamics 365 database doesn’t know dashboards exist. Add 50 new dashboard users tomorrow without anyone noticing performance change.

The model also compresses dramatically. A Dynamics 365 Finance general ledger with 50 million line items might compress to 500 megabytes in Power BI. A Direct Query approach queries the full 50 million rows every time a user opens a dashboard; an Import model loads once and serves fast queries.

Within Import mode, you gain access to calculated columns, measures, and DAX for sophisticated analytics. Calculate running totals, percentile rankings, trend lines, and complex financial metrics without touching the source database.

The trade-off is data freshness. If refresh happens every 4 hours and a user opens a dashboard at 3:59 AM, they see data from midnight. For operational dashboards needing sub-hourly updates, this becomes a problem. For strategic dashboards, it’s almost never an issue.

Hybrid and Push Approaches for Selective Real-Time

When some dashboard components need near-live data and others can be stale, hybrid approaches split the difference. A sales pipeline dashboard might import historical pipeline data (which changes slowly) but stream real-time opportunity counts from an API endpoint. These work only when you cleanly separate stale and live components.

Push Datasets allow you to stream data into Power BI in real-time, bypassing the database. A Dynamics 365 Finance workflow or custom service pushes event data (new orders, posted invoices, received payments) directly to Power BI as it happens. This is genuinely real-time and scales well because pushing is asynchronous.

Push Datasets make sense for operational dashboards tracking events: a manufacturing floor dashboard showing production events, an order-processing dashboard tracking fulfillment, or customer service dashboards displaying incoming tickets. They don’t work for analytical dashboards computing aggregates across historical data.

Choosing the Right Architecture

Start with business need, not technology.

For dashboards where data can be 4+ hours stale (finance reporting, executive dashboards, strategic analytics), use Import mode with nightly or 4-hour refresh. Build sophisticated DAX calculations. Serve unlimited concurrent users. This is your default.

For dashboards where data must be no more than 30-60 minutes stale (sales dashboards, customer service metrics, supply chain), use Import mode with more frequent refresh. Most dashboards fall here.

For operational dashboards tracking events (manufacturing, fulfillment, incident response), use Push Datasets if you can instrument the source system, or Dataflow with 5-10 minute refresh if you can’t.

For the rare sub-minute freshness requirement, use Direct Query, but explicitly cost the decision: calculate additional database licenses and query load needed. When directors hear “real-time reporting costs an additional 500k in database infrastructure,” cost-benefit calculations usually change.

Common Mistakes

Don’t design for yesterday’s requirements. Dashboards created for three analysts often serve 50 within a year. Design with Import mode and you’re prepared for scale.

Don’t confuse data freshness with query performance. A 4-hour-old dataset queried instantly feels faster than live data queried in 5 seconds.

Don’t use Direct Query because documentation says it’s for “live data.” Use it only after consciously calculating database costs.

The path forward is simple: pick the slowest freshness requirement you can justify, then design using Import mode. Scale up refresh frequency only if performance and business case demand it. Most organizations that follow this pattern end up with fast, stable dashboards and minimal infrastructure cost.

About Routeget Technologies: Routeget specializes in enterprise analytics and reporting architecture for Microsoft Dynamics 365 and Power BI implementations. Our consulting team helps organizations design dashboard strategies that balance business requirements with infrastructure costs, ensuring analytics scale with your organization without creating database performance bottlenecks.

#PowerBIDashboard #PowerBIPerformance #DataVisualization #RealTimeDashboards #PowerBIDirectQuery #PowerBIArchitecture #DataAnalytics

Power BI RLS at Scale: When Dynamic Row-Level Security Becomes a Bottleneck

Row-level security in Power BI seems straightforward during a pilot. You create a role-based filter on a User table, join it to your fact data, and suddenly users see only their assigned data. It works flawlessly with 10 users and a few hundred thousand rows. Then you move to production with 2,000 users and suddenly your dashboards refresh in 4 hours instead of 30 minutes, and the data warehouse query that used to run in 3 seconds now times out.

The culprit is almost always RLS implementation design, not hardware constraints or data volume. Most teams build RLS the way tutorials show: dynamic username matching against a lookup table. This pattern works until you hit scale. Once you do, the filter becomes computationally expensive, query engines struggle with the cardinality of the role definition, and your entire semantic model refresh becomes a bottleneck.

This isn’t a limitation of Power BI itself. It’s an architectural decision hiding inside seemingly innocent DAX formulas and role definitions. Get the architecture right early, and RLS scales smoothly. Get it wrong, and scaling becomes a major undertaking midway through your rollout.

How RLS Performance Actually Degrades

Most Power BI RLS implementations work by joining a Users table (containing user ID, email, username, and assigned business unit, region, or account) to your fact tables through a filtering relationship. In the role definition, you write something like:

[User_Email] = USERNAME()

This tells Power BI to filter the fact table to rows where the User_Email column matches the currently logged-in user’s email. Straightforward. But what happens underneath is what matters.

When a user opens a dashboard, Power BI doesn’t execute the RLS filter once and cache the result. Instead, the filter is embedded into every query the dashboard runs. If your dashboard has five visualizations, each visualization generates a separate query, and each query includes the RLS filter evaluated against your role definition. If your role evaluates USERNAME() against 50,000 user records to find a match, that’s 50,000 comparisons per query, times five queries, times however many concurrent users are refreshing reports at the same time.

This scales linearly downward with user count. Ten users means fifty thousand comparisons times five queries times ten simultaneous users. Two thousand users means fifty thousand comparisons times five queries times two thousand simultaneous users. The mathematics break quickly.

Additionally, most organizations layer RLS filters. You might have one RLS role for regional filtering, another for account-level filtering, and another for team assignment. Each layer adds another lookup and another set of comparisons. Three layers of RLS against large lookup tables is not uncommon, and it’s where the model refresh starts to visibly slow.

The Hidden Cost of Dynamic Username Matching

The USERNAME() function is convenient, but it’s also the root of many performance problems. USERNAME() returns the current user’s email or ID from Azure Active Directory (or whatever authentication system you’re using). That’s fine at a conceptual level. But in practice, USERNAME() is evaluated on every single row context change inside your queries.

Consider a common scenario: you have a Salesforce sync where you pull the current User table nightly. 30,000 user records. Each user has an assigned Region and an assigned Account list. Someone opens a Power BI dashboard with four visualizations. Power BI needs to execute four queries. Each query runs with RLS applied:

[UserEmail] = USERNAME()

Power BI’s query engine translates this into a filter condition in the underlying SQL or MDX query sent to your data source (whether that’s Azure SQL, Synapse, or a direct lake connection). The data engine evaluates this for every partition, for every table relationship, for every row that might match. With thirty thousand users and large fact tables, this isn’t trivial.

Then someone else logs in, and the same process repeats with a different USERNAME() value. In production, you might have hundreds of concurrent users, and each is generating this lookup and comparison overhead.

Design Patterns That Scale

The solution isn’t to eliminate RLS. It’s to change how you implement it so the filtering happens efficiently.

Pattern 1: Pre-computed Role Assignment in the Fact Table

Instead of dynamic lookup at query time, assign roles when data is loaded. Before your fact table lands in Power BI, compute which users have access to which rows and store that assignment as a column in the table itself. For example, add a column called AllowedUsers containing the user IDs or emails who can see that row. Then, in your RLS role:

[AllowedUsers] IN VALUES(...)

This is faster because you’re filtering on a pre-computed, indexed column rather than doing a lookup join at query time. The downside is that changes to user access require a full data refresh, not a runtime reevaluation.

Pattern 2: RLS at the Aggregation Layer, Not the Fact Layer

Many teams apply RLS to their most detailed fact tables. This is the most expensive place to filter. Instead, build your RLS semantics against aggregated or summarized tables. For example, if your fact table has order line-item level detail with thousands of rows per user, create a summary table at the order level, apply RLS there, and relate the detailed facts read-only. Users can’t drill below what they’re allowed to see.

Pattern 3: Role-Based Access Through a Mapping Table, Not a Lookup

Build a dedicated Role Mapping table that pre-computes which users belong to which roles. Populate it at load time, not query time. Then apply RLS against this mapping table using a relationship-based filter rather than a DAX formula:

Relationships: RoleMapping[UserID] -> FactTable[UserID]<br />RLS: [Role] = "SalesRep"

This delegates the filtering to relationship traversal, which database engines optimize heavily.

Pattern 4: Object-Level Security for Entire Semantic Model Sections

If individual row filtering becomes too expensive even with optimizations, consider object-level security. Hide entire tables, measures, or columns from certain roles. A regional sales manager might not see cost of goods or procurement details at all, not because the rows are filtered, but because those tables are invisible to them. This is blunter than row-level filtering, but it’s far more performant for large organizations.

Implementation Checklist

Before deploying RLS to production, verify:

1. Measure baseline query performance without RLS

Run your dashboards against a copy of the model with RLS disabled. How long does a refresh take? If it takes more than 30 minutes, RLS is not your bottleneck—your data model or query patterns are. Fix those first. If baseline is acceptable, proceed.

2. Identify your largest lookup table

User tables, regions, accounts, teams—whichever table you’ll use for role filtering. Count its rows. If it’s over 50,000, consider Pattern 1 or Pattern 3. If it’s under 10,000, standard dynamic username matching might be acceptable, but test at production scale first.

3. Test RLS with production user counts, not pilot counts

Set up a test model with realistic user counts. If you’ll have 2,000 users in production, create test roles for 500 of them and measure refresh time and query response. Don’t assume linear scaling. Cardinality issues often behave worse than linear.

4. Plan for re-architecture if needed

If you’re currently using dynamic USERNAME() matching against large tables, plan a migration to one of the patterns above. Don’t do this on the fly in production. Test the new architecture on a copy of the model first, measure performance improvement, then cut over.

5. Monitor refresh time trend

As your user base grows, your refresh times should not grow proportionally. If they do, your RLS implementation is hitting a wall. Catch this early, before users start complaining about stale data.

Conclusion

Power BI RLS is essential for organizations sharing a single semantic model across teams with different access rights. But RLS performance degradation is one of the most common production failures in Power BI deployments, and it’s entirely preventable with the right design pattern from the start. The difference between a dynamic username lookup against a 50,000-user table and a pre-computed role assignment is the difference between a 30-minute refresh and a 4-hour refresh once you scale.

Choose your RLS pattern based on your expected user count and role complexity before you build. Test at production scale before you roll out. And if you inherit a struggling RLS implementation, re-architecture isn’t a failure—it’s a necessary step toward a sustainable system.

#PowerBIRLS #RowLevelSecurity #PowerBIPerformance #EnterpriseAnalytics #DataSecurity #DAXOptimization #Dataverse #PerformanceOptimization