Implementing Row-Level Security at Scale in Power BI: Architecture Patterns for Enterprise Deployments

Implementing Row-Level Security at Scale in Power BI: Architecture Patterns for Enterprise Deployments

Row-level security (RLS) in Power BI is deceptively simple to configure at small scale but becomes architecturally complex at enterprise scale. A three-person team implementing RLS for department managers needs a different approach than a global organization securing access across 500 users in 30 business units with overlapping role structures. The difference between a working RLS implementation and a scaling nightmare often comes down to early architectural decisions.

The RLS Complexity Curve

Initial RLS implementations typically use role-based filtering on user principals through static mapping tables. For a 50-user deployment with 5-10 roles, this works fine. RLS rules defined in Power BI Desktop evaluate cleanly at query time, applying filters based on the USERNAME() or USERPRINCIPALNAME() function. But this pattern fails at scale for three reasons: maintaining role mappings as user counts grow becomes a data quality burden; overlapping roles and nested permission structures require increasingly complex DAX logic; and dynamic organizational changes require publishing new reports just to change who can see what.

Enterprise deployments need a different model. The RLS security source of truth should live in operational data (Dataverse, Azure AD, or a master HR system), not in report definitions. This shifts RLS from a static, publish-time concern to a dynamic, data-time concern. The row-level security rule itself becomes simpler (filtering based on a single dimension table), while complexity moves to maintaining accurate security attributes in the data model.

Architecture Pattern 1: Static Role-Based RLS

For organizations with under 200 users and stable role structures, a static role-based model works adequately if implemented carefully. Maintain a dedicated security role mapping table in your data warehouse that lists each user principal name and the rows they should access by department, business unit, or region. This table should load with every dataset refresh so changes flow through automatically without requiring report republishing.

Define your RLS rule using a simple CALCULATETABLE or FILTER statement that joins the user context against your security table. If your sales fact table has a DepartmentID column, and your security mapping table lists which departments each user can access, the rule evaluates user identity at query time and applies the appropriate filter. The rule is evaluated once per user session, so performance impact is minimal.

This pattern’s limitation is that organizational changes require updating the security table, which means a dataset refresh cycle before changes take effect. For most mid-market organizations, refresh cycles of twice daily are acceptable because role changes are planned events, not real-time operations. The payoff is simplicity: your rule is readable, auditable, and doesn’t require deep DAX expertise.

Architecture Pattern 2: Attribute-Based Dynamic RLS

Larger organizations with frequent organizational changes, multiple overlapping role dimensions, and matrix reporting structures need a dynamic approach. Instead of maintaining role mappings explicitly, encode user-to-data relationships as attributes on the user record itself.

Implement a user master table in your data warehouse that pulls from Azure AD or your operational HR system on every refresh. This user table includes standard fields plus security attributes relevant to your organization (department ID, cost center, region, business unit). The security rule joins the user context to this attribute table and filters based on the populated attributes.

This pattern has two advantages over static role mapping. First, organizational changes flow through automatically from the upstream system without requiring explicit RLS rule updates. Second, you express complex filtering logic as simple attribute comparisons. If a sales manager in the North region also has responsibility for a specific cost center and should see both regional data and cost-center data, you encode both attributes on the user record and your RLS rule filters where either condition is true.

The trade-off is that your data warehouse must stay in sync with the authoritative source system. If your HR system updates daily but your Power BI dataset refreshes every four hours, there will be windows where a role change hasn’t yet propagated. For most organizations, this latency is acceptable, but define the acceptable sync window and set expectations accordingly.

Architecture Pattern 3: Service Principal-Based RLS with Dataverse Integration

Organizations invested in the Microsoft ecosystem should consider a hybrid approach where Power BI datasets are refreshed by service principals, and RLS rules delegate to role-based access control (RBAC) enforced in Dataverse. Instead of embedding filtering logic in DAX rules, your Power BI dataset references a Dataverse view that already applies row-level filtering through Dataverse’s native RBAC system.

This pattern consolidates security logic in one place (Dataverse), making it auditable and changeable without touching Power BI. It works particularly well when your data originates in Dataverse anyway. The dataset refresh pulls data that has already been filtered by Dataverse’s row ownership and team access, and Power BI applies additional filtering if needed (for instance, date-based or region-based filtering that Dataverse doesn’t enforce).

Implementation Considerations at Scale

Regardless of which pattern you choose, several implementation decisions directly affect your ability to scale.

First, use object-level security (OLS) to complement RLS. OLS restricts which columns users can see, independent of rows. A sales manager should see sales volume and revenue filtered to their department, but should not see internal cost data or margin calculations. Separating these concerns makes your security model more maintainable.

Second, validate your RLS rules thoroughly before deploying to production. Test edge cases: users with no assigned security attributes, users with overlapping attributes, and changes in attribute values when a user moves departments. Power BI’s role modeling features in Desktop allow you to test rules locally before publishing.

Third, measure query performance impact. RLS rules are evaluated at query time, and poorly written rules can cause dramatic slowdowns. Test against realistic data volumes; don’t test with a 1000-row sample table when your production table has 100 million rows.

Fourth, document your RLS model. A spreadsheet or wiki page listing each role, the rule it enforces, and the business justification prevents future developers from breaking rules through seemingly innocent refactoring.

Common Pitfalls

One frequent mistake is treating RLS as a performance optimization rather than a security boundary. RLS is designed to ensure users cannot see unauthorized data. If you rely on RLS as a filter for performance, you introduce security risk if users gain direct database access.

Another common issue is RLS rule bloat. As business requirements expand, rules become complex nested IF statements. Move complexity into the data model (pre-computed security attributes on the user table) rather than into the rule itself. A rule should be a simple statement of how to filter, not a complex engine for deriving filter logic.

A third pitfall is insufficient testing of role transitions. When a user moves departments, their RLS access should update automatically through the next refresh cycle. Test this explicitly by changing roles in the upstream system, monitoring the refresh, and confirming access updates correctly.

Practical Path Forward

For organizations starting RLS implementations, begin with Pattern 1 (static role-based) to understand the mechanics. Build a security role mapping table, implement one simple rule, and test thoroughly. Once that’s working, you understand scaling constraints and can decide whether to move to Pattern 2 (attribute-based) or Pattern 3 (Dataverse-delegated) based on your organization’s size and rate of organizational change.

For existing deployments struggling with scaling, audit your current RLS logic. If you’re managing more than 30-40 explicit roles or role changes require manual dataset republishing, you’ve outgrown Pattern 1 and should migrate to attribute-based filtering. The investment is significant (4-8 weeks for most organizations), but the payoff is a security model that scales with organizational growth without requiring report republishing.


#PowerBIRowLevelSecurity #PowerBIArchitecture #DataGovernance #BusinessIntelligence #RLSImplementation #PowerBIBestPractices #EnterpriseSecurity

Real-Time Dashboard Design in Power BI: When Live Connections Hurt Performance and What to Use Instead

Many organizations treat “real-time reporting” as a checkbox requirement rather than a technical decision. A director asks for a dashboard showing “live data” without specifying what live actually means, and teams immediately configure Direct Query connections to Dynamics 365 databases. Six months into production, those dashboards crawl under concurrent user load, and the director’s dashboard times out during CFO presentations.

The problem isn’t live data itself. It’s that live data in Power BI comes in distinct flavors, each with different performance trade-offs, and choosing the wrong flavor destroys performance at scale. This article shows which real-time architecture fits which scenario, and when you’re better off abandoning the real-time requirement altogether.

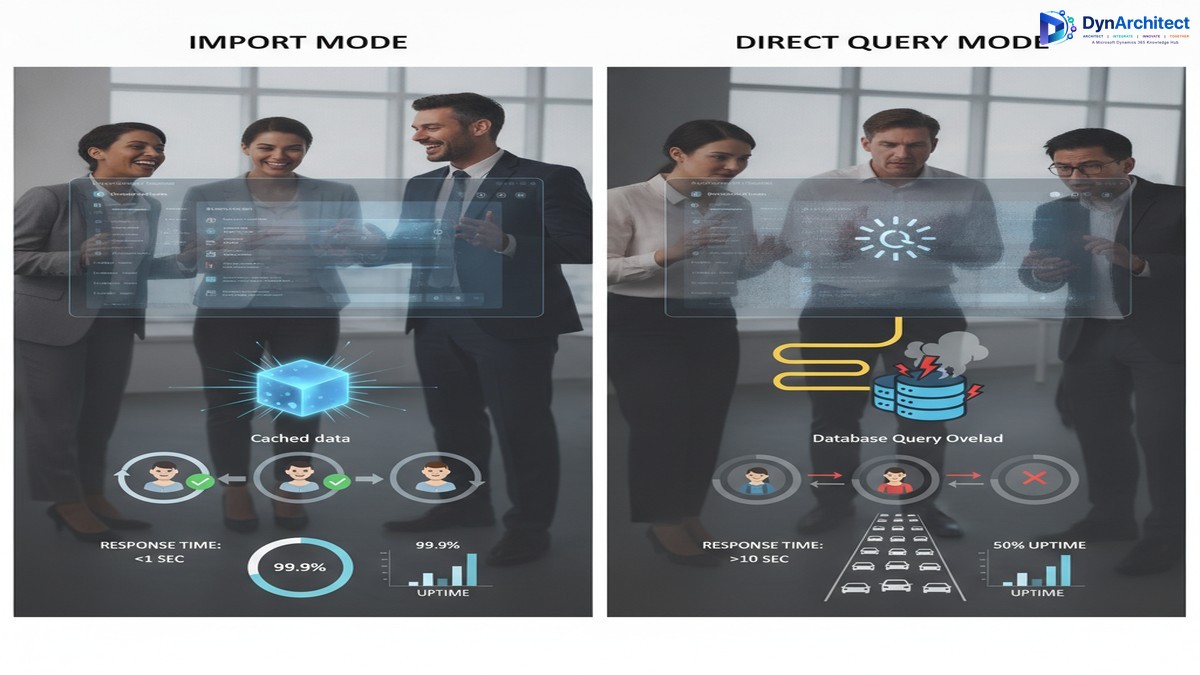
Power BI Import Mode vs Direct Query performance comparison dashboard

Understanding the Real-Time Spectrum

First, clarify what “real-time” means in your context. Most organizations conflate three different concepts: data freshness (how old is the data?), query latency (how fast does a dashboard query execute?), and update frequency (how often is new data available?). These are not the same.

A dashboard showing data refreshed every 15 minutes queries a cached aggregate table with instant response times. Alternatively, a dashboard querying a live Dynamics 365 database via Direct Query has zero latency from the database, but if 20 people open the dashboard simultaneously, queries become serialized and latency skyrockets. The “real-time” label obscures the actual performance characteristics.

Start by asking: How old can data be before a decision changes? A sales dashboard 10 minutes stale versus current-to-the-second rarely affects sales decisions. A finance dashboard showing expense reports can be 4 hours stale. A customer service dashboard showing ticket volume can be 30 minutes stale. Only a handful of use cases actually require sub-minute freshness.

Once you’ve anchored the actual freshness requirement, choosing an architecture becomes simpler.

Direct Query and Its Hidden Costs

Direct Query sends every user interaction as a live database query. No caching, no aggregation, just immediate translation of dashboard filters into T-SQL. On paper, this sounds ideal: always current, no data warehouse, minimal complexity.

In practice, Direct Query introduces three performance traps.

First, concurrent users crush database performance. When ten analysts open a Power BI dashboard simultaneously, Direct Query generates ten database queries in parallel. Add 15 more analysts, and suddenly transaction processing slows because the database is saturated with analytical queries. Power BI’s server-side caching helps only for identical queries. If each analyst filters by a different region, caching provides no benefit. You end up purchasing database resources purely for analytical load.

Second, complex calculations become prohibitively expensive. Direct Query works best for simple filtering and aggregation. The moment you need running totals, customer rankings, or month-over-month comparisons, you’re pushing calculations to the database or computing them in Power BI’s layer, both adding latency or complexity.

Most Dynamics 365 finance dashboards need these calculations. A cash flow dashboard ranking open invoices by days overdue, or a revenue dashboard showing year-to-date totals by region and product, requires a data warehouse layer or pre-computed calculations. With Direct Query, you can’t pre-compute anything because data always changes.

Third, network latency compounds with every filter. Each dashboard interaction triggers a new database query and network round-trip. In a data warehouse scenario, filtering might take microseconds (querying an in-memory cache). With Direct Query, it’s network latency plus database query time, often 2-5 seconds per interaction. A dashboard requiring five clicks to drill into detail takes 25+ seconds if each click pauses for network response. Users notice immediately.

Power BI analyst working with dashboards in modern office environment

Import Mode with Scheduled Refresh: The Workhorse

Import mode loads data into Power BI’s in-memory model, which you refresh on a schedule. For most enterprise dashboards, this is correct.

A finance dashboard might refresh every 4 hours. A sales dashboard every 30 minutes. A customer service dashboard every 15 minutes. Those intervals sound stale, but usually align with actual business decision cycles. A finance controller doesn’t make working capital decisions every 15 minutes; 4-hour refresh is sufficient. A sales manager checks pipeline daily, not per minute; hourly refresh is adequate.

Import mode’s advantage is simplicity at scale. Load data once, then serve the cached model to hundreds of concurrent users with zero database load. Your Dynamics 365 database doesn’t know dashboards exist. Add 50 new dashboard users tomorrow without anyone noticing performance change.

The model also compresses dramatically. A Dynamics 365 Finance general ledger with 50 million line items might compress to 500 megabytes in Power BI. A Direct Query approach queries the full 50 million rows every time a user opens a dashboard; an Import model loads once and serves fast queries.

Within Import mode, you gain access to calculated columns, measures, and DAX for sophisticated analytics. Calculate running totals, percentile rankings, trend lines, and complex financial metrics without touching the source database.

The trade-off is data freshness. If refresh happens every 4 hours and a user opens a dashboard at 3:59 AM, they see data from midnight. For operational dashboards needing sub-hourly updates, this becomes a problem. For strategic dashboards, it’s almost never an issue.

Hybrid and Push Approaches for Selective Real-Time

When some dashboard components need near-live data and others can be stale, hybrid approaches split the difference. A sales pipeline dashboard might import historical pipeline data (which changes slowly) but stream real-time opportunity counts from an API endpoint. These work only when you cleanly separate stale and live components.

Push Datasets allow you to stream data into Power BI in real-time, bypassing the database. A Dynamics 365 Finance workflow or custom service pushes event data (new orders, posted invoices, received payments) directly to Power BI as it happens. This is genuinely real-time and scales well because pushing is asynchronous.

Push Datasets make sense for operational dashboards tracking events: a manufacturing floor dashboard showing production events, an order-processing dashboard tracking fulfillment, or customer service dashboards displaying incoming tickets. They don’t work for analytical dashboards computing aggregates across historical data.

Choosing the Right Architecture

Start with business need, not technology.

For dashboards where data can be 4+ hours stale (finance reporting, executive dashboards, strategic analytics), use Import mode with nightly or 4-hour refresh. Build sophisticated DAX calculations. Serve unlimited concurrent users. This is your default.

For dashboards where data must be no more than 30-60 minutes stale (sales dashboards, customer service metrics, supply chain), use Import mode with more frequent refresh. Most dashboards fall here.

For operational dashboards tracking events (manufacturing, fulfillment, incident response), use Push Datasets if you can instrument the source system, or Dataflow with 5-10 minute refresh if you can’t.

For the rare sub-minute freshness requirement, use Direct Query, but explicitly cost the decision: calculate additional database licenses and query load needed. When directors hear “real-time reporting costs an additional 500k in database infrastructure,” cost-benefit calculations usually change.

Common Mistakes

Don’t design for yesterday’s requirements. Dashboards created for three analysts often serve 50 within a year. Design with Import mode and you’re prepared for scale.

Don’t confuse data freshness with query performance. A 4-hour-old dataset queried instantly feels faster than live data queried in 5 seconds.

Don’t use Direct Query because documentation says it’s for “live data.” Use it only after consciously calculating database costs.

The path forward is simple: pick the slowest freshness requirement you can justify, then design using Import mode. Scale up refresh frequency only if performance and business case demand it. Most organizations that follow this pattern end up with fast, stable dashboards and minimal infrastructure cost.

About Routeget Technologies: Routeget specializes in enterprise analytics and reporting architecture for Microsoft Dynamics 365 and Power BI implementations. Our consulting team helps organizations design dashboard strategies that balance business requirements with infrastructure costs, ensuring analytics scale with your organization without creating database performance bottlenecks.

#PowerBIDashboard #PowerBIPerformance #DataVisualization #RealTimeDashboards #PowerBIDirectQuery #PowerBIArchitecture #DataAnalytics