Configuring Field Service Requirement Groups Before You Turn On the Scheduling Operations Agent

Field service dispatcher reviewing a multi-resource schedule board on a large monitor

A dispatcher at a commercial HVAC contractor gets a work order for a rooftop unit replacement that needs a refrigerant-certified technician and a licensed electrician on site at the same time. Neither one can do the job alone, and the customer has a four-hour access window. On most schedule boards, this becomes two separate booking searches, two different sets of availability to cross-reference by hand, and a fair amount of guessing about who else is nearby when the first match falls through. Dynamics 365 Field Service has had a purpose-built answer to this for a while, and it lives inside a feature called Field Service requirement groups. What changes this year is that Field Service is also rolling out an AI agent that can optimize those multi-resource schedules on its own, and the two capabilities need to be understood together, not separately, if a rollout is going to hold up.
Field service dispatcher reviewing a multi-resource schedule board on a large monitor

Why Requirement Groups Exist

A requirement group bundles several resource requirements that are commonly scheduled together for a single job: two technicians with different skills, a technician paired with a piece of equipment, or a facility resource alongside the staff member who runs it. It solves a narrower problem than it sounds like it should. Field Service already has crews for resources who always work as a fixed unit, so requirement groups are reserved for combinations that vary from job to job, which is exactly the HVAC scenario above. Get that distinction wrong early and dispatchers end up maintaining crew records for what are really one-off pairings, which defeats the purpose of either feature.

Configuring Field Service Requirement Groups: A Three-Step Setup

Building a usable requirement group takes three steps, and the order matters more than the documentation implies, because the template governs everything downstream.

The first step is the requirement group template, created under Resource Scheduling settings. Two fields here decide how strict the matching logic is. The “Select” setting is either All, meaning every resource in the group must satisfy every requirement, or Any, meaning a resource can fulfill any one of them; nesting subgroups lets a team combine both, for instance a root group set to Any with two subgroups each set to All, which is how a dispatcher models “either an electrician-plus-tech pairing or a single dual-certified tech will do.” The “Part of Same” setting controls how tightly the resources have to be related to each other, ranging from a shared location association up through a shared organizational unit, which is the strictest option and the one most enterprises with multiple legal entities or regional service territories will actually need.

The second step is adding individual requirements to the template: duration, characteristics or skills, resource categories, work location (facility, on-site, or location-agnostic), and preferred resources, each capped at ten values. That cap is easy to hit for a services company with a large skills taxonomy, and the practical fix is to push filtering down to characteristics rather than trying to enumerate every acceptable technician by name.

The third step is booking through the schedule assistant, which searches for resources that can fulfill the group’s requirements and defaults to recommending the option requiring the fewest resources first. Requirement group templates can also be attached directly to incident types, so a work order created from a known incident type pulls in its multi-resource requirements automatically instead of relying on a dispatcher to remember which jobs need a paired booking.

The Detail That Breaks Onsite Jobs

One behavior catches teams off guard during go-live. The schedule assistant matches resources by arrival time, not by when they start traveling. For a job where both resources are dispatched from the same depot, that distinction rarely matters. It matters a great deal when one technician is thirty minutes from the site and the other is ninety minutes out on a different route; the assistant will still try to land them at the customer’s door at the same moment, which can mean the closer resource sits idle waiting for a window that a smarter dispatcher would have staggered. Any territory with technicians spread across a wide radius should account for this when setting expectations with dispatch staff, rather than treating a rejected recommendation as a bug.

A handful of other constraints are worth knowing before they show up as a production surprise. Requirement groups do not support multi-day scheduling; a job spanning more than one day needs Field Service’s separate multi-day scheduling capability instead. Every requirement inside a group must share the same duration, so a job needing a technician for four hours and a specialist for only the first hour has to be modeled as two bookings, with cascade crew changes disabled afterward so adjusting one booking’s length does not silently drag the other along with it. And incident types that already carry their own characteristics cannot be linked to a requirement group template at the same time, which pushes teams toward attaching characteristics to the individual requirements inside the group rather than to the incident type itself.
Two field service technicians consulting a tablet showing work order and scheduling details

Where the Scheduling Operations Agent Fits

Requirement groups solve how a multi-resource job gets modeled and booked once. The Scheduling Operations Agent, entering broader preview this month, is aimed at a different problem: keeping the whole day’s schedule coherent after the first booking, when cancellations, overruns, and priority changes start cascading across a technician roster. It already handled single and multi-resource optimization in an earlier preview; what is new is an “automate optimizations” capability that runs in two modes. Interactive mode surfaces suggested changes for a dispatcher to accept in the moment, which is closest to how the tool has worked so far. Batch mode runs asynchronously against a defined scope of resources, on a schedule, which is the part that actually reduces manual dispatch work rather than just speeding up the click-through.

The naming is a little ahead of what the feature currently does, and that gap is worth being precise about with stakeholders. Every optimization the agent proposes, in either mode, still requires human approval before it takes effect, and it will not touch a booking marked “Do Not Move.” That is a sensible guardrail, but it means batch mode is closer to an overnight queue of pre-vetted suggestions waiting for a morning review than to unattended rescheduling. Teams evaluating this as a way to cut dispatcher headcount should model it as an efficiency gain on the review step, not a removal of the step.

Setup runs through three admin-configured objects: goals, which define what the agent is optimizing for and the constraints it has to respect, such as skill eligibility and territory boundaries; scopes, which define which resources and requirements are in play; and plans, which schedule batch runs. None of this is exposed to end users by default, so a pilot needs a maker or admin to own the configuration from day one, and it needs a data foundation of accurate characteristics and territory assignments on the underlying resources, since the agent’s recommendations are only as good as the constraint data it is reading. This is also where requirement group discipline pays off twice: a schedule with sloppy or missing characteristics will produce weak optimization suggestions regardless of how well the agent itself is configured. Regional rollout is uneven as well; the feature is unavailable in Azure Government and China cloud environments and is still expanding across other regions, so a multinational deployment should confirm coverage before promising a go-live date to any specific site.

Sequencing a Rollout That Actually Holds

The practical order is to get requirement groups and their underlying characteristics right first, on a defined subset of incident types, before layering the agent on top. A team that tries to configure both at once tends to spend its pilot debugging which layer produced a bad recommendation. Once requirement group bookings are reliable for a specific service line, interactive-mode agent suggestions are a reasonable next step, since a dispatcher is reviewing every change anyway. Batch mode is worth piloting only after that interactive period has built some trust in the agent’s judgment on that same resource pool, and even then it should start on a narrow scope rather than the full technician roster. Routeget Technologies has run this kind of phased rollout with field service clients who tried to skip straight to full automation and ended up rebuilding their characteristic taxonomy mid-project instead; sequencing it the other way costs a little more calendar time upfront and considerably less rework later.


#FieldServiceScheduling #RequirementGroups #SchedulingOperationsAgent #MultiResourceBooking #DispatchOptimization #DynamicsFieldService

Why Your Supply Chain Visibility Stops at Your Warehouse Door: Building End-to-End Traceability in Dynamics 365

Why Your Supply Chain Visibility Stops at Your Warehouse Door: Building End-to-End Traceability in Dynamics 365

It’s 2 a.m. on a Tuesday. Your manufacturing facility just identified a critical defect in raw materials that arrived from a supplier last week. By the time your quality team finished root-cause analysis, those defective materials were already processed into three separate production batches. Now you’re facing potential customer recalls, regulatory notification deadlines, and no clear way to trace which finished goods actually contain the defective material. Your supply chain software told you where the raw material was ordered and when it arrived. It told you absolutely nothing about where it went after that.

This scenario plays out in manufacturing and distribution operations every day. Supply chain visibility systems excel at tracking inbound inventory but break down once materials enter production or move through fulfillment. For many operations leaders, the supply chain becomes a black box the moment inventory leaves the warehouse.

The business cost of that blind spot is substantial. When quality issues surface, traceability delays mean either expensive and conservative recalls that pull good products from shelves, or risky decisions to ship products you cannot confidently verify as safe. For regulated industries, regulators expect faster, more precise responses than manual investigation can deliver. Beyond quality, lost visibility into material flow makes it nearly impossible to understand true landed costs, verify supplier performance claims, or negotiate accurately on future contracts.

Dynamics 365 Supply Chain Management addresses this visibility gap by connecting procurement, inventory, production, and fulfillment into a unified traceability architecture. The difference is not just better information. It is speed and precision when those information gaps cost you the most.

The Visibility Problem Runs Deeper Than Poor Reporting

Most supply chain systems treat traceability as an optional feature bolted onto inventory management. A truck arrives with materials. The system records receipt and location. Then it moves to the next transaction. There is no continuous thread connecting that receipt to the production order that consumed it, to the manufactured batch that contains it, to the shipment that sent it to customers.

This architectural gap exists because legacy systems were built for transaction volume, not data continuity. A system designed in 1997 needed to process thousands of purchase orders and shipments daily. It could not afford to maintain detailed linkages between every input and output. Instead, operations relied on physical batch logs, manual tracking spreadsheets, and the assumption that anyone who needed to trace materials would do so through paper records and institutional memory.

That model breaks when scale grows, when complexity increases, and when regulators start asking for proof instead of accepting your word.

The actual impact shows up in three ways. First, quality investigations take weeks instead of days because tracing backward from a customer complaint requires manual detective work across multiple systems and warehouses. Second, compliance teams spend months preparing for audits because they cannot quickly demonstrate that materials flowed exactly as regulations require. Third, cost analysis remains vague because you cannot match specific materials through production to specific finished goods and actual profit margins by customer or product line.

For operations leaders evaluating the business case for new systems, this is the tension: your current software works fine for running day-to-day operations, but it leaves you strategically blind when problems surface.

Dynamics 365 Solves This Through Persistent Tracking Dimensions

Dynamics 365 Supply Chain Management addresses traceability through a concept called inventory tracking dimensions. These are optional attributes you assign to materials when they arrive that the system carries forward through every downstream transaction.

In practice, this means when a raw material shipment arrives from a supplier, you can assign a lot number, a batch identifier, or a supplier batch code to that inventory. Every time that material moves, Dynamics 365 maintains that linkage. When it gets consumed in production, the system knows exactly which finished goods batch contains that material. When the finished goods shipment occurs, the system knows which supplier lot reached which customer.

This is simpler than it sounds in theory and more complex in execution. The traceability chain only works if data quality is maintained at every step. Warehouse receiving teams must accurately record lot numbers when materials arrive. Production schedulers must use the right lot allocation logic so materials move in the order and combinations you intend. Finished goods picking must respect lot traceability so batches do not inadvertently mix material from multiple suppliers.

Beyond receiving and production, Dynamics 365 extends visibility into logistics through Transportation Management integration. When finished goods ship, the system can attach the upstream supplier and production batch information to the shipment record. If your logistics partners accept real-time shipment data, you can even extend visibility beyond your own dock to show customers or regulators exactly when and how products moved from your facility.

Quality management workflows layer on top of this. When a quality hold is placed on a supplier lot, Dynamics 365 can automatically flag all downstream inventory and production batches that contain that material. Recalls, when they become necessary, can be precisely scoped to affected batches rather than conservative over-recalls of everything you cannot immediately rule out.

The Implementation Reality

Building this capability requires more than buying software. It requires operational discipline and often represents a genuine change in how warehouse and production teams work.

First, data quality becomes non-negotiable. If lot numbers are not recorded accurately at receiving, the entire chain breaks. Many organizations find this is the hard part, not the technology. Warehouse teams accustomed to checking boxes now need to record specific identifiers and understand why precision matters. For operations leaders, this means investment in training and ongoing quality checks, not just software implementation.

Second, integration with logistics partners becomes necessary if you want visibility to extend beyond your facility. Most transportation management systems now accept data feeds, but the integration requires coordination and often custom mapping to match your identifier schemes with your logistics partners’ systems.

Third, implementation timelines are usually longer than initial estimates because the visibility you gain surfaces data quality issues that existing systems were hiding. You may discover that your receiving team has been using approximate lot numbers or that production scheduling has been commingling materials from different lots without clear documentation.

For most mid-market to large manufacturers, the return on investment justifies that effort. Once you have consistent end-to-end traceability, quality investigations that previously took ten business days now take one. Compliance audits shift from defensive documentation gathering to straightforward system queries. Supplier negotiations become evidence-based rather than assumption-based when you can show precisely how their material performed through your production process.

What This Means for Your Supply Chain Strategy

The businesses that maintain the strongest competitive positions today are those that treat supply chain as a strategic asset, not a cost center. Part of that strategy is building the visibility to know what you own, where it is, and what happened to it at every stage.

Dynamics 365 Supply Chain Management makes that visibility achievable at reasonable scale. The foundation is simple: persistent tracking dimensions that follow materials from receipt through production and shipping. The execution requires discipline and investment in data quality and integration. The payoff is speed and precision when quality issues surface, confidence in regulatory readiness, and the data you need to make supplier performance and profitability decisions based on fact instead of intuition.

If your current supply chain software has a blind spot after inventory leaves the warehouse, that blindness has a cost. The question is whether you measure it.


#SupplyChainTraceability #Dynamics365SCM #InventoryTracking #SupplyChainVisibility #LotTracking #QualityManagement #SupplyChainCompliance #ManufacturingERP

Business Central Production Scheduling: Why Visual Scheduler Configuration Fails When Demand Patterns Change

Production scheduling in Business Central sounds straightforward until you implement it at scale. The visual production scheduler promises drag-and-drop job sequencing and real-time capacity planning. Deploy it and discover that your demand patterns don’t fit the assumptions the system bakes into its default behavior. Planners revert to spreadsheets within weeks. The scheduler wasn’t broken; the configuration was incomplete.

The visual production scheduler in Business Central sits between shop floor execution and demand planning. It maps jobs to work centers, respects capacity constraints, and surfaces bottlenecks visually. But it works only when three conditions align: demand forecasts are stable, work center capacity is fixed, and job dependencies follow predictable patterns. Change any one of those, and the scheduler either produces schedules that don’t work or gets abandoned for manual planning.

Why Visual Scheduling Breaks Under Real Demand

Most implementations configure the scheduler once at go-live, assume demand won’t shift significantly, and leave it. Demand does shift. Seasonal patterns emerge. Customers request expedited jobs. Supply constraints force substitution of materials that process differently. The visual scheduler has no feedback loop; planners see outdated capacity assumptions in their schedules but have no way to tell the system that the underlying model has changed.

The core issue is that the scheduler operates on historical work center capacity and fixed routing assumptions. When a customer order arrives that doesn’t match the standard bill of materials or when a work center consistently underperforms its configured hours available due to changeover time or quality hold-ups, the scheduler still assumes standard capacity. Planners know the real constraint (the paint booth runs six hours a day, not eight, because of cure time between jobs), but the system doesn’t. Schedules become fiction.

Adding seasonality creates a secondary failure mode. Winter orders require different sequencing than summer demand. Heat-treating capacity bottlenecks shift based on product mix. The scheduler can’t recognize these seasonal patterns because configuration is static. A planner building schedules manually can say, “December through February, we prioritize thinner stock because it moves through coating faster.” The visual scheduler just sees jobs and available hours and proposes sequences that look optimal on the Gantt chart but fail in execution.

The Configuration Reality

Setting up the visual scheduler correctly requires knowing your capacity model in detail before you have execution data. That’s the uncomfortable truth. You need to define work center hours, parallel or sequential capacity, setup and teardown time, quality hold periods, material feed time, and routing flexibility. Get any of those wrong, and schedules drift immediately from what the system proposes to what planners can actually execute.

Most small and medium manufacturers don’t have this data documented at configuration time. They know their shop floor, but they don’t have it formalized into the work center master in Business Central. So they estimate. The estimates are close but not exact. Schedules are therefore slightly off from day one. The delta is small enough that planners don’t notice for weeks, but once they do, credibility in the tool evaporates.

Diagnosis: When Schedules Stop Matching Reality

The failure usually manifests as a mismatch between what the scheduler says can be done and what actually ships. A planner creates a schedule showing three jobs fitting into a work center in a day. The first job completes on time, but the second never starts because the first consumed more setup time than the system assumed. The planner gets blamed for a bad schedule. The scheduler gets blamed for being unrealistic. Neither blame is accurate; the system doesn’t know the real setup time.

Spot this problem early by comparing historical throughput data against scheduler assumptions. Pull actual shop floor execution history and overlay the capacity assumptions in each work center definition. If real throughput is 15 percent lower than configured, the system is optimistic. If throughput is 15 percent higher, the system is conservative (less common, but it happens when planners are very efficient or when the scheduler’s assumptions about parallel work are overstated). The gap is your calibration opportunity.

Three Production-Ready Fixes

The most effective fix is to build a demand-responsive scheduling loop. Instead of assuming demand is stable, capture actual demand patterns over a rolling window (usually 3-6 months of order data) and re-baseline the scheduler assumptions quarterly or semi-annually. This doesn’t require expensive plugins; it requires discipline in the operations team to review throughput variance and update work center capacity definitions when patterns change.

Second, implement a hierarchical scheduling approach. Use the visual scheduler for the primary constraint (often one critical work center) and leave everything else to manual planning or automated sequencing. Don’t try to optimize the entire job shop simultaneously; optimize the bottleneck. Everything else sequences around it. This reduces the configuration surface and makes the system more robust to planning changes.

Third, establish a feedback cycle between planners and the master scheduler. Every two weeks, have the planner who lives with the schedule review it and flag five jobs that were either much easier or much harder to execute than the system predicted. Feed those observations back into work center definitions. This is operational overhead, but it’s the operational overhead that keeps the scheduler aligned with reality instead of chart fantasy.

When to Accept Spreadsheets Instead

Not every manufacturer can or should use the visual scheduler. If your demand patterns change weekly, your jobs have highly variable routing, or your work centers have truly shared capacity across unrelated product families, the scheduler will always lag reality. In those cases, accept that planners will use spreadsheets or written job cards and build Business Central to support that workflow. Track scheduled completion dates and actual completion dates, but don’t pretend a static scheduler will optimize a fundamentally dynamic shop floor.

For manufacturers with repeatable products, stable demand patterns, and one or two clear bottlenecks, the scheduler is valuable. For job shops or custom manufacturers, it’s decoration.

Moving Forward

The visual production scheduler in Business Central is a tool, not a solution. It works best when you know your constraints and keep them documented. It fails quietly when assumptions drift from reality without anyone noticing until schedules stop matching execution. The organizations that sustain scheduler use treat it as a system that needs constant calibration, not a one-time configuration.

Start with the simplest possible scheduler setup: one work center, one product family, one demand pattern. Get that right before adding complexity. Use the first three months of data to calibrate. Then decide whether to expand or whether your planners are already doing a better job with their current method and the scheduler will just slow them down. That’s the conversation that happens too late in most implementations, when the scheduler is already abandoned.

About Routeget Technologies: With over a decade of Business Central implementation experience across discrete, process, and hybrid manufacturers, Routeget helps organizations design production planning systems that planners actually use. Our consultants focus on aligning system configuration with operational reality rather than forcing operations to match system assumptions.


#BusinessCentralManufacturing #ProductionScheduling #ManufacturingERP #JobShopScheduling #CapacityPlanning #BusinessCentral #SupplyChainOptimization #SmallManufacturing

Implementing Robust Error Handling in Power Automate: Patterns for Enterprise Deployments

One of the most insidious threats to enterprise automation is the silent failure—a workflow that appears to complete successfully but delivers corrupted data, skipped steps, or incomplete transactions. In Power Automate, uncaught errors compound this risk when operations fail without proper logging or recovery mechanisms. Implementing robust error handling isn’t just best practice; it’s essential infrastructure for reliable cloud automation.

Enterprise deployments demand structured, predictable error handling patterns that prevent cascading failures, enable rapid diagnosis, and allow graceful degradation when failures occur. This article explores the patterns and techniques that separate production-grade flows from prototype implementations.

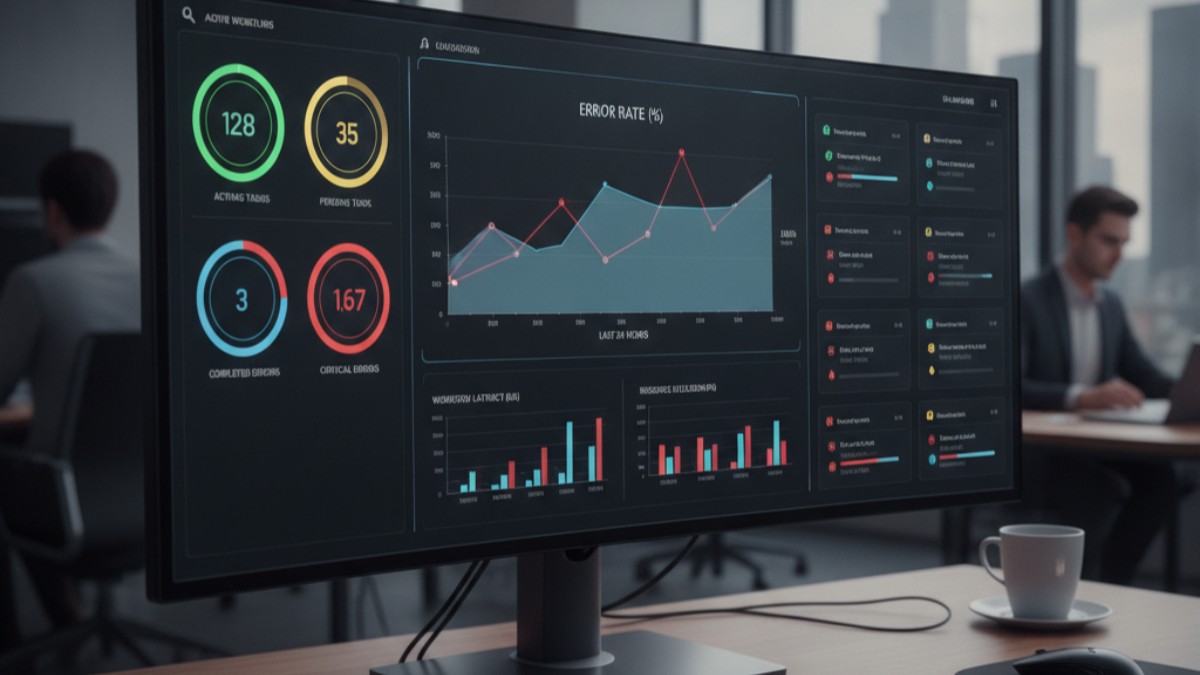
Professional dashboard showing real-time monitoring and error tracking for cloud automation workflows with status indicators and error rate graphs
Real-time error monitoring and tracking dashboard

One of the most insidious threats to enterprise automation is the silent failure—a workflow that appears to complete successfully but delivers corrupted data, skipped steps, or incomplete transactions. In Power Automate, uncaught errors compound this risk when operations fail without proper logging or recovery mechanisms. Implementing robust error handling isn’t just best practice; it’s essential infrastructure for reliable cloud automation.

Enterprise deployments demand structured, predictable error handling patterns that prevent cascading failures, enable rapid diagnosis, and allow graceful degradation when failures occur. This article explores the patterns and techniques that separate production-grade flows from prototype implementations.

Detecting and Classifying Errors

The foundation of error handling is visibility. Power Automate provides multiple error detection mechanisms, each suited to different scenarios:

Action-level error handling: Using “Configure run after” settings on each action lets you specify which states trigger conditional logic. You can configure actions to run on success, failure, timeout, or skip conditions. This approach is granular but can create complex conditional branches if overused.

Scope-based error handling: Wrapping related actions in a Scope action creates a logical transaction boundary. If any action within the scope fails, the entire scope transitions to a failed state. You can then configure error handling that applies to the entire scope rather than individual actions.

Try-catch patterns: Though Power Automate lacks explicit try-catch syntax, you can implement equivalent logic using scopes with nested conditional actions. A scope attempts operations; a parallel action monitors for failures and executes recovery logic.

Classification is equally important. Not all errors are equal. Transient network timeouts warrant automatic retry; authentication failures typically don’t. Data validation errors signal bugs in upstream systems and require investigation. By classifying errors according to their root cause and severity, you can implement proportionate responses.

Implementing Retry Logic

Retry logic is your first defense against transient failures. Power Automate HTTP actions support built-in retry policies with exponential backoff. For other action types, you implement retry using loops and counters:

Create a boolean variable “RetryNeeded” initialized to true, and a counter “Retries” initialized to 0. Wrap your operation in a Do-Until loop that continues while “RetryNeeded” is true and “Retries” is less than your maximum (typically 3-5 for transient failures). On success, set “RetryNeeded” to false. On failure, check the error type; if transient, increment “Retries” and let the loop continue. If permanent, set “RetryNeeded” to false and handle the error.

Exponential backoff is crucial: waiting 1 second, then 2, then 4, then 8 between retries reduces load on failing systems and increases success rates for temporary outages. Implement this using a Delay action whose duration scales with the retry count.

Always set a maximum retry count. Infinite retry loops mask underlying problems and consume flow runs unnecessarily. Three to five attempts generally balances resilience against resource consumption.

Structured Logging and Diagnostics

When errors occur, you need complete context: what was the input? What action failed? What was the error message? What was the state of related systems? Without this information, diagnosing failures in production consumes hours of investigation.

Implement structured logging by writing a standardized error record to a central log table immediately upon detecting failure. Include: timestamp (utcNow()), flow name and run ID (workflow().id and workflow().run.identity.id), action name, error message, error code, relevant data inputs, and severity level (critical, high, medium, low).

Store logs in a dedicated SharePoint list, a SQL database, or an Azure Table. Avoid relying solely on Power Automate’s run history UI; it’s designed for troubleshooting individual runs, not systematic analysis. A structured log enables you to identify patterns—which actions fail most often? Which error codes indicate configuration problems? Which failures correlate with specific input patterns?

Graceful Degradation and Fallbacks

Not every error requires stopping the entire workflow. Enterprise systems often tolerate partial failures if they degrade gracefully. An approvals workflow might succeed even if email notification fails. A data synchronization might proceed with historical data if the real-time source is unavailable.

Implement graceful degradation by identifying non-critical operations and wrapping them in error handlers that log the failure but allow the flow to continue. Use a “success” variable that starts true; non-critical action failures set it to false and log the error, but don’t stop execution. Upon completion, log the overall status as “partial success with warnings” rather than complete failure.

Fallback operations provide alternative paths when primary operations fail. If updating a primary database fails, write to an archive table. If sending to a preferred service fails, queue the work for later retry via a secondary system. If a required approval fails to complete, escalate to a manager rather than blocking indefinitely.

Monitoring and Alerting

Enterprise data center with server racks and network connections representing cloud infrastructure and automation systems

Structured logging is only valuable if someone monitors it. Configure automated alerts on your error log: if the error rate exceeds threshold, if a critical action fails repeatedly, or if specific error types appear. Use Power Automate itself to trigger alerts: a scheduled flow that queries your error log every hour and sends a summary to operational teams.

Alert fatigue is a real risk. Don’t alert on every error; many transient failures self-resolve. Alert on error rates exceeding baseline, on repeated failures from specific flows, and on critical errors. Include enough context in alerts that your team can begin investigation without accessing five different systems.

Dashboards that visualize error trends complement point-in-time alerts. A simple Power BI dashboard connected to your error log reveals which flows are deteriorating, which errors are emerging, and when flows became unreliable. This enables proactive maintenance before failures cascade.

Testing Error Paths

Errors happen in production, not in development. But you can test error handling by deliberately injecting failures. Create test flows that call your production flows with intentionally malformed inputs. Trigger HTTP actions against unreachable endpoints. Simulate database connection timeouts. Verify that errors log correctly and that alerts fire.

Version your error handling logic independently of feature logic. If you change retry counts, backoff intervals, or alert thresholds, test those changes in a lower environment first. A misconfigured retry loop that retries indefinitely is worse than no retry at all.

Enterprise Patterns in Practice

Real deployments combine these patterns. A robust data synchronization flow typically includes: scope-based error handling for logical transaction boundaries, retry logic with exponential backoff for transient failures, structured logging to every action, graceful degradation for non-critical operations, and monitoring that alerts on repeated failures.

A typical flow structure looks like: attempt primary operation in a scope; if scope fails, check error type; if transient, execute retry loop; if permanent, log and execute fallback operation or escalation; always log completion status (success, partial success, or failure).

The investment in error handling infrastructure pays dividends. Flows that handle errors gracefully recover automatically from transient outages without requiring manual intervention. Structured logs enable rapid diagnosis when problems do occur. Monitoring systems catch degradation before it becomes critical. Your team moves from reactive firefighting to proactive stability management.

About Routeget

Routeget specializes in enterprise automation architecture, helping organizations design and implement robust cloud workflows. Our expertise spans Power Automate, Logic Apps, and multi-cloud orchestration patterns. We help enterprises move from prototype implementations to production-grade systems that scale reliably.

Tags: #PowerAutomateErrorHandling #Dynamics365Development #CloudFlowPatterns #ErrorHandlingStrategy #PowerAutomatePatterns