Building Scalable Business Central SaaS Solutions: Multi-Tenant Architecture, Data Isolation, and Performance Optimization for Managed Service Providers

Building Scalable Business Central SaaS Solutions: Multi-Tenant Architecture, Data Isolation, and Performance Optimization for Managed Service Providers

If you are building managed services on top of Business Central, you face a recurring architectural tension. The platform wasn’t purpose-built for multi-tenant SaaS from the ground up the way pure cloud-native tools are. But it also cannot be treated as if each customer gets a separate on-premises deployment. The result is a set of hard choices about how to layer multi-tenancy, isolate data, scale databases, and manage performance when dozens or hundreds of customers share underlying infrastructure.

Most MSPs solve this by running one Business Central instance per customer (customer-dedicated), which is operationally simple but economically weak once you scale beyond a handful of tenants. Every new customer means a new database, new license costs, and new operational overhead. The alternative, true multi-tenancy (many customers in a single Business Central instance), unlocks economics but requires careful architecture to prevent performance collapse, ensure data isolation, and handle scaling.

The Multi-Tenancy Trade-Off

The starting assumption should be clear: Business Central’s native architecture is per-company, not per-customer. A Business Central instance can hold multiple companies, but the platform was designed for a single enterprise with multiple business units, not for multiple independent customers. Moving to true multi-tenancy (one instance, many isolated customer datasets) requires architectural work on top of Business Central, not within it.

The practical options are three. Customer-dedicated (one instance per tenant) is the operational baseline. Shared instance with logical isolation (one database, separate companies for each customer) reduces infrastructure costs but makes scaling harder and creates operational complexity around isolation enforcement. Shared database with custom isolation layer (true multi-tenancy, all customers in one company record with custom filtering) is the most economical and scalable but demands significant custom development and ongoing operational discipline.

Most established Business Central MSPs operate somewhere between the second and third model, typically starting with customer-dedicated and migrating to logical isolation as the customer base grows. The decision hinges on your customer profile. If you serve a small number of large enterprises, customer-dedicated is defensible. If you serve dozens or hundreds of small firms, the cost math favors shared infrastructure, but you must be willing to invest in isolation and multi-tenancy plumbing.

Data Isolation and Security Architecture

Once you commit to a shared instance, data isolation becomes your single largest technical and operational risk. A SQL query error, a batch job that doesn’t filter correctly, or a misconfigured permission can expose one customer’s data to another, which is a breach, a liability, and a loss of trust that no operational recovery can fully restore.

The first layer is at the database level. Even with logical separation (multiple companies), you are still operating within a single SQL database with a single set of users and roles. Business Central’s native security model (roles assigned to users, companies visible based on role membership) works for a single enterprise but is not designed to prevent a developer error from crossing company boundaries at the T-SQL level.

Practical isolation strategy: (1) All customer data must be tagged with a tenant ID, added to your core tables at the design stage, not retrofitted later. (2) Every report, batch job, form, and API call must filter on tenant ID at the table level before processing. This is not a UI-layer concern; it is a data-layer requirement. (3) Database permissions should be set so that application users and batch job service accounts have minimal direct SQL access. Most operations route through Business Central’s application layer and APIs, which give you a single enforcement point. (4) Audit and monitor large exports, bulk operations, and permission changes. (5) Separate test and production databases, and never allow production credentials to exist in test environments. (6) Document the isolation contract in your data model: which tables have a tenant ID column, which queries enforce it, which don’t (and why).

A common pattern is to add a TenantID integer to all major tables (Customers, Vendors, General Ledger Entries, Sales Orders), create a filtered view layer (SELECT * FROM Customers WHERE TenantID = @CurrentTenantID), and ensure all application code queries through views rather than directly against tables. This shifts isolation logic to a single place, making it easier to audit and less likely to be accidentally bypassed.

Database and Performance Scaling

When you share a database across many customers, performance becomes a shared-resource problem. One customer running a long-running batch job, generating a large report, or importing data can degrade responsiveness for all others if concurrency and resource contention are not managed.

Business Central sits on SQL Server, so conventional SQL scaling applies. For small deployments (under 20-30 concurrent users across all tenants), a standard SQL Server instance is adequate. Beyond that, you need active management. Index strategy matters more in multi-tenant contexts because a slow query now affects multiple customers simultaneously. Add a TenantID column to your major table indexes to ensure queries filtering by tenant are efficient. Monitor actual query plans and slow logs. Identify and tune the queries that run most frequently.

Connection pooling is critical. Each user session consumes a database connection. If you have 50 customers with 5 users each, that is 250 active connections under load. Business Central connection pooling can be configured via the Business Central configuration, but you should also run SQL Profiler periodically to verify connection reuse is actually happening and that idle connections are being recycled.

Workload isolation is the next tier. Business Central does not have native workload isolation (the ability to limit CPU or I/O consumed by one tenant’s queries). This means a misbehaving query from one customer can impact others. Some MSPs deploy a secondary read-only instance and route heavy reporting queries there, running the main instance for transactional work. Others implement query timeouts at the application layer, cancelling long-running operations before they escalate into broader performance problems.

For really high customer density, some MSPs partition data further, running multiple Business Central instances on different SQL databases, each managing a subset of customers, and routing traffic to the appropriate instance based on tenant ID. This increases operational complexity (monitoring, patching, deployment across multiple instances) but eliminates shared-resource contention. The right choice depends on your target customer density and the SLA you are committing to.

Operational Scaling and the Deployment Challenge

Multi-tenant architecture also changes how you deploy code. In customer-dedicated, you deploy customizations to each instance independently. In shared multi-tenant, you deploy once and all customers get the change. This is operationally cleaner but strategically riskier. A bug or incomplete feature benefits from being caught early and isolated to a small customer. Deploying to a shared instance means the bug affects everyone.

The mitigation strategy is staged deployment and extensive testing. (1) Maintain a canary instance that runs one real customer or a test customer. Deploy changes there first, run it for a period (days to weeks, depending on risk appetite), monitor, then promote to production. (2) Implement feature flags so you can deploy code without activating it for all tenants immediately. Roll out features to a subset of customers first, measure impact, then expand. (3) Develop a rapid rollback plan. If a deployment breaks, rolling back should take minutes, not hours. Keep a backup of the previous database state, have a tested restore process, and document it.

Operational Discipline and Monitoring

Multi-tenant architectures are only as strong as their operational discipline. Make tenant ID visible in monitoring and logs so you can isolate one customer’s database activity when they report slowness. Set up alerts on per-tenant CPU usage or transaction counts. Document your isolation assumptions, scaling limits (customers per instance, concurrent users), and escalation path. Communicate these limits to customers during onboarding so expectations are clear about when you may need to migrate a customer to a dedicated instance.

When to Re-Evaluate the Model

Multi-tenant architecture pays off when you have enough customers that the operational and infrastructure cost savings exceed the custom development and ongoing management burden. If you have fewer than 10 customers or expect to indefinitely, customer-dedicated is simpler. If you have 50 or more, multi-tenancy is almost certainly cheaper. The middle ground (10 to 50 customers) is where you need to actively decide, weighing your growth trajectory and engineering capacity.

The decision is also reversible. You can start customer-dedicated, measure actual growth, and migrate to multi-tenancy as customer density justifies the engineering investment. Many successful Business Central MSPs took this path, building the multi-tenancy layer only when economically justified.

Regardless of which architecture you choose, the foundation is the same: clear data isolation, disciplined code review, and monitoring that gives visibility into how each customer is using the system. These practices prevent the most common failure mode for SaaS businesses: one customer’s problem becoming everyone’s outage.


About Routeget Technologies: Routeget specializes in Business Central and Dynamics 365 implementation and managed services, working with MSPs to architect scalable SaaS solutions that operate reliably at customer densities of 50 to 500 tenants. Our architecture review and multi-tenancy design services help validate isolation assumptions and identify scaling bottlenecks before they impact customer experience.

#BusinessCentralSaaS #MultiTenantArchitecture #DataIsolation #CloudArchitecture #ManagedServices #BusinessCentral #Dynamics365 #SaaSArchitecture #DatabaseScaling #CloudComputing

Building Efficient Data Migrations into Business Central: ETL Patterns, RapidStart Configuration, and Real-Time Synchronization

Your legacy ERP implementation is seven years old. The system has grown brittle: custom fields have accumulated in unexplained places, vendor integrations rely on scheduled jobs that sometimes fail silently, and nobody quite knows why inventory positions don’t reconcile with the general ledger until month-end. You’ve committed to migrating to Dynamics 365 Business Central, and your implementation team is now staring at the reality that your current data is not structured the way Business Central expects it.

Data migration into Business Central is not a one-time ETL job. It’s a series of overlapping concerns: understanding Business Central’s data model constraints, designing transformation logic that can run repeatedly during pre-cutover validation cycles, choosing between built-in tools like RapidStart and custom integration patterns, and managing the transition from parallel-run validation to cutover-day data loading. Teams that treat migration as simply “extract, transform, load” often discover weeks into go-live that they have unresolved dependencies, incorrect intercompany eliminations, or missing dimension details that corrupt reporting. Teams that plan migration as an architecture pattern from the start avoid these problems.

Understanding Data Model Constraints

Business Central’s data model enforces relationships that many legacy systems do not. A sales line cannot exist without a sales header. A gl entry cannot post unless its balance sheet and income statement accounts match the financial dimension structure you’ve set up. Inventory transactions must have complete traceability back to a purchase or production order. These constraints are there for good reason, but they mean migration cannot be a simple row-by-row copy. Instead, migration requires understanding five key patterns: header-detail hierarchy construction, dimension and attribute mapping, data validation and cleansing orchestration, iterative migration cycles, and post-migration reconciliation.

Five Essential Migration Patterns

The first pattern is header-detail hierarchy construction. In your legacy system, you may have sales data stored flat, with the order header mixed with line-item details in a single table. Business Central separates them: every line must reference a parent header with a valid document number, customer account, posting date, and currency. More critically, Business Central validates business rules at load time. If a customer has a credit limit and your migration tries to load an order exceeding that limit without explicitly setting a flag to bypass the check, the load fails. The solution is to stage data in intermediate tables or external systems where you can construct the hierarchy correctly, apply validation rules intentionally, and load in dependency order: first headers, then lines, validating the relationship at each step. Tools like SQL Server Integration Services, custom PowerShell, or cloud-based ETL platforms such as Azure Data Factory allow you to perform this staging outside Business Central and load the validated result once, rather than attempting to transform data during the load process itself.

The second pattern is dimension and attribute mapping. Business Central’s general ledger uses dimensions (departments, cost centers, projects) to organize financial data. If your legacy system uses different dimension structures or names, you must map them before posting. Similarly, inventory items in Business Central require master data (unit of measure, costing method, posting groups) that your legacy system may not have captured consistently. For example, if you have items in the legacy system stored with a costing method inferred from transaction history rather than explicitly defined, you must resolve this during migration. Build a mapping table that documents how each legacy dimension value corresponds to a Business Central dimension, and validate that every financial transaction has a mapped dimension before loading. If legacy transactions have missing dimensions, decide whether to default them to a placeholder value, create ad-hoc dimensions during migration, or exclude them from the initial load and handle them separately. Document this decision in your migration specification so reviewers understand the trade-off.

The third pattern is data validation and cleansing orchestration. Business Central’s import tools (RapidStart for core setup and configuration, or manual import via templates and data providers) will validate your data against the system’s rules as you load. Some validations are obvious: an item cannot have a negative quantity on hand. Others are subtle: a sales order line for a discontinued item should fail unless the item is explicitly set to “blocked for sales.” Rather than discovering these failures during a timed cutover window, implement validation before loading. Write queries that identify duplicate master records, missing required fields, out-of-range values, and inconsistent hierarchies. Document the count of errors found and fixed for each category. This document becomes part of your cutover checklist, and it gives stakeholders confidence that edge cases have been identified and resolved rather than hidden.

The fourth pattern is iterative migration cycles. Your first migration run will not be your last. Between the initial data extract from the legacy system and final cutover, you may run ten or twenty test cycles. Each cycle should follow the same process: extract current data from legacy, apply transformations, validate results, load into Business Central, and reconcile key totals against the legacy system. Automate this cycle so it can be repeated without manual rework. Build a control table that tracks the source extraction timestamp, the count of records extracted, the count of errors found, and the final load status. If a subsequent cycle finds data inconsistencies (for example, an account balance that shifted between runs), your control table helps you understand whether the change occurred in the legacy system or in your transformation logic.

The fifth pattern is post-migration reconciliation. After you load data into Business Central, immediately run reconciliation reports that compare totals between the legacy system and Business Central: general ledger account balances, inventory quantities by location, customer account balances, and vendor payables. Discrepancies should be resolved before users begin transacting in the new system. Build reconciliation queries that group legacy and Business Central data by account, location, and customer, showing the legacy balance, the loaded balance, and the variance. If variances exist, do not assume they are the migration’s fault. Some discrepancies are expected because you may not migrate partial transactions (for example, a purchase order that was partially received in the legacy system may load as fully received in Business Central if you choose to migrate only the final state). Document the expected variance for each transaction type, and investigate any variance that falls outside the expected range.

RapidStart vs. Custom Integration

Choosing between RapidStart and custom integration deserves its own consideration. RapidStart is Business Central’s built-in data migration tool, designed for structured, relatively straightforward data imports. It excels at loading master data (customers, vendors, items, general ledger accounts) and provides UI-driven validation and error handling. If your migration is primarily master-data focused, RapidStart is efficient. If your migration includes complex transactions (intercompany eliminations, multi-step production orders, consolidated financial statements from multiple legacy systems), custom integration using Data Management Framework (DMF) or external tools gives you more control. Custom patterns also allow you to handle idempotency, the ability to run the same migration multiple times without creating duplicates or conflicting records. RapidStart migration can sometimes create duplicate records if run without careful cleanup. Custom patterns let you upsert (update if exists, insert if not) rather than always inserting, which is essential during iterative validation cycles.

A practical approach combines both. Use RapidStart for master data, which is relatively stable and can be validated in the UI. Use custom integration for transactional data, where you need more control, error handling, and the ability to reconcile against legacy totals. Implement idempotent logic that recognizes whether a transaction has already been loaded and skips re-insertion if the data is unchanged.

Building Long-Term Confidence in Data Integrity

Business Central migration is not fundamentally different from any ERP migration, but the specific constraints and tools require clear patterns. Header-detail hierarchy, dimension mapping, validation before load, iterative cycles, and post-migration reconciliation form the foundation. Teams that implement these patterns methodically reduce cutover risk, accelerate validation cycles, and build confidence that data integrity will be maintained as the business begins transacting in the new system.

Routeget Technologies has guided dozens of organizations through Business Central migrations, designing ETL patterns for complex legacy consolidations, building custom data providers that handle real-world ambiguities in historical data, and conducting pre-cutover validation that uncovers hidden data quality issues before they become cutover blockers. The work is detail-intensive, but the payoff is substantial: on-time go-lives, accurate financial reporting from day one, and users who trust the data they’re working with.

#BusinessCentralMigration #DataMigration #ETLPatterns #RapidStart #DataIntegration #BusinessCentral #ImplementationStrategy #DataQuality

Multi-Currency Operations and Exchange Rate Management in Business Central: Navigating Global Transactions with Confidence

Business Central multi-currency operations interface

Multi-Currency Operations and Exchange Rate Management in Business Central: Navigating Global Transactions with Confidence

Organizations operating across multiple geographies face a persistent challenge: managing transactions in foreign currencies while maintaining accurate financial reporting in their home currency. For midmarket companies expanding internationally, this challenge intensifies as foreign sales and sourcing become central to revenue and profitability. The cost of financial inaccuracy compounds across months of trading, creating either unexpected write-downs or inflated asset values that misrepresent organizational health to stakeholders and auditors alike.

Business Central addresses this directly through a built-in multi-currency framework that automates both conversions and accounting treatment of exchange rate fluctuations. Unlike manual spreadsheet-based approaches or systems that force workarounds, Business Central integrates currency management with general ledger posting, bank reconciliation, and financial reporting. This keeps your books accurate without requiring manual intervention after each transaction closes or demanding error-prone spreadsheet work during month-end.

Business Central multi-currency operations interface

The Problem With Currency Conversion At Scale

Most organizations begin handling foreign currency informally: receiving invoices in EUR or GBP, converting at the spot rate of the transaction day, and recording the home-currency amount manually. As transaction volume grows, this approach breaks down. Spot rates move daily. Which rate should you use for a purchase order placed Monday but invoiced Friday? When payment occurs three weeks later, the rate has shifted again. By year-end reconciliation, you have multiple rates applied to transactions in the same account with no clear audit trail of which rate was used when or why.

The financial statement impact is equally murky. Unpaid invoices in foreign currency represent unrealized gains or losses as rates fluctuate between transaction date and payment date. Without systematic adjustment, these gains and losses either go unrecorded until payment occurs or are manually estimated in spreadsheets, creating reconciliation risks and audit complications. For auditors and stakeholders reviewing financial statements, the inability to explain the currency position reliably signals weak financial controls over a core operational area.

Finance professional reviewing global transactions

Business Central solves this by enforcing a structured approach: every transaction in a foreign currency is recorded using a defined exchange rate, gains and losses are calculated algorithmically and posted to designated accounts in real time, and the entire history remains queryable and auditable.

How Business Central Structures Multi-Currency Operations

At its foundation, Business Central maintains a currency master file where each foreign currency you transact in is defined with an ISO code and associated exchange rates. You can enter rates manually through its Currency Exchange Rates interface, or configure external feeds to push rates automatically on a schedule you define. This choice affects both the frequency with which rates are updated and the operational overhead involved in maintaining current rates.

When you create a purchase or sales transaction in a foreign currency, Business Central records it using the exchange rate valid on the posting date. The system maintains this rate on the transaction itself, creating an immutable record of which rate was used for which transaction. This becomes critical when adjustments happen, because you can trace every change back to the posting date and its associated rate.

The exchange rate adjustment process, which Business Central runs via a batch job you schedule periodically (monthly is standard practice, though you can run it weekly or more frequently), is where the real financial control emerges. When exchange rates fluctuate between the posting date and payment date (or between posting date and month-end), Business Central calculates the unrealized gain or loss and posts it automatically. These adjustments hit designated accounts in your chart of accounts, which means they flow into financial reporting without manual journal entry and without the risk of being omitted.

For example, consider a 1,000 EUR invoice posted on January 1 at a rate of 1.12, creating a 1,120 home-currency liability. By month-end, the EUR strengthens to 1.125, and you run exchange rate adjustment. Business Central recalculates the liability to 1,125 and posts the 5-unit unrealized gain to your unrealized gains account. Three weeks later, when you actually pay the invoice and the rate is 1.12, the system reverses the unrealized gain and posts the realized loss, so your final cash outflow and gain/loss reflect the actual payment rate. This automation eliminates the reconciliation headache of manual currency adjustments and reduces the risk that period-end close occurs with outdated FX positions still in the books.

Implementation Considerations and Configuration Choices

Implementing multi-currency in Business Central requires deliberate choices about how rates are sourced and how gains and losses are distributed across your organization. The first decision is rate maintenance: will you update exchange rates manually through Business Central’s interface, or will you connect an external service to push rates automatically? For organizations with active trading in more than three or four currencies, automatic feeds significantly reduce operational overhead and eliminate the risk of a forgotten rate update that invalidates weeks of transactions. Business Central supports integration with common data services, and many organizations use this as part of a broader data automation strategy.

The second decision concerns the treatment of exchange rate adjustments across your chart of accounts. Business Central allows you to designate separate accounts for unrealized gains versus realized gains, and to choose whether those accounts roll up by currency, by customer/vendor group, or at the enterprise level. This choice affects how granular your FX reporting can be and what insights finance leaders can extract from the system.

A third consideration is the frequency of adjustment runs. Running exchange rate adjustment monthly is standard and aligns with close cycles, but some organizations run weekly, particularly if they have significant open positions in high-volatility currencies. Each adjustment run is reversible and can be previewed before posting, so running it more frequently carries minimal risk but does create more ledger entries.

For organizations with multiple legal entities, Business Central’s dimension functionality lets you attach currency exposure to any dimensional breakout you define. This means your FX reporting can follow your organizational structure.

Practical Benefits and Financial Outcomes

The operational benefit of Business Central’s multi-currency system is straightforward: it reduces the time and error risk in period-end close. Instead of manually identifying open foreign-currency items, looking up rates, calculating adjustments, and posting them as journal entries, the system does this automatically. For most organizations, this saves 2-5 hours of close time per month and eliminates one of the most error-prone manual steps.

The financial control benefit is more significant. Because all currency gains and losses are posted to the general ledger automatically, they cannot be overlooked. Every financial statement shows currency impacts accurately. For organizations evaluating Business Central against legacy systems, this multi-currency functionality is often a deciding factor, removing a category of financial risk that many organizations accept begrudgingly under their current systems.

Moving Forward

Organizations realizing the most value treat multi-currency not as compliance requirement, but as strategic capability. By maintaining clear system-based visibility into currency impacts, your finance team makes better decisions about hedging, payment timing, and currency-specific pricing strategies. This shifts currency management from necessary accounting chore to competitive tool.

Routeget Technologies helps organizations configure and optimize multi-currency operations in Business Central during ERP implementations and upgrades. If your finance team manages exposures through disconnected tools, or if you’re evaluating Business Central for your specific currency scenarios, we can walk through your environment and demonstrate how the system simplifies this complex area of financial operations.

#BusinessCentral #MultiCurrencyERP #ExchangeRateManagement #FinanceOperations #ERPImplementation #GlobalFinance

Business Central Production Scheduling: Why Visual Scheduler Configuration Fails When Demand Patterns Change

Production scheduling in Business Central sounds straightforward until you implement it at scale. The visual production scheduler promises drag-and-drop job sequencing and real-time capacity planning. Deploy it and discover that your demand patterns don’t fit the assumptions the system bakes into its default behavior. Planners revert to spreadsheets within weeks. The scheduler wasn’t broken; the configuration was incomplete.

The visual production scheduler in Business Central sits between shop floor execution and demand planning. It maps jobs to work centers, respects capacity constraints, and surfaces bottlenecks visually. But it works only when three conditions align: demand forecasts are stable, work center capacity is fixed, and job dependencies follow predictable patterns. Change any one of those, and the scheduler either produces schedules that don’t work or gets abandoned for manual planning.

Why Visual Scheduling Breaks Under Real Demand

Most implementations configure the scheduler once at go-live, assume demand won’t shift significantly, and leave it. Demand does shift. Seasonal patterns emerge. Customers request expedited jobs. Supply constraints force substitution of materials that process differently. The visual scheduler has no feedback loop; planners see outdated capacity assumptions in their schedules but have no way to tell the system that the underlying model has changed.

The core issue is that the scheduler operates on historical work center capacity and fixed routing assumptions. When a customer order arrives that doesn’t match the standard bill of materials or when a work center consistently underperforms its configured hours available due to changeover time or quality hold-ups, the scheduler still assumes standard capacity. Planners know the real constraint (the paint booth runs six hours a day, not eight, because of cure time between jobs), but the system doesn’t. Schedules become fiction.

Adding seasonality creates a secondary failure mode. Winter orders require different sequencing than summer demand. Heat-treating capacity bottlenecks shift based on product mix. The scheduler can’t recognize these seasonal patterns because configuration is static. A planner building schedules manually can say, “December through February, we prioritize thinner stock because it moves through coating faster.” The visual scheduler just sees jobs and available hours and proposes sequences that look optimal on the Gantt chart but fail in execution.

The Configuration Reality

Setting up the visual scheduler correctly requires knowing your capacity model in detail before you have execution data. That’s the uncomfortable truth. You need to define work center hours, parallel or sequential capacity, setup and teardown time, quality hold periods, material feed time, and routing flexibility. Get any of those wrong, and schedules drift immediately from what the system proposes to what planners can actually execute.

Most small and medium manufacturers don’t have this data documented at configuration time. They know their shop floor, but they don’t have it formalized into the work center master in Business Central. So they estimate. The estimates are close but not exact. Schedules are therefore slightly off from day one. The delta is small enough that planners don’t notice for weeks, but once they do, credibility in the tool evaporates.

Diagnosis: When Schedules Stop Matching Reality

The failure usually manifests as a mismatch between what the scheduler says can be done and what actually ships. A planner creates a schedule showing three jobs fitting into a work center in a day. The first job completes on time, but the second never starts because the first consumed more setup time than the system assumed. The planner gets blamed for a bad schedule. The scheduler gets blamed for being unrealistic. Neither blame is accurate; the system doesn’t know the real setup time.

Spot this problem early by comparing historical throughput data against scheduler assumptions. Pull actual shop floor execution history and overlay the capacity assumptions in each work center definition. If real throughput is 15 percent lower than configured, the system is optimistic. If throughput is 15 percent higher, the system is conservative (less common, but it happens when planners are very efficient or when the scheduler’s assumptions about parallel work are overstated). The gap is your calibration opportunity.

Three Production-Ready Fixes

The most effective fix is to build a demand-responsive scheduling loop. Instead of assuming demand is stable, capture actual demand patterns over a rolling window (usually 3-6 months of order data) and re-baseline the scheduler assumptions quarterly or semi-annually. This doesn’t require expensive plugins; it requires discipline in the operations team to review throughput variance and update work center capacity definitions when patterns change.

Second, implement a hierarchical scheduling approach. Use the visual scheduler for the primary constraint (often one critical work center) and leave everything else to manual planning or automated sequencing. Don’t try to optimize the entire job shop simultaneously; optimize the bottleneck. Everything else sequences around it. This reduces the configuration surface and makes the system more robust to planning changes.

Third, establish a feedback cycle between planners and the master scheduler. Every two weeks, have the planner who lives with the schedule review it and flag five jobs that were either much easier or much harder to execute than the system predicted. Feed those observations back into work center definitions. This is operational overhead, but it’s the operational overhead that keeps the scheduler aligned with reality instead of chart fantasy.

When to Accept Spreadsheets Instead

Not every manufacturer can or should use the visual scheduler. If your demand patterns change weekly, your jobs have highly variable routing, or your work centers have truly shared capacity across unrelated product families, the scheduler will always lag reality. In those cases, accept that planners will use spreadsheets or written job cards and build Business Central to support that workflow. Track scheduled completion dates and actual completion dates, but don’t pretend a static scheduler will optimize a fundamentally dynamic shop floor.

For manufacturers with repeatable products, stable demand patterns, and one or two clear bottlenecks, the scheduler is valuable. For job shops or custom manufacturers, it’s decoration.

Moving Forward

The visual production scheduler in Business Central is a tool, not a solution. It works best when you know your constraints and keep them documented. It fails quietly when assumptions drift from reality without anyone noticing until schedules stop matching execution. The organizations that sustain scheduler use treat it as a system that needs constant calibration, not a one-time configuration.

Start with the simplest possible scheduler setup: one work center, one product family, one demand pattern. Get that right before adding complexity. Use the first three months of data to calibrate. Then decide whether to expand or whether your planners are already doing a better job with their current method and the scheduler will just slow them down. That’s the conversation that happens too late in most implementations, when the scheduler is already abandoned.

About Routeget Technologies: With over a decade of Business Central implementation experience across discrete, process, and hybrid manufacturers, Routeget helps organizations design production planning systems that planners actually use. Our consultants focus on aligning system configuration with operational reality rather than forcing operations to match system assumptions.


#BusinessCentralManufacturing #ProductionScheduling #ManufacturingERP #JobShopScheduling #CapacityPlanning #BusinessCentral #SupplyChainOptimization #SmallManufacturing

Business Central Virtual Tables Eliminate the ETL Job Between BC and Dataverse. They Also Eliminate Half Your Filter Options.

Solution architect reviewing a real-time data integration visualization between enterprise systems

A solution architect scoping a Dynamics 365 Sales rollout for a distribution client recently asked a straightforward question: does the sales team need to see live Business Central order and inventory data inside their CRM records, or is a nightly sync job good enough? The honest answer took longer than it should have, because Business Central virtual tables, the feature Microsoft built specifically to answer this question, solve it only for a narrower set of scenarios than the AppSource listing and most walkthroughs suggest. The core mechanism works exactly as advertised. Where it falls short is rarely covered in the getting-started guides, and that gap is exactly where a scoping conversation needs to happen before anyone commits to an architecture.

Virtual tables have been positioned, correctly in most cases, as the end of a certain kind of integration project: the one where someone builds a scheduled job to copy Business Central records into Dataverse so Power Apps and Dynamics 365 Sales can read them. That job needs error handling, a schema that drifts every time BC gets a service update, and someone on call when the sync silently stops. Virtual tables remove that job entirely for read-heavy scenarios, just not for every scenario, and the difference is worth planning around before it’s discovered mid-build.

How Business Central Virtual Tables Actually Work

The Business Central Virtual Table plugin, published on AppSource, gives Dataverse a way to read and write Business Central records without copying that data into Dataverse storage. Under the hood, it consumes the Business Central API (v2.0), turns each endpoint’s response properties into virtual table columns, and maps the API’s own relationships into table relations that Power Apps and Power Automate can traverse like any native table. None of that translation happens on a schedule. Every query against a Business Central virtual table becomes a live OData call back to the Business Central tenant the moment a user opens a form, loads a subgrid, or a flow condition evaluates.

That real-time behavior is the actual selling point, and it’s a legitimate one. A Dynamics 365 Sales rep looking at an account record sees the customer’s current balance and open orders as they exist in Business Central right now, not as of last night’s sync window. There’s no data duplication to reconcile, no field mapping table to maintain as BC’s schema evolves, and no separate storage cost in Dataverse for records that already live somewhere else.

What Setup Actually Involves

Getting virtual tables running is a Power Platform admin task more than a developer task, which is worth knowing before anyone estimates the work. The solution installs from AppSource into a target Power Platform environment. Inside Business Central, an administrator enables the corresponding Microsoft Entra application, listed on BC’s own Entra applications page as the option for virtual tables. In Dataverse, the Business Central Virtual Data Source Configuration table needs the target BC environment name and a default company, since every request has to resolve to a specific company context.

Microsoft ships this as a set of managed solutions rather than one package: a company reference table every request depends on, the core plugin support, a catalog of tables available from the connected BC environment, and the generated virtual table definitions themselves. Because that catalog reflects the full breadth of Business Central’s OData surface, tables aren’t visible in Power Apps by default. An admin has to open the Business Central Configuration app and mark each table an app will use, a sensible governance control once you know it’s coming, and a confusing missing-table problem the first time you don’t.

Developer workstation displaying live data flow dashboards representing database integration

The Tenant Requirement That Ends Some Projects Before They Start

The detail worth checking on the first scoping call, not discovering three weeks into a build, is that the Business Central environment and the Dataverse environment must sit in the same Microsoft Entra tenant. For an organization that has run its Dynamics footprint under one tenant from the start, this is a non-issue. It becomes a real blocker for companies that grew through acquisition and still operate a separate Business Central tenant for a subsidiary, and it comes up constantly on engagements where a client’s CRM and ERP environments were provisioned years apart, sometimes by different vendors, under different tenants.

When that’s the situation, virtual tables aren’t an option regardless of how well everything else fits, and the project falls back to a conventional integration built on Power Automate flows against the Business Central API, or a dedicated integration platform between the two systems. Confirming tenant alignment costs a few minutes of checking admin center settings. Discovering the mismatch after a Power Apps screen is already designed around virtual tables costs a redesign.

Where the Filtering Restrictions Actually Bite

Because every virtual table query is a live OData call, the filtering grammar available to a Dataverse view or an advanced find is exactly as expressive as OData’s filter syntax, and no more. Predicates like does not equal, does not contain, does not begin with, and does not end with aren’t available. A view can’t combine AND and OR groups across different columns the way a native Dataverse table allows, and filtering on related tables or calculated fields isn’t supported either, nor are charts, attachments, images, or any BLOB-backed multiline text field built on a virtual table.

None of that shows up in a basic demo, which is the actual problem. A subgrid or gallery built against a virtual table for a first pass usually works, because the first pass rarely tests anything more demanding than “show me the open orders.” The gap surfaces once a real user asks for something like “show open sales orders where the requested ship date isn’t blank and the customer isn’t on credit hold,” a query needing a does-not-equal check on one column joined with an AND against a second. A native Dataverse table handles that without anyone thinking twice. A virtual table view can’t express it, and the fix ends up being either a purpose-built custom API on the Business Central side shaped for that exact query, or pushing the filtering logic into a Power Automate flow or a canvas app formula instead of the view. Either workaround is manageable, but only if someone anticipated it, and the tutorials rarely mention it exists.

Synthetic Relationships Connect the Models, But Only One Way

Virtual tables can also link to native Dataverse tables through what Microsoft calls synthetic relationships, letting a record like a Dataverse Account display related Business Central sales orders in a subgrid without custom plugin code. Building one means creating a foreign key on the native table first, then defining the relationship in the Business Central Configuration app’s Table Relations screen, mapping the native table’s key columns to the matching virtual table columns.

The relationship, once created, isn’t editable. Changing which columns participate means deleting it and rebuilding from scratch, and refreshing the underlying virtual table’s metadata while a relationship depends on it tends to throw errors rather than update quietly. The practical implication is to stabilize the Business Central side of the schema first: it’s far cheaper to adjust a Dataverse foreign key than to reconstruct several relationship mappings after a field gets renamed on the BC side. It’s also worth knowing upfront that relationships between two virtual tables aren’t supported at all, only between a native table and a virtual table, so an architecture chaining two Business Central entities purely through Dataverse relationships needs a custom API instead.

When Virtual Tables Are the Right Call

Virtual tables fit read-heavy scenarios well: a Power App or Dynamics 365 Sales form that needs current item availability, order status, or account balance without anyone owning a sync pipeline, where the filtering the business needs stays inside basic equality and straightforward AND logic. They’re a poor fit for anything involving attachments or images tied to BC records, analytics that need to chart or aggregate BC data directly, filter logic needing negation or mixed AND/OR groups, and any architecture spanning two Entra tenants.

The habit worth building into every Business Central to Dataverse integration scope is prototyping the specific filter and subgrid scenarios the business will actually use, not a generic list view, before the architecture is locked in. Almost every gap covered here only shows up once a real filter requirement meets OData’s grammar, and that’s cheap to test in the first week and expensive to discover after Power Apps screens are already built around the wrong assumption. Teams we’ve helped scope this kind of integration get the most value out of virtual tables when the tenant check and a short filter-requirements workshop are treated as the first two deliverables, not something left until a screen doesn’t do what the demo implied it would.

Virtual tables genuinely remove a maintenance burden that used to be permanent: the sync job nobody wanted to own, the schema drift nobody wanted to chase down. What they don’t remove is the need to know, before the architecture is set, exactly which filters, which tenant, and which record types the integration actually has to support.


#BusinessCentral #DataverseIntegration #VirtualTables #PowerPlatform #ERPIntegration #DynamicsConsulting

Business Central Doesn’t Ship a Visual Production Scheduler. Manufacturers Need to Budget for One.

A production scheduler pointing at a large touchscreen displaying a colorful Gantt-style production schedule in a factory control room

A finance director at a contract manufacturer we spoke with recently put it plainly: her company had spent seven figures moving off an aging NAV instance and onto Business Central, and the go-live checklist covered chart of accounts mapping, inventory valuation, and tax setup in exhaustive detail. Nobody on the project had asked how the shop floor supervisor would actually build tomorrow’s schedule. Three weeks after cutover, that supervisor was back to a whiteboard and a spreadsheet, because the production order list Business Central shipped with told him what needed to happen, not when it would fit around the machines he actually had.

That gap catches a lot of SMB manufacturers off guard, and it is worth naming directly: Business Central does not ship a visual production scheduler. It has a capable manufacturing module underneath, with production orders, routings, work and machine centers, and both finite and infinite capacity calculations. What it does not have, out of the box, is a Gantt-style planning board where a scheduler can see every order across every work center at once and drag one into a different slot. For a make-to-order or configure-to-order shop where the schedule changes twice before lunch, that missing piece is not cosmetic. It is the difference between planning and reacting.

What Business Central Actually Gives You Natively

It helps to be precise about where the native functionality stops, because vendors on both sides of this conversation tend to blur the line. Business Central’s core manufacturing app calculates capacity using calendars assigned to work and machine centers, supports forward and backward finite loading, and will flag overloads through capacity planning worksheets. A planner can run a capacity availability report, look at a load percentage by resource, and reschedule a production order’s dates through the order card. All of that is real, and for a job shop running a handful of routings with predictable sequencing, it can be enough.

Where it breaks down is visualization and speed of adjustment. The native screens are list-based: rows of orders, rows of capacity figures, filtered views that require a planner to hold the whole picture in their head. There is no single canvas that shows Order 4021 sitting on the CNC line from 2:00 to 6:00 while Order 4033 is queued behind it, waiting on a changeover. When a rush order lands, or a machine goes down mid-shift, the planner is reconciling several list views rather than looking at one board and dragging a block. That reconciliation work is exactly what visual scheduling tools were built to remove, and it is why the category exists as a distinct add-on market inside the Business Central ecosystem rather than a feature Microsoft has folded into the base product.

Where a Visual Production Scheduler Actually Fits

Search AppSource for Business Central manufacturing extensions and you will find several purpose-built scheduling tools, the most established being Netronic’s Visual Production Scheduler and its more advanced sibling, Visual Advanced Production Scheduler, alongside other entrants like Graphical Scheduler and MxAPS. These are not replacements for Business Central’s manufacturing data model; they sit on top of it, reading and writing directly to the same production order and capacity tables so nothing has to be exported to Excel or re-entered anywhere. What they add is the missing visual layer: a Gantt-style board that typically splits into two views, one answering “will I hit my delivery dates” by laying out orders against the calendar, and a second showing utilization by work or machine center so a scheduler can spot an overloaded resource before it becomes a missed shipment.

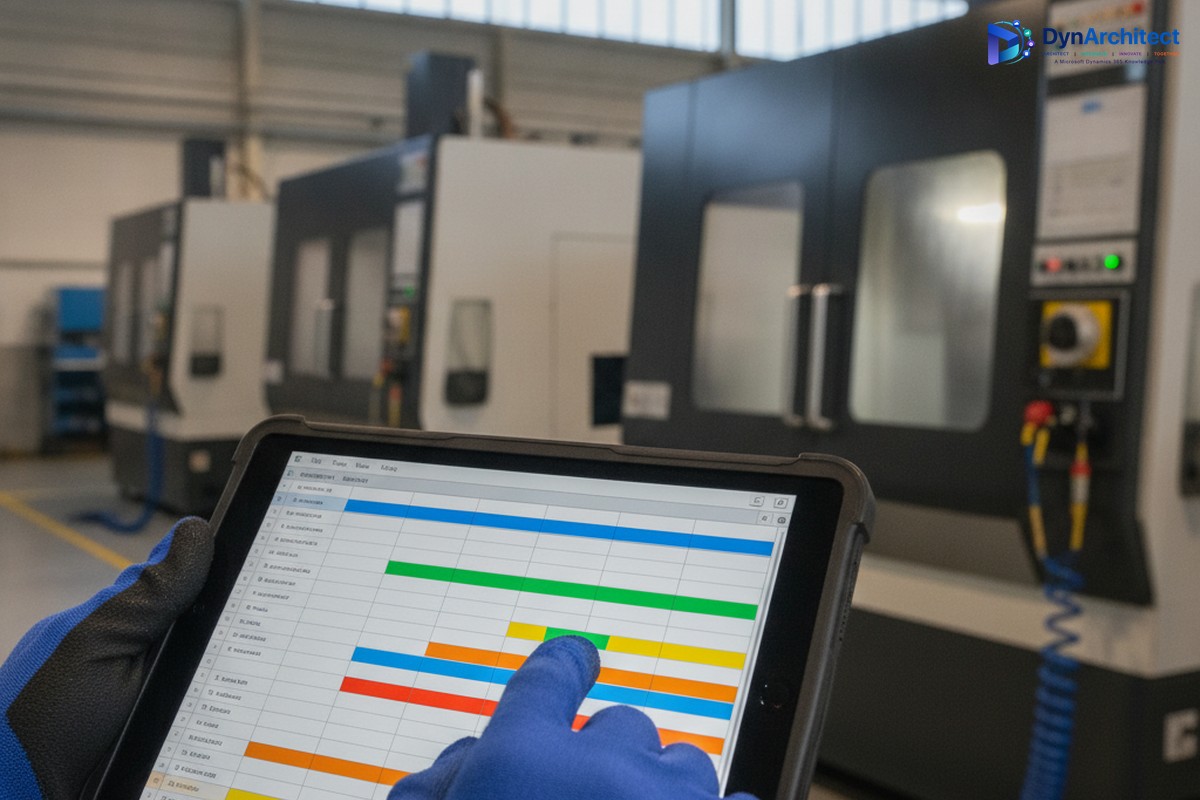
A shop floor worker holding a tablet showing a drag-and-drop visual production schedule next to CNC machining equipment

The interaction model is the actual value. Instead of opening a production order, changing a date field, and re-running a capacity check, a scheduler drags an operation block to a new slot and sees the conflict, or the lack of one, immediately. Reassigning an order from one machine center to another equivalent one takes the same drag-and-drop motion. Vendors in this space report meaningful gains in on-time delivery from customers who adopt this pattern, though as with any vendor-published figure, it should be treated as directional rather than a guaranteed outcome for every shop floor, since the actual result depends heavily on how disciplined the underlying routing and work center data already is.

The Decision a CFO or IT Director Actually Has to Make

None of this means every Business Central manufacturer needs a scheduling add-on on day one. A shop with two or three work centers and a stable, low-mix production schedule may genuinely be fine with the native capacity worksheets, and adding a third-party module there would be solving a problem that does not yet exist. The decision point is usually mix and volume: once a plant is juggling more than a handful of concurrent orders across multiple resources, with routing changes, rework, or expedites showing up weekly rather than monthly, the native list-based tools stop scaling with the complexity of the floor.

The practical mistake we see during Business Central selection and implementation projects is treating visual scheduling as something to revisit after go-live, almost as an afterthought bolted on once the finance and inventory modules are stable. That ordering gets the cost and the change-management burden backwards. Licensing a scheduling add-on is a separate line item, typically priced per named user or per environment, and it needs its own implementation time to map routings and work centers correctly, since the visual tool is only as good as the underlying capacity data it renders. Building that into the original project budget and timeline, rather than treating it as a post-go-live patch, avoids a second wave of user training and a second change request against a system that finance already considers “done.”

There is also a governance dimension worth flagging to IT: because these add-ons write directly back into core manufacturing tables, they need the same change-management scrutiny given to any other extension touching production data, including how they behave during version upgrades and whether the vendor maintains compatibility with the current Business Central release cadence rather than lagging behind it.

What to Ask Before You Buy

For a decision-maker evaluating this category, a few questions cut through most of the vendor marketing. First, does the tool read and write directly to standard Business Central production order and capacity tables, or does it maintain a shadow schedule that has to be reconciled back into the ERP, since the latter reintroduces exactly the synchronization risk the tool is supposed to eliminate. Second, does it support both finite capacity visualization and the specific constraint types your floor actually deals with, such as sequence-dependent changeovers or shared tooling across machine centers, rather than a generic Gantt view that looks good in a demo but cannot represent your real constraints. Third, what does the implementation actually involve beyond installing the extension, since the value of any visual scheduler depends entirely on routing and work center data being accurate before the drag-and-drop layer goes on top of it.

Getting this right is less about picking the “best” scheduling tool in the AppSource marketplace and more about being honest, early in a Business Central project, about whether the plant’s actual scheduling complexity requires this layer at all. Routeget has walked several manufacturing clients through exactly this evaluation during Business Central selection, and the pattern holds: the shops that budget for scheduling visibility from the start avoid the whiteboard relapse that pulls a supervisor back to manual planning three weeks after a system they were told would solve this problem for them.


#BusinessCentral #ManufacturingERP #ProductionScheduling #ShopFloorVisibility #ERPImplementation #DigitalTransformation

The Business Central Payables Agent Drafts Invoices. It Still Won’t Match a Purchase Order.

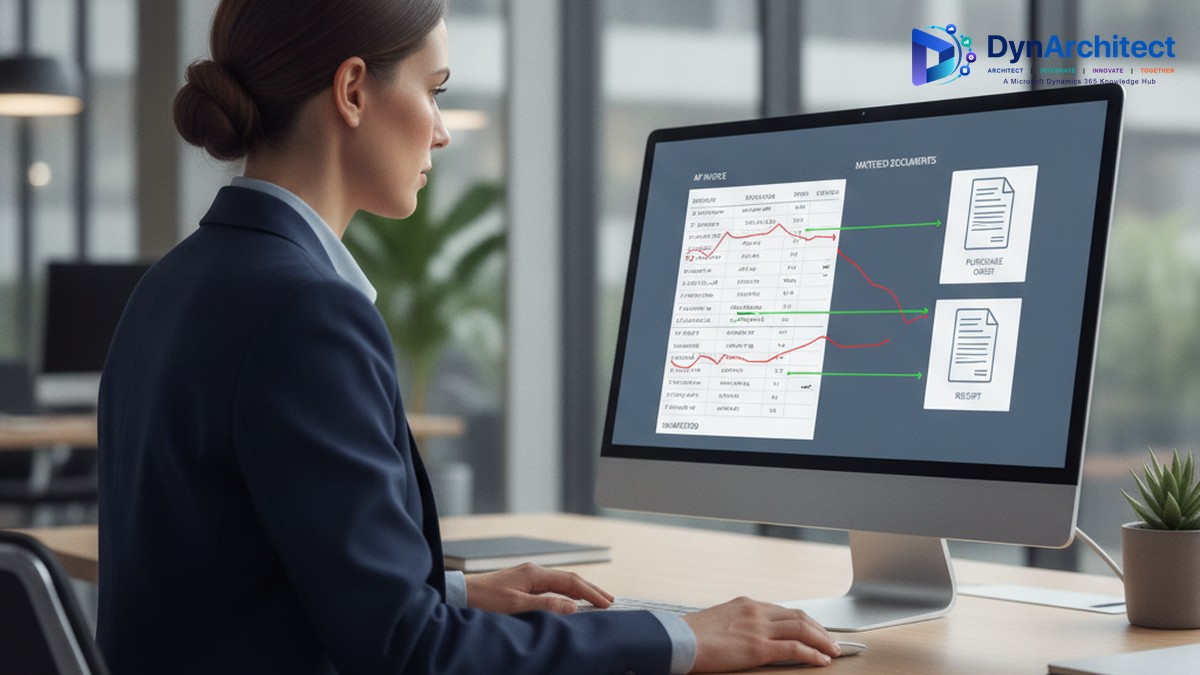
Finance professional reviewing an AP invoice matched against a purchase order and receipt on a computer dashboard

A controller at a mid-sized distributor recently described the moment her AP team realized what they’d actually bought. A vendor emailed a PDF invoice to the shared mailbox Business Central was watching, and within a few minutes the Business Central Payables Agent had pulled the vendor, mapped the line items to a G/L account, and dropped a fully drafted purchase invoice into the review queue. It looked like the AP clerk role had been automated away. Then someone asked whether the agent had checked the invoice against the purchase order or the goods receipt behind it, and the honest answer was no. It never does. Purchase order matching sits on Microsoft’s own published list of things the Payables Agent explicitly does not do, right alongside approval flows and anomaly detection.

That gap matters more than it sounds like it should, because Microsoft shipped a separate, unrelated feature in the same Business Central 2026 release wave that does handle order and receipt matching, and the two are easy to mistake for one connected capability. They are not. Understanding where the line actually falls is the difference between a rollout that genuinely reduces AP workload and one that quietly removes a control your finance team assumed was still there.

What the Business Central Payables Agent Actually Automates

The agent’s job starts and ends with turning an inbound PDF into a usable draft. It monitors a dedicated mailbox, pulls unread invoice emails, and runs each attached PDF through Azure Document Intelligence to extract the vendor name, amounts, and line detail. From there it tries to match the sender to an existing vendor record in Business Central; if it can’t do that confidently, it stops and asks a designated supervisor for instructions rather than guessing. When a new vendor genuinely needs to be created, the agent prefills the card from what it read off the invoice, but the record comes in blocked by default until a person reviews and releases it. Only after the vendor question is settled does the agent move to drafting the invoice itself, using historical purchasing patterns and item references to suggest which G/L accounts the line items belong to.

Finance professional reviewing an AP invoice matched against a purchase order and receipt on a computer dashboard

None of that becomes a posted transaction on its own. Every draft lands in a review queue where a human has to confirm, correct, or reject it before it becomes an actual purchase invoice, and Microsoft is direct about why: the agent’s account classifications and vendor matches “can be inaccurate,” and it has no way to evaluate business context the way a person reviewing the invoice would. That’s a reasonable design for what the agent is built to do, which is eliminate the manual keying and re-typing that eats the first half of most AP cycles. It is not built to answer the question of whether what you’re about to pay actually matches what was ordered and what showed up on the dock.

The Three-Way Match Gap Nobody’s Marketing Slide Mentions

Three-way matching, the practice of confirming an invoice against its purchase order and its receipt before payment, is the control most finance organizations rely on to catch overbilling, duplicate charges, and phantom deliveries. The Payables Agent doesn’t perform it. That’s not a bug or an oversight Microsoft is quietly working around; it’s a documented limitation, and as of this writing the agent itself is still labeled a public preview release rather than a finished, generally available feature.

What makes this genuinely confusing for a rollout is that the same 2026 wave 1 release also introduced “Match Purchase Invoices to Multiple Order and Receipt Lines,” a completely separate, non-AI capability built directly into standard purchase order processing. It adds a “Get Order Lines” action that surfaces received-but-uninvoiced or unreceived order lines, a “Matched Order Lines” page for reviewing and adjusting how invoice lines tie back to multiple purchase orders and partial receipts at once, and a “Receipt on Invoice” toggle that can auto-generate the receipt when a linked invoice posts. It reached general availability in April 2026, on its own timeline, with its own set of exclusions that keep it away from prepayment orders, item charges, projects, subcontracting, blanket orders, and intercompany transactions. Nothing in Microsoft’s documentation ties these two features together, and there’s no evidence the Payables Agent hands its drafts off into this matching workflow automatically. They simply shipped in the same release, aimed at the same purchase-to-pay process, and solve two different halves of the problem without talking to each other.

The practical result is that an AP team running the Payables Agent still needs to run invoices through order and receipt matching separately, whether that means the new native matching screens, an existing three-way-match process, or a third-party tool already in place. Treating the agent’s fast, clean drafts as evidence that matching already happened is exactly the kind of assumption that erodes a control environment quietly, one invoice at a time, until an audit or a duplicate payment surfaces the gap.

Consumption Billing Changes How You Budget for This

The licensing model adds a second layer finance leaders need to plan around before anyone flips this on for real volume. Copilot itself is bundled into Business Central’s Essentials and Premium subscription tiers, so the base chat and suggestion features a user sees day to day don’t carry a separate charge. Agents are different. The Payables Agent runs on Copilot Credits, a metered unit purchased through an Azure subscription, and consumption scales with how much work the agent actually does rather than with how many people are logged in. Microsoft’s own guidance is candid that it doesn’t publish a flat per-invoice rate; credit consumption depends on which features get used and what actions the agent performs on a given document, which means the honest answer to “what will this cost us” only comes from watching it run.

Hands comparing a printed purchase order against an invoice on a laptop screen during AP review

That variability lands at an awkward moment for most finance calendars. Invoice volume tends to spike at quarter-end and during seasonal peaks, which is precisely when a consumption-based bill is likely to jump, and precisely when a finance team has the least appetite for a surprise line item. Organizations used to a flat per-seat software cost don’t automatically have a forecasting habit built for variable, usage-driven spend, and marketing language that blurs “Copilot is included” with “the agent is included” doesn’t help anyone build one. There’s also a governance detail worth knowing before you assign ownership: viewing actual billing and consumption detail requires the SUPER or AGENT-DIAGNOSTICS permission set specifically. The narrower AGENT-ADMIN role that would typically administer the agent day to day does not, by itself, grant visibility into what it’s costing, so whoever ends up accountable for the Azure bill needs to be deliberately provisioned, not assumed.

What This Means for a Rollout Decision

None of this argues against adopting the Payables Agent. For an AP team drowning in PDF invoices that arrive by email in a single language, it removes a real chunk of manual entry, and the human-in-the-loop design means it isn’t going to post something wrong without a person signing off first. The documented ceilings are worth checking against your own volume before you commit to it as a strategy rather than a pilot: the agent tops out at 500 processed invoices and 100 monitored emails per day per environment, it’s validated for English only, it only reads PDF attachments up to a handful of pages and a few megabytes each, and it will not touch approval workflows or flag anomalies on its own. A high-volume, multi-language AP operation with heavy PO-based purchasing is going to run into those edges quickly.

The more useful framing for a CIO or CFO evaluating this isn’t “should we turn on AI for accounts payable.” It’s two separate questions that deserve two separate answers: does this reduce the manual work our AP team does today, and does it strengthen or weaken the matching controls we already rely on. The first answer, for the right invoice profile, is genuinely yes. The second, at least for now, is that the agent doesn’t touch that control at all, and the feature that does was built and shipped on its own, waiting to be adopted separately. Firms we’ve worked with on Business Central Copilot rollouts have had the smoothest results when they scoped the agent narrowly, ran it against real invoice volume for a full billing cycle before expanding it, and kept three-way matching exactly where it already lived rather than assuming the new AI layer had absorbed it.


#BusinessCentral #PayablesAgent #APAutomation #CopilotCredits #ThreeWayMatch #ERPGovernance

Business Central Expense Management Reaches GA in October. The License-Free Path Isn’t Actually Free.

Finance director reviewing an expense report approval dashboard in a modern office

If your Concur or Expensify renewal is sitting in front of your CFO this quarter, the timing is inconvenient. Microsoft is about to ship native Business Central expense management, a module inside Dynamics 365 Business Central that had been dismissed by practitioners as a minor, checkbox-only feature when it first appeared on the 2026 release wave 1 plan back in April. It no longer looks minor. Between the original release plan entry and the general availability date now set for October 2026, Microsoft quietly attached an AI-driven Expense Agent to the module that covers most of the ground people assumed only a dedicated T&E platform could handle: receipt scanning, mobile capture, email submission, mileage calculation, and policy compliance checks that flag violations before an expense report ever reaches a manager. For an IT Director or finance leader weighing whether to sign another year of a third-party contract, that changes the question from “does Business Central do expenses now” to “is it ready enough to consolidate onto, and what will it actually cost.”

Finance director reviewing an expense report approval dashboard in a modern office

What changed since Business Central expense management was first announced

When Business Central’s expense reports feature first showed up on the release plan, at least one well-known practitioner in the ecosystem publicly predicted it would fall flat. His reasoning was straightforward: without receipt capture, mobile submission, or corporate card integration, a native module was never going to pull organizations away from Concur or Expensify, tools built around exactly those capabilities. That skepticism was reasonable at the time, because the initial description of the feature read like a manual, form-based expense report tool bolted onto the general ledger.

What shipped alongside it in preview is a different story. The Expense Agent, which Microsoft documents as a production-ready preview feature, performs the parts of the workflow that used to require a third-party app: it reads a receipt image or PDF, extracts merchant, amount, date, and category, calculates mileage reimbursement against a configured company rate, and groups related expenses into a report automatically. Submission works through a dedicated web app, a mobile app with camera capture and offline support, direct email to an organization’s expense mailbox, or a Copilot chat interface inside Microsoft Teams. None of that requires opening Business Central at all. What Microsoft’s current documentation does not describe, at least not yet, is automatic reconciliation against corporate card statement feeds, a feature dedicated expense platforms have offered for a decade and that larger organizations in particular tend to depend on. That gap is worth watching, not dismissing; it may simply not have been documented yet ahead of GA.

The workflow, and who actually needs a Business Central license

The module organizes expenses through a status flow that will look familiar to anyone who has used a modern expense tool: Open, Pending Approval, Released, Approved, Rejected, Processed for Payment, and Completed. An employee can enter mileage, add participants to a shared expense, itemize a single receipt into multiple categories, or split a hotel bill into refundable and non-refundable lines when part of it (the minibar, say) falls outside policy. A manager reviews and approves or rejects from within that same flow, and an accountant posts approved reports to generate Expense Ledger Entries and drive reimbursement, with posting accounts controlled through Expense Categories and Expense Posting Groups an administrator sets up in advance.

Employee capturing a paper receipt with a smartphone for expense report submission

The detail that deserves the most attention from a finance leader is licensing, because it does not follow the pattern most Business Central features do. An employee who only submits expenses, whether through the web app, email, or the Copilot chat interface, does not need a Business Central license at all. That sounds like a straightforward cost win until you read the next line: that access method draws on Copilot Credits instead. Anyone who needs to open Business Central itself to manage or approve reports needs at minimum a Team Member license, and posting the reports and processing payment requires Essentials or Premium. So the module has effectively three separate cost levers rather than one: a consumption-based charge for expense-only submitters routed through Copilot Credits, a per-user subscription cost for anyone touching the module inside Business Central proper, and the underlying Essentials or Premium tier required to post anything at all. None of that is disclosed as a flat number in Microsoft’s documentation, which does not publish a specific Copilot Credit consumption rate for expense processing the way it has for some AI Builder scenarios.

Why that licensing structure matters more than the feature list

A CFO comparing this against a Concur or Expensify renewal is not just comparing feature checklists. They are comparing a predictable per-seat SaaS cost against a hybrid model where the cost of casual expense submitters scales with Copilot Credit consumption, a metric most finance teams have no historical baseline for. An organization with 40 people who occasionally submit an expense report and five people in finance who approve and post them will have a very different cost profile than one with 400 field employees submitting receipts weekly through the mobile app, even though both fit inside the same license categories. Before treating this as a straight replacement decision, it is worth actually modeling that consumption, not estimating it, because Copilot Credits behave differently from a fixed per-user fee and can move with usage in ways a traditional T&E contract does not.

There is also a timing consideration that is easy to overlook. As of this writing, the module and its Expense Agent are still labeled a production-ready preview, meaning Microsoft considers it stable enough to run in production but reserves the right to change it, and it operates under supplemental preview terms of use rather than Business Central’s standard product terms. October 2026 is the stated general availability date, but Microsoft’s own release plan documentation carries the standard disclaimer that projected functionality and delivery timelines may change. Organizations with a Concur or Expensify contract expiring in the next renewal cycle should treat October as a target to validate against, not a date to build a migration plan around before it actually happens.

What to do before the next contract renewal

The practical path for a finance or IT leader facing this decision now is a short, deliberate evaluation rather than an early commitment in either direction. Set up the module in a sandbox environment, route a real slice of a month’s expense volume through the Expense Agent’s mobile and email submission paths, and track how many receipts require manual correction after the AI extraction step, since the documentation itself notes that users should expect to review and correct results rather than trust them blindly. In parallel, ask your Business Central partner or internal admin to estimate Copilot Credit consumption against your actual expense submission volume, not a generic average, since that number is the one piece of this decision Microsoft has left for each organization to work out on its own. If your current Concur or Expensify agreement has a shorter renewal term available, or a month-to-month bridge option, that flexibility is worth paying for this cycle specifically so the decision isn’t forced before GA lands and the Copilot Credit math has a real quarter of data behind it.

None of this means the module isn’t a legitimate option. For organizations with straightforward expense policies, modest transaction volume, and no dependency on corporate card feed reconciliation, native Expense Management removes a genuine integration cost and keeps expense data inside the same ledger as everything else. Routeget Technologies has walked several Business Central clients through exactly this kind of licensing and consumption modeling ahead of a platform consolidation decision, and the pattern holds: the module’s capability gap has closed faster than the ecosystem expected, but the cost model needs its own diligence before it replaces a contract that already works.


#BusinessCentral #ExpenseManagement #ERPLicensing #CopilotCredits #FinanceTransformation #SMBERP #DynamicsBusinessCentral

Business Central’s Bank Reconciliation Copilot Went GA in 2024. The Docs Still Call It Preview.

Finance professional reviewing bank reconciliation Copilot matches on a laptop dashboard

A client’s controller asked a straightforward question during a recent Business Central scoping call: is the bank reconciliation Copilot feature safe to turn on for month-end close, or is it still something we should treat as experimental. The honest answer took longer to give than it should have, because Microsoft’s own documentation contradicts itself on this point. The 2024 release wave 2 plan lists general availability for “Complete bank account reconciliation faster with Copilot” as October 1, 2024. The current feature page and its companion FAQ, both carrying a May 2026 update stamp, still put “(preview)” in the title. For a firm advising clients on what they can rely on inside a signed statement of work, that gap between the release-plan record and the live documentation is not a footnote. It changes what you tell a client about support commitments, change-notice expectations, and whether the feature belongs in a production close process at all.

What Bank Reconciliation Copilot Is Actually Doing

Strip away the marketing language and the feature does two distinct jobs inside the Bank Acc. Reconciliation page. First, after Business Central’s standard rule-based automatch runs and leaves a set of unmatched bank statement lines, Copilot inspects the leftovers and looks for matches the deterministic engine missed, weighing transaction dates, amounts, and free-text descriptions together rather than requiring an exact rule hit. The example Microsoft uses in its own documentation is a single lump-sum deposit that actually represents five separate customer payments; automatch sees one bank line and five ledger entries and gives up, while Copilot can propose the one-to-many match. Second, for whatever remains genuinely unmatched, a separate Copilot action suggests a general ledger account to post the difference against, based on how the transaction description compares to your chart of accounts naming. A line that reads “Fuel Stop 24” gets proposed against a Transportation or Vehicle Expense account rather than sitting in a suspense account until someone investigates it manually.

Both actions are additive, not automatic. Nothing posts until a user reviews the proposed matches and explicitly selects “Keep it,” and the G/L suggestions can be saved into the Text-to-Account Mapping table so the same vendor description resolves the same way next month without asking Copilot again. That mapping table is worth building deliberately during rollout rather than letting it accumulate ad hoc, because it is the actual long-term efficiency gain here. The AI matching helps once; the mapping table helps every month after.

The status conflict, and why it matters for how you scope this

The release-plan record and the live docs cannot both be describing the same feature in the same state, so one of two things is true. Either the GA declaration from October 2024 covered only the base matching capability, and the newer G/L suggestion and mapping workflow that shipped afterward is what the current “(preview)” label actually refers to, or Microsoft’s documentation team simply never updated the page title when the feature graduated. Nothing in the current feature page, the FAQ, or the release-plan history explicitly resolves which of those is correct, and that ambiguity is the finding worth passing to a client rather than picking one interpretation and presenting it as settled fact.

Practically, this affects two decisions. The first is whether you commit to this feature working a specific way inside a contract, since preview features in Business Central online can change behavior without the same notice period Microsoft gives to GA capabilities. The second is how you frame it to the client’s audit or SOX-adjacent controls owner, who will reasonably ask whether a “preview” label means the output is less trustworthy. It does not mean that: the matching logic runs the same way regardless of the label, and the mandatory human review step is unchanged either way. But an auditor reading the page directly will see the word “preview” before they see your explanation, so raise it first rather than let them find it.

The entry-count ceiling most rollouts hit without noticing

The feature enforces a hard scan window: it only considers open bank account ledger entries dated between one day before the earliest bank statement line and the latest bank statement line, and it caps how many open entries it will process in that window. On 2025 release wave 1 and earlier, that ceiling sits around 1,000 open entries, depending on how long the description text runs. From 2025 release wave 2 onward, Microsoft raised it to roughly 3,000. Neither number is exposed anywhere in the user interface as a running count, so the first sign a client hits it is usually a reconciliation that used to surface a dozen AI-proposed matches suddenly surfacing none, with no error message explaining why.

For a company reconciling a single operating account monthly, 1,000 to 3,000 open entries is generous headroom. For a client running high-volume accounts payable through a single bank account, or one that has let old unapplied ledger entries pile up instead of writing them off, that ceiling is closer than it looks. Two mitigations are worth building into the rollout rather than discovering during a live close: confirm the client’s release wave version before promising Copilot behavior at a specific volume, and treat unusually old open ledger entries as reconciliation debt to clean up on a schedule, not just a reporting nuisance, since they silently consume slots in that scan window every single month.

Language alignment is a real constraint, not a compliance checkbox

Microsoft’s own guidance states plainly that matching accuracy depends on the G/L account names, ledger entry descriptions, and bank transaction descriptions all being in the same language, and that mixed-language data produces measurably fewer matches and suggestions. For a domestic single-language client this is a non-issue. For a multi-entity client running a shared chart of accounts across a US and a Mexico or Canada entity, where account names might be maintained in English but transaction descriptions arrive from a bank feed in Spanish or French, this is a concrete reason the feature will underperform in exactly the entity where the manual reconciliation burden is heaviest. Check the supported-language list against each legal entity’s actual operating language before setting client expectations, not after the first disappointing reconciliation run.

What the responsible AI documentation actually commits to

The FAQ is more specific here than most feature pages get, and it is worth quoting to a nervous data governance stakeholder rather than paraphrasing. Microsoft does not use company data, prompts, or Copilot responses to train its underlying models. Prompts and responses are retained as diagnostic data for twenty days, within the same geographic and compliance boundary as the rest of the company’s data, and that retained data is accessible only to Microsoft support personnel under existing Customer Lockbox controls. Usage telemetry is anonymized and excludes the actual prompts, responses, and customer data. None of this is unusual for a Business Central Copilot feature at this point in the platform’s maturity, but it answers the two questions a client’s compliance team will ask first, and having the citation ready saves a follow-up call.

Accountant reviewing AI-suggested bank transaction matches on a laptop dashboard

A rollout sequence that avoids the common failure mode

The most common way this feature disappoints a client is not a bad match, it is silence: a reconciliation runs, nothing gets proposed, and the user assumes Copilot is broken rather than assuming they hit the entry ceiling or a language mismatch. Enable the capability through the admin center first, confirm which release wave the client’s environment is on so you know the actual entry ceiling, and run the feature against one account’s real historical statement before go-live rather than a demo company, since Business Central’s built-in demo data is tuned to succeed and will not surface any of the above limits. During that test, deliberately build out the Text-to-Account Mapping entries for the client’s recurring, easily-categorized transactions, since that mapping table is what turns a one-time AI convenience into a permanent reduction in manual coding work. Finally, document the “Post if fully applied” auto-post option as an explicit decision rather than a default: it is convenient for a fully reconciled batch, but a client with a formal month-end sign-off process may want every AI-originated posting to pass through a human approval step regardless of match confidence, and that is a control decision worth having in writing.

Close-up of a bank statement reconciliation screen with matched and unmatched transaction lines highlighted

None of this makes the feature something to avoid. Two years after its stated GA date, the underlying matching logic is mature enough that Routeget now includes it as a standard discovery item on Business Central finance engagements, specifically so the entry-count ceiling and language dependency get surfaced during design rather than during the client’s first live close. The lesson is less about this specific feature and more about a pattern that shows up across the Copilot rollout in Business Central generally: the release-plan announcement and the day-to-day product documentation do not always stay in sync, and the responsible move is to check both before you tell a client what to expect, not just the one that sounds more finished.


#BusinessCentral #BankReconciliationCopilot #ERPIntegrations #FinanceAutomation #DynamicsFinanceOps #ResponsibleAI

Power BI Semantic Model Refresh Just Got Granular. Your Dynamics 365 Reports Still Refresh Everything.

A solution architect reviews a data refresh and capacity monitoring dashboard on a large screen at night

A Fabric capacity dashboard turning red at two in the morning is one of the more specific kinds of dread in Dynamics 365 reporting work. Somewhere in the tenant, a scheduled job kicked off a full refresh of a forty-table semantic model built over Dataverse-linked Finance and Operations data, and now every other overnight pipeline is queued behind it. The general ledger fact table alone might carry a decade of posted transactions. None of that history changed since yesterday. It gets reloaded anyway, because until recently, “refresh” in Power BI meant one thing: everything, from scratch, every time.

That default is finally negotiable. Power BI’s August 2026 update made granular semantic model refresh controls generally available in both Desktop and the service, giving report owners a real choice between refreshing schema, refreshing data, or refreshing both, down to the level of an individual table. For anyone maintaining Power BI models over Dynamics 365 F&O, Business Central, or Dataverse data more broadly, this is the kind of change that should prompt an actual architecture review rather than a shrug and a changelog skim.

What changed, specifically

The expanded Refresh control in Power BI Desktop and the service now exposes three distinct operations instead of one. Refresh Schema and Data is the familiar default: Power BI checks the source for structural changes, applies them, and then reloads data. Sync Schema Only updates the model’s structure, picking up new or renamed columns and data type changes, without pulling fresh rows. Refresh Data Only does the opposite: it reloads current values while deliberately ignoring any structural drift at the source, which matters more than it sounds like it should when a source system adds a column you have no interest in modeling yet.

Critically, this granularity now applies at the table level through the UI itself, not just through a REST call. Select a table in the Data pane, and you can choose to refresh its schema, its data, or both, independently of what happens to the rest of the model. Under the hood, this builds on the Enhanced Refresh API’s objects parameter, which has supported table- and partition-level targeting in JSON refresh requests for several years. What is new is that the capability is no longer something you had to script or automate through Power Automate to get; it is a first-class option in the interface most report authors actually use.

The timing lines up with Direct Lake’s move to general availability for OneLake semantic models in March 2026. Direct Lake models query OneLake data at query time instead of importing it into a separate in-memory copy, which changes what “refresh” even needs to accomplish. A schema-only sync is explicitly called out as the more sensible operation for many Direct Lake scenarios, since the underlying data is already current in OneLake and what actually needs updating is the model’s awareness of structural changes upstream.

Why Dynamics 365 semantic model refresh costs add up fast

Generic BI advice treats all semantic models as roughly interchangeable, but Dynamics 365 F&O and Business Central models have a particular shape that makes blanket full refreshes disproportionately expensive. A handful of tables, typically the ones behind AP aging, open sales orders, or current inventory positions, change constantly and need frequent, current data. Most of the rest of the model, historical GL transactions, closed projects, prior fiscal years, is functionally read-only from one day to the next. When Fabric Link or the older entity-store approach lands both categories in the same semantic model and a nightly job refreshes the whole thing on one schedule, the model pays the full cost of reprocessing static history every single time it wants fresh numbers for the tables that actually moved.

That cost shows up in two places that matter to whoever owns the Fabric capacity bill. Wall-clock refresh duration extends as historical fact tables grow, which is a slow-motion problem that eventually collides with the maximum refresh duration ceilings on shared and Premium capacity. And CU consumption on Fabric capacity is metered by the compute the refresh operation actually performs, so reprocessing unchanged partitions burns capacity that has no analytical payoff. Neither problem is solved by adding capacity; both are solved by refreshing less.

Applying granular refresh to a Dynamics 365 semantic model

The practical starting point is an honest table-by-table audit of your existing model, sorted by two questions: does this table’s data actually change day to day, and does its schema drift when Microsoft ships a Finance and Operations or Business Central update. Tables like open transactions, current inventory on-hand, and active project status are obvious candidates for a Refresh Data Only cadence that runs frequently, maybe hourly if the business case justifies it, without touching schema at all. Large historical fact tables, closed fiscal periods, and reference dimensions that rarely change structure are candidates for a much less frequent Refresh Schema and Data pass, perhaps weekly, with the understanding that if Microsoft renames a field or adds a column mid-week, you will not see it in the model until the next scheduled schema sync.

Abstract illustration of a few illuminated data table blocks refreshing among many dimmed, unchanged ones

Where this pairs particularly well with existing Power BI capability is incremental refresh policies on the largest transaction tables. Incremental refresh already partitions a table by date so that only the current period’s partition gets reprocessed on a routine basis; layering table-level refresh selection on top means you can decide, table by table, whether even that partitioned refresh needs to run tonight or can wait until the weekend. For a semantic model spanning several Dynamics 365 legal entities, this combination is usually the difference between a refresh job measured in tens of minutes and one measured in hours.

Implementing this through the Enhanced Refresh REST API rather than clicking through the UI is worth the extra setup for any model refreshed on a schedule, because it lets you express the table list as configuration rather than tribal knowledge sitting in someone’s memory of which tables to click. A request that targets specific tables through the objects array, with applyRefreshPolicy set appropriately for whether you want the incremental refresh window respected, is straightforward to build and far easier to audit six months later than a manual process. Teams running Power Automate flows or Azure Data Factory pipelines to orchestrate refreshes should treat this as the moment to replace a single “refresh the whole dataset” call with a small set of targeted requests, each on its own cadence.

Where this still needs judgment, not just configuration

Schema-only sync deserves particular caution in Dynamics 365 contexts because Microsoft’s release cadence for F&O and Business Central genuinely does add and rename fields with some regularity, and a model that never runs a full schema sync will eventually diverge from its source in ways that surface as confusing blank columns or broken relationships rather than clean errors. A reasonable middle ground is to schedule schema syncs on their own cadence, independent of data refreshes, rather than skipping them indefinitely because a table’s data refresh doesn’t need one.

It is also worth being explicit with report consumers and downstream teams about which tables now run on which schedule, since the old assumption that “refreshed this morning” meant the entire model was current no longer holds once refresh granularity is in play. A short data dictionary note next to each table, or a dedicated tab in the workspace documentation, prevents the kind of confusion where someone builds a decision on a historical table that was deliberately left out of last night’s run.

The architecture conversation this actually forces

The real value of granular refresh isn’t the UI convenience, it’s that it forces a semantic model design conversation that most Dynamics 365 reporting teams have been avoiding: which tables in this model are operational and which are archival, and should they even live in the same refresh schedule, or the same model, at all. Teams that have this conversation now, while the tooling to act on the answer just became native to the product, will end up with leaner Fabric capacity bills and faster refresh windows than teams that keep treating every semantic model as a single monolithic refresh unit. At Routeget, this is usually the point in a Fabric or Power BI engagement where we walk a client’s existing model inventory table by table rather than accepting the assumption that a full nightly refresh is simply the cost of doing business with ERP-scale data.


#PowerBIRefresh #SemanticModels #DirectLake #FabricCapacity #DynamicsFinanceOps #BusinessCentral