Power Apps Governance and Scaling: Building Enterprise Applications Without Creating Technical Debt

Enterprise Power Apps governance dashboard with application portfolio metrics and CoE framework

Problem Statement (Opening Hook)

Six months after launching your Power Apps initiative, you have 47 applications built across the organization. You’re congratulating yourself on driving digital velocity when IT discovers that 23 of those apps are querying the production Dataverse directly without connection audits, three apps are storing passwords in Power Automate flows, and nine apps were built with Dataverse tables that now conflict with the enterprise data model you’re implementing for Dynamics 365. You also cannot tell which apps are critical, which are experimental, and which are duplicates of work already done by other teams. This is not a Power Apps problem. This is a governance problem, and the cost of fixing it later vastly exceeds the cost of defining it now.

Why Power Apps Governance Matters at Scale

Power Apps succeeds because it is low-code. Business teams move faster. IT provisioning cycles shrink from months to days. Without governance, organizations end up managing application sprawl rather than portfolio. They face compliance risks when applications store regulated data without proper encryption. They accumulate technical debt through duplicate apps and integration spaghetti. Most critically, they lose the ability to retire old applications because no one remembers dependencies.

Governance does not mean blocking innovation. It means setting up boundaries so innovation happens inside a framework that scales. Done well, governance feels like enabling guardrails rather than restrictive rules.

The Three Pillars of Effective Power Apps Governance

Governance across Power Platform breaks into three interdependent areas: application lifecycle management (ALM), data governance, and access control. Each addresses a different aspect of operational risk, and each requires clarity before you have hundreds of applications in production.

ALM defines how applications move from development to test to production, who approves releases, and how rollback works. Without ALM discipline, applications get updated without testing and deployments happen without documentation. Microsoft Power Platform’s ALM tooling (solution containers, source control integration, deployment pipelines) is mature. Using it from the first application, rather than retrofitting later, saves significant effort.

Data governance specifies which Dataverse tables are available to which applications, which fields those applications can read and write, whether applications have direct table access or go through a custom API layer for auditing, and how data synchronization happens when multiple applications share tables. Organizations that skip data governance often discover halfway through Dynamics 365 F&O implementation that Power Apps developers were extending the General Ledger table directly, bypassing the compliance logic built into the F&O ledger posting engine. Starting with a canonical data model and enforcing read-write boundaries prevents those conflicts.

Access control governs who can create applications, what permissions they have, whether they can publish to production, and what user-level permissions applications inherit. Many organizations default to giving all users “create” permissions in Power Platform, then react with panic when app sprawl becomes visible. Instead, defining roles and mapping them to permission levels creates scalability. Skilled developers need broad creation rights. Business power users need constrained environments where they can build applications without affecting production infrastructure.
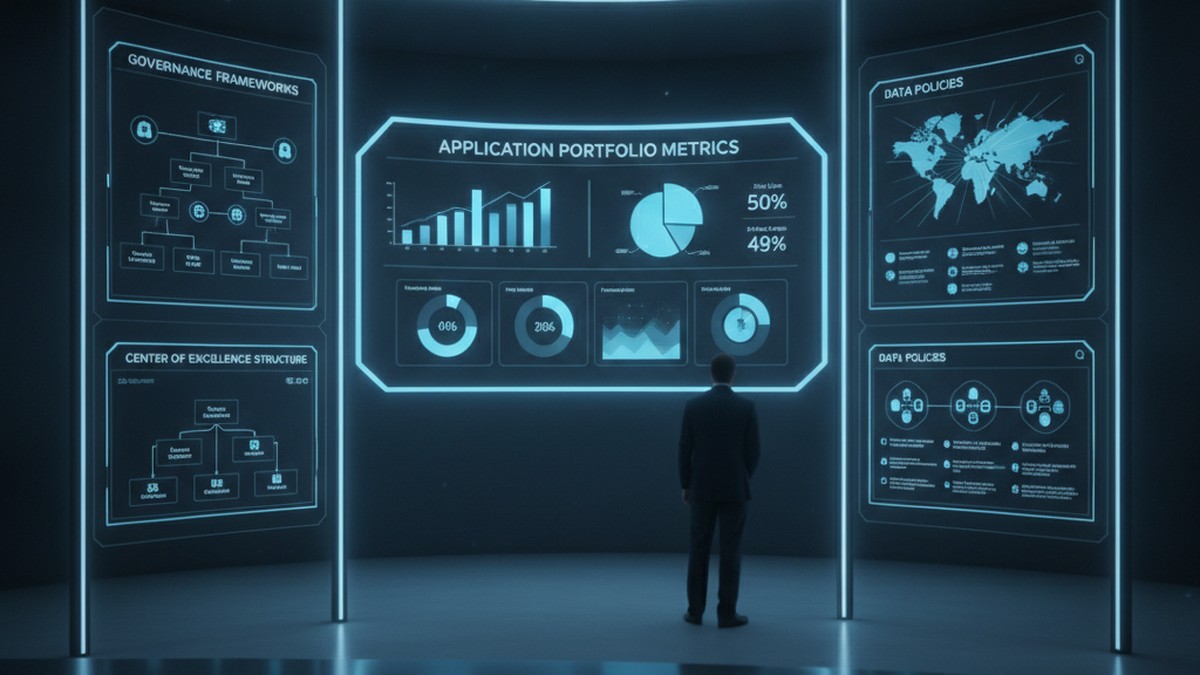
Enterprise Power Apps governance dashboard with application portfolio metrics and CoE framework

Common Governance Failures

Most organizations make one of three mistakes. The first is defining governance so rigorously it kills velocity. Requiring sign-off from multiple committees before publishing an app causes teams to work around the process in unsanctioned environments. The second mistake is defining no governance at all. Teams build freely until compliance audits arrive. Retrofitting governance then requires temporarily shutting down production applications to audit and repair them. The third mistake is defining governance on paper without technical enforcement. Policies exist but the actual permissions and Dataverse configurations never match. Effective enforcement requires embedding governance into administration, not just culture.

Effective governance finds the middle ground. It sets clear, enforceable boundaries while leaving room for teams to innovate within those boundaries. It is documented not in slides but in the actual configuration of your Dataverse, your solution containers, and your deployment pipelines.

Building a Practical Governance Framework

Start with application classification. Tier applications by criticality: mission-critical (runs the business and cannot fail), important (supports major business process and needs monitoring), and experimental (proof-of-concept or exploratory work). Mission-critical and important applications get the most scrutiny. Experimental applications get looser controls. This prevents governance overhead from killing innovation while ensuring critical work gets appropriate rigor.

Next, establish your Dataverse data architecture before widespread application development begins. Define which tables are canonical and which are read-only views or replicas. Specify who owns each table. Set up row-level security policies and field-level permissions. If applications bypass the model, audit logs show it. This enforces a single version of truth and prevents applications from accidentally conflicting.

Implement solution containers and source control integration. Every application goes into a solution container, not deployed loose to the environment. Solutions are version-controlled in Git. Deployments go through a clear pipeline: development environment, test environment, staging, production, with manual gates between stages. Automate testing at each stage where possible. This creates an audit trail of every change and makes rollback possible.
Enterprise development team collaborating with ALM workflows and CI/CD pipelines on display monitors

Set up a governance review board (often called a CoE governance committee) that meets monthly to review application portfolio health, approve new high-risk applications, and identify applications for retirement. The board includes IT architecture, security, compliance, and business process representatives. This is not a blocking committee. It is an enabling committee that helps teams navigate governance boundaries and flags risks early.

Finally, communicate governance as infrastructure, not as restriction. Frame governance conversations around what it enables: faster time to production for compliant applications, easier integration with enterprise systems, reduced security risk, and the ability to retire old applications without cascading failures. Teams that understand the rationale behind governance adopt it voluntarily.

Technical Debt and Long-Term Maintenance

Technical debt in Power Apps manifests quietly. An application built against a local Dataverse table works fine for six months until the enterprise decides to synchronize that table with Dynamics 365. The app breaks because its queries now hit a different data source. Another application stores customer IDs in a text field. When customer ID standards change, updating that field breaks any app that relied on the old format. A third application has hard-coded access credentials buried in flows. When those credentials rotate, the application goes dark.

These failures happen because applications were not architected for change. Avoiding technical debt requires discipline upfront: use API layers instead of direct table access, parameterize configuration values, separate data schemas from application logic, build retry logic into integrations, and document dependencies. It also requires governance processes that periodically review applications for architectural drift.

Balancing Speed and Control

The tension between moving fast and maintaining governance is real. The resolution is not to choose one or the other, but to acknowledge that different applications need different levels of control. A dashboard for business analytics needs different governance than an application that writes to the General Ledger. A proof-of-concept application needs different processes than a mission-critical customer portal. Tailoring governance to the application’s role allows you to move fast where speed matters and deliberate where risk is highest.

Organizations that execute this balance well report that governance, once established, does not slow velocity. If anything, it accelerates it. Teams know the boundaries. Deployments are predictable. Integration is straightforward. Failures do not cascade. Applications retire cleanly. The cost of operating the Power Platform ecosystem decreases even as the number of applications grows.

Building for Sustainable Scale

Power Apps’ promise is that business teams can build applications without IT intermediaries. Realizing that promise at scale requires intentional governance, not despite that governance, but because of it. The organizations building the most applications fastest are the ones with the clearest governance frameworks. They have defined what good looks like. They enforce it technically. They review it regularly. They adjust it based on what they learn.

If your organization is still in the early stages of Power Apps adoption, spending time now on governance infrastructure saves vastly more time later. If you are already in growth mode with sprawling applications, implementing governance means making deliberate choices about which applications to migrate to ALM pipelines first and which to retire. Either way, the question is not whether to govern Power Apps at scale. The question is how quickly you can build governance that enables scale rather than constrains it.

Routeget Technologies works with organizations across this journey, from establishing governance frameworks and Center of Excellence operations to implementing ALM pipelines and data architecture for large-scale Power Platform deployments. The difference between organizations that scale Power Apps sustainably and those that end up in technical debt rework usually comes down to governance discipline established early and reinforced consistently.

#PowerAppsGovernance #PowerPlatformCoE #ApplicationLifecycleManagement #LowCodeGovernance #EnterpriseArchitecture #DataverseGovernance #PowerAppsDevelopment #DigitalTransformation

Building Custom Dataverse Plugins for Real-Time Business Logic: Architecture Patterns and Deployment Strategies

Custom plugins remain one of the most powerful yet misunderstood levers in the Microsoft Dataverse platform. While Power Automate handles lightweight workflows and Power Apps provides UI automation, plugins solve a different problem: they execute business logic in response to Dataverse operations with the performance and security model of server-side code.

The challenge most organizations face isn’t whether to build plugins. It’s determining which problems *require* plugins versus which can be solved with lower-code alternatives. When plugins are the right answer, the next challenge becomes: how do you design, test, and deploy them in a way that scales without becoming a maintenance nightmare?

**The Real-Time Constraint Problem**

Dataverse operations happen in a transactional context. When a record is created, updated, or deleted, plugins can intercept that operation at two points: pre-operation (before the database transaction) or post-operation (after commit). This matters because pre-operation plugins can modify the data before it’s saved, validate input with business rules, or prevent the operation entirely. Post-operation plugins can trigger downstream processes once the change is safely committed.

Many organizations treat these as interchangeable. They aren’t. A pre-operation plugin that makes an external API call can block the user’s operation for as long as that call takes. A 5-second timeout becomes a frozen user interface. Scale that across hundreds of concurrent users, and you’ve created a denial-of-service vulnerability in your own system.

The architecture decision here determines whether your plugin becomes a reliable part of the system or a bottleneck that gets disabled during peak load because it’s failing too many operations.

**Three Plugin Execution Patterns**

The first pattern is synchronous validation. Pre-operation plugins should validate, transform, and enforce business rules before data is saved. They should execute in milliseconds. Any operation that takes longer—external API calls, complex calculations on large datasets, cross-system lookups—should be moved to a separate execution path. This pattern prevents bad data from ever entering the system. A pre-operation plugin validating that a customer’s credit limit isn’t exceeded, or that a purchase order references an active supplier, should complete in 50-200ms. If your logic can’t hit that target, it belongs in an async plugin.

The second pattern is asynchronous post-operation actions. After a record is safely committed, a plugin can trigger downstream effects without blocking the user’s operation. Sending notifications, updating related records in other tables, integrating with external systems, or kicking off approval workflows all belong in post-operation async plugins. These execute outside the user’s transaction and can tolerate higher latency. A 5-second external API call in a post-operation async plugin is acceptable. The same call in a pre-operation plugin is a performance problem.

The third pattern is event-driven architecture. Rather than having plugins orchestrate complex multi-step processes, plugins emit events that external systems subscribe to. A change to an opportunity triggers a plugin that publishes the event. A separate microservice (Azure Function, Logic App, or external system) consumes that event and decides what happens next. This decouples your Dataverse plugins from downstream business logic and lets you evolve downstream systems without changing your Dataverse model.

Each pattern solves a different problem. Synchronous validation makes the data layer trustworthy. Asynchronous actions keep the user’s experience snappy while still triggering necessary side effects. Event-driven architecture makes the system resilient to change.

**Registration and Filtering Strategy**

A common mistake is registering plugins on every attribute change when only a few attributes matter. If your plugin only needs to react when the Status field changes, don’t register on “all attributes.” Instead, register specifically on the Status attribute. This cuts the plugin’s execution count dramatically and improves overall system performance.

Filtering also applies to message types. A plugin doesn’t need to fire on every Create, Update, and Delete. It can fire on Update only. Combine message filtering with attribute filtering, and you’re executing your logic only when it’s actually needed.

Stage selection matters too. Pre-operation runs before validation, so it’s useful for modifying data before validation rules apply. Pre-operation 10 (earliest) runs before pre-operation 20 (later). Post-operation runs after the transaction commits and is useful for downstream actions. Each stage has a purpose; using the wrong stage adds latency where it isn’t needed.

**Testing and Deployment**

Plugin code runs server-side, with access to the organization’s data and permissions. A poorly written plugin can corrupt data at scale. Testing is not optional.

Unit tests should cover the logic of your plugin independent of Dataverse. Integration tests should run the plugin against a Dataverse environment and verify it behaves correctly. Deployment should happen through an Application Lifecycle Management (ALM) pipeline: develop in a sandbox, test in a staging environment, deploy to production only after validation.

One pattern that simplifies testing is moving the core business logic out of the plugin class and into a separate, testable library. The plugin becomes a thin wrapper: extract the input from the Dataverse SDK, call your logic library, and apply the result back to the execution context. This makes unit testing trivial and keeps your plugin logic independent of Dataverse framework details.

**Common Mistakes to Avoid**

Unintended recursion is a classic issue. A plugin modifies a record, which triggers the same plugin again, which modifies the record again, and so on until the system reaches a depth limit and throws an error. Prevention requires tracking execution depth and skipping logic if the current execution is a plugin-triggered update rather than a user-initiated change.

Another mistake is sharing state across plugin executions. Plugin instances aren’t persistent; each execution creates a new instance. Trying to use static variables to pass data between plugin invocations leads to race conditions and unpredictable behavior.

Excessive synchronous API calls create bottlenecks. If your plugin makes 10 external API calls sequentially, and each takes 500ms, your plugin runs for 5 seconds. Users experience 5-second operations for record updates. Move those calls to post-operation async or to a separate integration service.

**Moving Forward**

Dataverse plugins are not obsolete. They’re essential for enforcing business logic at the data layer, but they’re not the only tool. Modern Dataverse implementations combine plugins for critical synchronous validation, Power Automate flows for multi-step post-operation actions, and external microservices for complex integrations. The plugin’s job becomes focused: validate and transform data in real time. Anything else should run asynchronously or outside the transaction.

Routeget Technologies’ experience scaling plugin architectures across large Dynamics 365 deployments shows that the teams that succeed are those that treat plugin development as seriously as they treat any server-side code—with rigorous testing, clear ownership, and architectural intent behind every decision.

#DataversePluginDevelopment #DynamicsArchitecture #CloudIntegration #ServerSideLogic #ALMPipeline #PluginArchitecture #EnterpriseDataManagement #Extensibility

Power Apps Delegation Limits Don’t Throw an Error. They Just Give You the Wrong Answer.

Solution architect reviewing a data table dashboard on a large monitor, illustrating enterprise data query review

A finance team at a mid-size distributor built a canvas app to flag overdue receivables. It worked perfectly in every demo. Then it went into production against a SharePoint list that had grown past 4,000 rows, and the “overdue balance” total the app displayed started coming in a little low every week, never wildly wrong, just quietly off by a shrinking or growing margin depending on how the underlying data happened to sort. Nobody got an error message. Nobody got a warning banner in the running app. The gallery rendered, the total summed, and the number was simply incomplete, because Power Apps had silently stopped looking at the data after the first 500 records.

That is the practical shape of a delegation problem, and it is one of the more consequential gaps between how canvas apps behave in the maker’s testing environment and how they behave once real data volume shows up. Power Apps delegation limits determine whether a formula gets pushed down to the data source, which processes it server-side and returns only the matching rows, or whether Power Apps has to pull a bounded chunk of records locally and evaluate the formula against that chunk alone. When delegation fails and the underlying table is larger than the configured limit, the app does not stop working. It keeps working, on a subset of the data, without saying so.

Why Power Apps delegation limits fail silently instead of crashing

A crash gets fixed immediately because someone notices. A silently truncated query gets fixed only when someone happens to reconcile the app’s output against the source system and finds a discrepancy, which in the receivables example took several weeks. For a technical team supporting Dynamics 365 or Power Platform deployments, this is the argument for treating delegation as an architecture decision made at design time, not a performance tweak applied after a slow gallery gets noticed.

The default data row limit in a canvas app is 500 records, adjustable up to a hard ceiling of 2,000 in the app’s Settings under General. Raising that number is a common instinct and a bad one to rely on as a fix, because it just moves the cliff edge further out rather than removing it; a table with 50,000 rows behaves identically whether the limit is set to 500 or 2,000; it only changes how much data has to grow before someone notices something is wrong. Microsoft’s own guidance for this reason recommends the opposite move during development: set the limit down to 1 in a test environment, which forces every non-delegable formula to reveal itself immediately with obviously wrong results, rather than leaving that discovery to production data volume.

What actually gets delegated, and what does not

Power Fx delegates a meaningful set of operations against supported data sources, including Dataverse, SharePoint Online, SQL Server, and Salesforce. Filter, Search, LookUp, and First all delegate, as do the standard comparison operators, And, Or, Not, StartsWith, EndsWith, and the core aggregates: Sum, Average, Min, Max, CountRows, and Count. Sort and SortByColumns delegate as well, with an important caveat covered below for SharePoint. The In operator delegates too, but only against a column on the base table; the moment a formula tests In against a related or lookup column, delegation breaks and the query falls back to local evaluation.

Developer typing Power Fx formula logic on a laptop with a monitor showing abstract code in the background

The non-delegable list is longer and easier to trip over than most makers expect. FirstN, Last, and LastN do not delegate. Neither does If, which means embedding conditional logic inside a Filter predicate is a common way a formula that looks delegable quietly is not. String manipulation functions including Left, Mid, Len, Lower, and Upper are non-delegable, along with Concatenate and the & operator, GroupBy, Ungroup, and type-casting functions like Text and Value. Collect and ClearCollect are non-delegable by nature, since they materialize data locally rather than querying it. A formula like Filter(Fruit, Mid(FruitName, 1, 1) = “A”) looks reasonable and reads cleanly, but because Mid cannot be pushed to the data source, it only ever evaluates against the first page of records pulled locally, meaning a record named “Pineapple” sitting past row 500 will never match a search for names starting with “P,” not because the logic is wrong, but because the function never sees that row.

SharePoint makes this worse than Dataverse does

Anyone who has built canvas apps against both SharePoint lists and Dataverse tables has felt the difference in how forgiving each source is, and the gap is documented, not just anecdotal. SharePoint does not delegate relational comparison operators (less than, greater than, not-equal) on plain text fields at all, only equality. IsBlank does not delegate against text fields either, and the commonly suggested workaround, comparing to Blank() directly, does not behave identically for genuinely empty strings versus null values, which is a subtle correctness gap worth documenting in code review rather than discovering in production.

The bigger gap sits in SharePoint’s complex column types: Choice, Lookup, Person, Group, Task Outcome, Managed Metadata, and External Data. None of these support delegated sorting, so Sort or SortByColumns against a Choice or Person field will silently fall back to sorting only the locally retrieved page. StartsWith does not work against subfields of Choice or Lookup columns. Person and Group fields only delegate on their Email and DisplayName subfields, not on other properties. A set of SharePoint system fields, including ContentType, ModerationStatus, VersionNumber, and several path-related fields, do not delegate under any function at all. UpdateIf and RemoveIf against SharePoint are handled through a batching simulation bounded by the same 500/2,000 record limit rather than a true server-side delegated operation, which matters for any flow that bulk-updates list items from within the app rather than through Power Automate.

Dataverse does not eliminate delegation limits, but it closes most of these specific gaps: relational operators work against text columns, In delegates on base-table columns consistently, and sorting against lookup and choice columns behaves as makers expect. For any canvas app expected to scale past a few thousand records with complex filtering or sorting, that difference is a legitimate factor in the SharePoint-versus-Dataverse decision, not just a licensing or governance one.

Designing around it instead of hoping around it

The most reliable pattern is to push complexity toward the data source rather than the formula bar. Where a filter needs to test a derived value, calculated columns created in Dataverse (or, with more limitation, in SharePoint) let the comparison happen against a pre-computed, delegable field instead of a runtime string function the client has to evaluate locally. Where a search needs to match across multiple text fields, Search() itself delegates and is usually a better first attempt than a hand-built Filter with concatenated conditions, since it is one of the few functions built specifically to delegate substring matching.

For teams supporting these apps in production rather than just building them, the practical safeguard is process, not just formula discipline: run the app with the row limit forced to 1 during test cycles, review any gallery, dropdown, or KPI tile driven by a filter or sort against a table that could plausibly exceed a few hundred rows in production, and treat a yellow delegation warning triangle in Power Apps Studio as a defect ticket rather than a cosmetic nag to dismiss. The warning is not a suggestion about performance. It is Power Apps telling the maker, in the only language it has, that the number on screen may not represent all of the data.

We’ve walked enough Dynamics 365 and Power Platform clients through exactly this kind of discovery, usually during a post-go-live support engagement rather than a planned architecture review, to treat delegation as a first-week design conversation on every canvas app project involving a table that is expected to grow. It is a cheap conversation to have early and an expensive one to have after a finance report has been quietly wrong for a month.


#PowerApps #PowerFx #CanvasApps #Dataverse #SharePointOnline #EnterpriseArchitecture #LowCodeDevelopment

Dataverse Plugin Packages Are Code-First Now. Your Azure DevOps Pipeline Still Has to Script Around Them.

Solutions architect and developer reviewing a Dataverse deployment pipeline diagram on an office monitor

A solutions architect on a mid-size D365 F&O implementation recently ran into a problem that had nothing to do with business logic. Her team had finally moved their plugin assemblies into proper NuGet-based Dataverse plugin packages, the newer code-first model that the Power Platform CLI now supports directly. The build worked. The package generated correctly. And then the pipeline stalled, because nobody could answer a simple question: how do you tell Azure DevOps to actually deploy the thing you just built, when Microsoft’s own build tools extension has no task for it?

That gap is worth understanding in detail, because it sits at the exact point where Dataverse plugin development is genuinely improving and where its ALM tooling has not caught up.

Solutions architect and developer reviewing a Dataverse deployment pipeline diagram on an office monitor

From Manual Registration to Code-First Packages

For most of the last decade, deploying a Dataverse plugin meant compiling a class library in Visual Studio, opening the Plugin Registration Tool, and manually selecting an assembly to register or update. It worked, but it kept plugin deployment outside the discipline that governs everything else in a mature ALM pipeline: predictable artifacts, versioned builds, and a repeatable path from commit to environment.

The Power Platform CLI changes that equation with two commands: pac plugin init, which scaffolds a plug-in class library project, and pac plugin push, which imports the resulting artifact into Dataverse. The output of a build is no longer a loose assembly file. It is a NuGet package, generated automatically in the bin\outputPackages folder on every build, containing the plugin assembly and its dependencies bundled together. That single change, treating the plugin as a proper package rather than a file you happen to compile, is what makes plugin code finally look like the rest of a modern .NET pipeline.

What Dataverse Plugin Packages Actually Solve

The practical win is dependency handling. Under the old model, any third-party or shared library your plugin referenced had to be merged into the assembly or registered separately, and both approaches created their own headaches around versioning and duplication across solutions. A plugin package bundles dependent assemblies inside the same NuGet artifact, so the whole thing deploys and updates as one unit.

Signing works differently here too, and it is worth getting the policy decision right early rather than discovering it mid-project. Microsoft’s own guidance is explicit that signing is all-or-nothing: if the primary plugin assembly is strong-name signed, every dependent assembly in the package must be signed as well. Most teams find this impractical once they start pulling in third-party libraries they do not control, which is why pac plugin init exposes a --skip-signing flag, and why it has effectively become the default choice for anyone using dependent assemblies rather than a single self-contained plugin.

The Immutability Trap

Here is where the model’s real character shows up, and where a team can get burned if nobody flags it in advance. Once a plugin package is created in Dataverse, its name and version are fixed. An attempt to change either afterward, including through the API, simply fails. Every build produces a package with a new version embedded in its filename, which means there is no such thing as “redeploy the same package again.” Each build is a new, uniquely identified artifact from Dataverse’s point of view, whether you intended that or not.

That has two consequences that matter for pipeline design. First, if a plugin update removes an assembly or a type that is still referenced by an active plugin step registration, Dataverse rejects the update outright. You have to go remove or repoint those step registrations first, then update the package, not the other way around. Second, you cannot unregister a package at all while any of its assemblies still have active step registrations attached to them. Both rules are sensible from a data-integrity standpoint, but they mean plugin retirement has to be sequenced deliberately: deregister the steps, confirm nothing else depends on the assembly, and only then remove or replace the package.

One independent practitioner account, documented on the .NET Dust blog in 2024, captured how disruptive the versioning behavior can be during ordinary iterative development, well before any pipeline is involved. Because pac plugin push has no built-in notion of “the current build,” the developer had to script around it: an MSBuild target increments the file version before compilation, a post-build event persists that value into the project file through a small helper utility, the NuGet package picks up the new version automatically, and only then does an automated pac CLI call push the exact resulting filename. What should be a single command turned into a four-step workaround, built by one engineer, to get a repeatable local deployment loop. That is a reasonable thing for an individual developer to solve on their own machine. It is not something you want reinvented independently by every team building a Dataverse ALM pipeline.

The Build Tools Gap

That last point is the one worth taking to whoever owns your ALM strategy. Microsoft’s Power Platform Build Tools extension, the standard toolkit for Dataverse pipelines in Azure DevOps and GitHub Actions, covers an extensive set of operations: importing, exporting, packing, and unpacking solutions, applying upgrades, managing environments, running the Power Platform Checker, and even a preview set of catalog-submission tasks. Reviewing the current task reference, plugin packages and pac plugin push are not among them. There is no first-class, Microsoft-supported pipeline task for deploying a plugin package, in contrast to the mature tooling that already exists for solutions.

In practice, that means every team adopting code-first plugin packages has to write its own pipeline stage: typically a script task that installs a pinned version of the PAC CLI, authenticates against the target environment (a service principal, not a personal login, for anything beyond a developer sandbox), locates the build output, and issues the push. None of that is exotic engineering. It is, however, unsupported custom scripting sitting next to a set of Microsoft-maintained tasks that get security updates, documentation, and predictable behavior across CLI versions. That asymmetry is easy to miss until a CLI update quietly changes an argument name and a script that nobody has looked at in eight months starts failing in production.

Developer typing on a laptop with a monitor showing an abstract NuGet package deployment graphic

Building This Into an ALM Pipeline Properly

A few decisions are worth making explicit rather than leaving to whichever developer happens to write the first plugin deployment script. Pin the PAC CLI version in the pipeline definition itself, not just on developer machines, so a CLI upgrade cannot silently change push behavior in production. Treat the plugin push step as its own reviewed pipeline stage with the same environment gating and approval flow as solution deployment, rather than a script someone bolted on during a sprint to unblock a release. Decide the assembly-signing policy at the team or center-of-excellence level, since the all-or-nothing signing rule effectively locks in a convention for every future package once dependent assemblies enter the picture.

Sequence retirements carefully. Before removing or consolidating an old plugin package, confirm which step registrations still point at it and clear those first, since Dataverse will otherwise block the change regardless of what your pipeline script assumes should happen. And build the versioning logic into the pipeline itself, following the pattern the .NET Dust workaround demonstrated, rather than trusting a developer’s local environment to produce a consistently versioned artifact that a shared pipeline can then find and deploy.

None of this makes the code-first plugin package model a bad idea. It is a genuine improvement over registering assemblies by hand through a desktop tool, and it brings plugin code closer to how the rest of a .NET codebase is built and shipped. The catch is that Microsoft shipped the authoring half of that story before the deployment half, and the gap between them is exactly where implementation teams are currently improvising. Firms that have already built Dataverse ALM pipelines from the ground up, Routeget Technologies among them, have generally closed that gap with a small, explicitly maintained script stage rather than an ad hoc one, which is the difference between a pipeline that survives a CLI version bump and one that quietly breaks the next time someone updates it.


#Dataverse #DataversePlugins #PowerPlatformALM #AzureDevOps #ExtensibilityAndProDev #EnterpriseArchitecture