Dynamics 365 Omnichannel for Customer Service: Real Service Management Starts After Configuration Ends

Omnichannel Customer Service Featured

Omnichannel for Customer Service in Dynamics 365 promises a single, unified workspace where agents handle customer interactions from email, chat, social media, and phone without context switching. The promise is compelling: less time hunting between systems, faster resolution, better customer experience.
Omnichannel customer service dashboard in Dynamics 365

The reality is more complicated. Configuration is one thing. Operating omnichannel at scale—where fifty agents handle thousands of interactions daily across five channels—is another. Many organizations configure Omnichannel correctly in a test environment, deploy to production, and then discover that the system they built doesn’t match how work actually flows in a busy contact center.

Omnichannel’s Foundational Premise: Unified Workload Management
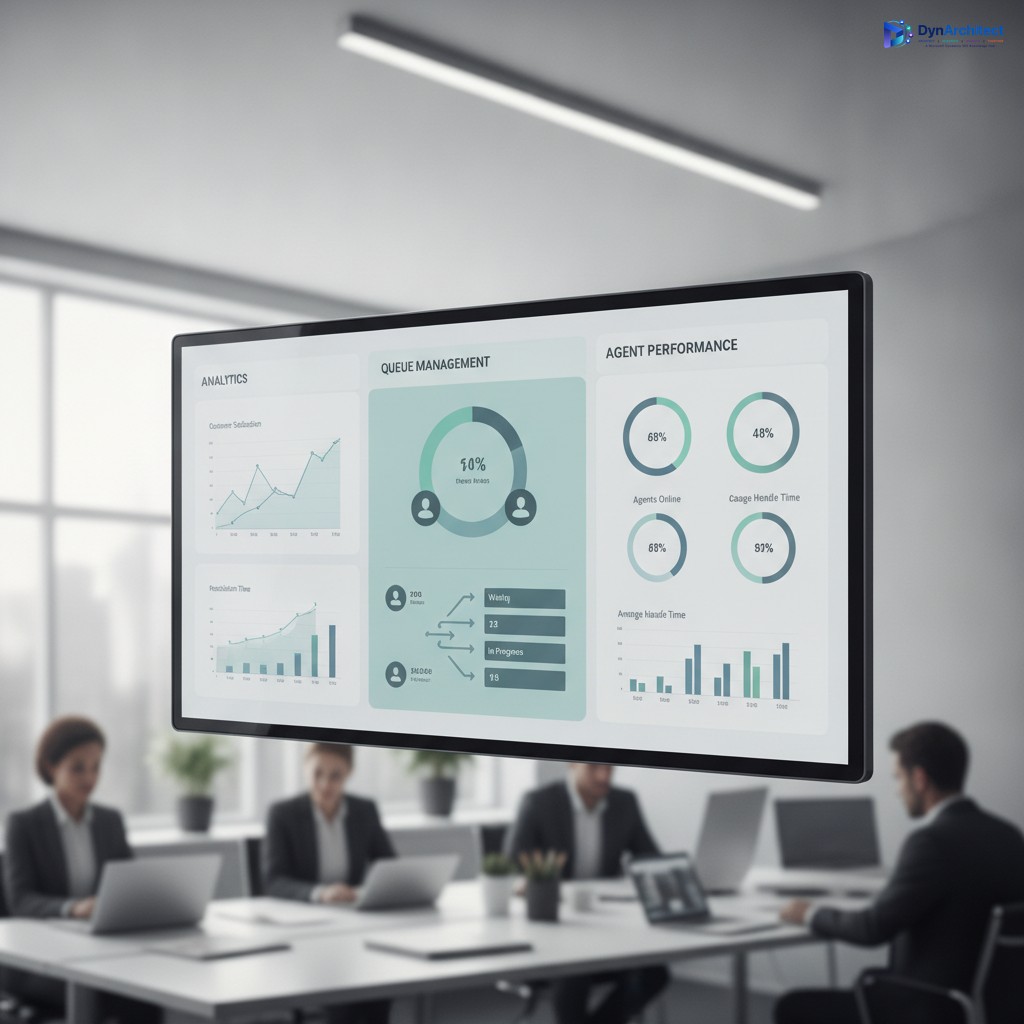
Customer service routing and queue management system

Omnichannel organizes customer interactions into a queue-based model. Every incoming chat, email, email-to-case conversation, social message, and phone call flows into a work item. That work item contains the customer context, conversation history, and metadata. Agents see a unified interface and pick up work items in order of priority, assignment rules, or routing logic.

The configuration itself is straightforward: define queues by channel or by business function, set up routing rules based on agent skills or availability, configure notification behavior, define service-level targets (SLA), and establish escalation paths. Most organizations complete this within a few weeks.

But here’s where the gap appears: once omnichannel starts processing real customer interactions at real volume, several operational realities emerge that no configuration screen fully prepares you for.

Issue One: Routing Logic Doesn’t Always Match Channel Behavior

Omnichannel supports skill-based routing, where work items are assigned to agents with matching skills. In theory, a chat about billing goes to agents tagged with “billing-expert,” and a social-media complaint about shipping goes to “escalations.”

In practice, skill tags accumulate overtime. Agents get tagged with more skills than they actually have capacity for, either because they once handled a specialized case and never got the tag removed, or because managers add skills to broaden an agent’s available work. The routing logic then becomes unreliable. A chat that should go to the most experienced agent instead goes to whoever technically has the skill but happens to be first in the queue.

Solution architects often respond by tightening the skill-assignment process and educating managers about the cost of skill inflation. But the underlying issue is that most organizations lack a systematic way to audit skill usage or enforce skill standards once omnichannel is live.

Issue Two: Phone Channel Integration Isn’t Truly Integrated

Omnichannel’s phone integration exists, but many organizations find it works best when phone calls are treated as a special case, not as peers to chat and email within the same routing logic.

Here’s why: phone interactions move at voice speed. An agent picks up a call, and the customer is already speaking. There’s no 30-second window to pull up customer records, like there is with an incoming email or chat. Phone calls also cannot wait in a queue the way digital channels can; the interaction starts immediately or the customer hangs up and calls a competitor.

Many organizations end up running phone as a parallel system within Omnichannel rather than truly integrated. Phone calls route to a dedicated phone team with their own skills, queues, and SLAs, and only occasionally transfer into the main omnichannel workspace for escalations. This defeats much of the “single workspace” promise, but it’s operationally simpler and more stable than trying to force voice into the same queue-driven model.

Issue Three: SLA Compliance Becomes Unpredictable at Scale

Omnichannel supports Service Level Agreements (SLAs) that measure, for example, “first response within 2 minutes for chat” or “resolution within 4 hours for email.” Configuration is simple: define the metric, set the target time, and choose what happens when it’s breached (notification, escalation, priority boost).

But at volume, SLA behavior becomes hard to predict. If your agents are handling 300 chat interactions per day and you have a service-level target of “first response within 2 minutes,” that means approximately 99% of your agents need to be available and responding to new chats within that 2-minute window. Missing that threshold by a few percentage points means dozens of chats violate the SLA daily.

Organizations often respond by tightening thresholds—maybe “first response within 1 minute” for very high-urgency chats—but this can paradoxically worsen agent satisfaction and error rates, because agents are constantly interrupted and switching context between work items.

The operational reality is that SLA targets need to account for actual agent capacity, not theoretical capacity. A team of 50 agents cannot sustainably respond to every chat within 2 minutes if they’re also handling email and other channels. The configuration screens don’t flag this contradiction; it surfaces only in production data.

Issue Four: Routing Rules Create Silent Failures

Omnichannel allows conditional routing rules. For example, “if the customer’s account is flagged for fraud review, route to the fraud team” or “if sentiment analysis detects high emotion, escalate to a supervisor.” These rules are powerful when they work.

They often don’t, silently. A rule might fail to fire because a prerequisite data field is empty (the customer record has no sentiment score yet), or because the rule’s condition was written too narrowly (it looks for exactly “fraud” but the account is flagged as “review-fraud-pending”). When a routing rule fails to fire, the work item doesn’t escalate and doesn’t get reassigned; it just continues down the default path.

The agent never sees a warning. The system doesn’t flag a rule failure. The work item eventually gets handled, maybe late, maybe incorrectly. Discovering these failures requires audit logs and data queries, not standard Omnichannel reporting.

Issue Five: Historical Context Fades Faster Than You’d Expect

One of Omnichannel’s core selling points is customer context. Every conversation thread, every case history, every previous interaction is visible in the unified workspace. An agent can see that a customer has contacted support three times this month about the same issue.

But in a high-volume contact center, historical context can degrade quickly. If a customer’s issue remains open for 72 hours without resolution, the record might accumulate 15 different interactions, notes, and case reassignments. A new agent picking up that conversation needs to scroll through all of that history to understand where the issue stands.

Many organizations respond by enforcing a maximum context retention policy—say, “only show interactions from the last 48 hours”—but this can mean losing important information. A customer might say, “This is the same issue I reported last week,” but the agent cannot see that previous week’s conversation because it’s been archived.

Operational Frameworks That Actually Work

Organizations that run Omnichannel successfully tend to implement several practices that don’t come out of the box:

**Skill Audit Cycles**: Quarterly (at minimum) audits of agent skills, removing skills that are no longer relevant and tightening the rules for when a skill can be assigned. This is a governance task, not a configuration task, and it requires someone’s time every quarter.

**Phone as a Managed Exception**: Accept that phone calls don’t fit the same queue model as digital channels. Establish phone as a dedicated workstream with its own routing, escalation, and SLA targets. This isn’t a failure of Omnichannel; it’s an acknowledgment of how voice works.

**SLA Targets Based on Capacity, Not Theory**: Before setting an SLA target, calculate what it actually requires. If you have 50 agents, each handling an average of 5 concurrent chat interactions, with 40 seconds average handling time, then you can sustain a 2-minute first-response target for roughly 70% of inbound chats. Set your SLA to that realistic threshold, not to an aspirational one.

**Routing Rule Validation**: Implement a monthly process to validate that routing rules are firing as expected. This means querying Omnichannel analytics to confirm that “fraud-flagged” accounts are actually reaching the fraud queue, and that sentiment-escalation rules are working. Fix silent failures as you find them.

**Context Management Policy**: Define what counts as “relevant context” for agents. Decide how far back conversation history should display (48 hours? 30 days?). Document which data fields agents need to see immediately versus which can be found in a related case. Enforce this consistently so agents know where to find what they need.

The Operating Model Matters More Than the Configuration

Many organizations approach Omnichannel as a technical implementation problem: install it, configure it, test it, go live. In reality, Omnichannel’s success depends far more on the operating model around it.

A mature Omnichannel deployment has a defined governance structure, regular audits of routing and skill assignments, SLA targets that reflect real capacity, and someone accountable for keeping it all working. Configuration is the easy part. Operations is where most organizations struggle.

If your organization is considering Omnichannel, or if you’re already running it but seeing unpredictable behavior, the first question isn’t “Is our configuration wrong?” It’s “Do we have the operational discipline to keep Omnichannel working correctly at volume?” The answer determines whether Omnichannel becomes a competitive advantage or a source of recurring complaints.

Financial Tags Finally Cover Purchase Order Invoicing in D365 Finance 10.0.49. Ledger Settlement Still Won’t Match Half of Them.

Finance professional reviewing a general ledger reconciliation dashboard with matched and unmatched transaction indicators

A controller running month-end reconciliation on a clearing account in Dynamics 365 Finance has a specific, recurring headache: the debit side of a transaction carries a purchase order number as a financial tag, the offsetting credit side does not, and the ledger settlement engine treats the two lines as unrelated even though anyone looking at the source documents can tell they belong together. Until version 10.0.49, this was a permanent structural gap rather than an occasional configuration mistake, because financial tags on purchase order invoicing simply did not exist as a supported scenario. Sales order invoicing got tag support years earlier. Purchase orders did not, which meant any finance team using tags to track PO references through the vendor side of the ledger was stuck writing the number into a description field or a financial dimension never designed to hold it. That gap closed with 10.0.49, and the fix is worth understanding in detail, because the parts of financial tags that already worked reasonably well are not the parts that are going to trip up the teams adopting this now.

What Financial Tags Actually Are, and Why the PO Gap Mattered

Financial tags are not a new concept in Dynamics 365 Finance. Introduced in version 10.0.16, they give a legal entity up to twenty user-defined fields that attach supplementary reference data directly to a general ledger voucher line, things like an external invoice number, a customer name, or a payment reference, without that data ever touching a subledger table or a financial dimension. That distinction matters more than it sounds. Financial dimensions were built for reusable, hierarchical, reportable categories: cost center, department, business unit. A purchase order number is none of those things. It is a single-use reference that exists to answer one question later: which document generated this line. Forcing that kind of data into a dimension structure bloats the dimension combination table and adds no analytical value, since nobody is running a financial report grouped by PO number. Tags were built specifically to hold this lower-reusability data cleanly, and by the time sales order invoicing gained tag support, most finance teams using the feature had already built tagging conventions around customer-side transactions. Vendor-side transactions were the obvious next step, and the 10.0.49 release finally delivers it, gated behind a feature called Enable financial tags for purchase order invoicing that sits alongside the equivalent, longer-standing sales order feature in Feature management.

Where the Real Work Starts: Ledger Settlement Matching

The reason this release deserves more than a changelog mention is that financial tags do something beyond passive record-keeping. They can serve as match criteria inside ledger settlement, the process finance teams use to pair debit and credit lines on clearing, prepaid, accrual, and other temporary accounts and mark them as settled. In principle, tagging both the AP-side and AR-side (or intercompany) legs of a transaction with the same PO reference should make settlement close to automatic: the engine finds the matching tag values and clears the pair. In practice, three specific failure patterns show up constantly, and none of them produce an error message that tells you what actually happened.

Close-up of hands reviewing a voucher transaction table with reference and status columns on a laptop

The first is the mismatched-side problem this article opened with. If the debit line carries a tag value and the credit line does not, or the two sides carry different values because they were entered by different people at different points in the process, settlement will not treat them as a match. There is no fuzzy matching here. The comparison is exact, and a trailing space or a different capitalization convention is enough to break it. The second is a timing problem specific to any organization adopting purchase order tagging now rather than at initial go-live: transactions posted before the feature was activated simply have no tag value on the line at all, which means every open item predating the 10.0.49 upgrade needs a separate remediation pass before it can participate in tag-based settlement. You cannot retroactively tag a posted voucher through the transaction UI; the supported path is the internal voucher data edit function, gated behind the Allow edits to internal data on general ledger vouchers feature, and it needs to run as a deliberate cleanup project, not something a settlement clerk discovers mid-close.

The third failure mode is the one that catches experienced admins off guard, because it involves a change that looks harmless. Tag labels can be renamed at any time without affecting already-posted data, which is a genuine convenience when a naming convention needs to evolve. But posted voucher lines retain whatever tag value was in effect at posting time, and if two lines that logically belong together were posted before and after a rename, or against two tags that were later consolidated under one label, the underlying stored values can diverge from what the current tag configuration implies, and settlement compares stored values, not current labels. A team that renamed a tag mid-quarter for good reasons can end up with a batch of open items that look identical in the UI but fail to match, and the only way to find out why is to pull voucher transactions against the general journal account entry table (not the financial tags table, which only exposes generic Tag01 through Tag20 labels and hides which business tag they actually correspond to) and compare raw values line by line.

Configuration Details Worth Getting Right Before You Enable the Feature

Beyond the settlement-matching behavior, a few configuration decisions are easy to get wrong on the first pass and expensive to unwind later. The delimiter used to separate tag values in General ledger parameters cannot be changed once set, so it is worth choosing a character your reference data will never plausibly contain, not just one that looks clean in a demo. Validation is optional by default even for list-type tags; as of 10.0.44, Fixed list and Fixed custom list value types exist specifically to prevent free-text drift, and for any tag that will be used as a settlement match key, that validation should be non-negotiable rather than left at the default. And because tag configuration changes are cached at the user session level, a tag that was just activated or edited will not reliably show up for a user until they sign out and back in and, in stubborn cases, clear the usage data cache under user options; teams that skip this step and conclude a newly enabled tag “isn’t working” are usually looking at a caching artifact, not a configuration bug.

For a finance function evaluating whether to turn purchase order tagging on now, the sequencing that avoids the most rework is to finalize the tag definitions and delimiter first, apply fixed-list validation to anything that will drive settlement matching, activate the feature and confirm both sides of a representative PO-to-payment cycle post with identical tag values, and only then decide how far back to remediate historical open items rather than assuming the feature will somehow reach backward on its own. None of this diminishes what 10.0.49 actually fixes: a real, years-old asymmetry between how sales and purchase transactions could be tagged is gone. What it does not fix, and was never going to, is the discipline required to keep tag values consistent across two sides of a transaction that are frequently entered by different people, in different modules, at different times. Routeget Technologies has helped finance teams build that discipline into their close process rather than discovering the gap during an audit, and the pattern is consistent enough across clients that it is worth planning for before enabling the feature rather than after the first failed settlement run.


#FinancialTags #DynamicsFinanceOps #LedgerSettlement #PurchaseOrderInvoicing #GeneralLedger #ERPReconciliation

Power BI Copilot’s Bill Isn’t a License. It’s Fabric Copilot Capacity You Share.

IT and finance leaders reviewing an enterprise Fabric capacity billing dashboard for Power BI Copilot usage

A CFO at a manufacturing group running Dynamics 365 Finance and Supply Chain recently signed off on an F64 Fabric capacity so the FP&A team could start using Power BI Copilot to draft variance commentary and summarize demand forecasts. Three weeks later, an IT director flagged something the approval memo never mentioned: two hundred report viewers across the business no longer needed Power BI Pro licenses at all. That wasn’t a bug or a surprise discount. It was a separate Fabric licensing rule that happens to kick in at the exact same capacity size Copilot is often recommended for, and the two get conflated constantly in vendor pitches and budget spreadsheets alike.

That conflation is the real problem for anyone trying to budget a Power BI Copilot rollout against a Dynamics 365 reporting program. Copilot in Power BI is not a per-seat add-on the way Microsoft 365 Copilot is. It is billed against Fabric capacity consumption, measured in capacity units, and organizations can even designate a specific Fabric Copilot capacity purely to centralize that billing. Whichever capacity ends up holding that designation is shared with every other Fabric workload your organization runs on it. Getting the cost model wrong in either direction, assuming it is included in your existing Pro licenses, or assuming it behaves like a fixed monthly fee, leads to budget requests that are either laughably low or defensively padded past what the workload actually needs.

IT and finance leaders reviewing an enterprise Fabric capacity billing dashboard for Power BI Copilot usage

What Copilot Actually Consumes, and Why the Rate Card Looks Strange

Microsoft’s own Fabric documentation describes Copilot consumption in capacity unit seconds, priced per 1,000 tokens, and the input and output rates are not the same. Input prompt tokens consume 100 CU seconds per 1,000 tokens, cached input tokens (system instructions, schema context, and conversation history that Fabric automatically caches without any configuration) consume only 10 CU seconds per 1,000 tokens, and output tokens, the actual generated text, consume 400 CU seconds per 1,000 tokens. That four-to-one gap between input and output pricing matters in practice: a Copilot-generated narrative summary of a Dynamics 365 SCM inventory report produces far more output tokens than the prompt that requested it, so output pricing dominates the bill.

Take a request with 2,000 input tokens and 500 output tokens, a reasonably typical size for a Copilot-drafted commentary on a Power BI report built over Dataverse or F&O entity data. The math works out to (2,000 × 100 + 500 × 400) ÷ 1,000, which is 400 CU seconds, or roughly 6.67 CU minutes. On its own that number means nothing to a finance leader. What it means in context is the second thing worth understanding: how that consumption gets classified against your capacity.

Background Job Smoothing Changes the Real Exhaustion Risk

Microsoft classifies Copilot operations as background jobs rather than interactive ones, and background jobs get smoothed over a 24-hour window instead of the 5-minute window used for interactive report rendering. Throttling only begins once the capacity has already committed all of its available CU budget for the next 10 minutes. Microsoft’s own documentation walks through this with an F64 example: an F64 SKU carries 64 × 24, or 1,536, CU hours in a single day. A single Copilot request consuming roughly 6.67 CU minutes works out to about 0.11 CU hours, which means an F64 capacity could theoretically absorb well over 13,000 such requests before exhaustion, assuming nothing else on that capacity is consuming CU budget at the same time.

That last clause is where the real governance risk sits, and it’s a genuinely different risk than “Copilot is expensive.” When capacity is exhausted, Microsoft’s documentation is direct about the consequence: all operations shut down, not just Copilot. If your Dynamics 365 reporting workspace, your dataflows, your semantic model refreshes, and your Copilot usage all live on the same Fabric capacity, and a finance analyst runs an unusually large batch of Copilot-assisted narrative generation during month-end close, everyone else’s scheduled refreshes and interactive reports can stall on that same capacity at the same time. This is an argument for isolating Copilot consumption onto its own designated capacity rather than an argument against adopting it at all, and Microsoft built a specific mechanism for exactly that.

Financial analyst working at a dual-monitor desk with Power BI analytics dashboards

The Fabric Copilot Capacity Designation Is Not the Same Thing as F64

Since April 2025, Microsoft has allowed organizations to designate any capacity of F2 or larger, not just F64 and above as originally required at the January 2025 preview launch, as a dedicated “Fabric Copilot capacity.” A Fabric admin enables Copilot for the organization, authorizes a capacity admin to make that designation, and the capacity admin then assigns user groups whose Copilot usage should bill there instead of wherever their content happens to be hosted. Once that’s done, no further action is needed. Users assigned this way can be on Pro, PPU, Trial, Premium capacity, or Fabric capacity license modes, though Embedded is explicitly not supported.

This solves a specific budgeting problem: without it, Copilot costs get spread across whatever capacity holds each user’s content, which makes centralized cost tracking nearly impossible for an IT Director trying to build a clean Copilot line item. With a designated Copilot capacity, every dollar of Copilot consumption lands in one place on the bill, separate from your Dynamics 365 reporting workspace’s own capacity consumption for refreshes and interactive use. Worth noting for architects planning this out: Fabric Copilot on other workloads (Data Factory, Data Engineering, Data Warehouse, Data Science, Real-Time Intelligence, and Activator) is only available on capacities smaller than F64, while Power BI Copilot specifically remains available regardless of capacity size. If your organization runs Copilot across multiple Fabric experiences, not just Power BI, that asymmetry affects which capacity size you actually want for the designation.

Why the F64 Threshold Gets Conflated With Copilot Pricing, and Why That Matters for Your Budget

Separately from anything Copilot-related, Microsoft’s Fabric licensing model has long included a straightforward rule: on any F SKU smaller than F64, every person viewing Power BI content needs a Pro, PPU, or individual trial license. At F64 or larger, a user with only a free Fabric license can view content, provided they hold a viewer role on the workspace. This rule exists independent of Copilot and predates Copilot’s current billing model by a wide margin. It’s an artifact of how Microsoft licenses Power BI content consumption at scale, not a Copilot feature.

The reason this matters for a CFO’s budget conversation is that vendors and consultants routinely present F64 as “the tier where Copilot gets cheap,” when the more accurate framing is that F64 is where per-viewer Pro licensing gets cheap, and Copilot’s own cost is a completely separate, consumption-based line that scales with usage regardless of which SKU size you land on. An organization with two hundred report viewers and modest Copilot usage might genuinely benefit from an F64 capacity purely for the license consolidation, independent of whether Copilot ever gets turned on. An organization with heavy Copilot usage across a small number of power users, finance analysts drafting narrative variance reports all day, might be better served by a smaller designated Copilot capacity and leaving Pro licensing exactly where it is. These are two different decisions being made to look like one decision, and separating them is the actual budgeting exercise.

What This Means for a Dynamics 365 Reporting Rollout

For an IT Director or CFO evaluating Power BI Copilot against Dynamics 365 Finance, Supply Chain, or Customer Engagement reporting, start by quantifying how many people will actually draft Copilot-assisted narratives, distinct from how many simply view the resulting reports, since those two populations drive different cost levers entirely. From there, model consumption using the token rates above against your actual reporting cadence rather than a vendor’s generic estimate, since output-heavy use cases like automated commentary generation consume capacity differently than short, targeted Q&A against a semantic model. Finally, decide separately whether an F64-or-larger capacity makes sense for license consolidation, and treat that as independent from whichever capacity you designate for Copilot billing.

Fabric’s list pricing follows the capacity unit count linearly, so an F64 capacity costs roughly thirty-two times an F2 capacity’s pay-as-you-go rate, and Microsoft’s own reservation pricing page states that a one- or three-year commitment can reduce that rate by roughly 41 percent compared to pay-as-you-go. Given how directly usage scales with cost here, that reservation discount is worth pricing into any multi-quarter Copilot rollout plan rather than treating it as an afterthought once the pilot succeeds.

None of this makes Power BI Copilot a bad investment for a Dynamics 365 reporting program. It makes it a capacity planning exercise with its own governance questions, closer to provisioning compute than provisioning software seats. Organizations that treat it as the latter tend to either under-budget it or, more commonly, over-provision a capacity size for reasons that had nothing to do with Copilot in the first place. It’s the kind of distinction our team at Routeget Technologies walks clients through before a single dollar of Fabric capacity gets provisioned, since separating the licensing decision from the consumption decision up front is what keeps a Copilot rollout from turning into an unplanned line item six months later.


#PowerBICopilot #FabricCapacity #CopilotCostGovernance #DynamicsFinanceOps #EnterpriseAI #FinanceTransformation

An AI Builder Prompt Inside a Copilot Studio Agent Skips Your AI Builder Credits. It Draws From Copilot Credits Instead.

Solution architect reviewing an AI agent cost analytics dashboard on a large office monitor

A solution architect at a mid-market manufacturer spent the spring building a Copilot Studio agent to triage vendor emails: pull the invoice number, classify the request type, draft a reply for a human to approve. The extraction logic ran through an AI Builder custom prompt, the same kind the finance team had already been using inside a Power Automate flow for months. The architect assumed the agent’s usage would draw from the same AI Builder credits the company had already purchased through a capacity add-on for that flow. It didn’t. Three weeks after the agent went live, the Copilot Credits pool that governed an entirely different project ran dry, and nobody could explain why until someone actually read the fine print on how AI Builder prompts get billed once they leave Power Automate and start running inside an agent.

This is not a hypothetical edge case. It is the direct, documented behavior of how Microsoft splits AI Builder consumption across its two billing meters, and it matters to anyone scoping a Copilot Studio project that leans on AI Builder for extraction, classification, or generative text work. The split is simple to state and easy to miss: AI Builder credits, whether seeded through a license or purchased as a capacity add-on, only ever pay for AI Builder usage inside Power Apps and Power Automate. The instant that same prompt is wired into a Copilot Studio agent, whether through a topic, an agent flow, or an AI plugin, the meter that runs is Copilot Credits, full stop, regardless of how much unused AI Builder capacity sits in the tenant.

How an AI Builder Prompt Actually Gets Into an Agent

There are three distinct ways to wire an AI Builder prompt into a Copilot Studio agent, and they carry different reliability and governance tradeoffs worth understanding before picking one for a production scenario. The first is a Prompt Action, built through Copilot Studio’s own five-step wizard: name the action, write the prompt with its input variables, map inputs and outputs, test it, and publish it as a general availability capability that Copilot for Microsoft 365 can invoke directly. The second is a Topic Node, where a “Call an action” step inside a scripted topic calls a custom prompt built inline, giving a developer explicit control over exactly when the prompt fires within a defined conversation flow rather than leaving invocation to the model’s own judgment. The third, still in preview, is an AI Plugin, where the agent decides on its own whether a user’s phrasing matches the prompt’s description closely enough to invoke it, which is convenient for open-ended agents but introduces a layer of semantic matching that a cost-sensitive, high-volume scenario probably should not depend on without testing it thoroughly first.

Each of these paths has a quirk worth planning around. Newly published actions can take a few minutes to actually appear inside the live agent experience, which has tripped up more than one team mid-demo. And because AI Plugin invocation depends on the model correctly matching a user’s intent to a prompt’s written description, a poorly worded action description will simply never fire, silently, with no error to debug against; the fix is almost always writing a sharper, more literal description of what the prompt does and when it should be used, not adjusting the prompt itself.

Close-up of hands on a keyboard with a dual-monitor setup showing an AI agent builder interface and a billing usage graph

How AI Builder Credits and Copilot Credits Actually Split

Microsoft’s own AI Builder credit management documentation states plainly that AI prompts run on AI Builder credits “in the context of Power Apps and Power Automate flows.” Its companion licensing page, updated as recently as June 2026, closes the loop on the other side: every AI Builder capability used inside a Copilot Studio agent, whether that’s a prompt fired from a topic, an action, or an agent flow, consumes Copilot Credits instead. There is exactly one carve-out, and it is a narrow one: prompts triggered from the agent’s own embedded test panel during development do not consume credits at all. Once that same prompt is live and being called by an actual conversation, real users, real credits.

The rate table behind that consumption is tiered in a way that rewards knowing which tier a given prompt actually needs. Basic text and generative tools run at roughly a tenth of a Copilot Credit per thousand tokens, characters, images, or pages processed. Standard-tier tools run fifteen times that rate, and premium-tier generative models run a hundred times the basic rate. Content processing tools, the category that covers document and image-heavy extraction work, run at eight Copilot Credits per image or page regardless of tier. An architect who defaults every prompt in an agent to the most capable underlying model available, out of an understandable instinct to maximize accuracy, can inflate the agent’s running cost by two orders of magnitude compared to a version that used a standard-tier model for routine classification and reserved the premium tier for genuinely ambiguous cases.

This distinction also reframes how a team should think about the AI Builder seeded-credit removal scheduled for November 1, 2026, when Microsoft strips seeded AI Builder credits out of existing license entitlements and stops selling new AI Builder capacity add-ons to net-new customers entirely. For a team whose AI Builder usage lives mostly inside Power Automate flows, that deadline is a real budgeting event requiring a Copilot Credits purchase to replace lost capacity. For a team whose AI Builder usage lives mostly inside Copilot Studio agents, the deadline changes almost nothing, because that usage was never drawing on AI Builder credits to begin with. Knowing which bucket a given deployment actually falls into, before the deadline rather than after, is the entire point of understanding this split.

Building a Cost Model Before Scaling an Agent

The practical move for a technical team is to treat cost measurement as a required step before an AI Builder-backed agent goes anywhere near production traffic, not an afterthought handled through a monthly invoice review. Run the agent through a realistic volume of test conversations in a sandbox environment first, using the same prompts, the same model tiers, and roughly the same document sizes the production scenario will see, then check the Copilot Credits consumption reported in the Power Platform admin center against the AI Builder consumption reported separately for the same period. The two numbers will not match the way a team accustomed to Power Automate-only AI Builder usage might expect, and that mismatch is the whole exercise.

It is also worth deliberately testing each invocation path’s actual reliability under realistic phrasing before committing to it for anything customer-facing. A Topic Node call is deterministic: it fires exactly when the flow logic says it should, which makes its cost entirely predictable and its behavior easy to audit. An AI Plugin action is probabilistic in comparison: it fires when the model believes it should, based on matching user language to a written description, which means its cost and its behavior both carry a margin of uncertainty that shrinks with better description writing and testing but never fully disappears. For a scenario where getting the wrong answer, or no answer, actually costs the business something, that tradeoff deserves to be a documented decision, not a default nobody examined.

None of this is a reason to avoid combining AI Builder with Copilot Studio; the pairing is genuinely useful, and it is how most organizations will end up bringing extraction and classification capability into a conversational agent without building a custom model from scratch. Routeget Technologies has walked several clients through exactly this kind of agent-cost modeling exercise before a production rollout, and the pattern is consistent: the surprise is never that the technology doesn’t work, it’s that the invoice arrives against a different budget line than the one everyone was watching. Building that visibility in during the design phase, rather than discovering it after a month of live traffic, is the difference between a predictable agent rollout and an uncomfortable finance conversation.


#AIBuilder #CopilotStudio #CopilotCredits #AgenticAI #PowerPlatformLicensing #EnterpriseAI

Power Platform Pipeline Extensibility Changes Where Your ALM Logic Actually Lives

Solution architect reviewing an abstract Power Platform pipeline deployment diagram with an approval gate on an office monitor at dusk

Every Power Platform admin who has rolled out native pipelines has run into the same wall eventually. The tool is genuinely good at the thing it was built for: letting a maker click “Deploy” and move a solution from development to test to production without learning Azure DevOps YAML or touching a service connection. What it has never let you do, until recently, is put anything of your own between that click and the deployment itself. No custom validation before export. No compliance check before the artifact lands in production. No way to route the actual deployment through a service principal instead of the requester’s own credentials. If your organization needed any of that, the answer was to abandon native pipelines and rebuild the whole thing in Azure DevOps or with the community powerplatform-actions GitHub Action, which meant losing the low-friction maker experience that was the point of adopting pipelines in the first place.

Microsoft’s new Power Platform pipeline extensibility closes that gap, and it is worth understanding closely before you turn it on, because the way it is built shapes what kinds of governance logic actually belong there versus what still belongs in your existing CI/CD stack.

What pipeline extensibility actually adds

The mechanism is Dataverse business events. Power Platform pipelines now emit a defined set of events at each stage of a deployment, and a Power Automate cloud flow sitting in the pipelines host environment can subscribe to those events using the ordinary “When an action is performed” trigger from the Dataverse connector, filtered to the Power Platform Pipelines category. There are seven distinct trigger actions you can hook: OnDeploymentRequested, OnApprovalStarted, OnApprovalCompleted, OnPreDeploymentStarted, OnPreDeploymentCompleted, OnDeploymentStarted, and OnDeploymentCompleted. OnDeploymentRequested fires for every deployment regardless of configuration, and it is also the event a pre-export validation flow hooks into. The approval and pre-deployment pairs only fire at all if you have explicitly enabled the corresponding extension on that pipeline stage, so a flow subscribed to OnPreDeploymentStarted simply never triggers on a stage that hasn’t turned that gate on.

Abstract illustration of a deployment pipeline with connected stage nodes and a glowing approval gate checkpoint

Three gated extension points sit on top of those events, and each one solves a different problem rather than being interchangeable flavors of “add a step.”

Pre-export step required

This is the earliest gate. It runs when a maker submits a deployment request, before the solution is even exported from the development environment, and Microsoft explicitly restricts it to the first stage of a pipeline. That restriction matters more than it looks: once a solution is exported, the pipelines host stores the managed and unmanaged artifacts and promotes that exact same artifact version through every downstream stage. You cannot re-validate or re-export at stage two. Whatever checks you want to run against the source solution, whether that is a naming convention audit, a check for unmanaged customizations, or a call out to an internal change-approval system, have to happen here or not at all.

Is delegated deployment

This extension solves a different problem: identity. Without it, a deployment runs under the requesting maker’s own credentials, which means that maker needs write access to the target environment, something plenty of organizations are uncomfortable granting to anyone below an admin for a production environment. With delegated deployment enabled, the actual deployment executes under a service principal instead, provided the pipeline stage owner is configured as an owner of that service principal in Microsoft Entra ID. A maker can request a production deployment, get it approved, and never hold standing access to production at all. For any organization that has been quietly working around this by granting temporary System Administrator roles before a release and revoking them after, this is the fix that was missing.

Pre-deployment step required

This is the last gate, sitting after approval but before the deployment itself actually runs. This is where a final compliance check, a change-freeze lookup, or a notification to a service desk system belongs, since by this point the deployment has already been approved and you are deciding only whether to let it proceed right now.

Wiring a flow to it

The implementation pattern is consistent across all three extension points. You build a cloud flow, in the pipelines host environment specifically, not in the source or target environment, using the Dataverse “When an action is performed” trigger. You can scope the trigger with a condition against the output parameters, most commonly DeploymentPipelineName or DeploymentStageName, so that a single environment does not end up running every organization’s validation logic against every pipeline. Inside the flow you run whatever logic you need, whether that is a call to an external API, an approval step, or a lookup against a governance table, and then you close the loop with an unbound Dataverse action: UpdatePreExportStepStatus or UpdatePreDeploymentStepStatus, setting the status to 20 for complete or 30 for rejected. A rejected status fails the deployment outright rather than leaving it hanging. Microsoft ships two sample managed solutions, Pipelines Extensibility Samples and Delegated Deployment Samples, that are worth installing into a sandbox before writing anything from scratch, since they cover the trigger and action wiring in a working state rather than leaving you to reverse-engineer the output parameter names from documentation alone.

Where this still falls short

None of this replaces a pro-code CI/CD pipeline, and it is not trying to. The GitHub Actions and Azure DevOps paths for Power Platform still own the things extend pipelines does not touch: source-controlled solution unpacking, automated build artifacts, and static analysis through the solution checker as part of a pull request gate rather than a deployment-time check. What extend pipelines is actually good at is inserting governance and identity control into the maker-facing deployment experience without forcing every citizen developer through a developer-grade toolchain. That is a narrower job, and treating it as a replacement for real CI/CD is the most common mistake I would expect teams to make with it.

The rollout itself is also worth flagging before you plan around it. As of this writing, Microsoft describes the extensibility features as being rolled out gradually across regions, and existing pipelines customers may need to update the Power Platform pipelines application through the admin center before any of these extension points even appear as configurable options. If you check a production tenant and do not see pre-export or pre-deployment settings on a pipeline stage, that is very likely a rollout or update-application issue rather than a misconfiguration on your end, and it is worth confirming with a support ticket before spending time debugging a flow that was never going to fire.

A few operational limits are worth building into your rollout plan from day one. Personal pipelines created inside make.powerapps.com cannot be extended at all, so any governance requirement has to be enforced through admin-managed pipelines rather than personal ones if extensibility is part of the plan. Makers retain the ability to cancel a pending deployment request, but only up until the final deployment step actually begins, so a long-running pre-deployment check is not a safe place to also expect cancellation to work cleanly. And because the exported artifact is immutable across all downstream stages, any pre-export validation logic needs to be strict enough to catch problems before that first export, since there is no second chance to reject the same artifact further down the pipeline.

For architects who have been asking Microsoft for a middle ground between no governance hooks at all and abandoning native pipelines for full Azure DevOps, this is that middle ground. At Routeget Technologies, this is the kind of gap our Power Platform ALM engagements have historically had to close with custom Azure DevOps pipelines, so a native option worth building a proof of concept around is a welcome addition. It is worth testing against a sandbox pipeline now, both to get ahead of the regional rollout and to work out which of the three extension points actually maps to a real control gap in your current deployment process, rather than instrumenting all three reflexively the day they become available in your tenant.


#PowerPlatformPipelines #ALMGovernance #DataverseBusinessEvents #DelegatedDeployment #PowerAutomate #EnterpriseAutomation

Business Central Withholding Tax Just Went Standard. The Setup Still Isn’t a Checkbox.

Finance director reviewing an international vendor payment and tax compliance dashboard in a modern office

For years, a Business Central partner fielding a withholding tax requirement from a customer expanding into Brazil, Nigeria, the Philippines, or a dozen other markets had exactly two honest answers: buy a third-party ISV solution built for that specific jurisdiction, or write custom code against the purchasing posting routines and hope the next major version upgrade didn’t break it. Neither answer was cheap, and neither scaled if the same customer later opened operations in a second country with a different withholding regime. That gap is what Microsoft’s new Business Central withholding tax engine is built to close. With the public preview that opened April 1, 2026 and general availability targeted for October 2026, Microsoft has built the calculation logic directly into the standard, non-localized version of the product, available for any country or region where a business needs it.

This matters more than it might sound like on first read. Country-specific withholding tax logic has existed in Business Central for a long time, but only inside the local functionality packs for markets like Italy, India, Australia, and New Zealand, each maintained as its own separate implementation with its own tables and its own quirks. A partner supporting a customer with entities in Italy and Colombia couldn’t reuse the Italian withholding tax setup for the Colombian entity, because the two were never built on shared logic. The new engine changes that by putting a single, configurable withholding tax framework into the base application, meaning any tenant, in any country, can turn it on without waiting for Microsoft (or an ISV) to ship a localization for that specific jurisdiction.

How the Business Central Withholding Tax Engine Works

The mechanics are straightforward at the conceptual level. When you post a purchase invoice or purchase order for a vendor flagged as withholding tax liable, Business Central calculates the applicable withholding tax based on your configuration, withholds that amount from what you’d otherwise pay the vendor, and creates a withholding tax entry for tracking and later settlement. A separate action, Calculate and Post Withholding Tax Settlements, lets you process and remit those withheld amounts to the tax authority for a given period. None of that is conceptually new to anyone who has worked with Italian or Indian withholding tax before. What’s new is that it’s no longer bolted onto a country pack; it lives in General Ledger Setup as a feature you enable directly.

Enabling it is only the first step, and this is where the “just flip a switch” narrative some blog posts have used falls apart under any real implementation pressure. After turning on Enable Withholding Tax in General Ledger Setup, you still need to build out four interconnected setup layers before a single invoice will calculate correctly. First, Withholding Tax Revenue Types, which define the categories of taxable transactions (each with its own code, description, and display sequence) and which later drive statutory reporting and certificate generation. Second, Withholding Tax Business Posting Groups, assigned to the vendors subject to withholding, and Withholding Tax Product Posting Groups, assigned to the items or G/L accounts the tax applies against. Third, a Withholding Tax Posting Setup record that links a specific business posting group to a specific product posting group and defines the actual calculation behavior: the calculation rule (less than, equal to, or another comparison against a threshold), a minimum invoice amount below which no tax is withheld, the withholding percentage itself, and a Realized Withholding Type that determines whether the tax is recognized at invoice posting, at payment posting, or at whichever comes first. Fourth, the G/L account setup for the prepaid and payable withholding tax accounts, plus the balancing account types and numbers Business Central needs to post the offsetting entries correctly.

That Realized Withholding Type field deserves particular attention from anyone implementing this for a jurisdiction they haven’t worked with before, because it isn’t a cosmetic timing preference. Statutory withholding regimes frequently specify exactly when the withholding obligation legally arises, and that moment doesn’t always match Business Central’s default assumptions. A configuration that recognizes withholding tax at invoice posting when the local rule requires recognition at payment will produce entries that reconcile cleanly inside Business Central while being wrong for the actual filing. This is not a gap in the software so much as a reminder that a generalized engine can’t encode every country’s statutory timing rules for you; that judgment call sits with whoever configures the posting setup, and it needs to be validated against actual local tax guidance, not against what feels intuitive from a US or UK accounting background.

Abstract illustration of a digital invoice with a portion of its value being withheld into a separate ledger

The Parts the Documentation Leaves for You to Test

Microsoft’s own documentation for this feature is candid about what it covers and noticeably quiet about several scenarios that any multinational deployment will eventually hit. There’s no published guidance yet on how withholding tax interacts with early payment discounts, where the discount changes the payment amount after the withholding calculation might already have run. There’s nothing specific on multi-currency purchase documents, where the withholding percentage presumably applies to a converted amount, but the conversion timing (invoice date rate versus payment date rate) isn’t spelled out. Prepayment scenarios, where part of the vendor payment happens before the final invoice, aren’t addressed either, and neither is whether a single vendor can carry more than one withholding tax code simultaneously for different transaction types.

None of this means the feature is unfinished in a way that should block evaluation. It means that any partner scoping an implementation should treat those four scenarios (discounts, multi-currency, prepayments, multiple codes per vendor) as required test cases before go-live, not edge cases to handle reactively after a customer complaint. Build a small set of test vendors and test posting groups in a sandbox, run each scenario through to a posted settlement, and compare the resulting entries against what the local tax authority actually expects. That’s a half-day of structured testing that will surface problems far more cheaply than discovering them during a live settlement run in month three.

There’s a second practical wrinkle worth planning around: coexistence with the existing localized versions. A customer running Italian local functionality for their Milan entity and the new standard engine for a newly opened Kenyan entity now has two withholding tax implementations active in the same tenant, built on different tables, with different setup pages, and (presumably, though Microsoft hasn’t published a migration path) no automatic bridge between them. For partners supporting genuinely multinational customers, this is worth raising proactively rather than waiting for someone to ask why the Italy withholding tax report doesn’t include Kenyan vendors.

Why the Timing Matters Right Now

Because the feature is still in public preview as of this writing, with general availability set for October 2026, this is the window where testing and feedback actually shape the shipped product rather than reacting to it after the fact. A conflicting timeline circulated by at least one independent Business Central blog puts general availability as early as June 2026, but Microsoft’s own release plan documentation lists October 2026 as the GA date, which is the figure worth planning around until Microsoft says otherwise. Partners with customers who have been paying for third-party withholding tax add-ons or running custom code against the purchasing module have a real opportunity here: a standard, Microsoft-supported alternative is arriving, and the preview period is the right time to validate it against the specific statutory requirements those customers already comply with, rather than assuming general availability means production-ready for every jurisdiction on day one.

At Routeget, this is the kind of feature we tend to see underestimated at the scoping stage, precisely because “Microsoft now supports withholding tax natively” sounds like it closes a requirement rather than opening a configuration project. The posting groups, the realized timing decision, and the untested edge cases are where the actual implementation effort lives, and getting them wrong doesn’t surface until a settlement run doesn’t match what the tax authority expected.


#DynamicsBusinessCentral #WithholdingTax #FinanceAutomation #TaxCompliance #ERPGovernance #GlobalFinance

Dynamics 365 Contact Center Voice Biometrics Just Reached GA. Your Compliance Review Hasn’t.

Contact center security analyst reviewing a voice authentication waveform and verification dashboard on a monitor

A customer calls in about a suspicious charge, and before a human agent ever picks up, the system has already confirmed who they are by the sound of their voice. No security questions about a mother’s maiden name, no four-digit PIN read aloud to a stranger, no thirty seconds of dead air while an agent pulls up an account and reads through a verification script. As of September 15, 2026, Dynamics 365 Contact Center voice biometrics is generally available, and for any organization running high call volumes through Microsoft’s platform, it is worth pausing on before flipping the switch. The technology is ready. The question most IT and legal teams haven’t finished answering is whether their organization is.

What Dynamics 365 Contact Center Voice Biometrics Actually Shipped

Voice biometrics authentication entered public preview in August 2026 and reached general availability a month later, built natively into both the Dynamics 365 Contact Center voice agent platform and Copilot Studio, so it works whether a caller is being verified by a bot or handed off to a person. The mechanics are straightforward on paper: a caller enrolls a voiceprint during an initial interaction, and on subsequent calls the system compares live speech against that stored print to confirm identity, either as a standalone factor or layered with a one-time SMS passcode and knowledge-based challenge questions for higher-risk transactions. Authentication happens before the call routes to a representative, which is the detail that matters most for anyone modeling the business case: the verification step that used to consume the first minute or two of an agent’s time now happens in the queue, invisibly, while the caller is still on hold.

Microsoft has packaged this with fraud case management tools, prebuilt performance dashboards, and centralized administration through the Customer Service Admin Center, so security and fraud teams get a single place to define policy, monitor false-accept and false-reject rates, and audit which callers were verified by voice versus a fallback method. That last piece, the audit trail, is going to matter more than most rollout plans currently assume.

Why this actually changes the cost equation

The economics here are more concrete than most AI-adjacent contact center features, because pre-authentication attacks a cost driver that finance teams already track closely: average handle time. Identity verification through spoken challenge questions is slow, it’s inconsistent across agents, and it’s one of the easiest points in a call for a trained social engineer to talk their way past a tired representative. Moving that verification into an automated, voice-based step ahead of routing shortens the part of the call an agent actually has to manage and removes a well-documented fraud vector at the same time. For contact centers handling account changes, payment authorizations, or sensitive service requests, that combination of lower handle time and reduced fraud exposure is the kind of dual benefit that gets a feature prioritized on a roadmap fast.

It’s also why this shouldn’t be treated as a routine feature-flag decision. Voice biometrics is biometric data collection, full stop, and that classification carries legal obligations that have nothing to do with how well the Dynamics 365 configuration works.

The compliance gap Microsoft’s documentation doesn’t close

Abstract illustration of a voice waveform authenticating through a glass security shield, representing voice biometric verification

Microsoft’s release notes for this feature describe the enrollment and verification flow in useful technical detail, but they are notably silent on consent language, retention schedules, and regional legal exposure. That’s not an oversight so much as a boundary: Microsoft is providing the platform capability, and the legal responsibility for how a specific organization collects and stores voiceprints from its customers sits with that organization, not with Redmond.

That responsibility is not trivial in the United States right now. Illinois’s Biometric Information Privacy Act remains the sharpest edge in this space, because unlike most state privacy laws, it grants individuals a private right of action, which is what has driven years of class-action litigation against companies that collected fingerprints, face scans, or voiceprints without the specific written notice and consent BIPA requires. A 2024 amendment narrowed the damages exposure somewhat, treating repeated collection through the same method as a single violation rather than a separate claim per scan, but the underlying notice-and-consent obligation didn’t go anywhere. Texas and Washington impose similar consent and retention requirements, enforced by their respective attorneys general rather than through private lawsuits, which changes the risk profile but doesn’t eliminate it. Colorado added more prescriptive deletion requirements to its biometric provisions in 2024, and Louisiana became the twenty-second state with a standalone biometric consent law in May 2026. For a multistate contact center, that adds up to a genuine patchwork, not a single compliance checkbox.

None of this makes voice biometrics a bad decision. It makes it a decision that has to be made jointly by IT, legal, and the security or fraud team, rather than one that gets configured and enabled the same week a Message Center notice lands.

What to actually check before enabling it

Start by mapping where your callers are located, not just where your contact center is headquartered. If any meaningful share of inbound volume originates in Illinois, or in any of the other states with biometric consent requirements, that determines whether you need affirmative, specific consent captured and documented before enrollment, not just a line buried in a privacy policy. Build that consent capture into the IVR flow itself, worded clearly enough that a caller understands they are being asked to enroll a biometric identifier, and log that consent event somewhere durable and auditable, ideally tied to the same Dataverse record the fraud dashboards already reference.

Retention and deletion policy needs equal attention. BIPA and its state counterparts generally require organizations to publish a retention schedule and actually delete biometric data once it’s no longer needed for the purpose it was collected for, which means someone has to define what “no longer needed” means for a voiceprint tied to an active customer relationship, and build the deletion workflow to match, not just write the policy and leave the data sitting in Dataverse indefinitely.

It’s also worth treating the rollout as opt-in rather than a default-on migration, at least initially. Keeping SMS OTP and knowledge-based challenges available as an equal-footing alternative, rather than a fallback for people who refuse voice enrollment, avoids putting the organization in the position of coercing consent, which is exactly the fact pattern that has produced some of the more aggressive BIPA litigation elsewhere. A phased pilot in a single, lower-risk jurisdiction, with legal and fraud teams reviewing false-accept rates and consent capture together before wider rollout, is a more defensible path than enabling it organization-wide the week after the Message Center notice arrives.

The takeaway for decision-makers

Voice biometrics in Dynamics 365 Contact Center is a genuinely useful capability, not a gimmick. It shortens calls, closes a real fraud gap, and gives fraud analysts tooling they didn’t have before. But general availability from Microsoft answers the technical readiness question, not the legal one, and the two timelines rarely move at the same pace. Organizations that treat this as a joint IT-legal-security decision, with consent and retention worked out before enrollment goes live, will capture the cost and fraud benefits without inheriting a class-action problem a year later. Routeget Technologies works with contact center teams on exactly this kind of platform-and-compliance sequencing when new Dynamics 365 capabilities reach GA faster than the surrounding legal review, and that pairing is usually the difference between a smooth rollout and a rushed one.


#DynamicsContactCenter #VoiceBiometrics #ContactCenterFraud #BiometricPrivacyLaw #OmnichannelCX #CustomerServiceSecurity

Power Platform Connector Certification Just Got Faster. Your DLP Policy Still Has a Gap It Doesn’t Close.

An IT governance leader reviewing a connector security and data classification dashboard in a modern office

An IT Director at a mid-size manufacturer recently found herself trying to explain, in a security review, why the company had eleven custom connectors feeding Copilot Studio agents and Power Automate flows, and why only three of them could be governed with any real precision. The other eight sat in a tenant-level policy bucket, classified by a URL pattern someone had written eighteen months earlier, long before anyone imagined an agent would be reading from that endpoint autonomously. Nobody had done anything wrong. The tooling simply hadn’t caught up to how fast custom connectors were multiplying once agentic AI entered the picture.

That gap between what Microsoft’s first-party and certified connectors can be governed with, and what a homegrown custom connector can be governed with, has existed for years. It matters more now because Copilot Studio agents lean heavily on custom connectors to reach line-of-business systems, and every one of those connectors is a new surface for a data loss prevention (DLP) policy to either control precisely or wave through by default. Microsoft’s overhaul of Power Platform connector certification, now routed through Partner Center, is worth a close look, not because it makes publishing easier (though it does), but because of what certification actually changes about how a connector can be governed afterward.

The governance gap custom connectors created

Power Platform’s DLP model treats connectors in three tiers: Business, Non-Business, and Blocked, with a rule that data can’t move between a Business-tier connector and a Non-Business one in the same flow or app. Certified and Microsoft first-party connectors slot cleanly into that model at the environment or tenant level. Custom connectors do too, technically, but the mechanics are cruder. At the environment level, an admin classifies each custom connector individually by name. At the tenant level, classification runs on URL pattern matching against the connector’s host address, using ordered allow and deny rules that end in a wildcard catch-all. It works, but it asks a governance team to maintain URL pattern lists by hand, and it treats a connector’s trustworthiness as a function of its address rather than anything Microsoft has actually reviewed.

Advanced Connector Policies (ACP), the newer and stricter allowlist model Microsoft has been rolling out for tenant-wide connector governance, makes the distinction sharper. ACP applies to certified connectors. Custom connectors and HTTP-based connectors, including the generic HTTP connector and HTTP Webhook triggers that many home-grown integrations depend on, are explicitly not supported in ACP as of this writing and still require classic DLP policies or connector endpoint filtering. In practice, that means a company standardizing on ACP for its governed estate is, by definition, leaving its custom connectors in a separate, less rigorous governance lane, no matter how business-critical those connectors have become.

What actually changed in Power Platform connector certification

Microsoft’s new certification pathway moves connector and Copilot plugin submissions into Partner Center, tied to enrollment in the Microsoft 365 and Copilot program. The prior process required manual review that partners reported taking two to five weeks, with limited visibility into where a submission stood or what specifically had failed if it was rejected. The Partner Center path automates the review, gives submitters real-time status and error detail, and covers four scenarios: new custom connectors built in Power Automate, version upgrades to already-certified connectors, custom connectors paired with an associated Copilot plugin, and version upgrades to that paired combination.

Once certified, a connector stops being a homegrown artifact and becomes a standard connector in Microsoft’s catalog. It shows up in the same list as first-party connectors in Power Automate, Power Apps, and Logic Apps, and if it has an associated plugin, that plugin becomes available for admins to enable through the Microsoft Admin Center for Copilot for Microsoft 365. For an enterprise that built an internal connector purely to reach an ERP or CRM system from a Copilot Studio agent, and never intended to publish it externally, this is the detail that matters most: certification is not only a go-to-market lever for ISVs, it is a path out of the custom connector governance lane described above.

Illustration of a digital padlock connecting through a certification gateway, representing connector certification and security governance

What certification does, and does not, fix

It would be a mistake to read this as Microsoft closing the governance gap entirely, and a CIO evaluating whether to push a critical connector through certification should go in with accurate expectations. Certification moves a connector into the standard three-tier DLP classification that Business and Non-Business connectors already use, replacing the name-based or URL-pattern approach reserved for custom connectors. That is a genuine improvement in precision, and it makes a connector eligible for ACP’s stricter allowlist model instead of being permanently excluded from it.

What certification does not do is retroactively fix the connectors an organization decides not to certify, and it does not extend ACP support to HTTP or HTTP Webhook connectors, which remain governed under classic DLP regardless of certification status elsewhere in the estate. A company with a mixed environment, some certified connectors under ACP and a long tail of custom and HTTP connectors under classic DLP, is still running two governance models side by side. Certification narrows that split. It does not eliminate it.

There is also a real cost to weigh. Certification requires standing up a Partner Center account, completing verification materials, and enrolling in the Microsoft 365 and Copilot program, none of which is a five-minute administrative task. For a connector built and used entirely inside one business unit with no reuse potential, that overhead is unlikely to pay for itself. For a connector that a dozen teams route sensitive financial, HR, or customer data through, or one that sits underneath a production Copilot Studio agent making autonomous decisions, the calculus is different.

Deciding which connectors are worth the investment

The practical question for an IT Director or CIO is not whether to certify every custom connector in the tenant. It is which ones justify the enrollment overhead and the ongoing maintenance of keeping a certified version current as the underlying API changes. Three characteristics are worth screening for. First, does the connector back a Copilot Studio agent or automated flow that acts on data without a human reviewing every step, since that is precisely the scenario where blunt, address-based DLP classification is riskiest. Second, is the connector reused across more than one business unit or environment, since URL-pattern tenant policies were never designed to express nuance across multiple consuming teams with different data sensitivity needs. Third, does the connector touch data categories, financial reporting, payroll, customer records, that already sit under stricter internal data handling policy, where a coarser custom-connector classification is a harder position to defend in an audit.

Connectors that fail all three tests, a one-off integration built by a single team for an internal utility with no agent dependency, probably do not need to go through Partner Center at all. The classic DLP tools, applied deliberately rather than left on default settings, are adequate for that tier. Where the calculus shifts is in exactly the kind of estate the manufacturer’s IT Director was trying to defend: a small number of connectors that carry disproportionate risk because of what they connect to and what increasingly autonomous agents do with that access.

Where this fits in a broader governance plan

None of this replaces the fundamentals. A tenant that has not yet adopted DLP custom connector parity, the capability that lets custom connectors be classified individually rather than only by URL pattern, should do that first, since it is available today at no additional cost and requires no Partner Center enrollment. Certification is the next step up for the specific connectors where individual classification still is not precise enough, and where eligibility for ACP’s allowlist model is worth the administrative investment.

Routeget Technologies has walked several clients through exactly this kind of connector inventory exercise, mapping which integrations sit behind agentic workflows and which ones are candidates for certification versus tighter classic DLP rules. The pattern that keeps showing up is not that organizations have too many custom connectors. It is that almost none of them have ever been ranked by actual risk, which is what makes the certification decision harder than it should be. Microsoft has removed the excuse that certification takes too long. The remaining work, deciding which connectors actually warrant it, is squarely a governance decision, not a technical one, and it belongs on the same review calendar as any other access control question in an increasingly agent-driven Power Platform estate.


#PowerPlatformGovernance #CustomConnectors #DataLossPrevention #CopilotStudio #EnterpriseAI #ConnectorCertification

Subcontractor Vendor Invoice Matching Is GA in Project Operations. Ten Silent Fields Decide If It Works.

Project accountant reviewing a vendor invoice reconciliation dashboard for subcontractor cost matching

A project controller at a mid-size engineering firm spends the third week of every month reconciling subcontractor invoices against timesheets in a spreadsheet, because the vendor invoice that lands in accounts payable has no native connection to the hours a contract welder actually logged against a task. She cross-checks rates, dates, and task codes by hand, then emails the project manager to confirm before anything gets marked ready for payment. That reconciliation gap is exactly what general availability of subcontractor vendor invoice matching to actuals in Dynamics 365 Project Operations, reached this September as part of 2026 release wave 1, is meant to close. For any organization running resource-based or nonstocked subcontracting through Project Operations, this is worth a close look before the next AP cycle, not because the concept is new (a version of automatic matching has existed since 2022), but because the field-level logic determining whether a match actually happens is stricter, and less forgiving, than most implementation teams assume going in.

What subcontractor vendor invoice matching actually changes

Subcontract-based project delivery in Project Operations has always followed a familiar shape: a project manager creates a subcontract against a vendor, attaches purchase price lists, links time-based or expense-based subcontract lines to either generic team members (to represent a staffing need) or named contract workers (to draw down capacity), and lets subcontractor resources log time, expenses, or product usage against tasks. Once that work is approved, it generates project cost actuals priced from the subcontract’s purchase rate. None of that is new. What the newly GA capability changes is the connective tissue between those cost actuals and the vendor invoice line items that eventually get paid.

Before this feature matured, matching a vendor invoice line to the underlying cost actuals was either manual or dependent on earlier, more limited automatic-association logic. Now, when a project manager records a vendor invoice with a line referencing a subcontract, Project Operations attempts to associate matching cost actuals automatically, and gives the project manager a structured, auditable workflow (built around a Verification status field) to confirm, adjust, or reject those matches before the invoice becomes eligible for payment.

The match logic: what has to line up

This is the part implementers need to internalize before go-live, because it determines whether the automatic matching actually fires or silently leaves everything to manual review. For a cost actual to link to a vendor invoice line, two separate conditions both have to hold.

Abstract illustration of cost actual records linking to vendor invoice line items in a reconciliation chain

The first is a status condition: the cost actual’s Adjustment status field must be blank. If a cost actual has been recalled, if its approval was cancelled, or if a correction journal against it is in progress, it is excluded from matching entirely, and the system will not surface it as a candidate no matter how closely the other fields align. This one trips up teams during parallel testing more than any other rule, because test data frequently includes actuals that went through a correction cycle, and those actuals simply never appear in the unmatched list, with no error message explaining why.

The second is field equivalence, and this is the longer list: project contract, project contract line, transaction class, project, task, resource category, transaction category, product, subcontract line, and bookable resource. Every one of these fields on the vendor invoice line has to match the corresponding field on the cost actual for a link to be proposed. There is one important carve-out worth building into your test plan: if a field is simply not populated on the vendor invoice line, it is excluded from the comparison rather than treated as a mismatch. That sounds like a convenience, and in some cases it is, but it also means a sparsely populated invoice line can match against a broader set of cost actuals than a fully populated one would, which is not always the outcome an AP team expects when they are trying to enforce tight three-way matching discipline.

Verification status: the workflow project managers actually see

Once matching candidates exist, the project manager works through a Verification status field that moves through three states. Not started is the default state for a fresh vendor invoice line, and it is the only state in which the line remains freely editable. The moment the first cost actual is matched to that line, status automatically advances to In progress, and the line locks against further direct edits outside the matching interface itself. From In progress, the project manager reviews the matched actuals in a grid, can pull in additional unmatched actuals or remove ones that were matched incorrectly, and once satisfied, sets the line to Complete, either manually or through the system’s own completion logic once every actual on the line has been addressed. Only when every line on a vendor invoice reaches Complete can the invoice itself be confirmed, and confirming it is what flips the invoice to Ready for payment, reverses the previously recorded project cost actuals, and books the actual cost from the vendor invoice onto the project instead. That last step matters for anyone reconciling project cost reports mid-cycle: costs on a project can genuinely shift in value between the point a subcontractor’s time is approved and the point the corresponding invoice clears verification, and finance teams need to know that is expected behavior, not a data integrity problem.

Unmatching works, but only in one direction of the workflow. A project manager can select one or more linked cost actuals from a vendor invoice line’s Matched cost actuals tab and unmatch them, but only while that line sits in In progress status. Once a line reaches Complete, unmatching is no longer available through the standard interface, which is a deliberate control: it keeps a verified invoice from being quietly altered after AP has already relied on that verification to release payment.

Implementation considerations before rollout

A few practical points are worth working through with the project accounting team before turning this on for a live subcontracting population. Fixed Price billing is not currently supported for resource-based or nonstocked subcontracting scenarios, so any subcontract lines built around milestone-based fixed pricing need a different reconciliation approach; automatic matching in this feature applies to time-and-material subcontract lines where cost actuals are generated from logged, approved work. Teams that run a mix of fixed-price and time-and-material subcontracts on the same project should map out, line by line, which subcontract lines are even eligible for automatic matching before assuming full invoice coverage.

It is also worth auditing how consistently your existing vendor invoice entry process populates the ten matching fields. If your AP team has historically entered vendor invoice lines with only project and transaction class filled in, and left task, resource category, or bookable resource blank as a matter of habit, the matching engine will happily use whatever partial field set is present, and the practical effect is a much looser match than your controls team may assume is happening. Before rollout, walk through a sample of recent invoices with both project accounting and AP to agree on which fields will be entered consistently going forward, because the strictness of this feature is only as good as the discipline behind the data feeding it.

Finally, because this capability reached general availability in the same month as several other Project Operations updates, including changes to correction journal usability and project accrued revenue reconciliation, it is worth testing subcontractor invoice matching in a sandbox environment that reflects your current configuration rather than assuming behavior documented earlier in the release wave still applies unchanged. Microsoft’s release cadence for Project Operations has been dense enough this year that features shipped in preview back in May have, in some cases, had their default behavior refined by the time they reached GA in September.

Organizations that get the field discipline right stand to remove a genuinely manual, error-prone step from project-based AP, and the audit trail built into the Verification status workflow gives finance a defensible record of exactly which actuals supported each payment decision. Routeget’s implementation teams have walked several clients through exactly this kind of subcontract reconciliation redesign, and the pattern holds consistently: the technology is ready well before the underlying data entry habits are, and that gap is where rollout timelines usually slip.


#SubcontractorInvoiceMatching #ProjectOperations #DynamicsFinanceOps #ProjectAccounting #VendorInvoiceReconciliation #ERPGovernance

Cross-Legal-Entity Fulfillment Enters Preview. Your Intercompany Setup Determines If It Works.

Operations team reviewing a network map dashboard showing warehouse fulfillment locations across a distributed retail supply chain

A retail operations director looks at a stalled online order and sees the maddening part immediately: the product is in stock, just not in the legal entity that took the sale. This happens constantly inside multi-entity retail and distribution organizations, the kind that grew by acquisition, by regional incorporation, or simply because tax and banking realities forced separate companies to hold separate inventory. To the customer, it looks like one brand. To Dynamics 365, it looks like several unrelated companies, each with its own stock ledger, unable to see past its own four walls without someone picking up a phone and negotiating a manual intercompany purchase order. Microsoft’s new cross-legal-entity fulfillment capability, built on top of Distributed Order Management (DOM), is aimed squarely at that gap. It reached private preview in version 10.0.48 this past August, with a public preview following in 10.0.49, and it is worth a serious look from any finance or operations leader running Dynamics 365 across more than one legal entity.

What Cross-Legal-Entity Fulfillment Actually Changes

DOM itself is not new. Dynamics 365 Commerce has used it for years to solve a narrower version of this problem: given an order and a set of warehouses inside a single legal entity, which location should fulfill it, based on inventory availability, distance to the customer, and cost. The new capability extends that same logic across company boundaries. DOM can now evaluate inventory sitting in a different legal entity entirely, and when it decides that location is the right one to fulfill from, it does not just flag the mismatch for someone to sort out manually. It automatically builds the full intercompany transaction chain: an intercompany purchase order in the entity that took the original sale, and a matching intercompany sales order in the entity actually holding the stock, synchronized so that when the fulfilling entity ships, both records update and the customer’s original order closes out correctly. For an organization that has been handling these situations with a spreadsheet and a Teams message between two warehouse managers, that is a real reduction in manual work, not just a marginal one.

The business case writes itself on the inventory side. Stock that would otherwise sit idle in one entity while a nearly identical order goes unfulfilled, or gets backordered, in another becomes usable. Organizations running regional legal entities for tax or regulatory reasons, but operating as one brand commercially, finally get a fulfillment engine that reflects how customers actually experience the business rather than how the org chart is drawn.

The mechanics matter just as much when things do not go according to plan. If a fulfilling entity cannot complete an order, whether because inventory shifted after DOM made its decision or a warehouse simply declines the assignment, DOM does not leave the order stranded. It marks the line rejected and attempts reassignment on its next scheduled run, first to another location within the same entity, then to a warehouse in a different one entirely. Partial fulfillment works the same way: if a location can only ship part of an order, the shortfall carries through the intercompany chain, and DOM can reassign the remainder on a later pass. For an operations leader weighing this against the status quo, that built-in retry logic is arguably as valuable as the initial sourcing decision, since it replaces exception handling that used to depend on someone noticing the problem before anyone could fix it.

The Setup Cost Nobody Puts in the Feature Announcement

None of this activates by flipping a single switch, and the gap between the headline and the configuration work is exactly where evaluation projects go wrong. The prerequisite that will consume the most calendar time is intercompany trading relationships. For every pair of legal entities that should be able to fulfill for each other, someone has to create and link a customer record in the selling entity and a vendor record in the fulfilling entity, then configure both for automatic intercompany order creation. With two entities that is a manageable afternoon of setup. With eight or ten, which is not an unusual footprint for a company that has grown through acquisition, the number of pairs that need configuring grows fast, and each one typically touches both an accounts payable and an accounts receivable process owner who may not have been in the room when this project got approved.

Beyond that, three technical dependencies are easy to miss until a pilot stalls on them. First, the DOM solver has to be set to Production Solver rather than Simplified Solver, because the simplified option cannot create intercompany orders at all, a detail that only surfaces after someone has already built out fulfillment groups and rules under the wrong configuration. Second, Azure Maps has to be enabled and licensed, because DOM uses it to calculate real distances between warehouses and delivery addresses when deciding which entity should fulfill an order, and that is a dependency an IT team evaluating this purely as an ERP feature might not budget for. Third, and most consequential for a phased rollout, every legal entity that should participate has to be explicitly added to the DOM fulfillment profile. Miss one, and DOM will not simply deprioritize its locations, it will not see them at all, which makes partial or staged rollouts across a large entity footprint riskier to get right the first time than the documentation implies.

Abstract illustration of warehouse facilities connected by a glowing digital inventory routing network

What’s Actually in Scope Today

It is worth being precise about where this feature currently draws the line, because a preview capability evaluated against the wrong assumptions leads to a rollout plan that has to be rewritten in six months. As of this preview, cross-legal-entity fulfillment covers retail order channels only: point of sale, e-commerce, call center, and headless Commerce Scale Unit orders. Sales orders originated directly in Supply Chain Management sit outside this scope for now. Microsoft has said SCM order support is on the roadmap, but roadmap language in a preview announcement is explicitly not a delivery commitment, and organizations that need cross-entity logic for B2B or wholesale sales orders processed natively in SCM should not build a 2027 plan around a capability that has not shipped yet.

The preview status itself carries the same caveat every Dynamics 365 preview does, and it is worth repeating because it gets skipped over in internal pitch decks more often than it should: preview features are for evaluation, are subject to change, and Microsoft’s own documentation is explicit that timing and functionality should not factor into purchasing decisions. Private preview in 10.0.48 moving to public preview in 10.0.49 is a normal, healthy cadence, not a signal that general availability is imminent.

How to Evaluate This Before You Pilot It

For a finance or operations leader deciding whether this belongs on next year’s roadmap, the useful first step is not a technical proof of concept. It is an honest audit of how complete the organization’s existing intercompany trading setup already is. Companies that have already done the work of linking customer and vendor records across their legal entities for other intercompany scenarios will find the DOM-specific configuration, the vendor mapping, fulfillment groups, and rules, relatively fast to layer on top. Companies where intercompany trade has been handled ad hoc, entity by entity, as problems came up, should expect the trading relationship setup itself to be the majority of the project timeline, not the DOM configuration.

It is also worth involving accounts payable and accounts receivable process owners earlier than a typical fulfillment feature would require, since this changes the volume and pattern of intercompany transactions those teams reconcile every period. A pilot scoped to a single, well-understood pair of legal entities, run alongside the existing manual process rather than replacing it immediately, gives a much clearer read on actual fulfillment savings and reconciliation impact than a broad rollout attempted on day one of public preview.

Cross-legal-entity fulfillment addresses a real and common operational gap, and the underlying DOM engine it builds on is mature technology, not an experimental one. The preview label applies to the cross-entity orchestration layer, not to order fulfillment optimization itself. Routeget Technologies has walked a number of multi-entity clients through intercompany trade configuration for other reasons, and the pattern holds here too: the technology adoption timeline is rarely the bottleneck. The completeness of the underlying intercompany setup is.


#DistributedOrderManagement #Dynamics365SCM #IntercompanyFulfillment #OmnichannelFulfillment #SupplyChainAutomation