Accounts Payable Settlement Priority Is Now On by Default in Dynamics 365 Finance. It Solves a Narrower Problem Than It Sounds.

Finance manager reviewing a vendor payment and cash flow dashboard on office monitors

A controller at a mid-market distributor recently asked her Dynamics 365 partner a reasonable question: now that accounts payable settlement priority is on by default in the 10.0.49 update, does that mean the system will hold back lower-priority vendors during a tight cash week and pay the critical ones first? The honest answer disappointed her. It doesn’t do that, and understanding exactly why is the difference between using this feature correctly and assuming it covers a problem it was never built to solve.

Dynamics 365 Finance 10.0.49 reached general availability for self-update customers in September 2026, with auto-update environments following in October. Buried in the Cash and Bank Management section of the release notes is a single line: “Accounts payable enable settle with priority” is now on by default. For years this capability existed behind a feature flag that most organizations never touched, largely because nobody explained clearly what problem it actually solves. Now that Microsoft has switched it on for everyone, finance teams are encountering it for the first time in production, often without having reviewed what it changes.

What Accounts Payable Settlement Priority Actually Does
Abstract illustration of digital invoices sorted into a prioritized settlement queue

Settlement priority operates at a narrower point in the payables process than most people assume. It has nothing to do with deciding which vendors get selected for a payment run in the first place. That job still belongs to the payment proposal, whether generated manually or through the automated vendor payment proposal process, and both of those continue to select invoices based on due date and cash discount date windows exactly as they did before this update.

What settlement priority governs is what happens after a payment already exists and needs to be applied against a vendor’s open invoices. When a single payment doesn’t fully cover everything outstanding for that vendor, perhaps because of a short remittance, a disputed line held back from the total, or simple rounding, the system has to decide which invoices get settled first and which remain partially or fully open. Before this update, that decision followed either manual selection or a straightforward date-based default. With settlement priority enabled, it instead follows a priority number you assign to the vendor, configured on the Settlement priority tab of the Accounts Payable Parameters page, with the option to extend the same logic into automatic settlement once both the “Prioritize settlement” and “Automatic settlement” parameters are turned on together.

That is a genuinely useful piece of consistency. Large accounts payable teams processing thousands of vendor transactions a month have historically dealt with inconsistent settlement outcomes when a payment fell short of the full balance, sometimes resolved by whichever clerk happened to be settling the transaction that day. Replacing that variability with a defined, auditable order is a real improvement, and it is the kind of quiet process-integrity fix that rarely gets attention until an auditor asks why two similar short-payment scenarios were resolved two different ways six months apart.

The Gap Between What CFOs Expect and What Ships

Where the confusion starts is in how naturally this feature’s name suggests something bigger. “Settle with priority” sounds like it should mean strategic vendor prioritization during cash-constrained periods, and that is precisely the capability many finance leaders have wanted from their ERP for years. If working capital tightens ahead of a large tax remittance or a seasonal inventory build, the instinct is to want the system to automatically defer discretionary vendors and protect payments to single-source suppliers or anyone with contractual penalty clauses for late payment.

That is not what happens here, and it’s worth being direct about the practical consequence. If your organization relies on the automated vendor payment proposal process to generate weekly or monthly payment runs, turning on settlement priority changes nothing about which invoices get proposed for payment. The proposal still pulls invoices based on due date adjustments and minimum payment date criteria defined in the process automation setup, with no awareness of cash position, vendor criticality, or the priority numbers you may have just configured. A vendor ranked as low priority in your new settlement configuration will still be selected for payment on schedule if its invoice falls inside the proposal’s date window, because priority only comes into play once a payment already exists and needs to be matched against that vendor’s open balance.

For genuine cash-position-driven prioritization, the lever still sits where it always has: in how proposals are filtered before generation, in manual holds placed on specific vendor accounts, or in a dedicated treasury or AP automation layer sitting alongside Dynamics 365 that can factor in real-time cash forecasts. Settlement priority is a settlement-application control, not a payables strategy tool, and treating it as the latter risks a finance team believing they have protection they don’t actually have during the next liquidity crunch.

What to Check Before This Silently Changes Behavior

Because this shipped as an on-by-default change rather than an opt-in feature, the practical risk isn’t that it’s dangerous. It’s that it’s invisible until someone notices settlement behavior has shifted. A few things are worth confirming in any environment that has moved to 10.0.49 or will auto-update in October.

First, check whether priority numbers have ever been assigned to vendors in your instance. If settlement priority is now active but no one has configured priority values, the system will apply whatever default ordering exists, and finance staff should know what that default actually is rather than assume it matches prior manual practice. Second, review whether “Automatic settlement” is also enabled alongside “Prioritize settlement,” since that combination extends priority-based logic into unattended settlement runs rather than only manual ones, which raises the stakes on getting the configuration right before it processes a batch overnight. Third, walk through a short-payment scenario in a test environment with a vendor that has multiple open invoices, to see firsthand which invoice gets settled and which remains open, rather than relying on documentation alone to predict the outcome.

Where This Fits in a Broader Payables Strategy

None of this diminishes the value of the underlying capability. Consistent, auditable settlement behavior matters more as transaction volumes grow and as more of the payables cycle runs through automation with less manual review at each step. Organizations running multi-entity or shared-service AP operations, where the same clerk may be settling transactions across dozens of legal entities with different vendor relationships, stand to benefit the most from replacing ad hoc judgment calls with a defined priority scheme.

The mistake to avoid is treating this release note as evidence that Dynamics 365 now handles strategic vendor prioritization end to end. It handles one well-defined piece of a much larger payables process, and the other pieces, cash forecasting, proposal filtering, vendor criticality scoring, still need to be designed deliberately, whether through native configuration, process automation rules, or a third-party AP platform. Firms that have implemented and tuned payables processes across enough Dynamics 365 environments tend to see this pattern repeat with almost every feature flip: the capability itself is sound, but the assumption about its scope is usually larger than what shipped. Reading the fine print before the next auto-update cycle is a cheap way to avoid finding out the gap the hard way, during the week cash is actually tight.


#DynamicsFinanceOps #AccountsPayable #VendorPaymentPriority #CashManagement #WorkingCapital #FinanceAutomation

Power BI Semantic Model Refresh Just Got Granular. Your Dynamics 365 Reports Still Refresh Everything.

A solution architect reviews a data refresh and capacity monitoring dashboard on a large screen at night

A Fabric capacity dashboard turning red at two in the morning is one of the more specific kinds of dread in Dynamics 365 reporting work. Somewhere in the tenant, a scheduled job kicked off a full refresh of a forty-table semantic model built over Dataverse-linked Finance and Operations data, and now every other overnight pipeline is queued behind it. The general ledger fact table alone might carry a decade of posted transactions. None of that history changed since yesterday. It gets reloaded anyway, because until recently, “refresh” in Power BI meant one thing: everything, from scratch, every time.

That default is finally negotiable. Power BI’s August 2026 update made granular semantic model refresh controls generally available in both Desktop and the service, giving report owners a real choice between refreshing schema, refreshing data, or refreshing both, down to the level of an individual table. For anyone maintaining Power BI models over Dynamics 365 F&O, Business Central, or Dataverse data more broadly, this is the kind of change that should prompt an actual architecture review rather than a shrug and a changelog skim.

What changed, specifically

The expanded Refresh control in Power BI Desktop and the service now exposes three distinct operations instead of one. Refresh Schema and Data is the familiar default: Power BI checks the source for structural changes, applies them, and then reloads data. Sync Schema Only updates the model’s structure, picking up new or renamed columns and data type changes, without pulling fresh rows. Refresh Data Only does the opposite: it reloads current values while deliberately ignoring any structural drift at the source, which matters more than it sounds like it should when a source system adds a column you have no interest in modeling yet.

Critically, this granularity now applies at the table level through the UI itself, not just through a REST call. Select a table in the Data pane, and you can choose to refresh its schema, its data, or both, independently of what happens to the rest of the model. Under the hood, this builds on the Enhanced Refresh API’s objects parameter, which has supported table- and partition-level targeting in JSON refresh requests for several years. What is new is that the capability is no longer something you had to script or automate through Power Automate to get; it is a first-class option in the interface most report authors actually use.

The timing lines up with Direct Lake’s move to general availability for OneLake semantic models in March 2026. Direct Lake models query OneLake data at query time instead of importing it into a separate in-memory copy, which changes what “refresh” even needs to accomplish. A schema-only sync is explicitly called out as the more sensible operation for many Direct Lake scenarios, since the underlying data is already current in OneLake and what actually needs updating is the model’s awareness of structural changes upstream.

Why Dynamics 365 semantic model refresh costs add up fast

Generic BI advice treats all semantic models as roughly interchangeable, but Dynamics 365 F&O and Business Central models have a particular shape that makes blanket full refreshes disproportionately expensive. A handful of tables, typically the ones behind AP aging, open sales orders, or current inventory positions, change constantly and need frequent, current data. Most of the rest of the model, historical GL transactions, closed projects, prior fiscal years, is functionally read-only from one day to the next. When Fabric Link or the older entity-store approach lands both categories in the same semantic model and a nightly job refreshes the whole thing on one schedule, the model pays the full cost of reprocessing static history every single time it wants fresh numbers for the tables that actually moved.

That cost shows up in two places that matter to whoever owns the Fabric capacity bill. Wall-clock refresh duration extends as historical fact tables grow, which is a slow-motion problem that eventually collides with the maximum refresh duration ceilings on shared and Premium capacity. And CU consumption on Fabric capacity is metered by the compute the refresh operation actually performs, so reprocessing unchanged partitions burns capacity that has no analytical payoff. Neither problem is solved by adding capacity; both are solved by refreshing less.

Applying granular refresh to a Dynamics 365 semantic model

The practical starting point is an honest table-by-table audit of your existing model, sorted by two questions: does this table’s data actually change day to day, and does its schema drift when Microsoft ships a Finance and Operations or Business Central update. Tables like open transactions, current inventory on-hand, and active project status are obvious candidates for a Refresh Data Only cadence that runs frequently, maybe hourly if the business case justifies it, without touching schema at all. Large historical fact tables, closed fiscal periods, and reference dimensions that rarely change structure are candidates for a much less frequent Refresh Schema and Data pass, perhaps weekly, with the understanding that if Microsoft renames a field or adds a column mid-week, you will not see it in the model until the next scheduled schema sync.

Abstract illustration of a few illuminated data table blocks refreshing among many dimmed, unchanged ones

Where this pairs particularly well with existing Power BI capability is incremental refresh policies on the largest transaction tables. Incremental refresh already partitions a table by date so that only the current period’s partition gets reprocessed on a routine basis; layering table-level refresh selection on top means you can decide, table by table, whether even that partitioned refresh needs to run tonight or can wait until the weekend. For a semantic model spanning several Dynamics 365 legal entities, this combination is usually the difference between a refresh job measured in tens of minutes and one measured in hours.

Implementing this through the Enhanced Refresh REST API rather than clicking through the UI is worth the extra setup for any model refreshed on a schedule, because it lets you express the table list as configuration rather than tribal knowledge sitting in someone’s memory of which tables to click. A request that targets specific tables through the objects array, with applyRefreshPolicy set appropriately for whether you want the incremental refresh window respected, is straightforward to build and far easier to audit six months later than a manual process. Teams running Power Automate flows or Azure Data Factory pipelines to orchestrate refreshes should treat this as the moment to replace a single “refresh the whole dataset” call with a small set of targeted requests, each on its own cadence.

Where this still needs judgment, not just configuration

Schema-only sync deserves particular caution in Dynamics 365 contexts because Microsoft’s release cadence for F&O and Business Central genuinely does add and rename fields with some regularity, and a model that never runs a full schema sync will eventually diverge from its source in ways that surface as confusing blank columns or broken relationships rather than clean errors. A reasonable middle ground is to schedule schema syncs on their own cadence, independent of data refreshes, rather than skipping them indefinitely because a table’s data refresh doesn’t need one.

It is also worth being explicit with report consumers and downstream teams about which tables now run on which schedule, since the old assumption that “refreshed this morning” meant the entire model was current no longer holds once refresh granularity is in play. A short data dictionary note next to each table, or a dedicated tab in the workspace documentation, prevents the kind of confusion where someone builds a decision on a historical table that was deliberately left out of last night’s run.

The architecture conversation this actually forces

The real value of granular refresh isn’t the UI convenience, it’s that it forces a semantic model design conversation that most Dynamics 365 reporting teams have been avoiding: which tables in this model are operational and which are archival, and should they even live in the same refresh schedule, or the same model, at all. Teams that have this conversation now, while the tooling to act on the answer just became native to the product, will end up with leaner Fabric capacity bills and faster refresh windows than teams that keep treating every semantic model as a single monolithic refresh unit. At Routeget, this is usually the point in a Fabric or Power BI engagement where we walk a client’s existing model inventory table by table rather than accepting the assumption that a full nightly refresh is simply the cost of doing business with ERP-scale data.


#PowerBIRefresh #SemanticModels #DirectLake #FabricCapacity #DynamicsFinanceOps #BusinessCentral

Project Operations Subscription Billing Is Live, But Not for Every Deployment

Finance controller reviewing a recurring billing schedule dashboard on a laptop

A finance director at a mid-size systems integrator called her Microsoft partner last week with a simple question: can we finally bill our managed services retainers automatically instead of re-keying the same fixed-fee lines into a project invoice every month? She had just read a Message Center notice about Project Operations subscription billing and wanted to know how soon her team could stop doing this by hand. The answer she got was more complicated than the announcement suggested, and it is worth walking through, because the gap between what is generally available today and what is entering preview later this month will shape a real budgeting decision for a lot of professional services firms this quarter.

Project Operations Subscription Billing: Two Announcements, Not One

There are actually two separate pieces of functionality connected to this topic, and conflating them is the easiest way to make a bad planning decision. The first, “enable project fee journals to support subscription billing,” has been generally available since Dynamics 365 Finance version 10.0.46, released in October 2025. It lets a project generate a billing schedule through the Subscription Billing module, using Project Fee Journal as the invoice transaction type instead of a standard project invoice. The second, tracked in Microsoft’s Message Center as MC1472430 and titled simply “support subscription billing for Project Operations,” entered public preview on September 30, 2026. It promises recurring billing on flexible cadences, tiered pricing models, subscription hold and termination handling, and refund management, described by Microsoft as reducing manual intervention in recurring invoicing. Only the first one exists in production today. The second is a preview, and previews change shape before they reach general availability.

How the Fee-Journal Mechanism Actually Works

For the capability that is live now, the workflow starts on the project record itself. From Project management and accounting, a user creates a new billing schedule directly from the project, and the system automatically populates the customer account, the project ID, and the funding source. The invoice transaction type gets set to Project Fee Journal rather than Sales Order, which determines how the billing schedule lines behave. Each line carries a fee category, a unit price, and the usual tax fields, but it flows through work-in-progress and accrual postings before it ever becomes a customer-facing invoice.

That sequencing matters more than it sounds. Rather than posting a project invoice the moment work is recorded, the system books WIP and accrual entries through the fee transaction first, then generates the actual invoice on a schedule, whether monthly, quarterly, or however the contract is structured. A firm can choose from three posting behaviors: generate the fee journal only and create invoices manually later, generate the journal and stop at an invoice proposal for review, or post the invoice automatically in one step. That range gives controllers real choice over how much human review sits between recognized revenue and a document that goes out to the client.

Finance controller reviewing a recurring billing schedule dashboard on a laptop

The catch, and it is a significant one, is that this fee-journal path is only available for Project Operations deployments that run on the Finance and Operations platform, what Microsoft’s own documentation refers to as Project Operations for manufacturing. A standalone deployment of Project Operations, the version many services firms chose specifically because it does not require standing up the full Finance and Operations stack, cannot use it. If your organization licensed Project Operations to avoid exactly that complexity, the subscription billing capability that shipped last October simply is not on your platform, no matter how current your update cadence is.

Why the Deployment Distinction Is the Actual Decision Point

This is where the finance director’s original question gets harder to answer cleanly. If her firm runs the Finance-integrated deployment, the fee-journal mechanism is already available, and the work is largely configuration: enabling the relevant features in Feature management, setting project stage rules to trigger billing schedule creation automatically, and deciding which of the three posting behaviors matches her team’s risk tolerance for unattended invoicing. If her firm runs standalone Project Operations, the near-term answer is to watch the MC1472430 preview closely rather than assume it will simply extend the same mechanism to her platform.

Microsoft’s release documentation for 2026 wave one describes the fee-journal capability specifically in the context of manufacturing deployments, and nothing in the public preview announcement confirms that the broader recurring billing framework will be deployment-agnostic once it reaches general availability. Firms that commit new client contracts to a subscription billing structure on the assumption that Project Operations will automate it end to end, without first confirming which platform variant they run, are setting up a manual workaround they did not budget for. That is an expensive mistake to discover six months into a new retainer agreement.

There is a real financial argument for making this move regardless of which deployment a firm is on, and it has less to do with saving a few hours of invoice preparation than with getting revenue recognition right. Because the fee-journal mechanism books WIP and accrual entries ahead of the customer invoice, it gives finance teams a documented, systematic separation between when value is delivered and when cash is billed. That separation is exactly what supports ASC 606 and IFRS 15 compliance for recognizing revenue independent of billing milestones. A firm still reconciling that gap manually in a spreadsheet, project by project, is carrying audit exposure that this feature is specifically built to remove. That argument for prioritizing the upgrade path is stronger than “we bill retainers and want less manual work,” even though the manual-work complaint is usually what starts the conversation.

Abstract illustration of a recurring billing cycle with glowing invoice nodes

What to Check Before the Next Contract Renewal Cycle

Before signing a new managed services or retainer agreement on the assumption that Project Operations will handle the billing automatically, confirm three things. First, identify which Project Operations deployment your organization actually runs, since the terminology in vendor conversations, and even in some Microsoft documentation, does not always make the distinction obvious to someone outside the implementation team. Second, if you are on the Finance-integrated deployment, treat this as a configuration and change-management project rather than a licensing question. Feature management settings, project stage rules, and the choice of posting behavior all need to be worked through with whoever owns your Dynamics 365 Finance environment before the first live billing schedule goes into production.

Third, if you are on standalone Project Operations, do not build a client-facing commitment around a preview feature. Track the Message Center entry, ask your partner directly whether the general availability scope will include your deployment type, and keep the manual process in place as a fallback until that answer comes back in writing rather than inferred from a roadmap post. Preview features are, by definition, subject to change, and a contract term written around one is a liability if the feature narrows or slips before it ships broadly.

The subscription billing announcement is a genuine step forward for firms trying to move recurring engagements off manual invoicing, and the fee-journal mechanism that already exists proves the underlying accounting model works in production. What it is not, yet, is a platform-wide capability every Project Operations customer can turn on this quarter. Firms that treat the distinction seriously now will spend less time unwinding a contract structure that outran their tooling. We have walked several clients through exactly this kind of platform-versus-roadmap gap during Project Operations rollouts, and the pattern holds: the tooling question is almost always simpler to answer once the deployment type is confirmed first, before a single retainer contract gets rewritten around a capability that may not yet apply to it.


#ProjectOperations #SubscriptionBilling #RevenueRecognition #ProfessionalServicesFinance #DynamicsFinanceOps #ERPGovernance

Document Intelligence 4.0 Gave AI Builder Table Confidence Scores. Most Invoice Models Still Can’t Use Them.

Finance analyst reviewing an AI-extracted invoice line-item table with confidence indicators on a laptop screen

A Dynamics 365 Finance implementation team building an automated three-way match workflow ran into a strange gap last month. Their AI Builder model pulled line items off vendor invoices cleanly enough, quantities, unit prices, and extended amounts all landing in the right columns, but the confidence score field meant to flag shaky extractions for human review came back empty for every table row. The fields around the table had confidence values. The table itself did not. Nobody on the team had touched the model’s configuration since it went into production eight months earlier, so the assumption was a bug, or maybe a licensing issue. It was neither. It was a decision made on day one, buried in a dropdown most builders click past without a second thought: whether the model was trained as a Fixed Template document or a General document.

That distinction matters more than it used to, because AI Builder table confidence scores quietly became a real capability when Microsoft folded Azure AI Document Intelligence 4.0 into the document processing model, and that upgrade behaves differently depending on which training path a model took.

Finance analyst reviewing an AI-extracted invoice line-item table with confidence indicators on a laptop screen

What Document Intelligence 4.0 Actually Changed

Microsoft moved AI Builder’s document processing engine onto Azure AI Document Intelligence 4.0 in stages, with public preview starting December 12, 2024 and general availability landing April 30, 2025. For a lot of Dynamics 365 and Power Platform teams, that rollout came and went without much fanfare, since existing models kept working exactly as before. The upgrade wasn’t a forced migration. It was closer to a set of new tools sitting behind the same interface, available to anyone building or rebuilding a model from that point forward.

The practical additions are worth knowing because they change what’s realistic to automate. OCR accuracy improved, particularly on dense or low-quality scans, the kind that come off a fax gateway or a photographed receipt rather than a clean PDF. Layout detection got better at handling documents where content shifts position from one vendor to the next. Signatures became a taggable field type in their own right, not just background noise the model had to work around, which opens the door to processing signed contracts, lease agreements, and approval forms in ways the older engine handled poorly. And confidence scoring extended down to the table level: individual cells, not just whole fields, can now carry a numeric value a flow or canvas app can act on.

That last point is where the invoice team’s gap came from.

The Model Type Decision Behind AI Builder Table Confidence Scores

AI Builder’s document processing wizard offers three starting points: Fixed Template documents, General documents, and an option to extend the prebuilt Invoices model with custom fields. Fixed Template is built for layouts that don’t move, the same vendor sending the same invoice format every time, and it trains fast because the model only has to learn a small set of positions rather than reason about structure from scratch. General documents is built for the opposite case, varied formats, inconsistent layouts, documents that might come from dozens of different sources, and it trains more slowly because it has to learn structural patterns rather than fixed coordinates.

Here’s the part that doesn’t show up until you go looking for it: table and cell-level confidence scores are only available on models trained as General documents. A Fixed Template model can absolutely extract a table, and it can extract it accurately, but it will not return a confidence score for that table’s cells. Field-level confidence outside of tables works normally on both training types. It’s specifically the table data, line items, schedules, itemized charges, where the gap shows up.

For an accounts payable automation scenario built around Dynamics 365 Finance or Business Central, this is not a minor footnote. Line-item extraction is usually the whole point. A header field like vendor name or invoice total is easy to validate against a purchase order regardless of confidence scoring, but line-item quantities and unit prices are where a bad OCR read causes a real financial error, and they’re exactly the data a human-in-the-loop review queue needs a confidence threshold to triage. A team that chose Fixed Template because their vendor’s invoice format never changes gets faster training and solid extraction, but loses the one signal that would tell them which rows need a second look before they hit the general ledger.

Signatures Change What’s Worth Automating

The signature field type deserves its own mention because it shifts the category of documents worth running through AI Builder at all. Before Document Intelligence 4.0, a signed document was something the model either ignored or occasionally misread as stray marks corrupting a nearby field. Now a signature can be tagged, detected, and reported on as a discrete extraction result, true or false, with its own bounding box.

That matters for scenarios well outside invoice processing. A Project Operations team processing subcontractor agreements can now confirm programmatically whether a returned PDF actually carries a signature before routing it into an approval flow, rather than relying on someone opening every file. A procurement team validating vendor onboarding paperwork gets the same benefit. It’s a narrow capability, but it removes a manual verification step that previously had no automated equivalent in AI Builder at all.

Abstract 3D grid of data cells representing table confidence scoring in AI Builder document processing

Migrating an Existing Model Without Starting Over

Teams running an older model built before the Document Intelligence 4.0 rollout are not required to rebuild from zero to get these capabilities, and the upgrade path is more forgiving than the version number might suggest. According to Microsoft’s own documentation, re-tagging every training document is only necessary if you’re adding new fields, checkboxes, tables, or signature detection that the original model didn’t have, or adding new documents to a collection. If the goal is simply to move an existing, working set of tagged fields onto the newer engine, editing and republishing the model carries the upgrade forward without forcing a full retagging pass.

That’s a lower bar than most people assume when they hear “new model version,” so the practical blocker for most teams isn’t technical effort. It’s the training-type decision made at the start, which can’t be changed after the fact. There’s no toggle that converts a Fixed Template model into a General documents model in place. If table confidence scores turn out to matter after production models are already live, the fix is a genuine rebuild, tagging documents again under the General documents path, not a settings change.

Getting Confidence Scores Into an Actual Review Workflow

Once a model is trained the right way, pulling confidence values into something a human reviewer or a flow can act on is straightforward. In a canvas app, a formula like First(FormProcessor1.Results.'Table 1').Amount.Confidence returns the score for a specific cell, and that value can drive conditional formatting, flag rows below a chosen threshold in red, or filter a gallery down to only the extractions that need eyes on them. In a cloud flow, the Extract Information from Documents action exposes the same values through dynamic content, which makes it possible to branch a flow so that high-confidence invoices post automatically while anything below the threshold routes to an approval step in Teams or a shared queue.

Setting that threshold is more art than science. Microsoft doesn’t publish a universal number, because the right cutoff depends on the cost of an error against the cost of unnecessary review. A finance team automating high-dollar vendor invoices will reasonably set a stricter threshold than a team processing low-value expense reports, and it’s worth running a batch of real historical documents through the Quick Test tool before committing to a number, since that’s where the actual confidence distribution for your document set becomes visible rather than theoretical.

Before You Build the Next One

The rebalancing lesson here isn’t that General documents is always the right choice. Fixed Template models train faster, tend to hit high accuracy sooner with fewer sample documents, and remain the right call for genuinely stable, single-format use cases where table validation isn’t part of the workflow. The mistake is making the training-type decision without knowing it also decides whether confidence scoring will be available on table data later, and finding that out only after a review process built around those scores comes up empty.

Anyone scoping a new document processing model, or auditing one already in production, should treat this as a five-minute check worth doing now rather than a surprise found in eight months. If line-item or table-level confidence scoring is part of the plan, even a future plan, General documents is the only path that supports it, and that has to be decided before the first sample document gets tagged.

At Routeget Technologies, this is the kind of gap we look for early in an automation build, not because the underlying capability is complicated, but because a wrong assumption made in a five-minute setup screen tends to surface eight months later, in production, exactly when it’s most expensive to fix.


#AIBuilder #DocumentIntelligence #InvoiceAutomation #AccountsPayableAutomation #PowerPlatform #EnterpriseAI

Dynamic Work Classification Rules Are Now On by Default. Your Warehouse Templates Still Need a Rewrite.

Warehouse operations supervisor reviewing an automated work routing dashboard on a wall-mounted screen in a distribution center

A client I spoke with last month runs three distribution centers and had built twenty-two separate work templates just to route outbound work by carrier, shipping deadline, and pick zone. Nobody had designed it that way on purpose. It grew one exception request at a time, until the warehouse team could no longer explain why template seventeen existed or what would break if someone deleted it. Then Supply Chain Management 10.0.49 shipped in September 2026, and dynamic work classification rules, which had been sitting in feature management as a production-ready preview since June, switched on by default. Nobody flipped that switch deliberately. It just happened, and now every one of those twenty-two templates is technically obsolete even though none of them have been touched.

That is roughly the position a lot of warehouse teams are in right now, whether or not they knew this feature existed. Understanding what a Power Fx formula here can and cannot do is the difference between quietly benefiting from a real simplification and quietly breaking work assignment logic nobody remembers building.

What Dynamic Work Classification Rules Replace

The traditional approach to routing warehouse work in D365 Supply Chain Management has always been template proliferation. Every combination of conditions, say three carriers crossed with two shipping windows crossed with four pick zones, has historically meant a separate work template with its own pool assignment, priority, and location directive setup. It works, but it fails quietly: someone adds a fourth carrier, forgets to clone the templates correctly, and outbound work for that carrier silently inherits default priority instead of being expedited.

Dynamic work classification rules collapse that structure into a single work template plus a Power Fx formula that evaluates conditions at the moment work is created, and optionally again when the underlying load changes. Instead of a template per carrier, one rule with a Switch statement handles all three:

Switch(workTable.Load.CarrierCode,
    "Carrier1", {WorkPoolId: "Carrier1", DefaultWorkPriority: 100},
    "Carrier2", {WorkPoolId: "Carrier2", DefaultWorkPriority: 50},
    "Carrier3", {WorkPoolId: "Carrier3", DefaultWorkPriority: 10}
)

That single formula does the job of three templates, and when a fourth carrier gets added, it is one more line in a Switch statement rather than a cloned template someone might configure incorrectly.

Two Points Where the Formula Actually Runs

The mechanics matter here because they determine what data a rule can see. A classification rule has a scope, and the scope is either "Work" or "Work and initial work lines." A work-scoped rule runs once, after the work header itself is created, and it can only reference header-level objects: the work record, its associated load, shipment, wave, and any transportation management appointment tied to it. That is enough for the carrier and deadline examples above, because carrier code and shipping schedule live on the load.

A rule scoped to work and initial work lines runs twice: once for the initial pick line, where it has access to line-level data including the item master record, warehouse-specific item settings, and the pick zone, and again at the header level using the same objects a work-scoped rule sees. This matters when classification depends on something below the header, such as routing freezer-zone picks to a restricted work class that only certified workers can claim, which requires referencing workLine.ZoneId, a field only available at the initial-line evaluation.

Picking the wrong scope is a common early mistake. A rule written to reference workLine fields will simply fail or return blank values if it is configured with "Work" scope, because that data object was never in scope for the formula to read from.

Reading Blank and Empty String Correctly

The formula's return values control four fields on the work header: the work pool ID, a numeric default work priority, a set of location directive code overrides, and, for line-scoped rules, work class overrides. The distinction that trips up almost everyone writing their first rule is what happens when a field is omitted or explicitly cleared.

Returning Blank() for a field, or simply leaving it out of the returned record, tells the system to preserve whatever value the work template already had configured. Returning an empty string actively clears that value. These look similar on a quick read of a formula, but they produce opposite outcomes, and the difference is invisible until a load hits an edge case the formula author did not anticipate and the work pool field ends up wiped instead of defaulted. Anyone porting logic from a spreadsheet of business rules into Power Fx should treat this distinction as a required review step, not a detail to catch during testing.

Time-based priority formulas are where this feature earns its keep beyond simple carrier routing. A formula that reads a load's scheduled ship time and converts it into a same-day numeric priority, nine in the morning becoming priority 900 and three in the afternoon becoming 1500, while pushing anything scheduled for a future date to a flat low-urgency value, replaces what used to require either a batch job recalculating priorities on a schedule or a set of static templates keyed to time windows that someone had to remember to update every quarter.

The Reclassification Setting That Determines Whether This Helps or Hurts

The warehouse management parameter setup has a field called "Work classification on load update" with two practical states: disabled, meaning rules fire once at work creation and never again, and synchronous, meaning any load change, a carrier reassignment being the obvious case, triggers an immediate reclassification of every work record tied to that load before the user's screen returns.

Synchronous reclassification is correct in low-volume environments where a carrier reassignment genuinely should re-route work immediately. In a high-volume distribution center running continuous wave releases, setting this to synchronous means a single load correction by a transportation coordinator can trigger a reclassification pass across hundreds of work records in the same transaction, and that user experiences the delay directly. Time-based priority formulas compound this: if a formula depends on current time rather than a fixed schedule value, it needs recalculating on a recurring interval rather than only on load events, pushing the design toward a scheduled batch job instead of synchronous evaluation. Teams that enable this feature without deliberately choosing this setting are, by default, accepting whatever behavior comes pre-configured, which is not necessarily what their volume can tolerate.

Abstract illustration of a digital routing engine sorting warehouse work into color-coded priority lanes

Migrating Off Template Sprawl Without Guessing

The practical migration path starts with the Preview function built into the rule editor, which evaluates a candidate formula against existing work headers without committing any changes, letting a solution architect validate logic against real production data before it goes live. The Copy function on existing rules turns a working formula into a starting point for the next variation rather than requiring every rule to be written from scratch.

The one alignment check that gets skipped most often is making sure work template grouping settings match what the formula actually classifies on. A rule that assigns work class based on pick zone only makes sense if the underlying work template groups work so that each header contains lines from a single zone. If the template grouping mixes zones within one work header, a zone-based classification formula is evaluating against a header that spans multiple zones, and the result will not reflect the intent of the rule. This is a configuration mismatch, not a Power Fx defect, and it will not surface as an error, only as classification results that look wrong for reasons that are not obvious from the formula itself.

There is also no built-in mechanism for chaining multiple rules or setting rule priority across rules. Only one dynamic work classification rule can be attached to a given work template, so any scenario requiring multiple conditional layers has to be built as nested logic within a single formula rather than as a stack of separate rules evaluated in order. Teams used to unified routing's classification rulesets in Customer Service, where multiple rulesets and conditions can be layered, will find this a meaningfully different mental model, and formulas that try to replicate that layered structure will need to do it with nested If and Switch statements rather than rule ordering.

Where This Actually Pays Off

The twenty-two-template warehouse from the opening is not a rare case. Template sprawl is what happens by default in any warehouse operation that has been live for more than a couple of years and has accumulated exception handling one request at a time. Dynamic work classification does not eliminate the need to think through routing logic, but it moves that logic into a formula that a single person can read end to end, version, and test against real data before deployment, rather than a folder of templates whose relationships to each other exist only in institutional memory. Getting the scope, the Blank-versus-empty-string distinction, and the reclassification timing right the first time is what determines whether that consolidation actually reduces operational risk or just relocates it into a formula nobody has reviewed yet. Routeget's warehouse implementation work increasingly starts with exactly this kind of template audit, because the fastest way to write a good classification rule is to first understand precisely which decisions the old templates were actually encoding.


#DynamicsSCM #WarehouseManagement #PowerFx #WarehouseAutomation #SupplyChainOptimization

Power Apps’ Model App-Builder Skill Just Reached GA. The Approval Step Needs a Real Definition.

IT director reviewing an AI-generated model-driven app blueprint on a monitor

An IT director at a mid-sized distribution company got a message last week that would have been unthinkable two years ago: a business analyst on the finance team had built a complete case-management app, tables, forms, a security role, and an approval workflow included, in an afternoon, by describing what she needed in plain English. No developer was involved. No ticket sat in a backlog. The app worked on the first try. The IT director’s reaction was not relief. It was a question nobody on her team could immediately answer: who actually checked what that security role grants access to? The tool behind the app, it turned out, was the newly generally available Power Apps Model App-Builder Skill.

That scenario is no longer hypothetical. Microsoft’s September 2026 Power Platform update confirmed general availability for the Power Apps Model App-Builder Skill, a capability that lets makers use AI coding tools such as GitHub Copilot CLI or Claude Code to generate an entire model-driven app from a natural-language description, including Dataverse tables, forms, views, sitemaps, security roles, business process flows, and business rules. This sits alongside the already-GA generative pages capability, which handles individual pages inside a model-driven app the same way. Put together, the distance between “someone wrote a paragraph describing an app” and “a production business process exists in Dataverse” has collapsed to something close to zero.

For a CIO or IT director already managing a Power Platform footprint, the interesting part isn’t the productivity story. That part is straightforward: fewer requests stuck behind a scarce pool of Dataverse developers, faster turnaround for genuinely simple line-of-business apps, and a natural entry point for citizen developers who previously needed a professional developer just to get a security role configured correctly. The interesting part is what happens between the prompt and the deployment, because Microsoft did build a checkpoint into this workflow. The question worth asking before turning it on broadly is whether that checkpoint checks the things an organization actually needs checked.

What the Power Apps Model App-Builder Skill Actually Generates

The documented workflow follows a pattern Microsoft has used elsewhere in its AI code generation tools for Power Apps: a planner agent reads the natural-language requirement and proposes a plan describing what it intends to build, the maker reviews that plan and can ask for adjustments, the maker confirms once the plan matches intent, and only then do specialized agents generate the artifacts and deploy them. Some workflows in this family include an optional verification pass using automated browser testing before the app goes live. Microsoft’s own guidance is candid about where responsibility lands afterward: the tools make “a best-effort attempt to generate complete, production-ready code with accessibility and security best practices,” but the maker is ultimately responsible for validating what gets produced.

That single sentence is worth sitting with, because it reframes what “the app worked on the first try” actually means. It means the functional description matched. It does not mean the security role’s field-level permissions match the organization’s data classification policy, or that the generated business rule doesn’t create a downstream conflict with an existing plugin, or that the sitemap navigation doesn’t expose a table that shouldn’t be visible to that user’s role. A business analyst confirming a plan in the reviewer step is answering “does this do what I described,” which is a different question from “is this safe to run in production,” and most of the people who will use this tool are, by design, not the people equipped to answer the second question.

Abstract illustration of an AI-generated application blueprint with tables and workflow icons being approved by hand

Not Every Piece of This Carries the Same Guarantee

There’s a second nuance worth flagging before any organization treats “Model App-Builder Skill: GA” as a blanket green light. The broader family of AI code generation tools for model-driven apps includes capabilities at different maturity levels within the same feature set. Microsoft’s own documentation for the related generative pages capability, for instance, states plainly that connector support for reaching data outside Dataverse is a preview feature, and adds the standard caution that “preview features aren’t meant for production use and may have restricted functionality.” That distinction matters in practice: a maker building a generated page or app that only touches Dataverse tables is working with generally available functionality, while a maker who extends that same generation flow to pull data through a connector has quietly stepped into preview territory without necessarily realizing it, since the interface doesn’t force that distinction on them.

The practical lesson isn’t that this capability is unready. It’s that GA status attached to a feature name in a release announcement doesn’t automatically extend to every path a user can take through that feature. Anyone signing off on a broad rollout should ask, capability by capability, which specific paths are GA and which are still preview, rather than accepting the headline classification at face value.

Where the Business Case Genuinely Holds Up

None of this argues against adopting the capability. The economics are real. Organizations running Power Platform at any scale already carry a backlog of small, well-understood app requests that never justify a professional developer’s time: an approval tracker for a regional office, a case log for a compliance team, an intake form tied to a simple review workflow. These are exactly the apps this tool is suited to generate, and getting them built by the people who understand the business process, without a six-week wait for developer capacity, is a legitimate efficiency gain. The plan-review step, imperfect as a security control, is also a genuine improvement over the alternative most organizations had before AI-assisted building existed, which was citizen developers hand-configuring security roles inside the maker portal with even less structured oversight than a mandatory plan review provides.

What to Put in Place Before Turning This On Broadly

The fix isn’t to block the capability. It’s to extend existing Power Platform governance so it explicitly accounts for AI-generated artifacts rather than assuming manually built and AI-generated apps carry the same risk profile by default. A few specific steps hold up in practice. First, the plan-review step needs a defined second reviewer for any app that generates a new security role or business process flow, someone who understands the Dataverse security model and can evaluate a generated role’s actual grants, not just the person who requested the app confirming it matches their description. Second, generated apps should flow through the same promotion gate as manually built ones before reaching a production environment, meaning a Managed Environment with rules that don’t exempt AI-generated solutions from the review and testing stages already required for everything else. Third, generated solutions should be identifiable as such, through naming convention or solution metadata, so a Center of Excellence audit can actually find and review them as a distinct population rather than discovering one during an incident. Finally, before authorizing broad use, someone on the platform team should walk through which specific capabilities inside this tool family are GA and which remain preview, since that boundary will keep shifting as Microsoft continues to expand it through 2026 release wave 2 and beyond.

None of this is a reason to slow-walk adoption. It’s a reason to make sure the governance conversation happens at the same speed as the feature rollout, rather than six months after the first generated security role turns up somewhere nobody expected it. The tools that let a business analyst build a working app in an afternoon are genuinely useful, and organizations that get the review discipline right early will capture that speed without absorbing the risk that comes from treating a functional plan review as if it were a security review. Routeget Technologies has been helping clients extend Center of Excellence frameworks to explicitly cover AI-generated Power Platform artifacts as this category of tooling matures, and the pattern holds across nearly every engagement: the technology is ready faster than the governance process is, and closing that gap deliberately is cheaper than closing it after something ships that shouldn’t have.


#PowerApps #ModelDrivenApps #AIAppBuilder #PowerPlatformGovernance #CitizenDevelopment #EnterpriseAI

Business Central Accelerated Depreciation Reaches GA. The Real Decision Isn’t in the Setup Screen.

Finance office desk with a laptop, binders, and a plant, representing fixed asset depreciation recordkeeping

A controller at a mid-market manufacturer with a French subsidiary spends part of every quarter close doing something Business Central was never quite built to do natively outside that one country: running two depreciation schedules for the same fixed assets. One follows straight-line depreciation for consolidated financial reporting. The other follows an accelerated, tax-driven method required by local law, applied through a coefficient that increases with the asset’s useful life. The two schedules rarely agree, and reconciling the gap between them, quarter after quarter, in a spreadsheet that lives outside the ERP, is exactly the kind of manual process that turns a routine close into a source of quiet risk.

That gap is what Microsoft is closing with Business Central accelerated depreciation, a new capability that makes accelerated depreciation methods for fixed assets standard, general-purpose functionality rather than a country-specific add-on. The feature entered public preview on June 5, 2026, and Microsoft’s release plan lists general availability for October 2026, putting it in the same wave as several other core financial management updates, including new handling for withholding taxes and vendor-specific numbering for self-billing invoices. For finance leaders at Business Central customers with international operations, particularly anyone with entities subject to accelerated or declining-balance tax depreciation requirements, this is worth planning for now rather than discovering after the fact.

Finance office desk with a laptop, binders, and a plant, representing fixed asset depreciation recordkeeping

How Business Central Accelerated Depreciation Works

Business Central has supported multiple depreciation methods for years, including declining-balance calculations. What’s new is not a depreciation method in isolation, but a mechanism for running two depreciation views of the same asset side by side and automatically tracking the difference between them. Setup happens in two places. A depreciation book is configured to use an accelerated depreciation method, and the fixed asset card itself is where the acceleration coefficient and related settings get entered. From there, Business Central calculates the accelerated depreciation amount, the equivalent straight-line amount for the same period, and the variance between the two, posting all three to the appropriate general ledger accounts without any custom extension in the mix.

This will look familiar to anyone who has worked with Business Central’s existing France localization, where a very similar pattern already exists to satisfy French tax law: companies above certain size thresholds must track the difference between accounting depreciation and a faster tax depreciation schedule, using what the system calls a derogatory posting structure, with the variance flowing to dedicated derogatory accounts. The mechanics described for this new, generalized feature (an acceleration coefficient, an automatically calculated linear equivalent, a tracked variance, and inquiry pages showing annual depreciation, variance, and remaining book value) map closely onto that existing model. Whether or not the underlying code is literally shared, the design clearly draws from a pattern Microsoft already had working and tested in one jurisdiction, and is now making available as base functionality rather than something scoped to a single country’s localization pack.

That distinction matters for anyone evaluating this outside France. A business in the United States, India, or the UK, for instance, doesn’t operate under the same statutory requirement to track a tax-accelerated depreciation variance the way French entities do. But plenty of these organizations still want the option: a US subsidiary with MACRS-based tax depreciation running alongside GAAP book depreciation, or a private company that simply wants to accelerate cost recovery for internal planning purposes while keeping a clean straight-line view for lenders or investors, are both scenarios this feature could serve without anyone needing to install a country pack that assumes French tax law.

Abstract illustration of two diverging depreciation curves converging into a single reconciled sphere

The Business Case, in Concrete Terms

The immediate value is not abstract. Today, a company that wants to run accelerated depreciation alongside standard book depreciation, without the France localization applying, typically does it in a spreadsheet, in a bolt-on tax fixed-asset tool, or by approximating it through manual journal entries. Each of those approaches introduces the same three problems: someone has to remember to update the calculation every period, the numbers live outside the system of record, and reconciling the two views at close consumes hours that could go toward analysis instead of arithmetic. Native support inside Business Central removes the reconciliation step almost entirely, because the accelerated amount, the linear equivalent, and the variance are all calculated and posted automatically as part of the standard depreciation run.

There’s a second, less obvious benefit for organizations weighing platform decisions. Companies migrating off legacy systems such as Dynamics GP or NAV, or evaluating Business Central against alternative ERPs during a broader Dynamics 365 implementation, often assume that anything resembling statutory dual-book depreciation requires a heavier, F&O-tier platform or a bolt-on fixed-asset module. A capability like this narrows that gap, and it’s a reasonable data point for IT directors and finance leaders building the business case for a Business Central consulting engagement rather than a more expensive alternative.

What Finance Leaders Should Decide Before Turning It On

The setup itself, a depreciation book configuration plus a coefficient on the asset card, is not the hard part. The hard part is the policy decision that has to happen first, and it belongs with the CFO and controller, not with whoever configures the system.

The first question is which assets actually warrant an accelerated view, and why. If there’s no statutory requirement driving it, the acceleration coefficient becomes a matter of internal accounting policy, and that policy should be documented and applied consistently rather than set asset by asset based on whoever happens to be entering the fixed asset card that week. The second question, and arguably the more consequential one for finance teams that haven’t dealt with dual-book depreciation before, is what the tax-versus-book variance actually represents on the balance sheet. In jurisdictions where accelerated tax depreciation legitimately exceeds book depreciation, that gap is typically the source of a deferred tax liability, and finance teams new to running parallel schedules should loop in their tax advisor or external auditor before the first variance posts, not after it shows up in a quarterly review with no clear explanation.

Third, this is a case where the preview window is genuinely useful rather than a formality. With public preview available since June and general availability not expected until October, there’s real time to configure this in a sandbox environment, run it against a representative sample of fixed assets, and confirm the inquiry pages produce numbers that match what a manual parallel calculation would show, before it touches production data. Given how much else is shipping in the same core financial management wave, including changes to withholding tax handling that could interact with the same vendor and asset records, a sandbox validation pass is worth the time even for teams that don’t consider themselves early adopters.

Finally, IT and finance should jointly confirm whether this actually reduces total license or tooling cost. If a bolt-on fixed-asset or tax depreciation tool is currently in use specifically to solve this problem, this feature is a legitimate reason to reevaluate that contract, but only after the sandbox testing confirms the native functionality produces defensible, audit-ready numbers on its own.

None of this makes accelerated depreciation a feature every Business Central customer needs to touch. Most domestic, single-entity businesses running straight-line depreciation for both book and tax purposes will have no reason to configure it at all. But for finance teams already juggling a manual reconciliation between two depreciation views, whether because of a French entity, a multinational tax position, or an internal policy choice, this closes a gap that has existed in Business Central’s core financial management module for a long time. Routeget Technologies has walked clients through comparable dual-book depreciation setups during Business Central and legacy ERP migrations, and the pattern holds regardless of which system is involved: the software can automate the calculation, but only the finance function that owns the underlying accounting policy can decide what that calculation should actually produce.


#BusinessCentral #FixedAssetDepreciation #TaxBookReconciliation #FinanceTransformation #ERPTaxCompliance #ERPModernization

Why Your AI Builder Default Model Keeps Changing Without Warning

An IT governance leader reviewing an AI model version timeline on a widescreen office display

A finance team at a mid-size distributor built a Power Automate flow eighteen months ago that reads incoming vendor contracts, pulls out payment terms and renewal clauses with an AI Builder prompt, and routes a short summary to the approver queue. The flow still runs every morning. Approvals still clear. Nobody who built the flow works there anymore, and nobody currently on the team could tell you which language model is actually answering the prompt today. It is not the one that answered it when the flow went live, and there was no meeting, no change ticket, and no line in a release note that told anyone it had changed.

That gap is not a one-off. It is how AI Builder’s generative AI prompts are designed to work, and it is worth understanding before the next swap happens rather than after a downstream process quietly starts behaving differently.

AI Builder’s prompt capability, the “Create text using a prompt” action available in Power Automate and Power Apps, runs on the same Prompt Builder infrastructure Microsoft also surfaces inside Copilot Studio. Unless a maker deliberately pins a specific model, every one of those prompts runs against the AI Builder default model, and Microsoft’s own documentation is explicit that this default is “periodically upgraded as new, more capable models become generally available.” The upgrade happens on Microsoft’s schedule, not the customer’s, and it happens without a change request landing on anyone’s desk.

Why the AI Builder default model keeps changing

The churn is not hypothetical. Microsoft’s published model availability record for Copilot Studio and AI Builder prompts shows GPT-4o and GPT-4o mini retired in July 2025, replaced by GPT-4.1 and GPT-4.1 mini. The o1 reasoning model retired the same month in favor of o3, which was itself retired on December 4, 2025 and replaced by GPT-5 reasoning. As of the current documentation, GPT-4.1 mini is the default model behind AI Builder prompts. Sitting just behind it in experimental status, available in limited regions ahead of a wider rollout, are GPT-5.3 chat, GPT-5.2 reasoning, Claude Sonnet 4.6, Claude Opus 4.6, and Grok 4.1 Fast. Experimental status is where every prior default model spent its final months before becoming the new standard, so this list is a reasonably good preview of what gets promoted next.

This is not even the first time the underlying mechanism itself has changed. The original AI Builder GPT feature, announced in December 2023 on GPT-3.5-Turbo, was itself deprecated in favor of the current Prompt Builder architecture. Teams that built early automation on that first action had to migrate the action type entirely, not just adjust to a new model version answering the same call. The lesson from that history is that the platform underneath these prompts has changed twice already, and there is no reason to assume it stops changing now.

Abstract illustration of glowing spheres arranged in a rotation cycle, representing AI model versions turning over

Thirty days is the entire window

When Microsoft promotes a new default, the model it replaces does not disappear immediately. Documentation for Copilot Studio confirms that a retired model stays usable for up to one month after retirement, and there is a setting, buried under an agent’s Settings page in the Model section, called “Continue using retired models,” that lets a maker keep running the outgoing version during that window while testing against the new one. It is a genuinely useful control. The problem is that it lives inside Copilot Studio’s authoring surface, and most of the people who built and now maintain a production flow in Power Automate or an app in Power Apps have never opened Copilot Studio at all. The setting exists. Whether the person responsible for a given prompt even knows to look for it is a separate question, and for most organizations right now, the honest answer is no.

The practical risk is not that the new model performs worse. Often it performs better on the metrics Microsoft optimizes for. The risk is that a model swap can shift output length, formatting, tone, or how confidently it phrases an uncertain answer, and none of that shows up as an error. A prompt that used to return a clean three-sentence summary might start returning five sentences with a caveat clause, and if a downstream Power Automate step parses that output into a fixed-width field or feeds it into a condition check, the flow keeps running successfully while quietly producing something different from what was tested and signed off.

What bring-your-own-model actually fixes, and where it does not

Microsoft’s answer to this is a real one: since September 15, 2025, AI Builder and Copilot Studio prompts have supported bringing your own model from Azure AI Foundry instead of relying on the shared default. An organization deploys its own model in its own Foundry resource, connects the deployment’s chat completion endpoint inside the prompt editor, and from that point forward it owns the version, the region, and the retirement timeline. Nobody upgrades it out from under them. For a prompt that feeds a regulated process, or one where consistent output structure genuinely matters, this is the correct fix, and it has been generally available for a full year.

It comes with two limits worth knowing before anyone builds a governance policy around it. First, a bring-your-own model connected through Prompt Builder can only be used inside prompt actions themselves. It cannot serve as the primary orchestration and planning model for a Copilot Studio agent, so it solves the AI Builder prompt problem specifically rather than every generative AI surface in the platform. Second, GPT-5-class models are not currently supported for bring-your-own connections at all. An organization that has already standardized its Azure AI Foundry deployments on GPT-5 cannot yet point an AI Builder prompt at that same deployment, which means the newest, often best-governed model choice is precisely the one this workaround does not yet cover.

There is also a licensing wrinkle that changes how a team should think about where a prompt lives in the first place. AI Builder credits are consumed when a prompt runs inside Power Apps or Power Automate, but the same prompt running inside Copilot Studio does not draw down those same credits. Two functionally identical prompts can carry meaningfully different cost profiles purely based on which product surface invokes them, which is easy to miss when a finance team is estimating consumption ahead of a rollout.

The governance moves worth making now

None of this requires a large program to address, but it does require someone to own it deliberately rather than let the platform default apply by omission. Start with an inventory of every production flow or app using a Prompt Builder action, and flag which ones are pinned to a specific model versus riding the default, since only the latter is exposed to the thirty-day retirement clock at all. For anything feeding a regulated, financial, or customer-facing process, evaluate whether bring-your-own-model through Azure AI Foundry is worth the setup cost given its current limits. At the environment level, the Power Platform admin center lets administrators disable the “Preview and experimental AI models” feature and lock that setting tenant-wide through environment group rules, which is a low-effort way to keep makers from quietly adopting an experimental model that has not been through any review. Because AI Builder sits inside the Dataverse connector for data loss prevention purposes, existing DLP boundaries already extend to prompt outputs, so that control is worth confirming rather than assuming.

The technology here is not the risk. A rolling default model, upgraded on a vendor’s schedule with a one-month grace period, is a reasonable design for a platform serving millions of makers. The risk is that most organizations have not assigned anyone to watch that clock. The AI Builder engagements Routeget gets pulled into to troubleshoot rarely trace back to a broken prompt. They trace back to a model decision nobody revisited since the day the flow was built, quietly drifting further from what the business actually validated.


#AIBuilder #PowerPlatformGovernance #CopilotStudio #AIModelGovernance #AzureAIFoundry #EnterpriseAI

Bridged Payment Clearing Just Became Mandatory in Dynamics 365 Finance

Finance professional reviewing a bank reconciliation dashboard showing bridged transaction clearing

A technical consultant reviewing the release notes for Dynamics 365 Finance and Operations version 10.0.49 will hit a line that looks routine until it isn’t: automatic clearing of bridged transactions during bank reconciliation, previously something you could turn on when you were ready, is now mandatory. Self-update customers got the build on September 11, and autoupdate production environments follow on October 2. Anywhere bridging accounts, methods of payment, or bank reconciliation parameters were never fully configured, that gap stops being a backlog item and becomes an active problem in the general ledger the moment the update lands.

This is the kind of change that rewards people who read upgrade notes closely and punishes people who don’t. Bridged payment clearing isn’t a new concept in F&O, Microsoft first shipped the automatic version of it a couple of release waves back, but plenty of environments left it disabled because the manual clearing process, while tedious, was at least predictable. Mandatory rollout removes that opt-out, so it’s worth walking through what bridging actually does, what specifically changes in 10.0.49, and what a technical team should check before the autoupdate window closes in early October.

Finance professional reviewing a bank reconciliation dashboard showing bridged transaction clearing

How Bridged Payment Clearing Actually Works

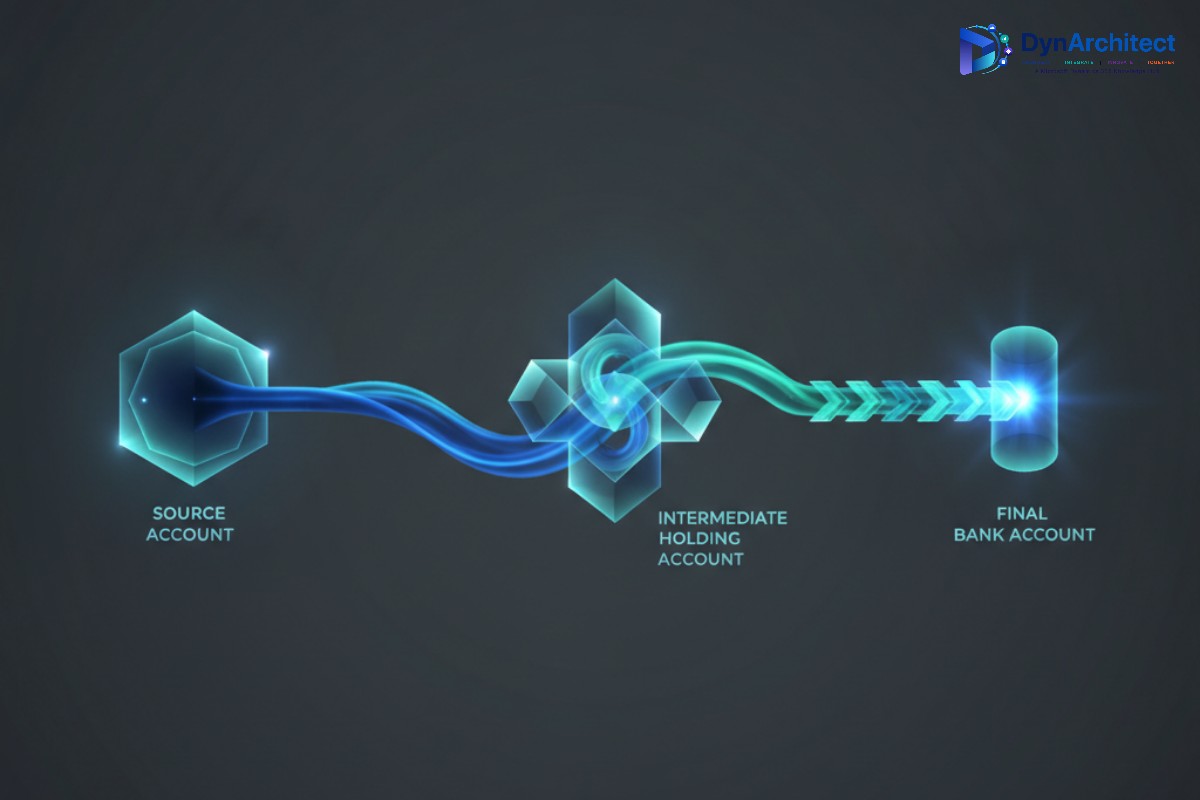
A bridging payment is a payment that posts to the general ledger in two steps instead of one. When a vendor or customer payment is created, the amount lands first in an intermediate bridging account rather than directly in the bank main account. It only moves to the real bank account once the transaction actually clears, which is confirmed during bank reconciliation. The gap between those two events, sometimes hours, sometimes several business days for checks or ACH batches, is exactly the timing problem bridging accounts exist to solve. Without one, your cash position either overstates funds that haven’t cleared yet or requires someone to manually track which payments are still in flight.

Centralized vendor payments add a second layer of complexity on top of that timing gap. When a shared services organization pays vendors out of one legal entity on behalf of several operating entities, the bridging transaction has to reconcile correctly across that entity boundary, not just across time. That’s the specific scenario the 10.0.49 changes target, and it’s also the scenario most likely to have been left half-configured, because centralized payment setups tend to get built by one team and handed off before every downstream parameter gets revisited.

Abstract illustration of payments flowing through a bridging account to a final bank account

What Changes in Version 10.0.49

Three related capabilities move from optional to mandatory in this release: automatic clearing of bridged transactions through advanced bank reconciliation, the extension of that clearing to centralized bridged vendor payments specifically, and use of the latest exchange rate when posting bank transactions. A fourth item, clearing bridged customer payments automatically on the accounts receivable side, reaches general availability this same month, giving Finance teams parity between the vendor and customer sides of bridging for the first time. Microsoft also shipped a preview capability to review automatic bank reconciliation matching results before they post, along with performance improvements to bridge transaction selection that matter once you’re running this at real transaction volume rather than in a sandbox.

The practical effect is that any environment relying on the older manual clearing workflow, where a user posts a general journal by hand after reconciliation, no longer has that as a supported path once the mandatory feature activates. If your bank reconciliation parameters, methods of payment, or bank account records were never updated to support automatic clearing, the reconciliation worksheet’s “mark as reconciled” action will attempt to post clearing journals against configuration that isn’t there, and that’s where things go sideways.

Configuring It Before the Update Lands

The setup itself isn’t complicated, but it touches three separate configuration surfaces, and missing any one of them is enough to cause posting failures. Start in Feature Management and confirm that “Automatic clearing of centralized bridged vendor payments during bank reconciliation” is actually enabled rather than assuming it inherited a default; feature flags introduced in earlier waves don’t always carry forward cleanly into new environments cloned from production.

Next, check the methods of payment used for the affected vendor and customer payment types. The “Bridging account by bank account” parameter determines which account the system treats as the offset for the bridging entry: turned on, it pulls the bridging account configured on the bank account itself, and turned off, it falls back to whatever bridging account is set on the method of payment record. Mixed configurations, where some payment methods rely on the bank account setting and others rely on their own override, are a common source of confusion during testing, so it’s worth documenting which methods use which approach rather than assuming consistency.

Bank account records need attention in two places. On the General tab, confirm the bridging account itself is populated and points to a valid, active main account. On the Reconciliation tab, the “Clear bridged transactions during reconciliation” toggle needs to be on; if it’s off, the system still requires someone to clear bridging payments through a manual general journal, which defeats the purpose of the mandatory automation and will look like the feature “isn’t working” when really it’s configured to not run. Finally, in Cash and Bank Management parameters, the clearing journal name on the Bank reconciliation tab has to point to a journal name that’s actually set up to accept these postings; a blank or misconfigured journal name is a quiet failure point that won’t surface until someone tries to reconcile a real bank statement.

Handling What Doesn’t Clear Automatically

Even with configuration correct, individual transactions will occasionally fail to clear automatically, usually because of a data issue on the underlying payment rather than a setup problem. Dynamics 365 Finance includes a periodic batch job for exactly this situation: Cash and Bank Management > Periodic Tasks > Clear Bridged Transactions lets you select a specific reconciliation ID and resubmit the clearing attempt as a batch process rather than trying to force it through the interactive reconciliation worksheet again. Building a habit of checking this job’s history after each reconciliation cycle, at least for the first few months after the mandatory rollout, will catch configuration gaps faster than waiting for a period-end variance to surface them.

The posting date logic is also worth knowing before someone asks why a clearing entry landed where it did: the system uses the earlier of the reconciliation cut-off date or the system date, not always the date the bank statement itself is dated. For teams doing month-end close under a tight calendar, that detail affects which period a clearing entry hits and is easy to get wrong if you’re reasoning from the statement date alone.

Testing Before the Autoupdate Window Closes

Self-update customers already have this behavior live as of September 11. Autoupdate customers have until October 2 before it arrives automatically, which is a narrow but workable window to validate configuration in a sandbox tier rather than discovering gaps in production. The most useful test isn’t a single sample transaction, it’s running a full reconciliation cycle against a realistic batch of centralized vendor payments, ideally spanning more than one legal entity, and confirming the clearing journals post to the correct centralized entity with the correct offset accounts. Teams that skip straight to production validation tend to find out about a missing bridging account setup during the first live bank statement import after go-live, which is a worse time to find out.

Extending the same test to accounts receivable is worth the extra hour, since the customer-side clearing feature is landing in the same window and shares enough of the underlying mechanics that a gap on one side often points to the same gap on the other.

Routeget Technologies has walked several clients through advanced bank reconciliation configuration changes like this one, and the pattern holds across most of them: the technical setup itself takes an afternoon, but tracking down which of dozens of payment methods and bank accounts were configured inconsistently over several years takes longer than the actual fix. Treating this mandatory change as a prompt to audit that configuration now, rather than after a reconciliation cycle breaks, is the difference between a routine update and an unplanned fire drill.


#BridgedPaymentClearing #BankReconciliation #AccountsPayable #DynamicsFinanceOps #CashManagement #ERPGovernance

What the Power BI PBIR Format Means for Dynamics 365 Reporting Teams

A solution architect reviewing a code diff and a business analytics dashboard on dual monitors in a modern office

A finance reporting team running Power BI over Dynamics 365 Finance and Operations data has a familiar problem: exactly one person can safely have the working capital dashboard open at a time. Everyone else waits, or worse, someone opens the file anyway, makes a change, saves over a colleague’s unsaved edits, and nobody finds out until a client asks why a visual disappeared. That is not a hypothetical. It is how nearly every Power BI report built on top of Dynamics 365 or Dataverse data has been managed since the tool existed, because a .pbix file is a single binary blob. There is no diff, no merge, no pull request, just a file lock enforced by social convention. The Power BI PBIR format changes that mechanic directly, and as of May 2026 it became the default way Power BI Desktop saves new reports, which makes this less a curiosity for early adopters and more a decision every Dynamics 365 reporting practice needs to make on purpose.

PBIR stands for Power BI enhanced report format, and it replaces the older single-file report.json approach (itself an earlier attempt at the same problem, now referred to as PBIR-Legacy) with a folder of small, human-readable JSON files. Microsoft first shipped it as a Desktop developer mode preview several years ago, but the May 2026 update made it the default for both new PBIX files and PBIP projects, meaning teams that never opted into the preview are now creating PBIR reports without necessarily realizing the storage model underneath them has changed.

What the Power BI PBIR Format Actually Changes on Disk

Open a PBIR report’s project folder and you will find a definition directory containing a pages subfolder, a bookmarks subfolder, a report.json for report-level settings, and a version.json that records which format version the report requires. Inside pages, each report page gets its own folder with a page.json and a visuals subfolder, and inside that, every single visual on the page gets its own visual.json file describing its position, formatting, and query. A bookmark becomes its own file too. This sounds like a lot of small files for what used to be one, and it is, but that granularity is the entire point: a change to one chart’s conditional formatting now shows up as a one-file diff instead of an unreadable delta buried inside a compressed binary.

Each of these JSON files declares a public schema URL at the top, and Microsoft has published those schemas on GitHub, which means a report can be opened, validated, and even edited in VS Code with real IntelliSense rather than guesswork. Objects get 20-character generated identifiers by default (something like 90c2e07d8e84e7d5c026), which is ugly to read in a diff but can be renamed to something meaningful through Power BI Desktop, with the caveat that renaming requires restarting Desktop for the change to stick. There is also a lesser-known annotations feature: name-value pairs that Power BI itself ignores completely but that a deployment script can read, which turns out to be useful for marking which page should be the default landing page in a given environment or flagging a visual for environment-specific suppression.

Abstract illustration of branching and merging version control lines connecting to report dashboard blocks

The Git Workflow This Finally Enables

None of the file structure matters much without source control actually using it, and this is where the practical shift happens. A pull request against a PBIR report can now show a reviewer exactly which visual changed and how, the same way a code review shows a diff of a function. Two developers working on different pages of the same report can genuinely work in parallel and merge without one silently overwriting the other, something that was structurally impossible with a monolithic .pbix. Fabric’s own Git integration, which connects a workspace to Azure DevOps or GitHub, extends this further by tracking reports and semantic models at the workspace level and preserving folder structure in the repository, though it is worth being precise here: the file format reaching general availability in Desktop and Fabric’s Git integration support for report and semantic model items reaching full production maturity are two different milestones, and as of this writing the latter is still documented as preview for several connection scenarios, including reports tied to Analysis Services live connections.

A report’s connection to its semantic model is itself stored declaratively, through either a byPath reference that opens the model in full edit mode alongside the report, or a byConnection reference that opens the report in live connect mode with only report-level measures editable. Which one a team chooses affects how much of the semantic model layer gets included in the same Git history as the report, and it is worth deciding deliberately rather than by whatever Power BI Desktop defaulted to on first save.

Why This Matters More for Dynamics 365 Reporting Portfolios

Generic Power BI advice tends to treat this as a nice-to-have for BI teams in general. For a Dynamics 365 F&O or Business Central reporting practice specifically, it addresses a sharper pain point. These environments accumulate large report portfolios fast: financial statement packages, inventory and demand dashboards, project cost tracking, often built by a rotating cast of internal analysts and external consultants over several years. Ownership gets murky, undocumented changes creep in before a board meeting, and when something breaks nobody can say with confidence what changed or when. Power BI Desktop’s version history feature, which also reached general availability in the May 2026 wave alongside the default PBIR change, gives that audit trail natively inside the desktop tool for the first time, which is directly relevant to any organization treating financial report changes as something that needs a change management trail rather than an honor system.

Deployment pipelines benefit in a related way. A report promoted from a development workspace to test and then production can carry annotation-driven configuration differences (a different default page, a different data source binding) without manual reconfiguration at each stage, and the promotion itself becomes something a pipeline log records rather than something a person remembers doing.

Rolling Out PBIR Without Breaking Anything

The rollout mechanics are straightforward but deserve a plan rather than an ad hoc toggle. PBIR is enabled through Power BI Desktop’s preview features under Options, and existing PBIR-Legacy reports convert automatically on the next save, with Desktop creating a backup copy first. That backup detail matters because there is no supported rollback path once a report has converted; the backup is the rollback path, and it lives in a local temp folder with a 30-day retention window, not somewhere a team should rely on long term. The sensible sequence is to pick one lower-stakes report first, ideally something without heavy custom visual dependencies, convert it, get comfortable with the folder structure and the Git workflow in a sandbox repository, and only then extend the practice to the financial statement packages where a mistake actually costs something. Establishing a branching convention (a feature branch per report change, a pull request before merging to the branch a production workspace tracks) before the first real conversion saves a team from learning that lesson under time pressure.

What Still Doesn’t Work Smoothly

A few limitations are worth knowing before committing a whole reporting portfolio to this model. Edits made directly in a code editor do not sync live; the report has to be reopened in Power BI Desktop for those changes to take effect, so treat external JSON edits as a batch operation rather than a live-editing workflow. Two developers can still step on each other if they edit the same page at the same time rather than different pages, since the conflict resolution is granular but not infinite. Service-side limits apply too: a report tops out at 1,000 pages and 1,000 visuals per page, and resource packages are capped at 300 MB, ceilings that rarely matter for a typical operational dashboard but are worth knowing about before designing something unusually large. And a handful of connection types, including push datasets, live connections to on-premises Analysis Services, and older model versions, are excluded from Git integration support entirely for now.

None of that undermines the core shift. Power BI reports built on Dynamics 365 data have functioned for years as single-owner artifacts, reviewed by nobody, versioned nowhere, and handed off through tribal knowledge. PBIR does not fix that automatically, but it removes the technical excuse for not fixing it. The teams that treat this as an application lifecycle management decision, with branching conventions, review checklists, and a deliberate rollout order, will get real governance out of it. The teams that flip the preview toggle and keep working exactly as before will just have smaller binary files. At Routeget, we have been sequencing client Dynamics 365 F&O reporting portfolios through this conversion starting with the highest-change-frequency reports rather than the highest-visibility ones, on the theory that the reports changing every month are where a missing audit trail actually costs someone time.


#PowerBI #PBIR #GitVersionControl #DynamicsFinanceOps #ReportGovernance #MicrosoftFabric