
$(cat /tmp/claude-0/-home-claude/07d39bf1-06fe-5f0b-8c7f-ec7fed5bbc49/scratchpad/final_content.html | jq -R .)

$(cat /tmp/claude-0/-home-claude/07d39bf1-06fe-5f0b-8c7f-ec7fed5bbc49/scratchpad/final_content.html | jq -R .)

Most Dynamics 365 implementations contain at least one field that should not exist. It is usually a number that sums values from child records, or a formula that derives from related data. The reason it exists is always the same: someone wanted real-time access to that information from a parent record, without running a report or opening a separate list.
Dataverse calculated columns and rollup columns promise to solve this problem. Calculated columns apply a formula to one or more fields on the current record, showing the result live without code. Rollup columns sum, count, average, or find min/max values from related records, showing that aggregation on the parent record. Both sound straightforward in a demo. Both become serious performance liabilities in production when misapplied.
The problem is not that calculated columns or rollups are poorly designed. The problem is that their flexibility and ease of configuration make it tempting to create them for every question a user asks, and because Dataverse computes these columns synchronously during record operations, each one you add delays every operation touching that record or its related data. At scale, calculated columns and rollups can turn a fast, responsive system into one where simple form loads lag and mass operations hang.
Calculated columns in Dataverse run when a record is created, updated, or retrieved. Unlike plugin code you can optimize or disable, calculated columns execute on every interaction. If you define a calculated column that divides a budget by a count of child records, that division happens every time anyone loads the form, every time a Power Automate flow retrieves that record, and every time an integration fetches the data via the API.
Rollup columns add another layer of complexity. A rollup does not just read data from related records; it must traverse a relationship, evaluate a condition on each related record, and then compute the aggregation. If you create a rollup that counts all incomplete tasks related to an account, Dataverse must walk through every task record linked to that account, check each one’s status, and return the count. On an account with 50,000 tasks, this query can take seconds.
Both calculated columns and rollups are recomputed on a schedule. Dataverse does not compute them in real-time on demand; instead, the system recalculates them asynchronously in batch jobs. This means that displayed values may not always reflect the absolute latest state of the source data. For a dashboard or a report, this lag is usually acceptable. For a workflow that needs to make a decision based on that value, the delay can cause logic to fail or bypass critical checks.
Performance issues with calculated columns and rollups typically emerge at one of three trigger points.
First is load time. A form containing multiple calculated columns or rollups can take noticeably longer to render, especially on mobile or slower connections. Users perceive this as a slow or unresponsive system. The impact scales with the number of columns; a form with 2 or 3 calculated fields performs fine, but one with 10 or more can lag visibly.
Second is mass operations. Bulk operations such as Power Automate loops that create or update thousands of records will execute more slowly if those records contain calculated columns or rollups. Each record operation pays the calculation cost, so a loop that would normally complete in 30 seconds might take 3 minutes. Workflows that timeout during scheduled jobs often have calculated columns as a hidden root cause.
Third is query performance. Reports or Power BI dashboards that query many records will hit slowdowns if the records contain expensive calculated columns or rollups. The calculation must complete before the record is returned, so querying 10,000 records with heavyweight calculations forces Dataverse to compute all 10,000 calculations before the query finishes.
A fourth, more subtle issue is the logical inconsistency created by asynchronous recalculation. If a workflow reads a rollup column value, performs business logic based on that value, and then the rollup recalculates a moment later and changes, the workflow has acted on stale data. This can create gaps in audit trails or cause business logic to diverge from the actual state the user sees.
Before optimizing, you need to know if calculated columns or rollups are actually the problem. A few diagnostic approaches work.
Check the Dataverse environment’s performance reports. Look for slow-running queries or forms that take longer than expected. If a form with calculated columns loads in three seconds and the same form without them loads in one second, the columns are adding two seconds of latency. Similarly, check Power Automate run histories for timeouts or slow execution in flows that work with records containing rollups.
Enable Plugin Trace Log (under Settings in your Dynamics environment) and examine traces for records being retrieved with calculated columns. Look at the duration of retrieve operations; if simple record retrievals are taking longer than 500 milliseconds, calculated or rollup columns are a likely culprit.
Query the Dataverse API directly with and without calculated columns in the result set. Use select parameters to request only the columns you need. If adding a calculated column to the query selection significantly increases response time, you have confirmed the issue.
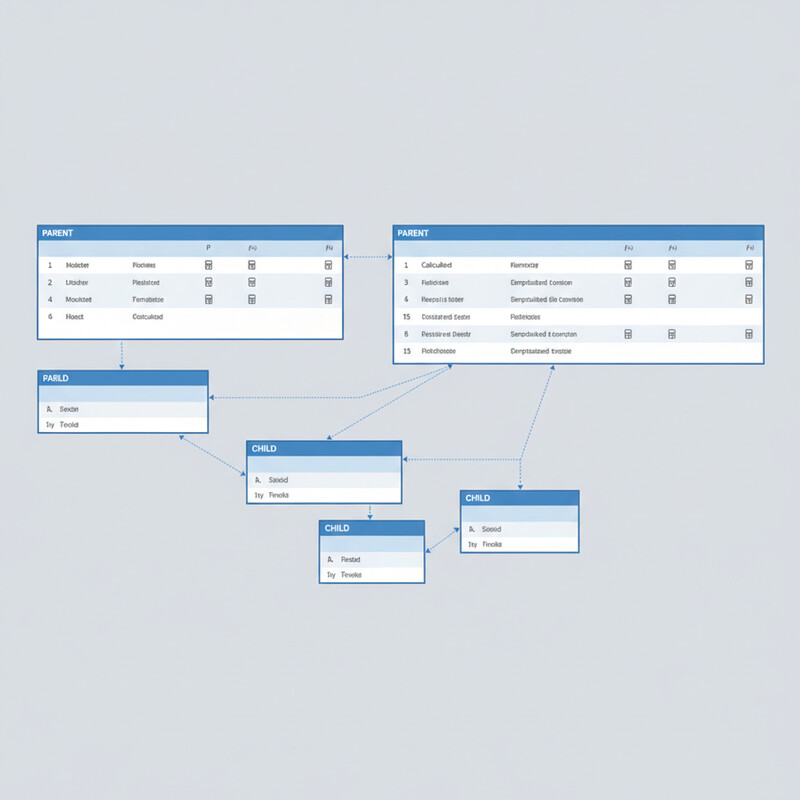
If you have identified a bottleneck, you have several options. The best choice depends on your specific scenario.
Use plugins or Power Automate to calculate on demand. Instead of computing the value every time a record is retrieved, calculate and store it only when necessary. A plugin triggered on form load can calculate a summary and display it in a banner, showing fresh data without impacting record retrieval. A Power Automate cloud flow can run on a schedule to update rollup values once per hour or once per day, depending on your tolerance for staleness. This approach keeps the permanent record lean.
Move calculations to the reporting layer. Power BI does not care if a column is calculated in Dataverse or computed in the dataset; the result looks the same to an end user. Create a calculated column in a Power BI dataset instead of in Dataverse, and use that column only for dashboards and reports. Forms and integrations get the base data without calculation overhead.
Use views and roll-up jobs sparingly. If you do use rollups, create them for only the most critical summaries. A single rollup that counts open orders on an account is reasonable; four rollups that count open orders, sum order amounts, calculate average order value, and find the date of the latest order should be four separate on-demand calculations in Power Automate or a custom plugin.
Denormalize selectively. For high-cardinality relationships (an account with tens of thousands of related records), consider storing pre-calculated values in a separate summary table updated by a scheduled batch process, rather than relying on Dataverse to calculate them live. This trades a small amount of design complexity for significant performance gains.
In practice, high-performing Dataverse implementations keep calculated and rollup columns minimal. A good rule of thumb: if a column is not displayed on a form or used in a critical workflow decision, it should not exist as a calculated or rollup column.
When you do create them, profile the specific form or report where they appear. Measure load time before and after; if latency increases by more than 200 milliseconds per column, investigate alternatives. For rollups, test with realistic data volumes; a rollup that works fine with 100 related records may not work at all with 10,000.
Document which forms, reports, and integrations depend on each calculated or rollup column. This becomes essential when troubleshooting slow operations; knowing that a dashboard uses a particular rollup helps you understand why it is not refreshing quickly.
Finally, review calculated and rollup columns every few months. As your implementation matures and data volumes grow, columns that performed acceptably in early stages may become bottlenecks. Removing a column that no longer serves a critical business purpose often has an immediate, measurable impact on overall system responsiveness.
Calculated columns and rollups are powerful tools when used deliberately. They become performance anchors when used casually. The teams that manage Dataverse best treat them not as convenience features, but as performance decisions that must be justified by real business need and validated through testing at production scale.
#DataversePerformance #CalculatedColumns #RollupOptimization #DataverseTuning #Dynamics365Performance #CloudArchitecture #DataverseArchitecture #SystemPerformance
Your Copilot Studio instance has been live for three months. The generic responses work fine for routine customer questions. Finance users can ask about invoice status, support teams can access knowledge articles, and operations can trigger basic workflows. Then a regional finance controller asks the system to calculate cross-border tax liability on a specific transaction type, and the Copilot returns something confidently wrong. You prompt-engineer for two weeks, add retrieval augmented generation, feed it more context documents. The Copilot still hallucinates because the business logic you need is not in any training data and cannot be reliably expressed as plain-language instructions. This is the moment you need custom AI plugins.
Copilot Studio has become the dominant interface for enterprise AI in Microsoft’s ecosystem. It handles conversation orchestration, knowledge integration, and basic AI coordination reasonably well. But enterprises running this platform often discover a hard boundary: Copilot’s core language models and retrieval pipelines, however well-prompted, cannot reliably execute business logic that requires domain-specific reasoning, real-time calculation, or proprietary algorithms. At that point, the architecture choice is clear. You build a custom plugin that encapsulates your logic, expose it to Copilot through the API, and let Copilot handle the conversation while your code handles the reasoning.
The first question teams ask is practical: when should we stop refining prompts and start building a plugin? The answer depends on measurability and consistency. If the Copilot’s output accuracy has reached a plateau after refinement, and accuracy is below your business threshold, a plugin is justified. If the required logic involves calculations, date arithmetic, multi-step conditionals, or reference data lookups (like product pricing, tax rates, or inventory counts), those belong in code, not prompts. If the same request returns different answers depending on minor variations in phrasing, or if the Copilot sometimes invents plausible-sounding answers rather than admitting it cannot answer, those are signals that the language model is not the right tool for that part of the workflow.
Consider a typical scenario: a Dynamics 365 Finance user asks Copilot about available cash in a specific cost center, accounting for committed purchase orders and pending payroll. The Copilot needs to query Dynamics, aggregate real-time data, apply business rules about what counts as committed, and return a specific number. Prompting the Copilot to do this might work in a demo. In production, with thousands of daily queries across different cost centers, exchange rates, fiscal calendars, and policy variations, a language model will eventually return incorrect numbers, usually with complete confidence. A plugin solves this by running the exact query and calculation logic every time, leaving the Copilot to handle the conversation and formatting.
Copilot Studio plugins connect to external APIs. That external API can be anything you build: a cloud function, a containerized service, a Logic App with Power Automate, or a .NET Azure Function. The Copilot describes what it wants to do (based on the conversation context), the plugin action is triggered, your code executes, and the result is returned to the Copilot for further conversation.
The simplest architecture is a single Azure Function or cloud function (AWS Lambda, Google Cloud Functions) that accepts a JSON request from Copilot and returns a JSON response. The function can call Dynamics 365 APIs, query a database, call third-party services, or execute business logic. From Copilot’s perspective, it simply sends a request and gets back structured data.
For enterprise scenarios, though, you need to think about authentication, rate limiting, audit logging, and error handling. Copilot can send requests at high volume during peak usage. Your plugin needs to handle this without degrading Copilot’s response time or running up costs. You should implement proper logging of what Copilot requested, what your code returned, and any failures, so you can debug issues later. You should also plan for security: the plugin is exposing business logic and potentially sensitive data (cost center balances, tax calculations, procurement data). Access should be restricted to authenticated users, requests should be validated, and responses should be filtered by role so users only see what they are authorized to see.
A common pattern is the data enrichment plugin. Copilot receives a user’s question about a purchase order. The Copilot extracts the order ID or vendor name from the conversation, calls your plugin, and the plugin queries Dynamics 365 Supply Chain Management to return order status, delivery dates, budget allocation, and any policy exceptions. The Copilot then uses this structured data to answer the user’s question accurately. Without the plugin, the Copilot might guess or confuse details from different orders.
Another pattern is calculation and validation. Finance teams often need to validate transaction proposals before they are committed. A user might ask Copilot whether a specific expense is compliant with policy, and Copilot needs to check the expense amount against the cost center budget, the employee’s spending tier, the transaction category, and any special approvals in place. This logic is too complex and too sensitive for a language model to handle. A plugin runs the exact validation rules and returns yes or no with an explanation of which rule applies.
A third pattern is workflow initiation. Copilot can receive a user’s request to approve a contract, create a purchase requisition, or escalate an issue. Instead of trying to directly modify systems, Copilot calls a plugin that creates a structured request in your workflow engine (Power Automate, Logic Apps, or a custom orchestration service), which then handles the actual business process with proper audit trails, notifications, and approval chains.
The most common failure in production is latency. A Copilot session timeout is usually 30 seconds. If your plugin takes 15 seconds to execute (because it is doing multi-step Dynamics queries or waiting for external services), Copilot will time out before your plugin even returns. You need to either cache data, run asynchronous jobs, or redesign the plugin to return partial results and update the Copilot UI after the full result arrives. Teams that skip this step often end up with Copilot sessions that fail silently or time out repeatedly in production.
A second failure mode is incomplete error handling. A plugin fails (database is down, Dynamics is temporarily unavailable, an API call returns an unexpected error). The plugin should catch this, log it, and return a clear error response to Copilot, not crash or hang. Copilot should then explain to the user that it could not retrieve the data and suggest alternatives (like checking the system status page or contacting support). Without this, users see broken Copilot sessions with no explanation.
Authorization is a third area. Your plugin receives a request from Copilot that includes the user’s identity. Your plugin must verify that this user is actually authorized to see the data they are asking about. If your plugin does not check authorization, users can escalate privileges by asking Copilot for data they would not normally have access to. This is a security and compliance issue, especially in regulated industries like finance and healthcare.
Microsoft’s AI Builder sits between pure prompting and custom plugins. AI Builder lets you build models that can do optical character recognition, sentiment analysis, or predictive scoring, and expose these as Copilot actions. For some use cases (document classification, customer sentiment analysis, basic prediction), AI Builder is sufficient and faster to build than a custom plugin. But for complex business logic, multi-step reasoning, or calculations with regulatory requirements, a custom plugin is necessary because you control exactly what the code does and can audit every decision.
Once a plugin is built, it should be versioned and deployed through your standard application lifecycle management pipeline. Changes to plugin logic should go through testing and approval before hitting production. You should have monitoring in place: track response times, error rates, and plugin usage patterns. Set up alerts if response times exceed thresholds or error rates spike. Log every request and response (at an appropriate detail level, respecting privacy) so you can audit what Copilot asked, what your plugin returned, and whether the result was accurate.
This monitoring becomes particularly important when Copilot’s behavior changes. If Copilot suddenly starts calling your plugin more frequently or with different inputs, your plugin needs to handle it gracefully. If a new version of Copilot changes how it describes requests, your plugin should either adapt or return a clear error rather than silently misinterpreting the request.
Copilot Studio is effective at conversation and orchestration, but it is not a replacement for business logic. Custom AI plugins let you draw a clear line: Copilot handles the conversation and user interaction, while your code handles the reasoning, calculation, and access control. This division of labor produces systems that are both more accurate and more maintainable than trying to encode all business logic as prompts. The engineering effort to build a plugin is real, but for any enterprise scenario involving calculations, multi-step reasoning, or regulated data access, the plugin approach is the right architecture choice.
#CopilotStudioAI #AIPlugins #EnterpriseAI #PowerPlatform #CustomAIPlugins #Dynamics365AI #CloudArchitecture #PluginArchitecture

A CFO reviewing next year’s Power Platform renewal usually finds the same line item growing faster than anything else on the invoice: Dataverse database capacity. For a Dynamics 365 Finance and Supply Chain Management customer with a few years of general ledger, tax, inventory, and sales order history behind it, that growth is not a mystery. Transactional tables in F&O apps do not shrink on their own, and every fiscal year adds another layer of records that almost nobody queries but that the platform still has to store, index, and back up at full price.
IT’s answer to that problem usually arrives as a single line in a capacity review deck: turn on Dataverse long-term retention and archive the old transactions out of the live database. It is a real fix, and Microsoft’s own numbers back it up. But the conversation tends to stop there, before anyone asks the question a security or compliance lead should be asking, which is what happens to the encryption key protecting that data once it moves.
Dataverse long-term retention, sometimes shortened to LTR, lets an organization move inactive records out of live application tables into a separate, read-only retention layer that still lives inside Dataverse and is still governed by Microsoft Entra ID. For Finance and Supply Chain Management specifically, Microsoft currently supports archiving general ledger transactions, tax transactions, inventory transactions and journals, sales orders, and Commerce transactions this way. Attachments are explicitly excluded for now.
The financial case is straightforward once you see the compression numbers. Microsoft states that data moved into Dataverse long-term retention consumes roughly half the capacity of the same data sitting in a live table, and when the F&O-specific archive process goes a step further and migrates that data into history tables rather than leaving it only in retention, the history-table footprint can run closer to 30 percent below the original. At a commonly cited list price of roughly 40 dollars per gigabyte per month for Dataverse database capacity, an organization sitting on several hundred gigabytes of aging general ledger and inventory history is not looking at a rounding error. It is looking at a five- or six-figure annual number that a straightforward archive policy can meaningfully cut, without touching a single report a controller actually runs day to day.
That is the pitch that gets this feature onto a roadmap. It is also, on its own, an incomplete pitch.
The mechanics matter for planning purposes, not just for understanding the technology. Microsoft’s documentation describes the F&O archive process as a sequence of stages: replication of records into Dataverse long-term retention, marking of records that meet the retention policy’s criteria, reconciliation to confirm every record made it across intact, and finally migration, where the data is moved into history tables and removed from the live application tables. Only after that full sequence completes does the capacity reduction actually show up in reporting, and Microsoft’s own timeline for that is seven to fourteen days depending on data volume, with archival jobs deliberately run at lower priority than normal application workloads.
There is a detail buried in that same documentation that tends to surprise architects who assume large-scale platform jobs run in parallel by default: they do not, here. Microsoft states plainly that the stages of the F&O archival process “run sequentially in the background.” If you are planning to archive several years of general ledger, tax, and inventory history in the same cycle, that sequencing, not the compression ratio, is what actually determines how long your capacity relief takes to land. A rollout plan built around a single “flip the switch and wait a week” assumption is usually wrong by a factor of several weeks once multiple table types and several years of backlog are involved.
None of that is disqualifying. It is simply the kind of operational detail that belongs in a project timeline, not a surprise a program manager discovers in week three.
Here is where the conversation should slow down before a decision gets made, particularly for regulated industries such as financial services, healthcare, government contracting, or any organization with a contractual or regulatory commitment to control its own encryption keys.
Microsoft Power Platform has moved through two generations of customer-controlled encryption. The older mechanism, generally referred to as bring your own key or BYOK, is now explicitly positioned by Microsoft as a legacy predecessor to the current customer-managed key, or CMK, model. That distinction is not cosmetic. Microsoft’s own migration guidance states that environments still running the legacy BYOK encryption model are locked out of a specific list of newer Dataverse capabilities until they migrate to CMK, and Dataverse long-term data retention is on that list, alongside elastic tables, Dataverse search, AI Builder, and several others. An organization that has not made the BYOK-to-CMK move simply cannot turn retention on yet.
For organizations evaluating the F&O-specific archive path directly, Microsoft’s own archive documentation adds a second, sharper detail. It states that customers using the legacy BYOK model should be aware that data moved into Dataverse long-term retention is encrypted with a Microsoft-managed key rather than the customer’s own key, and it recommends migrating to customer-managed key as a result. Read carefully, that is Microsoft telling its own customers that the encryption custody model can change the moment data crosses from a live table into the archive, unless the tenant has already completed the CMK migration first. It is worth noting that the guidance itself is not fully explicit about whether this applies only to tenants still on the older model or to every tenant regardless of current key configuration, and a security team relying on this feature for a compliance commitment should confirm the current behavior for their specific tenant and encryption configuration directly with Microsoft before treating archived data as covered by the same key custody guarantee as their live data.
For a business that markets its own data handling on the strength of customer-held encryption keys, whether to a regulator, an auditor, or a customer contract, that is not a footnote. It is a governance gap that needs to close before the capacity-savings project starts, not after an auditor asks where the archived general ledger data actually lives and under whose key.
The organizations that get this right treat Dataverse long-term retention as a governance initiative with a cost-savings side effect, not the other way around. That means confirming current encryption status first: whether the tenant is still on legacy BYOK, already on CMK, or using Microsoft-managed keys by default, since only the first case actually creates a conflict. It means building the CMK migration, if one is needed, into the project plan ahead of the retention policy rollout rather than in parallel with it, since Microsoft’s own guidance describes CMK migration as something that can happen without contacting Microsoft support, which removes one common excuse for delay. And it means setting expectations with finance leadership that the capacity savings materialize over a multi-week sequential process per table type, not overnight, so the budget conversation is not built on a timeline the platform cannot actually deliver.
We at Routeget Technologies have walked F&O customers through exactly this sequencing, and the pattern holds consistently: the technical archive configuration itself is the easy part. The harder, more valuable conversation is the one between IT, finance, and compliance about what “the data is still in Dataverse” actually means once the key protecting it is no longer necessarily the one the organization chose.
The capacity savings on a Dataverse long-term retention rollout are real, and for an F&O environment with years of transactional history, they are often large enough to justify the project on cost grounds alone. But the encryption question is not a technicality to resolve after the fact. It is the first question a CIO or CFO should ask before the retention policy goes live, and the answer determines whether this is a two-week configuration task or a multi-month project that starts with a key migration.
#DataverseRetention #CustomerManagedKey #BYOKMigration #DynamicsFinanceOps #ERPCostOptimization #CloudArchitecture

A bulk delete job runs at 2 a.m. against the wrong view filter. By the time anyone in operations notices, eleven thousand account records are gone, and the only recovery plan anyone can point to is a nightly export sitting in a storage account nobody has tested restoring from in two years. That scenario is why Microsoft spent nearly two years moving deleted record recovery in Dataverse from public preview to general availability in late April 2026. For solution architects and Dynamics 365 technical teams, a native Dataverse recycle bin restore capability closes a gap that has existed since the platform’s earliest days: there was never a supported, in-product way to undo a delete. Now there is one. The problem is that plenty of teams will configure it, assume it behaves like the Recycle Bin on a Windows desktop, and discover the gap between what it restores and what they actually needed restored only during a real incident.
The feature’s actual behavior is narrower and more procedural than its name suggests, and the places where it falls short map directly onto the customizations most F&O, Business Central, and Customer Engagement implementations already carry.
The capability itself is straightforward to enable. From the Power Platform admin center, under an environment’s Settings, Product, Features, there is a “Keep deleted Dataverse records” toggle with a retention window configurable from one to thirty days. Turn it on, and Dataverse begins tracking rows that get deleted so a System Administrator can view them under Data management, Deleted Records, and issue a Restore request against the ones worth recovering. The setting lives at the environment level, not the tenant level, so a sandbox and its corresponding production environment can carry entirely different retention windows, which matters if you’re testing destructive changes in a lower environment that doesn’t need the same thirty-day buffer production does.
The detail that trips up almost every team on first contact is that the feature is not retroactive. Only rows deleted after the setting is enabled and has finished propagating, which the documentation notes can take up to thirty minutes, become recoverable. A record deleted an hour before someone flips the toggle is gone exactly as it always was. If you’re reading this and haven’t enabled retention on a production environment yet, that thirty-minute propagation window is the argument for doing it now rather than after the incident that makes you wish you had.
Restoration happens through the Restore message, available in the SDK for both early-bound and late-bound entities, or as an action call through the Web API. The request takes a full target record rather than a bare reference, so you can override specific column values as part of the restore rather than being forced to bring back an exact snapshot. Deleted rows are also queryable directly: a FetchXml query with datasource='bin', or a QueryExpression with its DataSource property set the same way, returns rows sitting in the bin rather than the live table, which is enough to build a lightweight internal tool that surfaces what’s recoverable without routing every check through the admin UI.
The exclusion list is where the feature’s real limits show up, and it is long enough that assuming universal coverage is a mistake worth catching before an incident rather than during one. Virtual tables are excluded entirely: if a record surfaced from an external system through a virtual table disappears, there was never anything in the bin to restore, since that row was never really “deleted” from Dataverse’s perspective so much as it stopped resolving. Elastic tables, increasingly common for high-volume telemetry, IoT-style logging, or activity history where standard table row limits become a constraint, are excluded as well. So are solution component tables, and so is any table that has grown past six hundred attributes, a ceiling that heavily customized standard entities in mature Dynamics 365 implementations can approach faster than teams expect.
Beyond those structural exclusions, Microsoft maintains a list of roughly two hundred and fifty system tables that don’t support deleted-record retention regardless of configuration: async operation records, background operation records, bulk delete failure logs, Power Automate flow run and flow log tables, solution and solution component tables, plugin assembly tables, and the full family of msdyn_ and mspp_ prefixed tables tied to first-party Dynamics 365 apps and Power Pages. None of that is arbitrary; those tables tend to be high-volume, system-managed, or tightly coupled to processes where a stale restored row could reintroduce more problems than it solves. But it does mean that if your disaster recovery narrative for a Power Pages portal assumes the recycle bin has you covered, it’s worth checking the actual exclusion list against your table inventory before that assumption ends up in a postmortem.
Where this feature gets genuinely interesting for anyone who has built out relationship cascading behavior is how it treats dependent records. Rows removed because of a configured cascade delete relationship, the kind set up through standard relationship behavior rather than custom code, are restorable, but not independently. You have to restore the parent record first; attempting to restore a cascaded child before its parent throws RefCannotBeRestoredRecycleBinNotFound, and the platform expects you to work back up the dependency chain in the correct order rather than picking records to restore arbitrarily.
Custom logic is a different story, and it’s the part of the feature architects need to internalize before promising anyone a one-click recovery story. If a plugin or a Power Automate flow deletes related records as a side effect of deleting the primary record, none of that custom-triggered deletion is automatically reversed by a Restore call. The recycle bin captures what Dataverse’s own relationship engine did, not what your business logic did on top of it. That means any implementation with plugins that clean up child records, cancel related cases, or cascade status changes on delete needs a mirrored restore path: a plugin registered against the Restore message, in the PostOperation stage specifically since the restored record isn’t available yet during PreOperation, that re-creates or re-links whatever the delete-time logic tore down. Skip this step and a team restores the parent record, then discovers days later that none of the related activity history, case associations, or downstream integration records came back with it, because nothing ever told them to.
A handful of other failure modes are worth knowing before you hit them live. Restoring a record whose ID has since been reused by a new record throws DuplicateExceptionRestoreRecycleBin, since Dataverse preserves the original primary key on restore rather than generating a new one. If a deleted record referenced an option set value that has since been removed from the choice definition, the restore fails with PicklistValueOutOfRangeRecycleBin. Both are recoverable situations, but only if whoever is running the recovery understands what the error is actually telling them instead of treating it as a generic restore failure and giving up.
None of this argues against enabling the feature. It argues for treating it as infrastructure that needs its own runbook rather than a switch you flip and forget. A reasonable rollout enables retention on every production environment now, sets the window to match your actual incident response SLA rather than defaulting to the maximum thirty days without weighing the storage tradeoff, and documents exactly which tables in your specific implementation fall outside the coverage: your virtual tables, any elastic tables you’ve adopted, and anything near the six-hundred-attribute ceiling.
The more valuable investment is building and testing the restore path before you need it: registering the mirrored Restore-stage plugin logic anywhere delete-time custom logic exists, confirming cascade restore order against your actual relationship map rather than assuming it will be intuitive mid-incident, and running a deliberate test delete-and-restore cycle in a sandbox so the first time anyone executes this procedure isn’t during a live outage. It’s also worth being explicit internally that this is record-level recovery, not a replacement for environment-level point-in-time restore, which remains the right tool for a broader corruption event or a bad deployment rather than a scoped accidental deletion. Teams that conflate the two end up with a false sense of coverage in exactly the scenario where they can least afford one.
The recycle bin is a genuinely useful addition, and it’s the kind of foundational reliability work that doesn’t generate much attention next to agent and Copilot announcements but matters more day to day for the teams operating these environments. Routeget has walked several clients through exactly this kind of gap analysis between what a new platform capability claims to cover and what a specific implementation’s customizations actually need, and the pattern holds here too: the feature is only as good as the runbook built around it. Treat this GA date as the trigger to write that runbook, not as the moment the problem quietly solves itself.
#Dataverse #DataverseRecycleBin #DataRecovery #PowerPlatformGovernance #ITDisasterRecovery #CloudArchitecture

A solution architect running Dynamics 365 Finance and Operations across forty legal entities kicks off an archive job for General Ledger transactions on a Friday afternoon, then checks back a week later to find eleven entities still sitting in the queue. Each job runs start to finish before the next one begins, so a single line of sequential processing does all the work no matter how much idle capacity sits behind it. That queue is a direct consequence of how Archive with Dataverse Long-Term Retention was originally built: one job in flight per scenario, and everything else waits. Microsoft’s March 2026 private preview changes that constraint, and it does so through one new configuration concept worth understanding before requesting access: the job criteria key that makes parallel archive processing possible.
Archive with Dataverse Long-Term Retention moves data through three stages: active, historical but retained for compliance, and eventually deleted. Getting a record from the first stage to the second is a six-step background process: replication into Dataverse, marking the source record as eligible, updating its retention status, reconciling that the copy landed correctly, migrating it out of the live table, and finally exposing it to inquiry pages that can still read history. Depending on data volume, that full cycle runs seven to fourteen days, and it runs at a deliberately low priority so it doesn’t compete with transactional workloads during business hours.
The scenarios supported today span general ledger and tax transactions in Finance, inventory transactions, inventory journals, and sales orders in Supply Chain Management, and commerce transactions in Commerce, with more expected in future releases. None of that changes with parallel processing. What changes is how many of those seven-to-fourteen-day cycles a tenant can have running at once. Until this preview, the answer was one, regardless of whether an organization operates three legal entities or three hundred. A multi-entity deployment with a genuine general ledger archiving need could watch a backlog grow for months simply because the platform had no concept of running two independent jobs side by side, even when the two jobs touched completely unrelated data.
The mechanism Microsoft introduced is narrower than “run everything at once.” It hinges on a job criteria key, a partition identifier assigned when an archive job contract is created. When the scheduler sees two jobs with different criteria key values, it checks whether they target non-overlapping sets of records, and if they do, it lets both run concurrently instead of forcing the second to wait. If they don’t, or if the system can’t establish that they don’t, the original sequential behavior still applies.
That non-overlap condition is stated as an absolute in Microsoft’s own documentation: each job with a different criteria key value must process a completely distinct set of records, with zero overlap. There is no partial-credit version of this feature where jobs run concurrently and reconcile conflicts afterward. DataAreaId, the field that already partitions Finance and Operations data by legal entity, is the criteria key Microsoft is leading with in preview, and it’s an obvious starting point precisely because it satisfies that zero-overlap requirement by construction. Two legal entities never share a General Ledger transaction, so keying parallel jobs off DataAreaId is close to a free performance win rather than a configuration exercise with real risk attached, provided the archival scenario itself doesn’t reach across entity boundaries somewhere a solution architect hasn’t accounted for.

The scenario itself doesn’t change; the contract does. When an archive job contract is created, the criteria key value is set alongside the usual scope of tables and date ranges, and it’s this value the scheduler reads to decide whether two in-flight jobs can share the pipeline. In practice, that means an implementation planning parallel General Ledger archiving across, say, twelve legal entities creates twelve contracts, one per DataAreaId value, rather than a single contract configured to somehow fan out internally.
Once jobs are running, the Archive with Dataverse Long-Term Retention workspace is where the criteria key earns its keep operationally. It surfaces each job’s key value alongside its status, so an administrator can confirm at a glance that the jobs actually running in parallel are the ones intended to run in parallel, rather than discovering after the fact that two jobs quietly targeted overlapping data. For organizations building custom archival scenarios against custom tables, the sequencing matters here specifically: those custom scenarios and their criteria key logic need to be defined and validated before the first parallel job runs against them, not adjusted afterward, because the zero-overlap guarantee has to hold from the first concurrent execution onward.
The zero-overlap requirement is also where the risk concentrates. A criteria key that looks like a clean partition on paper, a custom dimension that’s supposed to map one-to-one with a business unit, for instance, can turn out to have edge cases where two values legitimately touch the same record, particularly in customized environments where table relationships have been extended past their original design. Because the preview enforces zero overlap by requirement rather than by runtime detection of every possible conflict, the burden of proving that a custom criteria key is safe sits with the team configuring it, not with the platform.
Two other details are easy to miss because they don’t show up until after a job finishes. First, capacity reporting lags the actual archival work: history table capacity reductions from automatic tuning can take up to seven days to appear, and Dataverse’s own capacity figures take up to a day to catch up. Running four jobs in parallel instead of one doesn’t make that lag disappear, so finance and IT stakeholders expecting an immediate storage win on the day parallel jobs complete need that timeline set correctly in advance. Second, organizations that use customer-managed encryption keys should know that long-term retained data lands under Microsoft-managed keys regardless of how many jobs move it there in parallel, which means a CMK migration for that retained data is a separate project, not something parallel processing resolves as a side effect. Finance and operations attachments still aren’t supported in any configuration, and while data that hasn’t yet been archived can be handled through normal processes, data that has already made the trip into Dataverse long-term retention cannot be pulled back to live tables.
Because this is a private preview, access starts with an enrollment request rather than a feature flag, and the honest advice for anyone requesting it is to have a specific backlog problem in mind rather than general curiosity about the feature. Organizations with dozens of legal entities and a General Ledger or inventory transaction archive that has been queuing for weeks are the clearest fit. A three-entity organization archiving a modest transaction volume is unlikely to notice much difference between sequential and parallel processing, since the queue was never the real bottleneck to begin with.

Once enrolled, the safer rollout path is to pilot parallel jobs against two or three legal entities in a sandbox first, confirm through the workspace that the criteria keys behaved as expected and that no overlap issues or data inconsistencies surfaced, and only then scale up to the full legal entity list in production. Given that archived data can’t be moved back to live tables, a misconfigured criteria key is not a mistake worth discovering at production scale. Treat the capacity reporting lag and the CMK migration question as items to raise with finance and security stakeholders during that same pilot, not after the first production jobs complete, so nobody is caught explaining an unexpected reporting delay or an encryption gap after the fact. For organizations already running Archive with Dataverse Long-Term Retention against a multi-entity Finance and Operations deployment, this preview is worth requesting now. Routeget has been helping clients sequence long-term retention rollouts around exactly this kind of phased validation, and parallel archive processing is a natural next step for any environment where the backlog, not the archive design itself, has become the actual problem.
#DataverseArchive #ParallelProcessing #LongTermRetention #DynamicsFinanceOps #DataCapacityPlanning #CloudArchitecture

Somewhere in your Dataverse environment, or bolted onto Dynamics 365 Finance and Operations through Lifecycle Services, there is probably a data pipeline that has been quietly exporting records to Azure Data Lake Storage for years without anyone touching its configuration. That pipeline stops working for good on November 30, 2026. Microsoft has confirmed there will be no further extensions past that date, which means any architect or BI team still running the legacy Export to Data Lake add-in needs an Export to Data Lake migration plan in motion now, not a vague intention to “look at it before year end.” With roughly eleven weeks left on the clock as of this writing, the practical question is not whether to move, but which of the two supported replacements to move to, and what actually breaks in the schema when you do.
The confusion around this deprecation runs deeper than most Microsoft retirements, largely because the naming has changed twice in the last two years and the marketing language has blurred two genuinely different services into one. It is worth being precise about what is actually going away before touching any configuration.
Export to Data Lake, the LCS-installed add-in that let finance and operations apps write entity data directly into a customer’s Azure Data Lake Storage Gen2 account, was marked deprecated back in October 2023 and stopped accepting new adopters on November 1, 2024. What has not been widely understood is that existing customers were allowed to keep running it on a grace period, and that grace period ends permanently on November 30, 2026. After that date, no further data lands in the lake through that pipeline. Downstream Synapse pipelines, Power BI datasets, and any custom ETL jobs reading from that storage account simply stop receiving updates, with no error thrown anywhere obvious enough to trip an alert.
What is not retiring, despite frequently being confused with the legacy add-in, is Azure Synapse Link for Dataverse itself. Microsoft has stated plainly that Synapse Link is a long-term supported service. The naming has shifted again as of the July 2026 UX refresh: the feature is now presented under a unified “Link data” page in Power Apps, split into “Fabric Links” as the recommended path and “Other Links” covering the Azure Synapse option. If your team has been searching documentation for “Export to Data Lake” and finding nothing current, that rename is why.
Once the rename is out of the way, the real architectural decision is between two genuinely different integration models, and picking the wrong one for your organization’s actual downstream consumers is the most common mistake we see in migration planning.
Link to Microsoft Fabric is a no-copy model. Data stays inside Dataverse’s managed storage and is exposed to Fabric and Power BI through OneLake shortcuts rather than being physically copied into a separate account you control. Setup is fast: a four-step wizard handles workspace identity authentication (now the recommended method over service principals, since Microsoft’s own release notes describe it as removing “the most common Fabric link setup failure mode”), table selection, and initial sync, which typically completes within about sixty minutes for moderate data volumes. The tradeoff is that you do not own the underlying storage account, table selection for non-system tables is largely automatic rather than admin-curated, and any custom pipeline tooling outside the Microsoft Fabric ecosystem has no direct file-level access to the data.
Azure Synapse Link for Dataverse, by contrast, continuously exports data as Delta Parquet files into a storage account your organization owns and controls. If your analytics estate depends on non-Microsoft tools, custom Spark jobs reading raw Parquet, or an existing Synapse workspace with pipelines your team has already built and tuned, this is almost always the correct choice, and it remains fully supported going forward. The tradeoff is that you take on more operational responsibility: managing the storage account, its firewall rules, and eventually a private endpoint migration if your organization needs one (a related but separate deadline, the trusted-services firewall exception for private link configurations, retires August 1, 2027, so build that into planning if it applies to you).
This is the part of the Export to Data Lake migration that catches teams off guard even after they have chosen a replacement path, because the schema produced by Fabric Link and Synapse Link is not a drop-in replacement for what the legacy add-in produced. Several changes will break any downstream job written against the old CSV-based output.
The most disruptive change for finance and operations data is that the primary identifier field, previously exposed simply as ID, is now surfaced as FnO_Id. Any view, stored procedure, or Power Query step that hard-codes the old column name will fail or silently return nulls after cutover, and this is worth grepping for across your entire analytics codebase before you flip the switch, not after. Time zone identifier (TZID) fields, which were largely unused legacy artifacts in the old export anyway, have been dropped entirely. Binary data columns are no longer included in the export at all, and nvarchar(max) fields are truncated at 2,000 characters, which matters if any process was relying on long free-text fields such as notes or descriptions coming through intact. On the positive side, the new format adds a proper isDelete flag for row-level soft-delete tracking, which the legacy CSV export never handled cleanly, so reconciliation logic that used to infer deletions by diffing snapshots can often be simplified.
There is also a prerequisite that trips up more migrations than the schema differences themselves: only tables with the Track Changes property enabled will appear as selectable in either Fabric Link or Synapse Link. A meaningful number of legacy finance and operations entities were never configured for change tracking, and some cannot have it enabled without developer involvement to extend the entity definition. Audit which tables your current pipeline depends on and confirm change tracking status on each one before you assume the new link will simply mirror what you already have.
The safest sequencing we recommend is to stand up the replacement link in parallel with the legacy export while both are still functional, rather than decommissioning the old pipeline first and troubleshooting the new one under deadline pressure. Run both for at least one full reporting cycle, ideally a month-end and quarter-end close if the data feeds financial reporting, and reconcile row counts and key totals between the two outputs before cutting anything over. Microsoft’s FastTrack team publishes two open-source transition tools worth using rather than building your own equivalents from scratch: a SQL Analytics Endpoint tool for validating Fabric Link output against expectations, and a Virtual Data Warehouse tool for Synapse Link migrations. Both are available through the Dynamics 365 FastTrack Implementation Assets repository and can shortcut a meaningful amount of validation work.
Two configuration details are also worth checking before you commit to a path: profiles that were originally set up in CSV format cannot be linked forward to Fabric, and profiles secured with managed identities have the same restriction. Both require a fresh setup rather than an in-place conversion, so factor that into your timeline if either applies to your current configuration. Once the new link is validated and running cleanly, the legacy Export to Data Lake add-in itself should be formally uninstalled through Lifecycle Services rather than simply left dormant, both to avoid confusion for the next person who inherits the environment and to remove a component that will stop functioning anyway once November 30 passes.
None of this is a difficult migration in isolation. A Fabric Link setup for an organization with modest data volumes and no custom storage requirements can realistically be completed in a day, including validation. What makes this deprecation worth taking seriously now rather than in October is the schema drift buried inside it: the ID field rename alone is enough to quietly break a Power BI model or a downstream integration that nobody has looked at closely in over a year. We have walked several clients through this exact transition at Routeget Technologies, and the pattern holds consistently: the technical setup is fast, but finding every place the old schema was assumed to be permanent takes the real time. Start that inventory now, while there are still weeks to spare rather than days.
#ExportToDataLake #AzureSynapseLink #MicrosoftFabric #DataverseIntegration #CloudArchitecture #ERPGovernance