Optimizing Power Automate Cloud Flows for Enterprise Scale: Concurrency Control, Throttling Strategy, and Real-World Performance Tuning

The Performance Cliff

A developer deploys a Power Automate cloud flow to process a weekly batch of 500 customer records, each requiring a Dataverse query and a downstream system call. The flow runs flawlessly in a 10-record test. Three weeks into production, on the first run against the full dataset, the flow executes for two hours, times out, and leaves downstream records in an inconsistent state. The root cause is rarely what the developer guessed: it is almost always concurrency misconfiguration, API throttling, or both working together to create cascading delays.

Performance optimization in cloud flows is not about elegance or best-practice theory. It is about understanding the difference between sequential and parallel execution, respecting API rate limits before hitting them, and building flows that scale linearly with data volume rather than falling off a cliff at some invisible threshold.

Sequential Versus Parallel: The Apply to Each Misconception

The most common performance mistake in enterprise Power Automate flows is the default assumption that Apply to Each loops run in parallel. They do not. By default, Apply to Each loops in Power Automate execute sequentially, processing one item at a time. For a 100-item array, this means 100 iterations, not a batched parallel execution.

Enabling parallelism requires an explicit configuration step. In the Apply to Each action, set the Degree of Parallelism to a value between 1 and 50. Setting this value to 50 allows Power Automate to process up to 50 items simultaneously, dramatically reducing total execution time. For a flow that processes 500 items and would take ten minutes to run sequentially, switching to degree 50 parallelism can reduce execution time to under two minutes.

The catch is that parallelism introduces complexity. When 50 copies of the same action execute at once, they are also making 50 concurrent API calls to downstream systems. If the downstream system is not designed to handle this concurrency, the flow succeeds but the target system becomes a bottleneck, throttles the requests, and the parallel advantage evaporates.

Understanding Throttling: Limits and Backoff

Power Automate cloud flows operate within hard throttling limits set by both the platform itself and by the connectors they use. The standard throttling limit for Power Automate connectors is approximately 2,000 requests per 60 seconds from a single tenant. Exceeding this limit causes the connector to return HTTP 429 (Too Many Requests), and Power Automate automatically backs off and retries.

A flow that makes rapid sequential calls to a single connector (for example, 50 parallel calls to Dataverse in the same second) will quickly hit this limit. Each call that hits the throttle is delayed, sometimes by seconds, which defeats the purpose of parallelism.

The strategy is not to avoid throttling entirely, which is impossible at scale. The strategy is to manage it deliberately. Three approaches work in practice:

Controlled concurrency pairing. Process data in smaller batches rather than maximizing parallelism. For a dataset of 500 items, instead of a single loop with degree 50, use an outer loop with degree 5, and within each iteration, process ten items in parallel. This spreads the load over time and prevents the thundering herd of concurrent calls that triggers heavy throttling.

Connector-specific limits. Different connectors have different effective throttle limits. A Dataverse connector used by twenty concurrent flows will throttle faster than a single flow making equivalent calls. Check the specific connector documentation and test against realistic concurrent load. Most enterprise Dynamics 365 environments can handle 10 to 20 concurrent Dataverse operations without throttling, but 50 concurrent operations will almost certainly trigger it.

Exponential backoff and retry logic. When a call fails due to throttling (HTTP 429), Power Automate applies its own retry logic by default, but it is aggressive. Implement explicit retry logic with exponential backoff: on the first retry, wait one second; on the second, wait two seconds; on the third, wait four seconds. This prevents the request storm from pounding the system again immediately and allows headroom for other operations.

Real-World Tuning: The Compose Trick and Other Optimization Patterns

Small performance gains accumulate. A surprising optimization emerged from the Power Automate community: the Compose action executes approximately twice as fast as a variable assignment for simple array operations. For a flow that iterates 500 times over an array, replacing a variable assignment with a Compose can shave twenty to thirty seconds off execution time. On its own, negligible. In combination with parallelism tuning, it contributes to the difference between two minutes and four minutes of runtime.

Another pattern is filtering and projection at the source. If a flow queries Dataverse to fetch 500 customer records but only needs the account ID and name, fetch only those columns rather than the full row. This reduces bandwidth and iteration overhead. Likewise, filter records at query time rather than within the flow, reducing the dataset the flow must process.

Batch update APIs offer dramatic speedups for bulk operations. Instead of updating 500 records one at a time (even in parallel), batch operations on SharePoint, Dataverse, or other enterprise systems can update hundreds of records in a single call. The performance difference is not marginal. A flow that updates 500 records individually, even at degree 50 parallelism, will take two to three minutes. The same operation using batch APIs completes in ten seconds.

Monitoring and Diagnosis in 2026

Power Automate’s monitoring capabilities have matured significantly. The 2026 wave 1 update includes process intelligence dashboards that show execution time breakdowns per action, helping identify bottlenecks. Using these dashboards is essential before optimizing. A developer who assumes the Apply to Each loop is the bottleneck, only to find that 90 percent of execution time is spent waiting for a single downstream system call, will chase the wrong optimization.

Process advisor, available in the cloud flow monitoring interface, visualizes where time is spent and flags potential inefficiencies. Running a flow through process advisor on a realistic dataset (not a ten-record test) exposes the true bottlenecks immediately.

Implementation Reality

The practical sequence for deploying a high-volume cloud flow is three stages. First, build the flow and test it against a small dataset (ten to fifty records). Validate the logic is correct. Second, test the flow against a realistic volume (500 to 2,000 records) in a non-production environment, using process advisor to identify bottlenecks. Third, implement tuning based on what the monitoring revealed: adjust concurrency, add batch operations if available, implement controlled backoff, filter data at the source. Retest at scale. Only then deploy to production.

A flow that works perfectly at ten records and poorly at 500 is not untested. It is tested against the wrong scenario. The difference between success and production outage is this single step of testing at realistic scale.

Conclusion

Cloud flows at enterprise scale are fast only when they respect both the parallelism opportunities the platform provides and the throttling limits that keep the infrastructure stable. The flows that scale well combine judicious parallelism (degree five to twenty, not fifty), connector-aware batching, and explicit retry logic. Monitoring at scale with process advisor, not test runs of ten records, is how developers find the real bottleneck and tune accordingly. Performance optimization in Power Automate is not a mystery. It is systematic pattern recognition, realistic testing, and the discipline to respect the platform’s limits before the platform enforces them at three in the morning during a production batch run.


Cloud flows running at scale require architecture-level thinking, not just action configuration. Routeget Technologies helps organizations design Power Automate solutions that grow with data volume rather than break at it. Our Power Platform architects have tuned flows processing hundreds of millions of records across global Dynamics 365 implementations.

#PowerAutomatePerformance #CloudFlowOptimization #PowerPlatformArchitecture #EnterpriseAutomation #DynamicsIntegration #ProcessAutomation #RPA #CloudWorkflows #DeveloperExperience

Building Custom REST API Connectors in Business Central: Exposing Data Securely for Third-Party Integrations and Mobile Apps

Building Custom REST API Connectors in Business Central: Exposing Data Securely for Third-Party Integrations and Mobile Apps

Business Central’s strength lies in its ability to integrate with modern cloud applications, but the real challenge emerges when you need to expose your financial and operational data through APIs that external systems and mobile clients can reliably consume. Out-of-the-box endpoints expose standard entities, but most integration scenarios demand custom data shapes, calculated fields, filtered subsets, or aggregate views tailored to specific business processes. Building these custom REST API connectors requires careful architectural decisions around authentication, data filtering, performance optimization, and monitoring, particularly in organizations handling high transaction volumes or supporting third-party mobile applications.

Understanding Business Central’s Native API Framework

Business Central exposes data through two primary API mechanisms: OData v4 endpoints for standard pages and tables, and the newer Pages API designed for application-level consumption. The Pages API builds on the modern AL language and provides a more controlled, versioned approach to data exposure than direct table access. Unlike Dynamics 365, which includes a unified Microsoft Dataverse layer, Business Central requires you to explicitly architect data exposure through custom API pages, which means your integration strategy must balance between leveraging the platform’s built-in capabilities and accepting responsibility for designing clean, maintainable contracts between Business Central and consuming systems.

The distinction matters operationally. Standard OData endpoints expose the database schema directly, which couples external consumers tightly to your internal data model. When you restructure a table or rename a field for internal reasons, external integrations break. Custom API pages decouple that contract, allowing you to evolve your internal schema independently from the promises you have made to external systems.

Designing Custom API Pages for External Consumption

Custom API pages in Business Central are AL procedures exposed through the REST endpoint /api/v2.0/companies({company-id})/custom-apis/. Define these using the Page object subtype, marking them as API and APIVersion to control versioning and backward compatibility. The page structure mirrors a standard page but operates as a service layer, processing inbound requests and returning structured JSON responses rather than rendering a user interface.

The design pattern establishes a clear separation: your custom page receives the incoming request, validates it, queries the underlying tables or reports with any necessary business logic, transforms the result into the contracted JSON shape, and returns it. This allows you to filter at the data layer, aggregate values, apply security row-level filters, and enforce business logic before data leaves the system. For example, a third-party field service application might request customer shipment history and location data. Rather than exposing raw table access, you create a custom API page that joins customer, sales order, and shipment tables, filters by the authenticated user’s assigned territory, calculates on-time delivery percentage, and returns only the fields the mobile app requires.

Authentication and authorization flow through the AL code itself. Within the API page, AL procedures can access the authenticated user’s context and apply permissions hierarchically. A request arriving with a specific OAuth token corresponds to a Business Central user; that user’s role, responsibility center assignments, and dimension filters determine what data the API returns. Building this filtering into the API page ensures that integrations consuming the endpoint respect your organization’s security model without requiring external filtering logic that might go stale or be misconfigured.

Authentication Strategies and Secure Data Exposure

Business Central supports OAuth 2.0 authentication via Azure AD, which securely delegates user identity without transmitting credentials directly to applications. For third-party integrations, you register the consuming application as an Azure AD client, establish trust with Business Central’s tenant, and issue tokens that grant scoped access. This pattern scales across internal applications, third-party SaaS vendors, and mobile apps developed for field teams.

For service-to-service integrations where no interactive user exists, you configure Azure AD application permissions and use the client credentials flow. The integrating service authenticates with its own client ID and secret, receives a token, and calls the API with that token’s authority. Business Central’s authorization layer validates the token and enforces whatever permissions the service principal has been granted, typically read-only access to specific entities for automation scenarios.

The critical security decision is scope: never grant an external service permission to the entire database. An automated reconciliation job needs specific journal entries and GL accounts, not access to vendor master records or payroll data. Implement this by controlling AL permissions at the table and field level within your custom API page. The code executes in a specific permission context; requests outside that context return 403 Forbidden before any data is retrieved.

Rate limiting prevents external integrations from accidentally or intentionally overwhelming Business Central with requests. Implement this at the API page level using a simple counter in a temporary table or in-memory structure, logging the authenticated user’s token, timestamp, and request count, then rejecting requests that exceed a threshold (for example, 100 requests per minute per token). This protects the system during integration testing when third-party code loops unexpectedly, or when a mobile app’s sync logic gets into a retry storm during network instability.

Common Integration Patterns and Implementation Considerations

Third-party integrations typically follow one of three patterns: read-heavy analytics flows that pull data into external dashboards or reporting systems, transaction-driven flows that insert or update Business Central records from external sources, and bidirectional syncs where data changes in either system trigger updates in the other.

For read-heavy scenarios, design your custom API to return data in a shape optimized for the consuming tool. A data warehouse pulling nightly sales history might request summarized daily shipment totals grouped by customer and region, not individual line items. An analytics platform might want both transaction details and aggregated metrics in a single response. Custom API pages let you compute these shapes once in Business Central and deliver them efficiently.

For transaction-driven inbound flows, implement idempotency. When a third-party order management system sends a new sales order to Business Central, include a unique idempotency key. The API page stores this key with the created record; if the same request arrives again due to a network retry, the API recognizes the duplicate and returns the existing record without creating a second one.

Bidirectional syncs require careful conflict resolution. If Business Central and an external inventory system both allow updates to stock levels, and both systems update the value simultaneously, which one wins? Document your conflict resolution policy explicitly: last-write-wins, field-level rules, or row-level versioning. Without explicit conflict resolution, silent data loss occurs.

Performance Optimization and Monitoring at Scale

As external integrations scale, API performance directly affects integration throughput and cost. A slowly responding API forces external systems to maintain more concurrent connections and retry more frequently. Optimize by indexing the tables you query most frequently within the custom API, filtering at the database layer rather than in application logic, and using efficient AL patterns.

Monitor API health using Application Insights or similar observability tools. Instrument your custom API page to log request count, response time, error rates, and authenticated users consuming high volumes. This visibility lets you spot performance degradation early and make data-driven decisions about whether to add rate limits, optimize queries, or provision additional capacity.

Establish a communication channel with integrating partners about expected availability, planned maintenance windows, and API contract changes. When you modify a custom API’s response shape, maintain backward compatibility by supporting both versions for a defined sunset period.

Conclusion

Secure, maintainable API integration in Business Central demands intentional architecture. Custom API pages decouple your internal data model from external contracts, authentication flows enforce security boundaries, and thoughtful rate limiting and monitoring protect system stability. Organizations that treat API design as a core platform responsibility, document integration contracts clearly, and actively monitor consuming applications’ health build integration ecosystems that scale with business growth rather than becoming bottlenecks during busy cycles.


Routeget Technologies has architected integration frameworks for mid-market and enterprise Business Central deployments, helping organizations balance the flexibility of third-party ecosystems with the security and governance demands of regulated industries. Custom API design, Azure AD federation, and integration monitoring are core areas of our Dynamics and Power Platform consulting practice.

#DynamicsIntegration #BusinessCentralAPI #RESTfulArchitecture #MicroservicesPatterns #CloudIntegration #DataSecurityGovernance #EnterpriseIntegration #APIDesignBestPractices

Integrating External Data Sources into Copilot Studio Agents: Building Secure Connectors for Real-Time Dataverse and Business Data Access

Most Copilot Studio implementations start with agents trained on static documentation or internal knowledge bases. That’s reasonable for onboarding and FAQs. But the moment you want an agent to answer “What’s my account status?” or “When does my contract renew?” you hit a boundary static training cannot overcome. A Copilot agent connected to your operational systems becomes a front-end to your data itself, multiplying its value immediately.

Getting there requires moving beyond the out-of-the-box experience. You need custom connectors that let agents retrieve data from Dataverse, call enterprise APIs, or query databases on demand. The architecture matters because you are no longer building a conversational interface to static content; you are building a conduit to operational data. Security, latency, error handling, and scalability all become real constraints.

Why Agents Need Real-Time Data Access

Standard Copilot topics ground agents in documentation, useful for tier-one support. The moment an agent needs to look up customer-specific information like account status, order history, or contract terms, static training fails. The agent needs a live connection to your system of record.

Many organizations stall here, overestimating the effort required. A well-architected connector to Dataverse or a single key API multiplies agent value immediately. A support agent that retrieves real data handles tier-two inquiries without routing to a human. A sales agent seeing current contract terms can suggest renewals in a single conversation instead of an email chain. This is where the real business value emerges.

Architecture for Safe Data Access

The standard pattern is a Copilot topic that calls a Power Automate cloud flow, which calls your data source. The flow can be a custom connector to Dataverse, a standard connector to SharePoint or SQL Server, or an HTTP action calling a REST API you own.

The flow is the security boundary. Copilot Studio does not call Dataverse directly; the flow sits between and enforces access control. This distinction matters because agents are exposed to broader audiences than typical internal applications. You cannot safely let every user query every Dataverse record. The flow is where authorization logic lives.

A typical customer support flow works like this: the agent extracts parameters (customer ID, order number, date range) from the conversation, passes them to the flow, the flow verifies the user has permission to view that customer’s data by checking security roles or a permission table, and only then retrieves the requested information from Dataverse. If the user lacks permission, the flow returns an error the agent can explain to the user in natural language. This pattern is durable because once your first connector works, adding more follows the same template. Second and third connectors compress substantially in implementation effort.

Building Dataverse Connectors

Dataverse connectors come in two forms: the out-of-the-box Power Platform connector, which is too permissive for Copilot use, and custom connectors wrapping your retrieval logic with proper authorization.

For Copilot agents, build a cloud flow that filters by customer ID, security role, or status. Retrieve specific columns only, not entire records. This removes unnecessary data and prevents the agent from accidentally leaking information users should not see. It also keeps response size reasonable.

Dataverse calls from Power Automate count against throttling limits. A single conversation triggering five data lookups can consume budget quickly, especially if users ask similar questions. Do not give up on live data; instead, cache results briefly within conversations. If a conversation asks “Show my orders” and then “Status of order X,” the first query returns the list and subsequent queries work from that result rather than calling Dataverse again.

Error handling deserves explicit attention. If a Dataverse query times out, the agent should not tell the user “the lookup failed” in a raw way. Instead, the flow should return a structured response indicating the issue. “I’m having trouble retrieving current data; please contact support” is far better customer experience than a stack trace.

Extending Beyond Dataverse

Not all business data lives in Dataverse. Supply chain inventory in ERP systems, pricing in commerce platforms, communication history in separate CRMs—all require the same pattern: the Copilot flow calls a cloud flow, which calls whatever API or database holds the data.

External systems typically require API authentication (OAuth, API keys, certificates) and have their own rate limits and latency characteristics. You cannot assume a three-second response time like Dataverse typically provides. Timeout handling and retry logic become critical. If your shipping system API is temporarily down, the agent degrades gracefully rather than hanging the conversation.

Retrieve data in parallel where possible. If the agent needs customer profile, order history, and open cases from three different systems, call them simultaneously using parallel branches rather than sequentially. This keeps total response time near three seconds instead of nine, which matters for user experience.

Security and Authorization

The most common mistake in live-data Copilot implementations is treating agents as if they have the same access as human users. They do not. An agent might be exposed to customers, partners, or the public, not just internal staff. Your authorization logic must be explicit and enforced at the flow level.

In Dataverse, verify the logged-in user’s security role or check a permission table mapping users to accessible data before returning any records. For external APIs, you may call with a service account that has broad access, but filter the response based on the user’s explicit permissions before passing data to the agent.

Data residency and compliance add another layer. Copilot conversations flow through Copilot Studio (hosted in a specific region), Power Automate (hosted in a specific region), and your data source. All components must align with compliance requirements. Do not assume restricted regions or systems are accessible without explicitly validating the architecture first.

Performance and Cost Optimization

Live-data Copilot agents consume more resources than static agents. Every conversation that retrieves data burns API calls, Dataverse capacity, or third-party API quota.

Caching is the first optimization. If a conversation asks about “my account” twice, do not query Dataverse twice. Store results in a variable the flow reuses. For repeated conversations, you might cache longer, but be explicit about cache invalidation. An agent returning stale data is worse than one that refreshes slowly.

Batch operations reduce latency. Dataverse supports batch retrieval. If the agent needs customer orders, ask Dataverse for ten orders at once rather than one at a time. This cuts round-trips and aligns with user expectations. A few-second wait for a complete list is acceptable; thirty seconds of sequential queries is not.

Set realistic expectations about latency. A Copilot pulling from multiple systems will not be instant. Users will notice a two or three-second delay while data loads. Build the UI to indicate the agent is “thinking” or “retrieving data” so the user does not think the connection has hung.

Moving Forward

A Copilot agent with live data access is no longer just a conversational interface to documentation. It becomes a front-end to your operational data. This requires treating security, error handling, performance, and compliance as first-class concerns from the start, not afterthoughts.

Start with one connector, one data source, one use case. Get authorization and error handling right. The pattern repeats for subsequent connectors, with substantially less effort. Within a quarter, your Copilot can answer substantive business questions rather than repeating training documentation.

#CopilotsStudioIntegration #AgenticAIDataAccess #EnterpriseAI #DataConnectors #CopilotDevelopment #DynamicsIntegration #CloudAutomation

Building Agentic AI Systems with Copilot Studio: Model Context Protocol Server Integration

Enterprise organizations building AI agents face a fundamental challenge: enabling large language models to perform meaningful work within existing systems while maintaining security, auditability, and control. Copilot Studio provides the interface layer for conversational agents, but traditional API integrations create fragility. Each new action requires endpoint configuration, error handling, and tight coupling to specific business logic. Model Context Protocol (MCP) servers offer a structured alternative. They allow agents to discover, request, and invoke actions across distributed systems through a standardized interface. For development teams architecting production-grade agentic systems, understanding how to design and integrate MCP servers into Copilot Studio workflows separates proof-of-concept prototypes from systems that scale across departments and organizational boundaries.

Understanding MCP as an Agent Capability Layer

The Model Context Protocol is a lightweight, JSON-RPC based standard defining how AI models interact with external tools and data sources. Rather than embedding specific tool definitions directly into an agent’s configuration, MCP creates a server layer that exposes capabilities in a way agents can discover and invoke independently. An MCP server implements two core patterns: resource exposure (providing read access to data or context) and tool definition (declaring executable actions with input schemas and return formats).

In Copilot Studio terms, an MCP server acts as a capability broker between the agent and backend systems. When a user interacts with a Copilot, the agent receives the request, determines which capabilities it needs, and queries the MCP server for available tools. The server responds with a catalog of action definitions; the agent selects appropriate tools, constructs parameters according to the schema, and requests execution. The server performs the action against the underlying system, returns structured results, and the agent synthesizes those results back to the user.

This architecture decouples the agent from specific implementation details. If business processes change or you need to add new backend systems, you extend the MCP server without rewriting agent logic. Teams building multiple agents needing access to the same core systems can reuse the same MCP server across different Copilots, reducing duplication and maintenance overhead.

Designing MCP Servers for Enterprise Dynamics 365 Scenarios

Most MCP server use cases in enterprise environments involve exposing Dynamics 365 and Microsoft Power Platform capabilities through standardized interfaces. Common patterns include MCP servers that expose Dataverse operations (create, read, update, delete with role-based access control), Power Automate flow invocation (triggering automated workflows from agent requests), or custom business logic endpoints (order fulfillment checks, inventory queries, approval workflows).

The design process begins with identifying which actions agents need to perform and who should be authorized. An MCP server accepting arbitrary Dataverse record creation is a security liability; an MCP server that only creates records in a specific table with predefined field values, within the scope of the user’s Dataverse security role, is architecturally sound. Define input parameters explicitly, validate data types and constraints before passing to backend systems, and handle errors gracefully by returning structured error messages the agent can interpret.

Consider a scenario where multiple Copilots need to query customer records, trigger approval workflows, and update lead status based on user interactions. Rather than hardcoding these capabilities into each Copilot, you build an MCP server exposing three tools: GetCustomerInfo, TriggerApproval, and UpdateLeadStatus. Each tool includes access control checks, parameter validation, and error handling. That server becomes the single source of truth for those capabilities; updating the underlying business logic happens once and applies across all agents that use it.

Implementation Considerations and Integration Patterns

Integrating an MCP server with Copilot Studio requires understanding the data flow and potential failure points. The Copilot Studio SDK provides mechanisms for discovering and invoking MCP servers. Configuration points to the server’s network location and credentials. At runtime, when a user interacts with a Copilot, the agent constructs a request to the MCP server’s tool discovery endpoint, which returns available actions. The agent processes the user’s natural language request, determines which tools apply, formats parameters, and invokes the tool via the MCP server. The server responds with execution results (success, failure, or partial success) that the agent interprets.

Resilience matters in this chain. What happens if the MCP server is temporarily unavailable? A well-designed agent might inform the user that a capability is temporarily offline or queue the request for retry. What if the user’s security role doesn’t allow the requested action? The MCP server should reject clearly, rather than attempting the action and failing silently. What if the underlying system returns unexpected data? The MCP server should normalize responses into the schema the agent expects.

Monitoring and observability are equally important. Log which tools were invoked, by which user, with which parameters, and what the outcome was. Structured logging (JSON format, clear event types) makes it easier to analyze patterns and identify when tools start failing unexpectedly.

Building Custom Tools Within the MCP Server Framework

Custom tools are where the MCP server delivers business value. Instead of asking users to navigate a system directly, an agent can expose a conversational interface that guides users through actions and invokes appropriate tools. An example: an expense approval workflow. The underlying Dynamics 365 workflow requires expense data (employee ID, category, amount, justification) in specific fields, routed to appropriate managers. An agent with access to an MCP-exposed tool can accept the conversational description (“I need to submit a client dinner expense of $500 for Tuesday”), parse relevant details, validate them against business rules (Is the user authorized? Is the amount within policy?), and invoke the approval tool, all without asking the user to navigate a form.

Building these tools requires clarity about inputs, validation, and return values. Tool definitions in MCP include a name, description (used by the agent to understand when to invoke), input schema (JSON schema specifying required and optional parameters), and implementation code. The implementation typically retrieves information from Dynamics 365 or Power Platform, applies business logic (checking approval authority, order fulfillment status, next process steps), and returns structured results. If implementation requires multiple backend calls (query Dynamics 365 customer data, check Power Automate status, verify external inventory), the MCP server orchestrates those calls and returns unified responses.

Error handling at this layer is critical. If a tool invocation fails (customer record not found, workflow error, API timeout), return error information the agent can act on. A generic “something went wrong” response is not useful; “Customer record with ID X not found in Dynamics 365” gives the agent actionable context.

Scaling and Common Pitfalls

As organizations mature their agentic AI adoption, a single MCP server often serves multiple Copilots across departments. A sales Copilot needs customer and opportunity records; an operations Copilot needs inventory and order fulfillment data; a finance Copilot needs expense and budget information. A centralized MCP server exposes core capabilities in a standardized way, and each Copilot calls the same server but requests only the tools it needs, avoiding duplication and inconsistent business logic.

Scaling also means handling load. An MCP server might receive tool requests from dozens of agents simultaneously, each serving multiple concurrent users. The server should queue requests appropriately, implement rate limiting if necessary, and fail gracefully if backend systems become unavailable. Caching helps. If the same customer record is requested repeatedly, the MCP server can cache it briefly rather than querying Dynamics 365 every time.

Teams new to MCP often make predictable mistakes. One: defining tool inputs too loosely. A tool that accepts “any Dataverse table name” is a security risk. Constrain tool inputs to specific, well-defined options. Two: insufficient error handling. Wrap backend calls in try-catch blocks, validate responses against expected schemas, and return clear error messages. Three: lack of monitoring. Implement structured logging, alert on tool invocation failures, and track response times so you identify performance regressions.

Moving Forward

If your organization is building agentic AI systems with Copilot Studio, the decision to use MCP servers should be driven by scope and complexity. A single Copilot performing a handful of simple lookups might not need the structure MCP provides. A multi-Copilot environment where agents need access to shared capabilities benefits significantly from MCP’s decoupling and standardization.

Start by inventorying the capabilities your agents need to perform. Group them by system (Dynamics 365 capabilities, Power Automate invocations, external APIs). Design an MCP server that exposes those capabilities through well-defined tools, with input validation, access control, and error handling. Build incrementally. Launch with the core capabilities your first Copilot needs, then extend it as additional Copilots come online. Monitor usage and iterate on tool definitions based on agent feedback.

The result is a more maintainable, scalable, auditable system where agents focus on conversational understanding and reasoning, while MCP servers handle the complex work of integrating with enterprise systems reliably and securely.

—

Routeget Technologies brings deep expertise in designing and deploying agentic AI systems within Microsoft Dynamics 365 and Power Platform environments, from MCP server architecture to multi-Copilot deployment strategies.

Tags: #AgenticAI #CopilotStudio #ModelContextProtocol #AIAgents #DynamicsIntegration #PowerPlatform #AIDevelopment #CloudArchitecture #Dynamics365 #EnterpriseSoftware

Building Approval Loops in Power Automate That Don’t Fall Apart

Enterprise approval workflow dashboard with timeout and escalation management

Approval workflows sound simple in theory. Send a request, wait for response, move forward based on outcome. But somewhere between the proof of concept and production reality, approval loops accumulate failures so quietly that six months pass before anyone notices half your approvals never closed, escalations silently vanished, and the finance team is manually reworking approvals that should have auto-completed.

The gap between what you design and what survives in production typically opens in three places: timeouts on waiting responses that get no notification when they expire, escalation logic that triggers but assumes someone is actually paying attention to a hand-passed email, and no mechanism to detect an approval that was submitted but never reached the assigned approver. Each failure is small enough to dismiss as a one-off, but they compound quickly enough that the flow looks broken even when it is technically working.

This isn’t a flaw in Power Automate itself. Approval loops are possible and reliable at scale. But they require specific configuration practices that most documentation glosses over because they fall outside the “happy path” that gets written up in tutorials. The actual production implementation involves setting constraints, monitoring for stuck states, and building reminders and escalations that stay responsive even when people are unavailable.

The Three Failure Modes in Approval Workflows

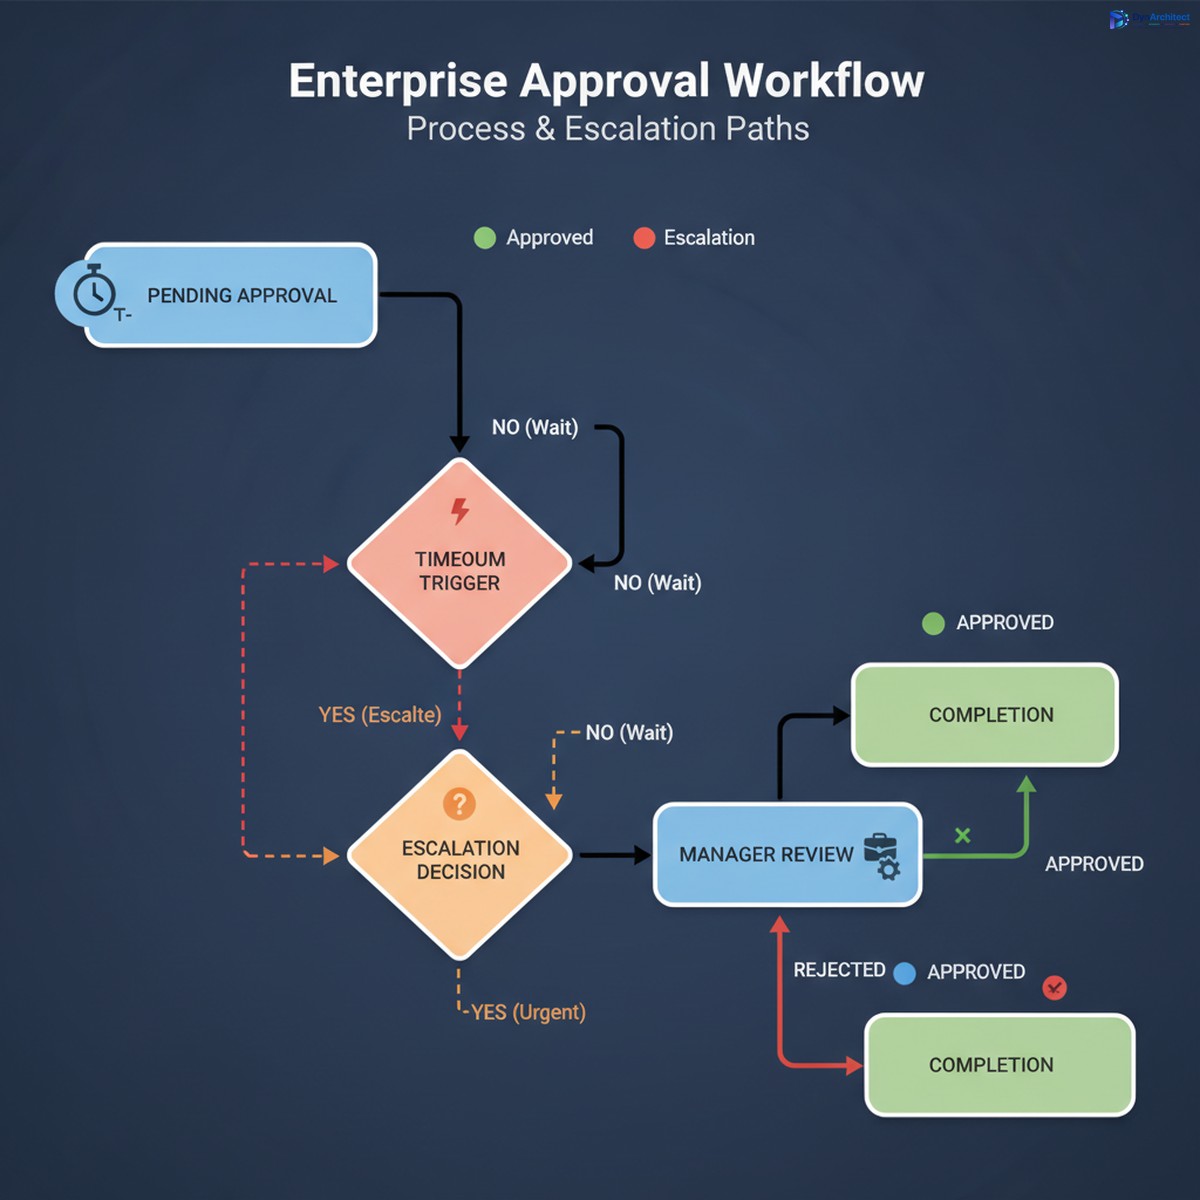
Power Automate approval workflow state transitions showing timeout and escalation paths

The first and most common failure mode is the timeout without escalation. By default, an approval waits forever for a response. In production, this means a request sits in someone’s inbox for days while they’re in meetings, on vacation, or simply overwhelmed. The approver eventually rejects or approves, but by then the original requestor has stopped watching and other parts of the process have already stalled or errored out. Better practice: set an explicit timeout on the approval action itself. Don’t wait indefinitely. Use a 48 or 72 hour window depending on your business, and when the window closes without a response, trigger an escalation workflow instead of just abandoning the request.

The second failure mode is silent escalation that nobody actually sees. When a primary approver times out, many designs hand off to a backup approver or manager using a simple email notify step. But email is not a reliable alert mechanism inside workflows. The backup approver doesn’t get a red flag in their task management system. The approval request lands in a folder with two hundred other emails. Three days later, the request is still pending, nobody knows why, and you discover by accident that the backup approver never saw it. Better practice: when escalating, create an explicit escalation record in a tracked system, assign it directly to the backup approver through Power Automate’s assignment or Outlook task creation, and log the escalation so you can report on it later.

The third failure mode is the orphaned approval that disappears from tracking. An approver response can fail for reasons outside your control: the response email is misrouted, the approval action times out before the response is processed, or the flow logic that handles the response encounters an error and doesn’t retry. In many cases, there’s no notification that the approval failed, so it simply stays pending forever. The requestor has moved on, the approver thinks they responded, and your audit log shows a request that was submitted but never resolved. Better practice: attach a completion deadline to every approval, separate from the timeout. If the approval has not resolved by that deadline, automatically resolve it with a fallback decision, and send a notification that escalation occurred.

Implementing a Production-Ready Approval Loop in Power Automate

Start with an approval request that includes a deadline. Use a scheduled cloud flow as a failsafe trigger that runs daily or every six hours and checks for approvals that have been pending longer than expected. If one is found, resolve it by creating a comment on the original record and moving the process forward with a fallback decision (typically approval, pending manager review). This sounds like it adds complexity, but it prevents the entire workflow from silently stalling.

The approval action itself should have a timeout set explicitly, measured in hours rather than days. In Power Automate’s approval action settings, set “Time Out In” to a value between 24 and 72 hours depending on your business rhythm. When that timeout is reached, the flow should not just stop. Instead, trigger an escalation workflow that routes to a backup approver, creates an escalation record, and sends an alert through a more reliable channel than email, such as a Teams message or a specific task in a project management system.

The escalation workflow should include logic that detects whether the backup approver is available. If the backup is out of office, the flow should identify an additional escalation level and continue upward. This requires maintaining a clear escalation path in a configuration table or SharePoint list, but it is the only way to ensure approvals don’t stall when a single person is unavailable.

Every approval flow should also log its state transitions to a tracking table. Each time an approval is requested, assigned, escalated, responded to, or timed out, write a record to a SharePoint list or a database table that includes the approval ID, the approver name, the action taken, the timestamp, and the outcome. This log is what makes it possible to audit the flow later, identify patterns of missed approvals, and debug failures when they occur. Without logging, you’re flying blind.

Error Handling and Retry Logic

Approval flows should not fail silently. Every step that might fail, particularly the send approval action itself, should have an error handler configured. If the approval action fails, the flow should retry once or twice before escalating. Use the retry policy built into cloud flows to automatically retry transient failures without adding extra steps.

The response handling section is where most approval flows fail operationally. The flow waits for a response, the response arrives, and then the flow tries to parse it or use it in a downstream action. If the response object is malformed or the downstream action fails, the approval is left in an inconsistent state. Configure error handling around the response processing step, and if it fails, log the failure, notify an administrator, and set the approval to a manual-review state so it can be handled by a human.

Avoiding the Common Pitfalls

Many approval flows make the mistake of embedding the approval timeout in a scheduled flow instead of setting it on the approval action itself. This doubles the complexity and introduces a race condition where the approval might respond after the timeout is checked but before the scheduled flow resolves it. Set the timeout on the approval action, not as a separate scheduled check.

Another pitfall is using the approval owner’s email address to send escalations. Escalations should be routed through the actual escalation workflow, not as emails copied to a backup. If the email approach is used, the escalation has no status tracking and no way to know whether the backup actually saw it.

A third pitfall is assuming that because an approval was sent, it was received. Always add a receipt confirmation step after sending the approval, using a follow-up flow or a scheduled check that verifies the approver’s status. Some organizations send a brief Teams message or Slack notification alongside the approval to ensure the approver knows to check their Outlook task.

Monitoring and Iteration

Once an approval loop is deployed, the real work begins. Run reports monthly on approval cycle times, timeout rates, escalations, and manual overrides. If escalations are happening more than 5% of the time, the timeout is too aggressive or the approval routing is misaligned. If timeouts rarely occur, you may be able to shorten the window to speed up the overall flow.

Track approvers who consistently miss deadlines and consider reassigning their responsibilities. Some approval routing that looks good on paper breaks down in practice because a particular approver is overloaded or rarely checks their tasks.

Approval loops are a reliable part of any organization’s workflow infrastructure when they are designed with production reality in mind. But that reality is messier than most documentation acknowledges. The difference between a working approval flow and one that silently breaks down is attention to timeouts, escalations, and monitoring from the start.

About Routeget Technologies: Routeget specializes in enterprise transformation across the Microsoft cloud ecosystem, including Power Automate automation and workflow optimization. Organizations looking to build production-ready approval systems that scale reliably can engage our consulting team to design governance frameworks, implement monitoring patterns, and optimize approval workflows for their specific operational needs.


#PowerAutomateApprovals #ApprovalWorkflows #EnterpriseAutomation #PowerAutomate #WorkflowOptimization #DynamicsIntegration

Power Automate API Request Limits Are Losing Their Grace Period. Most Dynamics 365 Integrations Aren’t Ready.

IT solutions architect reviewing a Power Automate integration flow dashboard on a large screen in an enterprise operations center

A finance operations lead watching a month-end close dashboard notices something odd: a batch of vendor invoices has been sitting in “waiting” status for eleven minutes. No error message, no failed run in the flow history, just silence. The Power Automate flow pulling records from Dataverse and pushing them into a document management system hasn’t crashed. It has been throttled, and almost nobody on the team knows that’s a distinct condition from a broken flow, let alone what triggers it or how long it lasts.

That gap in understanding is about to matter a lot more. Microsoft has spent the better part of the last two years quietly running Power Automate’s API request limits in what it calls a transition period: real entitlements exist on paper, actual enforcement is loose, and most tenants are running well past their official limits without consequence. That period has a stated end point, tied to when Power Platform Request usage reporting in the admin center reaches general availability, plus roughly six months. Teams that built integration flows assuming today’s permissive behavior is permanent are going to have an uncomfortable conversation with their CIO when enforcement tightens.

What Actually Counts Against Your Limit

The mental model most consultants carry around, that a “request” means one API call your flow makes to an external system, undersells how quickly limits get consumed. Every action in a flow run generates a request, whether it succeeds or fails. An action sitting inside an Apply to Each loop generates one request per item processed, not one request for the loop as a whole. Pagination counts separately too, so a flow that queries a Dataverse table with 50,000 rows and pages through results in batches of 5,000 will burn ten requests just retrieving data it hasn’t done anything with yet.

This is where a lot of Dynamics 365 integration flows get into trouble without anyone noticing during development. A flow built and tested against a sandbox environment with a few hundred sales order records behaves completely differently once it hits production volume. The loop that ran fine at fifty iterations in UAT becomes five thousand iterations against the live sales order table, and each of those iterations might trigger two or three downstream actions: a lookup, a field update, a notification. What looked like a lightweight automation in testing turns into a five-figure daily request count in production.

Developer typing on a laptop with a blurred Power Automate cloud flow diagram visible on a monitor in the background

The Power Automate API Request Limits That Actually Matter

Most teams that have heard of Power Automate throttling think of it as a single ceiling. In practice there are three separate mechanisms stacked on top of each other, and hitting any one of them produces the same frustrating symptom: a flow that stops making forward progress without a clear error.

The first is the 24-hour rolling entitlement, calculated per user for licensed accounts and pooled at the tenant level for application users and service accounts. A user with a standard Power Automate per-user or Dynamics 365 base license carries a 40,000 request allowance in any trailing 24-hour window. That window doesn’t reset at midnight. It slides continuously, so a burst of activity at 9 a.m. today is still being counted against the limit at 9 a.m. tomorrow, and any requests left unused simply expire rather than carrying forward.

The second is a five-minute burst cap of 100,000 requests, which applies independently of how much daily entitlement remains. A flow with a per-flow Process license carrying 250,000 requests per day can still get throttled mid-run if it tries to push too many of those requests through in a short burst, which is exactly what happens when an integration flow processes a large batch without pacing itself.

The third, and the one with the sharpest teeth, is continuous throttling over time. A flow that stays in a throttled state for 14 consecutive days gets turned off automatically. It can be reactivated, but if the underlying request pattern hasn’t changed, it cycles back into the same state. For a scheduled integration that runs nightly, two weeks of silent throttling is enough time for a genuinely broken process to look, from the outside, like nothing more than a slow week.

Architecting Integrations to Survive Enforcement

None of this means Power Automate is a poor choice for high-volume Dynamics 365 integration work. It means the flows need to be built with request budgets in mind from the start rather than retrofitted after a production incident.

Batching is the highest-leverage change available to most teams. Dataverse supports native batch operations that bundle multiple create, update, or delete operations into a single request rather than issuing one request per record. A flow rewritten to batch 100 record updates into a handful of batch calls instead of 100 individual actions can cut its request footprint by well over ninety percent for that segment of the process. This is worth doing even on flows that aren’t currently near any limit, because the same restructuring also improves run time and reduces the blast radius of a partial failure.

Child flows deserve more architectural attention than they usually get. Breaking a single monolithic flow into a parent that orchestrates and several children that each handle a bounded chunk of work makes it possible to apply concurrency control and pacing at a granular level, rather than trying to throttle an entire end-to-end process as one unit. Concurrency control settings on the trigger, often left at their defaults, are one of the more overlooked levers here: capping how many instances of a flow can run in parallel directly controls how fast it can burn through the five-minute burst allowance.

Trigger conditions matter more than most teams treat them. A flow that fires on every Dataverse row update and then checks conditions inside the flow body has already consumed a trigger execution and started accumulating requests before it decides the record doesn’t actually need processing. Moving that filtering logic into the trigger condition itself, evaluated before the flow run even starts, is free request savings that costs nothing to implement.

For flows that are genuinely high-volume by design, such as a real-time integration syncing order status between D365 Finance and Operations and an external logistics platform, the right answer may simply be licensing rather than architecture. A per-flow Process license carries a 250,000 request daily allowance on its own, and multiple Process licenses can be stacked on a single flow inside a solution, each one adding another 250,000 to that flow’s dedicated entitlement. For tenants not ready to change licensing, the Power Platform Request Capacity add-on adds 50,000 requests per 24 hours per pack and can be layered onto existing entitlements as a stopgap.

Get Ahead of the Reporting Gap

The Power Platform admin center’s usage reports are still catching up to the complexity of the limits themselves. Current reporting covers Power Automate API requests reasonably well but doesn’t yet give a clean picture of Dataverse, Copilot Studio, or Power Apps consumption in the same view, which means a team relying solely on the admin center dashboard is working from an incomplete picture of its actual request footprint. Until that reporting matures, the more reliable approach is instrumenting flows directly: logging request counts per run, watching for 429 responses in run history, and treating a spike in run duration as an early warning sign rather than waiting for a flow to get switched off.

Organizations we’ve worked with on Dynamics 365 and Power Platform integration architecture are increasingly building request budgeting into the design review for any flow expected to process more than a few thousand records a day, the same way they’d review a database query plan before it goes to production. That habit is worth adopting now, while the transition period still offers room to fix a poorly architected flow before enforcement makes the fix urgent instead of optional.


#PowerAutomate #APIRequestLimits #DynamicsIntegration #PowerPlatformGovernance #IntegrationArchitecture #EnterpriseAutomation