Preventing Unintended Blocks: Implementing Data Loss Prevention Policies Without Paralyzing Your Power Platform

Data Loss Prevention governance dashboard with security controls and policy checkpoints

Data Loss Prevention (DLP) policies in Power Platform sit at an uncomfortable intersection: they’re necessary for governance, but they’re easy to misconfigure so that your first draft breaks legitimate business workflows. Most organizations learn this the hard way, after a DLP policy ships and silently blocks connector calls in production automations. A finance team’s approval workflow mysteriously stops routing to Slack. A sales process can’t write leads to an external data warehouse. Nobody notices until something breaks on a Tuesday afternoon.

The challenge is structural. DLP policies operate at the connector level, not at the individual action level, so a single overly restrictive rule can disable entire classes of integrations across your tenant. The organizations that avoid catastrophic blocks are not the ones that build the most restrictive policies first. They’re the ones that start with a clear map of what data actually needs protection, then craft policies targeting that specific risk rather than trying to lock down anything that looks suspicious.


Understanding DLP in Practice

A Data Loss Prevention policy defines which connectors can share data with each other. You classify connectors as Restricted Data (like SQL Server, Dataverse, SharePoint), Limited Business Use (like Slack, Teams), or General. The policy enforces rules like “data from Restricted connectors cannot flow to Limited Business Use connectors.”

The critical point most organizations miss: these classifications are tenant-wide and apply to all environments unless you create specific overrides. A policy blocking Slack from receiving SQL Server data blocks it everywhere, for everyone. That sounds straightforward on paper, but most organizations have at least a dozen legitimate integrations that move data between categories that look “risky” in isolation. A financial reporting automation sending a Slack summary of daily sales. A customer service workflow pulling account data from Dataverse to an external ticketing system. A sales tool reading opportunities from Dynamics 365 for pipeline visibility.

None of these are data leaks. All would be blocked by an overly broad DLP policy.


Common DLP Mistakes

The first mistake is auditing too aggressively. Many organizations activate DLP in Audit mode to collect data on actual usage patterns without blocking anything. The theory is sound. The practice is crushing volumes of alerts, most false positives or unavoidable business integrations. Teams see 10,000 violations in a month with no systematic way to separate real concerns from critical workflows. They either give up on enforcement or ship a policy based on highest-volume alerts, which usually fails.

The second mistake is confusing audit alerts with actual risks. Not every data flow represents a security problem. A sales team’s external deal tracker is not a breach waiting to happen just because it reads from Dataverse. An approval workflow sending Teams notifications is not exposing proprietary information just because Teams is classified as Limited Business Use. Organizations conflate appearance of complexity with presence of risk, then tighten policies to zero out complexity. This transfers risk to shadow IT. People still move the data they need. If official integrations are blocked, they’ll build their own via Excel and manual uploads.

The third mistake is shipping policies without environment-level testing. DLP policies are tenant-scoped by default, so a broad policy breaks production systems across business units before validation in staging. The correct pattern is testing in specific environments, monitoring real workflow impact, then rolling out to the entire tenant. Executives want company-wide governance immediately, but breaking multiple workflows costs more than a phased rollout.


Building a Working DLP Policy
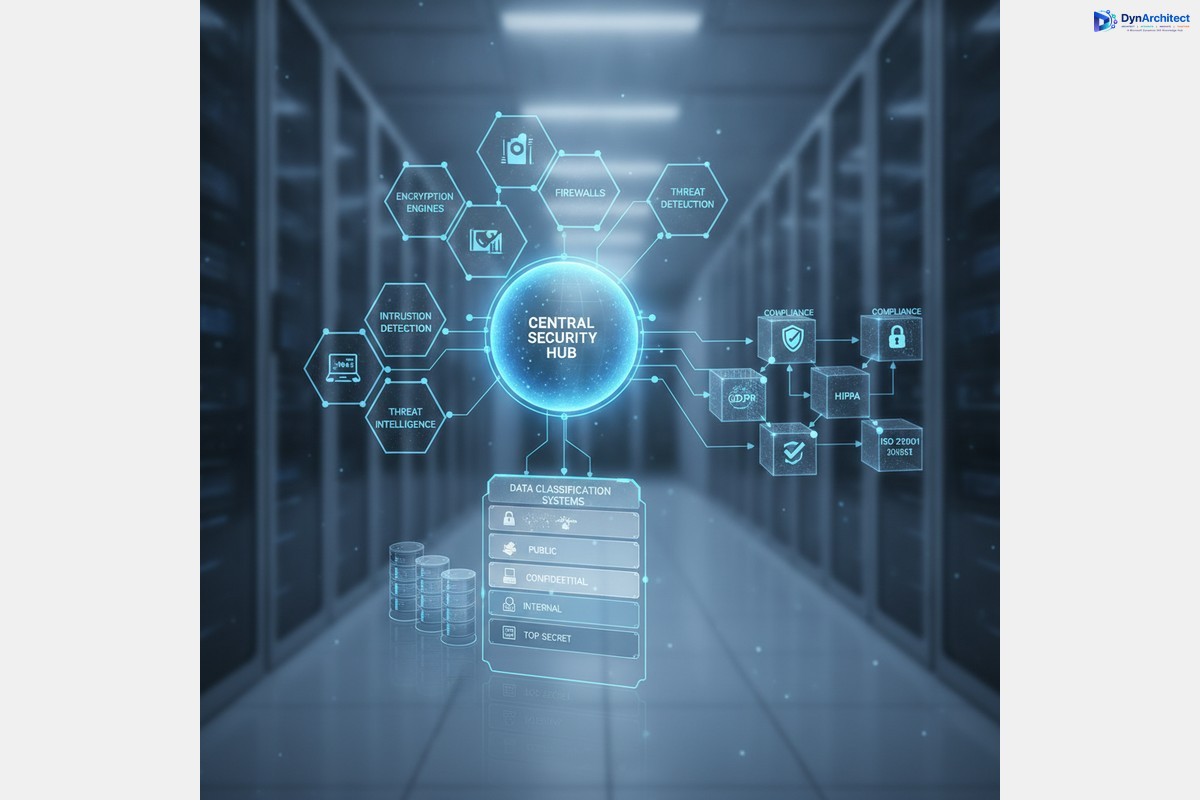
Enterprise security infrastructure showing data governance and compliance controls

Start with an actual inventory of your integrations, not a theoretical one. Go through your most business-critical Power Automate flows (approval automations, financial data movements, sales processes) and document which connectors they use and what data moves between them. Don’t ask business owners what they think is critical. Inspect the flows. You’ll find integrations that look risky but are actually essential. A manufacturing team’s work order system pulling from Dataverse and posting to an external MES system. A finance team’s journal import flow reading CSV from a web service and loading into Dynamics 365. These would fail under restrictive DLP, and stakeholders will fight when they break.

Second, classify connectors based on actual data sensitivity, not theoretical risk. Dataverse and SQL Server carry genuinely sensitive data and warrant strong controls. SharePoint carries mixed content and needs nuance. Slack and Teams are low-sensitivity by themselves but become sensitive only when receiving restricted data. The mistake is classifying Slack as Limited Business Use, then treating any flow from SQL Server to Slack as violation. That blocks the finance team’s daily sales summary, sales team’s pipeline snapshot, and customer service team’s alert automation. These aren’t leaks, they’re operations.

A better approach is classifying Slack as General for normal use, then building specific policy exceptions for flows that legitimately move summarized data from restricted systems. This requires identifying those flows in advance.

Third, build your initial policy at the environment level, not tenant-wide. Create a restrictive policy for sandbox and development environments. Test your business-critical flows in staging with your proposed tenant-level DLP policy before shipping. You will find your policy breaks something unexpected. Refine the policy, create flow-specific exceptions, or move that flow to a dedicated environment with looser rules. All beat discovering your policy broke production automations.

Fourth, document every policy exception and why. When carving out exceptions for flows moving data between connector categories, write down the business reason, data classification, and approval stakeholder. This prevents exceptions from becoming a free-for-all over time. Each exception should have a clear owner and documented security rationale. Quarterly audits will make sense of your policy instead of inheriting blackbox carve-outs.


Monitoring and Maintenance

Finally, review your DLP policy every quarter. Power Platform gets new connectors regularly. Integration patterns change as teams adopt new tools. A policy from Q1 might be outdated by Q3. Quarterly review catches new patterns, adjusts classifications as you learn more about actual data flow, and retires unnecessary exceptions. Organizations that ship a policy and never touch it end up either too restrictive (silently blocking workflows) or too permissive (defeating the point).

Set up Power BI reporting against Power Platform audit logs. Create dashboards showing DLP violations over time by connector pair, environment, and flow. Most organizations find 80 percent of violations come from a handful of flows or connector combinations. For each, decide: Is this legitimate and needs exception? Is it shadow IT to replace? Or is it misconfigured? Document the decision.

Engage with solution architects and flow owners before violations happen. After quarterly reviews, share audit logs with teams owning business-critical integrations. This conversation prevents surprises and keeps teams aligned rather than feeling DLP is something done to them.


DLP policies are not set-and-forget security controls. They’re part of ongoing governance between your security team, platform team, and business stakeholders. Organizations implementing DLP successfully are not enforcing maximum-security policies. They start with a clear picture of what they’re protecting, build policies addressing that specific risk, and refine them as their integration landscape evolves. That approach is slower than dropping maximum-security on the entire tenant, but it’s the only approach that works in organizations where Power Platform ties directly to business operations.


#PowerPlatformGovernance #DataLossPrevention #DLPPolicy #PowerAutomateIntegration #MicrosoftCloudSecurity #EnterpriseGovernance

Business Central Doesn’t Ship a Visual Production Scheduler. Manufacturers Need to Budget for One.

A production scheduler pointing at a large touchscreen displaying a colorful Gantt-style production schedule in a factory control room

A finance director at a contract manufacturer we spoke with recently put it plainly: her company had spent seven figures moving off an aging NAV instance and onto Business Central, and the go-live checklist covered chart of accounts mapping, inventory valuation, and tax setup in exhaustive detail. Nobody on the project had asked how the shop floor supervisor would actually build tomorrow’s schedule. Three weeks after cutover, that supervisor was back to a whiteboard and a spreadsheet, because the production order list Business Central shipped with told him what needed to happen, not when it would fit around the machines he actually had.

That gap catches a lot of SMB manufacturers off guard, and it is worth naming directly: Business Central does not ship a visual production scheduler. It has a capable manufacturing module underneath, with production orders, routings, work and machine centers, and both finite and infinite capacity calculations. What it does not have, out of the box, is a Gantt-style planning board where a scheduler can see every order across every work center at once and drag one into a different slot. For a make-to-order or configure-to-order shop where the schedule changes twice before lunch, that missing piece is not cosmetic. It is the difference between planning and reacting.

What Business Central Actually Gives You Natively

It helps to be precise about where the native functionality stops, because vendors on both sides of this conversation tend to blur the line. Business Central’s core manufacturing app calculates capacity using calendars assigned to work and machine centers, supports forward and backward finite loading, and will flag overloads through capacity planning worksheets. A planner can run a capacity availability report, look at a load percentage by resource, and reschedule a production order’s dates through the order card. All of that is real, and for a job shop running a handful of routings with predictable sequencing, it can be enough.

Where it breaks down is visualization and speed of adjustment. The native screens are list-based: rows of orders, rows of capacity figures, filtered views that require a planner to hold the whole picture in their head. There is no single canvas that shows Order 4021 sitting on the CNC line from 2:00 to 6:00 while Order 4033 is queued behind it, waiting on a changeover. When a rush order lands, or a machine goes down mid-shift, the planner is reconciling several list views rather than looking at one board and dragging a block. That reconciliation work is exactly what visual scheduling tools were built to remove, and it is why the category exists as a distinct add-on market inside the Business Central ecosystem rather than a feature Microsoft has folded into the base product.

Where a Visual Production Scheduler Actually Fits

Search AppSource for Business Central manufacturing extensions and you will find several purpose-built scheduling tools, the most established being Netronic’s Visual Production Scheduler and its more advanced sibling, Visual Advanced Production Scheduler, alongside other entrants like Graphical Scheduler and MxAPS. These are not replacements for Business Central’s manufacturing data model; they sit on top of it, reading and writing directly to the same production order and capacity tables so nothing has to be exported to Excel or re-entered anywhere. What they add is the missing visual layer: a Gantt-style board that typically splits into two views, one answering “will I hit my delivery dates” by laying out orders against the calendar, and a second showing utilization by work or machine center so a scheduler can spot an overloaded resource before it becomes a missed shipment.

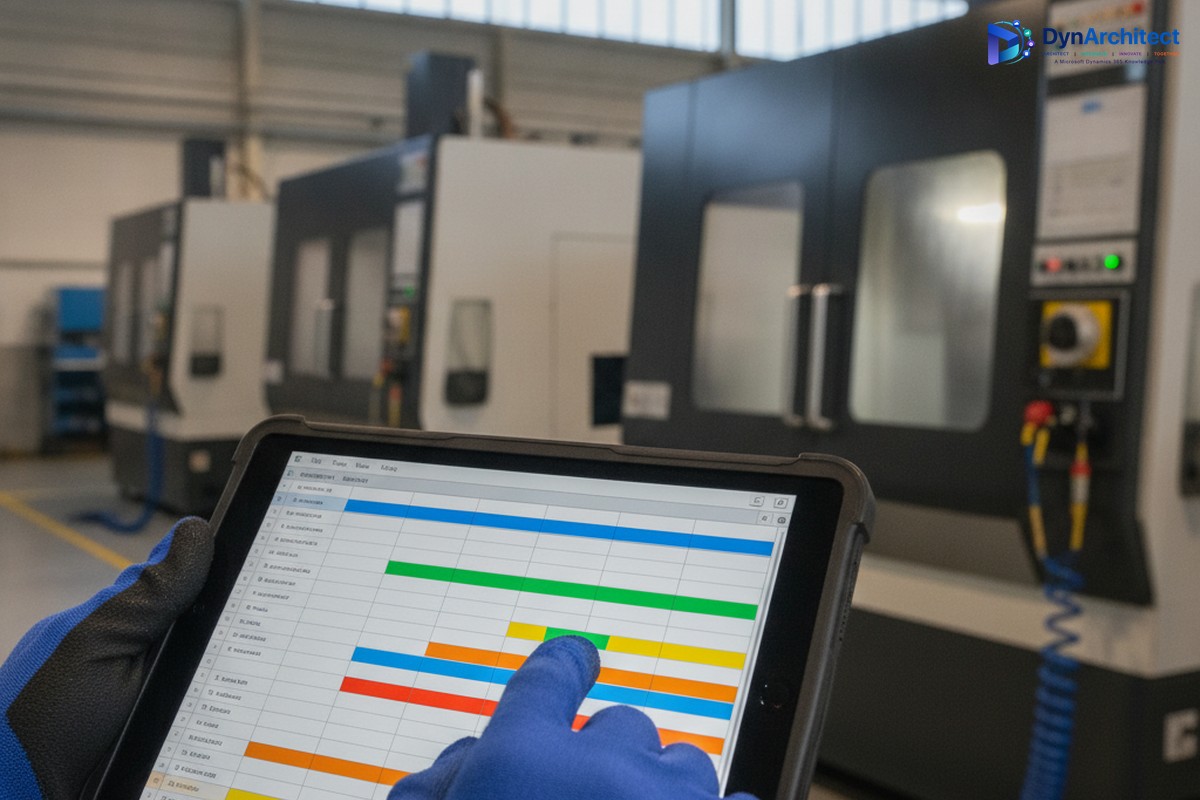
A shop floor worker holding a tablet showing a drag-and-drop visual production schedule next to CNC machining equipment

The interaction model is the actual value. Instead of opening a production order, changing a date field, and re-running a capacity check, a scheduler drags an operation block to a new slot and sees the conflict, or the lack of one, immediately. Reassigning an order from one machine center to another equivalent one takes the same drag-and-drop motion. Vendors in this space report meaningful gains in on-time delivery from customers who adopt this pattern, though as with any vendor-published figure, it should be treated as directional rather than a guaranteed outcome for every shop floor, since the actual result depends heavily on how disciplined the underlying routing and work center data already is.

The Decision a CFO or IT Director Actually Has to Make

None of this means every Business Central manufacturer needs a scheduling add-on on day one. A shop with two or three work centers and a stable, low-mix production schedule may genuinely be fine with the native capacity worksheets, and adding a third-party module there would be solving a problem that does not yet exist. The decision point is usually mix and volume: once a plant is juggling more than a handful of concurrent orders across multiple resources, with routing changes, rework, or expedites showing up weekly rather than monthly, the native list-based tools stop scaling with the complexity of the floor.

The practical mistake we see during Business Central selection and implementation projects is treating visual scheduling as something to revisit after go-live, almost as an afterthought bolted on once the finance and inventory modules are stable. That ordering gets the cost and the change-management burden backwards. Licensing a scheduling add-on is a separate line item, typically priced per named user or per environment, and it needs its own implementation time to map routings and work centers correctly, since the visual tool is only as good as the underlying capacity data it renders. Building that into the original project budget and timeline, rather than treating it as a post-go-live patch, avoids a second wave of user training and a second change request against a system that finance already considers “done.”

There is also a governance dimension worth flagging to IT: because these add-ons write directly back into core manufacturing tables, they need the same change-management scrutiny given to any other extension touching production data, including how they behave during version upgrades and whether the vendor maintains compatibility with the current Business Central release cadence rather than lagging behind it.

What to Ask Before You Buy

For a decision-maker evaluating this category, a few questions cut through most of the vendor marketing. First, does the tool read and write directly to standard Business Central production order and capacity tables, or does it maintain a shadow schedule that has to be reconciled back into the ERP, since the latter reintroduces exactly the synchronization risk the tool is supposed to eliminate. Second, does it support both finite capacity visualization and the specific constraint types your floor actually deals with, such as sequence-dependent changeovers or shared tooling across machine centers, rather than a generic Gantt view that looks good in a demo but cannot represent your real constraints. Third, what does the implementation actually involve beyond installing the extension, since the value of any visual scheduler depends entirely on routing and work center data being accurate before the drag-and-drop layer goes on top of it.

Getting this right is less about picking the “best” scheduling tool in the AppSource marketplace and more about being honest, early in a Business Central project, about whether the plant’s actual scheduling complexity requires this layer at all. Routeget has walked several manufacturing clients through exactly this evaluation during Business Central selection, and the pattern holds: the shops that budget for scheduling visibility from the start avoid the whiteboard relapse that pulls a supervisor back to manual planning three weeks after a system they were told would solve this problem for them.


#BusinessCentral #ManufacturingERP #ProductionScheduling #ShopFloorVisibility #ERPImplementation #DigitalTransformation

Copilot Studio ROI Measurement: Why Resolution Rate Isn’t Enough Before You Scale

Operations manager reviewing a customer service agent performance dashboard in an enterprise office

A customer service director at a mid-market manufacturer recently walked into a steering committee meeting with a number she was proud of: her Copilot Studio agent was resolving 78 percent of engaged sessions without a human handoff, up from 61 percent three months earlier. The CFO asked one question that stopped the meeting cold. Had customer satisfaction moved in the same direction? It hadn’t. CSAT had drifted down two points over the same period. The agent was closing more conversations. It was not clear it was actually helping more people.

That gap is becoming the central question for any organization running a Copilot Studio pilot with an eye toward production scale. Copilot Studio ROI measurement has matured considerably over the past year, with Microsoft now publishing a formal value framework alongside the platform’s built-in analytics. But the metrics that make a pilot look successful to an internal audience are not automatically the metrics that justify expanding it to every customer-facing channel a company operates. Getting that distinction right, before the budget request goes to the board, is the difference between a scaling decision built on evidence and one built on a single flattering number.

Operations manager reviewing a customer service agent performance dashboard in an enterprise office

What the Monitor Tab Actually Tells You

Copilot Studio’s built-in analytics, accessible from the Monitor tab in the maker portal, track session outcomes across four categories: resolved, escalated, abandoned, and unengaged. Resolution rate is calculated as the share of engaged sessions that end in a resolved state, and Microsoft’s documentation is specific about how “resolved” gets determined. A session counts as resolved either when a user explicitly confirms an answer solved their problem, or, more quietly, when the user simply doesn’t respond after receiving one. That second path, an implied resolution, is where the manufacturer’s numbers started to diverge from reality. A user who gives up on a chatbot and closes the browser tab looks statistically identical, in the resolution rate calculation, to a user who got exactly what they needed.

Escalation rate and abandonment rate round out the core picture: escalation tracks handoffs to a human agent, split into system-intended handoffs (the bot routes on purpose), system-unintended handoffs (something went wrong), and user-requested handoffs. Abandonment tracks sessions that time out without either outcome. Engagement rate measures the share of total sessions that move past a passive greeting into an actual topic or system flow. CSAT, on a straightforward one-to-five scale, is the metric most likely to contradict a rosy resolution number, and it deserves at least as much weight in a scaling decision as the headline resolution figure, not a supporting-cast role beneath it.

The Quality-Versus-Throughput Trap

The pattern the manufacturer ran into has a name among practitioners who implement these agents for a living: the quality-versus-throughput trap. A resolution rate climbing while CSAT falls is a specific, checkable warning sign, not statistical noise. It usually means the agent is getting faster at closing sessions without getting better at actually answering the underlying question, and implied resolution is the mechanism that lets that happen without tripping any alarm in the standard dashboard view.

The fix isn’t complicated, but it does require deliberately pulling two numbers into the same review rather than reporting resolution rate in isolation. Any pilot-to-production decision should require both metrics on the same slide, tracked over the same window, with a defined tolerance for how far they’re allowed to diverge before the rollout pauses for investigation. It’s also worth checking topics with unusually high implied-resolution counts specifically, since a handful of poorly scoped topics are often responsible for most of the gap, and fixing those few topics can move the CSAT number more than a platform-wide tuning pass would.

Two IT professionals reviewing a chatbot conversation on a laptop screen

Microsoft’s Own Framework for Copilot Studio ROI Measurement

Microsoft has published a genuinely useful, if underused, structure for this problem in its Copilot Studio guidance documentation, organized around four value drivers: efficiency, quality, revenue, and strategic value. Each driver comes with its own pricing logic rather than a single blended score. Efficiency is priced as hours returned multiplied by a fully loaded hourly rate. Quality is priced as the change in error rate multiplied by transaction volume and the cost of an error. Revenue is priced as a conversion delta multiplied by volume, unit revenue, and an attribution discount that accounts for the agent not being the only factor in a customer’s decision. Strategic value, the hardest to quantify, folds in things like optionality, talent retention, and organizational resilience.

The most concrete piece of this framework is a formula Microsoft calls Agent Assisted Hours, which converts raw session data into a labor-hours estimate. It weights sessions that cite a knowledge source and sessions that don’t, applies outcome weights of 1.0 for resolved sessions and 0.7 for escalated or abandoned ones, and multiplies the result by a default time-savings assumption of six minutes per reference before dividing by sixty to get hours. Microsoft’s own worked example uses 10,000 monthly sessions, split between sessions with knowledge citations and sessions without, arriving at roughly 1,440 assisted hours per month. At the platform’s default hourly rate of 72 dollars, drawn from U.S. Bureau of Labor Statistics compensation data, that works out to a bit over 100,000 dollars in monthly value and something in the neighborhood of 1.2 million dollars annualized. Whether that specific rate or those specific session ratios apply to any given organization is a separate question, but the formula itself is a far more defensible way to talk to a CFO than “resolution rate went up.”

Where the Numbers Get Murky

Three complications are worth flagging before anyone builds a board presentation around these figures. First, Microsoft’s own documentation is inconsistent on how long a session has to sit idle before it counts as abandoned, with one guidance page citing thirty minutes and another citing an hour. That’s a small detail, but it changes the abandonment denominator enough to matter if two teams are comparing numbers pulled from different reference points.

Second, and more consequential for organizations running both a Copilot Studio agent and a Dynamics 365 Omnichannel contact center, the two systems measure resolution, escalation, and abandonment differently by design. Copilot Studio analytics track only the bot’s portion of an interaction, while Omnichannel analytics track the full lifecycle including the human agent’s part of the conversation. A single customer interaction can register as several distinct sessions in Copilot Studio’s counting logic while showing up as one session in Omnichannel. Microsoft states this plainly in its own guidance. It means a CIO comparing a “before Copilot Studio” baseline against an “after Copilot Studio” number needs to be certain both figures came from the same measurement system, not two systems with similarly named metrics that are quietly counting different things.

Third, the billing model underneath all of this changed in September 2025, when Copilot Studio moved from message-based billing to Copilot Credits. Microsoft’s admin center documentation describes a credit as one user interaction generating one response, a simple one-to-one framing. Partner implementers who have actually run production traffic describe something messier: a single turn that triggers generative grounding plus a connector action can consume well over ten credits, which means historical message-volume estimates from before the change can’t be used to forecast credit consumption after it. Microsoft does publish a Copilot Studio Agent Usage Estimator specifically because the credit math isn’t intuitive from the documentation alone, and any organization sizing a production rollout should run its own traffic patterns through that tool rather than extrapolating from a pilot that ran under lighter, less representative usage.

A Practical Checklist Before the Scaling Decision

None of this argues against scaling a Copilot Studio agent. It argues against scaling on the strength of one number that happens to look good in isolation. Before a pilot moves to production, pair resolution rate with CSAT on the same review cycle and set a divergence threshold that triggers a pause. Pull actual credit consumption from the Power Platform admin center’s agent-level usage view, not a projection based on pilot-stage traffic, since real usage patterns tend to run heavier than early testing suggests. Build a test set using Copilot Studio’s Agent Evaluation feature, which reached general availability in March 2026 and lets makers validate topic reliability against up to a hundred defined cases before exposing a scaled version to live customers. And export feedback comments and transcripts to an external store on a regular cadence, since the native Analytics tab retains free-text feedback for only twenty-eight days, which is not long enough to support a continuous improvement program that spans a full budget cycle.

The organizations getting real value from these agents are the ones treating the Monitor tab as a starting point for questions, not a finished scorecard. Routeget Technologies has walked several clients through exactly this transition, from pilot metrics that looked convincing on their own to a value model that could actually survive a CFO’s second question. That second question is usually the one that matters most.


#CopilotStudio #AgenticAI #CustomerServiceAI #AIGovernance #EnterpriseAI #DigitalTransformation

Dynamics 365 Contact Center Playbooks Let Supervisors Write Routing Logic in Plain English. IT Still Has to Govern It.

Contact center supervisor reviewing a live conversation routing and queue dashboard

It is 8:40 on a Monday morning and a contact center supervisor at a mid-size distributor is watching a queue for premium accounts back up past the fifteen-minute mark. Two years ago, fixing that meant opening a ticket with IT, waiting for someone who understands the routing rule builder to free up an afternoon, and hoping the change didn’t collide with three other rules already live on that queue. Today, in a growing number of Dynamics 365 Contact Center environments, that supervisor can type a sentence: if a Gold-tier customer waits more than thirty seconds with no agent available, raise their priority every thirty seconds until someone picks up. The system takes it from there.

What Dynamics 365 Contact Center Playbooks Actually Do

Conversation orchestration, the feature behind this shift, is not simply a rebrand of unified routing’s existing rule engine. Traditional unified routing evaluates a conversation once, at the moment it arrives, against a static classification ruleset and assigns it to a queue. Dynamics 365 Contact Center playbooks instead monitor a conversation across its full lifecycle and respond as conditions change: wait time climbing, an agent signing out, a queue moving from staffed to unstaffed outside business hours. The playbook itself is authored through a guided template rather than a rule-tree editor. An administrator (Microsoft’s documentation specifically calls out System Administrator and Omnichannel Administrator roles, not a developer role) picks a scenario such as dynamic prioritization, overflow handling, or bullseye expansion of the eligible agent pool, attaches up to ten conditions built from context variables like customer tier or region, and writes the logic as a sentence rather than a nested if/then structure.

Underneath that plain-language input, a language model converts the sentence into a structured runtime policy the routing engine can actually execute. That detail matters more than it sounds like it should, and we will come back to it.

The Real Change: Configuration Authority Moves Off IT's Desk

For a Contact Center Director, the operational upside is straightforward to state. Routing changes that used to require a developer familiar with the classification rule syntax, plus a change window, plus regression testing against every other rule on that queue, can now be drafted, tested in draft status, and published by the person who actually owns the queue’s performance. Microsoft’s own framing of the feature leans hard into this: playbooks are meant to be authored and published “within minutes” by operations staff, not routed through an IT backlog. For an organization running twenty or thirty queues across voice and chat, each with its own seasonal patterns and VIP handling rules, that is a genuine reduction in the lag between noticing a problem and fixing it.

It also changes who is accountable for a bad outcome, and that is where the governance conversation needs to start well before rollout, not after the first incident.

Why Dynamics 365 Contact Center Playbooks Need a Governance Layer Before Broad Rollout

Microsoft’s own documentation is candid about a specific limitation worth reading closely: because the system uses a language model to translate a plain-language playbook into structured runtime logic, the converted output might not fully capture what the administrator actually intended, and any deviation can only be identified once the playbook is running against live conversations. In practice, that means a supervisor could write a sentence that sounds unambiguous to a person and have it compiled into routing logic that behaves slightly differently than expected, with no warning until customers start landing in the wrong place. This is not a hypothetical edge case worth dismissing. It is the stated behavior of the feature, documented in the same page that describes how to build a playbook.

That single fact should shape how any organization rolls this out. Treating a published playbook as production logic the moment it goes live, with no observation period, skips the one safeguard the platform actually gives you: the Draft status. A playbook can sit in Draft indefinitely while an administrator reviews it, and Microsoft’s diagnostics tooling for unified routing extends to playbooks as well, giving supervisors a way to watch what a rule is actually doing against real traffic before trusting it unattended. Any rollout plan that skips a monitored soak period on a low-risk queue, in favor of pushing straight to a high-volume VIP line, is accepting a risk the documentation already flagged.

Contact center team configuring routing logic while agents handle live conversations in the background

There is a second governance thread that CIOs and legal or compliance stakeholders should not miss. Microsoft’s supplemental terms for the feature include an explicit disclaimer that conversation orchestration is not intended for, and should not be used to make, decisions affecting an employee’s compensation, rewards, seniority, or other employment-related entitlements, and that organizations remain responsible for complying with employee monitoring and consent laws in their jurisdiction. That guardrail exists because the underlying mechanism, real-time monitoring of live conversations and automated action based on evolving conditions, sits close enough to workforce monitoring that Microsoft felt the need to draw the line explicitly rather than leave it implied. Any organization piloting playbooks for agent-assignment scenarios, where the system is reconnecting customers with representatives they spoke to previously, should have its HR and legal teams review the scope of what is being monitored and why before the first playbook touches a live queue with actual agents on it.

Rollout Considerations Worth Deciding Before the First Playbook Goes Live

A few practical constraints shape how this should actually be piloted. The feature currently supports voice and live chat channels only, so any organization running significant volume through digital messaging channels, social, or SMS will need to keep those on the existing classification ruleset for now. Microsoft has stated plans to expand channel coverage, but has not committed to a date at the time of writing, so it should not be assumed for planning purposes. The platform also enforces validation that prevents publishing two playbooks for the same scenario on the same queue, which forces a useful discipline: one queue cannot end up with silently conflicting logic, but it also means teams need to decide up front which playbook owns a given scenario rather than layering fixes on top of each other the way ad hoc rule trees sometimes accumulate over the years.

Licensing is the other piece worth confirming before a pilot gets too far along. Conversation orchestration carries its own licensing requirement separate from base Contact Center or Customer Service entitlements, and organizations on a pay-as-you-go consumption model need an Azure subscription with billing configured before the feature will run in production. This is easy to miss during a proof of concept built in a sandbox environment and then discover as a blocker when it is time to move to a live queue, so it is worth confirming with a Microsoft licensing specialist as part of the pilot scope rather than after.

Where This Leaves a CIO Weighing the Rollout

The case for conversation orchestration is not that natural-language configuration is a novelty. It is that it collapses the distance between the person who understands a queue’s real-world behavior and the person who can change how it routes, without requiring both of those people to be the same person or to coordinate through a ticket queue. That is a legitimate operational gain, particularly for organizations whose contact center staffing and customer tiers shift with seasonality or promotions. But the platform’s own documentation hands you the risk list: translation drift between what was written and what actually runs, employment-law boundaries around monitoring, and a validation layer that assumes disciplined ownership of which playbook governs which scenario. None of those are reasons to skip the feature. They are the checklist for a rollout plan that treats a published playbook the way any other piece of production logic deserves to be treated, with a review step, an observation period, and a named owner. Organizations that have gone through this kind of change management before, when unified routing itself first replaced manual queue assignment, will recognize the pattern. This is the same shift one layer further along, and it rewards the teams that plan for it rather than the teams that discover the gaps live.

Routeget Technologies has helped clients stage this kind of rollout, pairing the operational speed of self-service configuration with a review process that catches translation drift before it reaches a live queue, and it is the kind of governance work that pays for itself the first time a playbook does not do quite what the sentence said it would.


#DynamicsContactCenter #UnifiedRouting #ConversationOrchestration #ContactCenterGovernance #CustomerServiceAI #ITGovernance

Dataverse Long-Term Retention Can Cut Your F&O Storage Bill in Half. It Doesn’t Keep Your Encryption Key.

IT and finance leaders reviewing a Dataverse storage capacity dashboard in a boardroom

A CFO reviewing next year’s Power Platform renewal usually finds the same line item growing faster than anything else on the invoice: Dataverse database capacity. For a Dynamics 365 Finance and Supply Chain Management customer with a few years of general ledger, tax, inventory, and sales order history behind it, that growth is not a mystery. Transactional tables in F&O apps do not shrink on their own, and every fiscal year adds another layer of records that almost nobody queries but that the platform still has to store, index, and back up at full price.

IT’s answer to that problem usually arrives as a single line in a capacity review deck: turn on Dataverse long-term retention and archive the old transactions out of the live database. It is a real fix, and Microsoft’s own numbers back it up. But the conversation tends to stop there, before anyone asks the question a security or compliance lead should be asking, which is what happens to the encryption key protecting that data once it moves.

Why F&O Capacity Grows Faster Than the Budget Assumes

Dataverse long-term retention, sometimes shortened to LTR, lets an organization move inactive records out of live application tables into a separate, read-only retention layer that still lives inside Dataverse and is still governed by Microsoft Entra ID. For Finance and Supply Chain Management specifically, Microsoft currently supports archiving general ledger transactions, tax transactions, inventory transactions and journals, sales orders, and Commerce transactions this way. Attachments are explicitly excluded for now.

The financial case is straightforward once you see the compression numbers. Microsoft states that data moved into Dataverse long-term retention consumes roughly half the capacity of the same data sitting in a live table, and when the F&O-specific archive process goes a step further and migrates that data into history tables rather than leaving it only in retention, the history-table footprint can run closer to 30 percent below the original. At a commonly cited list price of roughly 40 dollars per gigabyte per month for Dataverse database capacity, an organization sitting on several hundred gigabytes of aging general ledger and inventory history is not looking at a rounding error. It is looking at a five- or six-figure annual number that a straightforward archive policy can meaningfully cut, without touching a single report a controller actually runs day to day.

That is the pitch that gets this feature onto a roadmap. It is also, on its own, an incomplete pitch.

What Dataverse Long-Term Retention Actually Does, and How Long It Takes

The mechanics matter for planning purposes, not just for understanding the technology. Microsoft’s documentation describes the F&O archive process as a sequence of stages: replication of records into Dataverse long-term retention, marking of records that meet the retention policy’s criteria, reconciliation to confirm every record made it across intact, and finally migration, where the data is moved into history tables and removed from the live application tables. Only after that full sequence completes does the capacity reduction actually show up in reporting, and Microsoft’s own timeline for that is seven to fourteen days depending on data volume, with archival jobs deliberately run at lower priority than normal application workloads.

There is a detail buried in that same documentation that tends to surprise architects who assume large-scale platform jobs run in parallel by default: they do not, here. Microsoft states plainly that the stages of the F&O archival process “run sequentially in the background.” If you are planning to archive several years of general ledger, tax, and inventory history in the same cycle, that sequencing, not the compression ratio, is what actually determines how long your capacity relief takes to land. A rollout plan built around a single “flip the switch and wait a week” assumption is usually wrong by a factor of several weeks once multiple table types and several years of backlog are involved.

None of that is disqualifying. It is simply the kind of operational detail that belongs in a project timeline, not a surprise a program manager discovers in week three.

The Encryption Question That Actually Changes the Decision

Close-up of a compliance professional reviewing an encryption key management interface on a laptop

Here is where the conversation should slow down before a decision gets made, particularly for regulated industries such as financial services, healthcare, government contracting, or any organization with a contractual or regulatory commitment to control its own encryption keys.

Microsoft Power Platform has moved through two generations of customer-controlled encryption. The older mechanism, generally referred to as bring your own key or BYOK, is now explicitly positioned by Microsoft as a legacy predecessor to the current customer-managed key, or CMK, model. That distinction is not cosmetic. Microsoft’s own migration guidance states that environments still running the legacy BYOK encryption model are locked out of a specific list of newer Dataverse capabilities until they migrate to CMK, and Dataverse long-term data retention is on that list, alongside elastic tables, Dataverse search, AI Builder, and several others. An organization that has not made the BYOK-to-CMK move simply cannot turn retention on yet.

For organizations evaluating the F&O-specific archive path directly, Microsoft’s own archive documentation adds a second, sharper detail. It states that customers using the legacy BYOK model should be aware that data moved into Dataverse long-term retention is encrypted with a Microsoft-managed key rather than the customer’s own key, and it recommends migrating to customer-managed key as a result. Read carefully, that is Microsoft telling its own customers that the encryption custody model can change the moment data crosses from a live table into the archive, unless the tenant has already completed the CMK migration first. It is worth noting that the guidance itself is not fully explicit about whether this applies only to tenants still on the older model or to every tenant regardless of current key configuration, and a security team relying on this feature for a compliance commitment should confirm the current behavior for their specific tenant and encryption configuration directly with Microsoft before treating archived data as covered by the same key custody guarantee as their live data.

For a business that markets its own data handling on the strength of customer-held encryption keys, whether to a regulator, an auditor, or a customer contract, that is not a footnote. It is a governance gap that needs to close before the capacity-savings project starts, not after an auditor asks where the archived general ledger data actually lives and under whose key.

Sequencing the Decision Correctly

The organizations that get this right treat Dataverse long-term retention as a governance initiative with a cost-savings side effect, not the other way around. That means confirming current encryption status first: whether the tenant is still on legacy BYOK, already on CMK, or using Microsoft-managed keys by default, since only the first case actually creates a conflict. It means building the CMK migration, if one is needed, into the project plan ahead of the retention policy rollout rather than in parallel with it, since Microsoft’s own guidance describes CMK migration as something that can happen without contacting Microsoft support, which removes one common excuse for delay. And it means setting expectations with finance leadership that the capacity savings materialize over a multi-week sequential process per table type, not overnight, so the budget conversation is not built on a timeline the platform cannot actually deliver.

We at Routeget Technologies have walked F&O customers through exactly this sequencing, and the pattern holds consistently: the technical archive configuration itself is the easy part. The harder, more valuable conversation is the one between IT, finance, and compliance about what “the data is still in Dataverse” actually means once the key protecting it is no longer necessarily the one the organization chose.

The capacity savings on a Dataverse long-term retention rollout are real, and for an F&O environment with years of transactional history, they are often large enough to justify the project on cost grounds alone. But the encryption question is not a technicality to resolve after the fact. It is the first question a CIO or CFO should ask before the retention policy goes live, and the answer determines whether this is a two-week configuration task or a multi-month project that starts with a key migration.


#DataverseRetention #CustomerManagedKey #BYOKMigration #DynamicsFinanceOps #ERPCostOptimization #CloudArchitecture

The Power Pages Enhanced Data Model Migration Tool Reached GA. The Four Templates That Couldn’t Move Now Can.

Solution architect reviewing data migration dashboards on a dual-monitor workstation in a modern office

The Migration That Kept Getting Delayed

If you have maintained a Dynamics 365 Customer Self-Service, Partner, Community, or Employee Self-Service portal since before the Power Pages rebrand, you have almost certainly run into this wall: everything Microsoft has shipped for Power Pages application lifecycle management over the last three years, solutions support, Power Platform pipelines, environment variables, faster provisioning, has applied only to sites built on the enhanced data model. Your site, built on the standard data model with its familiar adx_ prefixed tables, has been sitting outside that perimeter the entire time. You could read every announcement, watch every demo, and still not be able to touch any of it, because the migration tooling that was supposed to bring your site along explicitly excluded the four Dynamics 365 portal templates. That changed on September 7, 2026, when Microsoft moved the standard-to-enhanced data model migration utility in the Power Platform CLI to general availability and, for the first time, extended it to Customer Self-Service Portal, Employee Self-Service Portal, Community Portal, and Partner Portal sites.

This is not a small technical footnote. For a lot of organizations running production portals on these templates, it is the first realistic path off a data model that Microsoft has been quietly deprecating in practice, if not in name, since 2023.

What the Standard Data Model Was Actually Costing You

The distinction between the standard and enhanced data models is not cosmetic. On the standard data model, website configuration lives in a set of legacy adx_ entities: adx_webpage, adx_webrole, adx_weblink, and so on. Those tables were never built for the deployment discipline that modern ALM assumes. Configuration changes get made directly against a live environment, promotion between environments means manually reconciling records or wrestling with unmanaged solution exports, and Microsoft has to maintain backward compatibility with a table structure that predates Dataverse solution awareness altogether. The enhanced data model consolidates that configuration into the newer powerpagecomponent table structure, which is solution-aware, supports environment variables, and plugs directly into Power Platform pipelines. Sites on the enhanced data model also provision faster and pick up feature and security updates automatically, rather than waiting on package installs that someone on your team has to remember to schedule.

None of this was news. What was missing, until this month, was a supported way to get an existing site there without rebuilding it from scratch. Microsoft’s own documentation was blunt about the gap as recently as March 2026, stating outright that sites created with the four Dynamics 365 templates could not be migrated and that only new sites on those templates would land on the enhanced data model. If you were running a production Partner Portal from 2021, your only two options were live with the limitation indefinitely or replatform the entire site.

What the Enhanced Data Model Migration Utility Shipped at GA

The migration utility itself is not new. Microsoft first previewed pac powerpages migrate-datamodel back in April 2024, and it worked reasonably well for the templates it supported: starter layouts, application processing, blank page builds, program registration, and scheduling sites. What reached general availability on September 7 is both a maturity milestone and a scope expansion. The scope expansion is the four Dynamics 365 templates finally being added to the supported list, which is the headline for most technical teams reading this. The maturity milestone is three specific capabilities that were not reliable enough to trust in preview: a genuinely useful customization dependency report that tells you what will break before you commit to anything, a status-check command so you are not guessing whether a large migration job is still running or has stalled, and a formal rollback path if validation turns something up after the data has moved.

Running the migration itself still follows the same sequence architects who piloted the preview will recognize. You authenticate against the target environment, generate a customization report scoped to a specific website ID, and read that report closely before doing anything else, since it is the tool telling you exactly which of your customizations depend on tables that will not exist in the same form once you move. From there, you migrate configuration data and, separately, transactional data referencing that configuration, using mode flags that let you split the work rather than attempting a single all-or-nothing pass. A status-check command lets you monitor long-running jobs on sites with meaningful data volume, and only once you are satisfied do you run the command that actually switches the site over to serve from the enhanced data model record. The CLI now requires Power Platform CLI 2.11.2 or later, along with updated Dataverse base portal and Power Pages core packages, so confirm your tooling versions before you start rather than discovering a version mismatch mid-migration.

Close-up of a developer typing CLI migration commands with terminal windows and a data flow diagram in the background

The Five Things That Will Actually Break

The customization report is useful precisely because most Dynamics 365 portal implementations that have been running for several years have accumulated customizations the original template never anticipated, and those are where the real work lives. Five categories come up consistently. Custom columns added directly to the legacy adx_ metadata tables have no equivalent in the enhanced schema, so you will need to stand up a new custom table, add a lookup back to powerpagecomponent, and migrate the data across rather than expecting an automatic mapping. Relationships built between your custom tables and the old adx_ tables need to be recreated against their powerpagecomponent equivalents, which means auditing your solution for every such relationship before you migrate, not after. Liquid code that references entities directly, something like assigning a variable from entities[‘adx_weblinks’], needs to be rewritten to use the corresponding Liquid object instead, since the enhanced data model does not expose those legacy entity names the same way. FetchXML embedded in Liquid templates that queries adx_ entities by name has to be rewritten against powerpagecomponent with a componenttype filter, and getting that filter value wrong is a common source of queries that silently return nothing rather than failing loudly. Finally, any custom plugins or classic workflows registered against the old tables need to be re-registered against their enhanced equivalents, which is easy to forget if that logic was written by a developer who has since moved on and the automation itself has been running quietly in the background for years.

None of these are migration blockers on their own. They are the reason the customization report exists, and the reason this gets treated as a project with a real test phase, not a command run against production on a Friday afternoon.

How to Actually Run This

Start on a full copy of the production environment, not a shared sandbox someone else is also using that week. Run the customization report first and treat it as your scope document: every item it flags becomes a line in your migration plan, and if it flags nothing, that itself is worth double-checking against a manual review of your solution, since undocumented customizations from years back do not always get picked up cleanly. Migrate configuration data and configuration data references as separate, deliberate steps rather than reaching for the combined mode on a first attempt, since separating them gives you a natural checkpoint to validate before moving transactional data. Watch your table sizes going in: the migration processes records in batches of five thousand, so a site with a large volume of case records, form submissions, or forum content tied to configuration should expect the migration job to take real time, and you should plan your maintenance window accordingly rather than assuming it finishes in minutes. Once the migration completes, work through the five customization categories above methodically against your report before you consider the environment production-ready, and only then schedule the actual cutover during a low-traffic window given that end users will be locked out or degraded while the switch happens.

Treat this as a two-track modernization rather than folding it into the separate Bootstrap 5 template migration Microsoft made generally available for these same four templates back in June. One is about the underlying data model and ALM story, the other is about front-end markup and CSS, and combining them multiplies your testing surface for no real benefit. Sequence the data model migration first, stabilize, then take on Bootstrap as its own scoped effort.

Why This Is Worth Prioritizing Now

Every enhanced-data-model-only feature Microsoft has shipped since 2023 stays out of reach until you make this move, and the pace of that list is not slowing down. In our work at Routeget Technologies with legacy Dynamics 365 portal environments, we have consistently seen operational overhead trace back to being stuck on manual package management and unmanaged solution exports, simply because migrating never had a supported path for the specific template a client was running. That excuse is gone now. The work is not trivial, and the five customization categories above are real effort, not boilerplate. But for a portal your organization depends on, closing that ALM gap and getting onto a data model Microsoft is actively investing in is a better use of a sprint than continuing to work around a limitation that no longer needs to exist.


#PowerPages #EnhancedDataModel #PowerPlatformALM #DynamicsPortalMigration #LowCodeGovernance #PowerPlatformCLI

The CoE Starter Kit Is Dead. Agentic Center of Enablement Isn’t the Full Replacement Yet.

IT governance director reviewing a Power Platform admin governance dashboard on a large office monitor

If your organization still runs the Power Platform Center of Excellence Starter Kit, you already know something changed this year. The monthly release cadence that used to ship new Power BI dashboards, governance flows, and inventory jobs went quiet in February. By May, Microsoft made it official: the kit is “no longer receiving ongoing feature investments or updates.” For a lot of IT Directors and Power Platform CoE leads, that left a real question sitting on the desk. The DIY governance stack your team spent two or three years building and patching now has no vendor behind it, and the natural next move, moving everything into the Power Platform admin center, only gets you partway there.

That gap just got a little smaller. In September 2026, Microsoft opened public preview on the Agentic Center of Enablement, a set of three AI agents built directly into the admin center that are meant to take over a chunk of what the CoE Starter Kit used to do by hand. It is a meaningful step. It is not, on its own, a like-for-like replacement, and understanding exactly where the line falls matters more than the headline announcement.

What Actually Happened to the CoE Starter Kit

The timeline is worth stating plainly, because a lot of the commentary around this has blurred it. Development on the CoE Starter Kit effectively stopped in February 2026. Microsoft’s public confirmation followed in the spring, framed not as an abandonment but as a redirection of engineering effort: governance capability was moving from a community-maintained accelerator into the product itself. That framing turned out to be accurate, just slower to materialize than the announcement implied. Between May and September, organizations that depended on the kit for environment inventory, maker identification, and license reclamation were largely left running an unsupported toolset with no clear native equivalent for several of its core jobs. The admin center had usage and licensing dashboards, but not the ownership tracking, lifecycle states, or cross-tenant rollups that a mature CoE program actually runs on day to day.

That is the backdrop the Agentic Center of Enablement is stepping into, and it explains why the reaction from practitioners has been cautiously interested rather than celebratory.

IT governance director reviewing a Power Platform admin governance dashboard on a large office monitor

Agentic Center of Enablement: Three Agents, One Governance Loop

The Agentic Center of Enablement is not a dashboard you configure. It is three purpose-built agents that run continuously against your tenant, and each one does a distinct job in what Microsoft is positioning as a closed governance loop.

The Highlights agent produces a daily snapshot of tenant activity with no setup required: new resource creation, capacity consumption shifts, and other changes an admin would otherwise have to go looking for. The Insights agent is the one doing the heavier analytical work. It scans the tenant continuously and surfaces governance issues, ownerless resources, activity happening in the default environment, and security, compliance, performance, and adoption problems, then ranks them by impact so an admin isn’t left triaging a flat list. The Action Plan agent takes whatever the Insights agent surfaces and turns it into a concrete remediation plan with defined steps, which an admin reviews and approves before anything actually executes. Every action any of the three agents takes is logged in a full audit trail, which matters for organizations that need to show a paper trail to internal audit or a regulator.

Access is straightforward by design. It requires at least one managed environment in the tenant and the Power Platform administrator role, and it activates automatically rather than needing a deployment project the way the old kit did. For a CIO comparing total cost of ownership, that alone is worth noting: there is no solution to import, no Power Automate flows to maintain, no Dataverse tables to keep patched against breaking API changes.

Solution architect typing at a keyboard with dual monitors showing governance and application inventory analytics

Picture the scenario the Insights agent is actually built for. A regional sales team spins up a canvas app in the default environment to solve an immediate problem, the maker moves teams six months later, and the app keeps running with nobody watching its connector permissions or its data exposure. Under the old model, that app surfaces only if someone happened to run the right CoE Starter Kit inventory flow and then manually reviewed the output. Under the new model, the Insights agent flags it as default-environment activity with an ownerless resource attached, ranks it against everything else it found that day, and the Action Plan agent proposes reassigning ownership or migrating it into a governed environment before anyone has to go looking. That is a genuine reduction in the manual triage work a CoE analyst used to own.

Where the Gap Still Sits

Here is where the caution comes in. Reviews of the preview from consultants who ran real CoE programs on the Starter Kit have flagged the same handful of missing pieces, and they are not minor ones. The admin center, even with the new agents layered on top, still does not give you shadow IT detection in the sense the kit’s telemetry did, since it inventories what exists inside the platform rather than surfacing unsanctioned use happening around its edges. Lifecycle management, the process of formally retiring an app or flow, reassigning ownership when someone leaves the company, or tracking an asset through draft, active, and deprecated states, is not something the Insights and Action Plan agents currently model. Cross-tenant visibility, relevant to any organization running multiple tenants after an acquisition or a regional split, also is not part of what shipped in September’s preview. And the business context that made the old kit useful to non-technical stakeholders, tagging an app as customer-facing, financially regulated, or tied to a specific business unit, still has to be built and maintained separately, because the agents currently work from platform telemetry rather than organizational metadata.

None of that makes the Agentic Center of Enablement a disappointment. It genuinely automates the parts of governance that used to eat the most analyst hours: finding orphaned resources, flagging default-environment sprawl, and building a first-draft remediation plan instead of starting from a blank spreadsheet. It just is not yet the full replacement that some of the messaging around the CoE Starter Kit’s retirement implied it would be.

What This Means for Your Governance Roadmap

For an organization still weighing what to do with its Starter Kit investment, the practical move right now is not to rip anything out. The kit’s dashboards and flows will keep functioning even without updates, and the specific gaps described above, ownership workflows, lifecycle tracking, cross-tenant reporting, are exactly the pieces worth keeping running in parallel while the native agents mature. Treat the preview period as a chance to pilot the Insights and Action Plan agents in a single managed environment, compare their findings against what your existing telemetry already tells you, and use the overlap to decide which manual processes can retire first. Ownerless resource detection and default-environment cleanup are reasonable early candidates, since those are exactly the categories the Insights agent targets today.

A workable sequence looks like this. Start by enabling the agents in whichever managed environment already has the most mature governance discipline, since that gives you a clean baseline to compare against rather than a noisy one. Spend two or three weeks letting the Highlights and Insights agents run before acting on anything, so you get a real read on how their findings line up with what your team already knew versus what genuinely surprises them. Then hand a small batch of the Action Plan agent’s proposed remediations to whoever currently owns that work by hand, and measure the time saved rather than assuming it. Only after that comparison holds up across a full reporting cycle does it make sense to talk about retiring pieces of the Starter Kit stack rather than just running both in parallel.

It is also worth flagging this to whoever owns license and compliance risk in your organization, since the daily snapshot and continuous scanning behavior changes what “governance coverage” means for audit purposes, even during preview. A feature that is not yet generally available can still become the thing an auditor asks about six months from now.

We have walked several clients through exactly this kind of platform transition at Routeget Technologies, and the pattern holds regardless of which specific tool Microsoft is retiring or introducing: the risk isn’t in adopting the new capability too early, it’s in assuming a preview feature already covers ground it hasn’t gotten to yet. Run the pilot, keep the documentation for what the old system covered that the new one doesn’t, and revisit the gap list when general availability lands, since that is typically when Microsoft fills in the pieces a preview release leaves out.


#AgenticGovernance #CoEStarterKit #PowerPlatformGovernance #ShadowITRisk #EnterpriseAI #LowCodeGovernance

Copilot Studio’s Computer-Use Agents Reached GA. The Success Rate Numbers Change the Business Case.

IT director reviewing an automated workflow diagram representing a Copilot Studio computer-use agent on an office monitor

A mid-market distributor recently asked its systems integrator for a quote to build an API bridge between Dynamics 365 Finance and Supply Chain Management and a fifteen-year-old carrier portal that still runs on a browser-only interface with no exposed endpoints. The estimate came back at nine weeks and roughly $160,000, most of it spent reverse-engineering a login flow and a rate-lookup screen that changes its layout every few months. That is the exact situation Copilot Studio’s computer-use agents were built for, and as of May 2026 the capability is generally available rather than sitting in preview. For CIOs and finance leaders staring down a similar quote, the real question is not whether the technology works. It is whether it works well enough, cheaply enough, and safely enough to replace a project that would otherwise sit on the backlog for a year.

What Copilot Studio’s computer-use agents actually shipped at GA

Computer-use agents let a Copilot Studio agent operate a website or a Windows desktop application the way a person would: it takes a screenshot, reasons about what it sees, and performs a click, a keystroke, or a scroll toward a stated goal. Microsoft’s own release announcement frames the GA milestone around three changes from the preview period. Credential handling moved to a more secure model rather than embedding logins in flow definitions. Customers can now choose which underlying model drives the automation, matching cost and capability to the task instead of accepting a single default. And the agents became noticeably more resilient to interface drift, meaning a carrier portal that shuffles a form field or repositions a button is less likely to break the automation outright, which was one of the most common failure modes reported during preview.

The feature also picked up a genuinely useful architectural change: computer-use steps can now be embedded inside a broader workflow, so a single process can call an API where one exists, fall back to UI automation where it does not, and route to a human approver for anything in between. That matters more than it sounds. Most legacy integration problems are not purely API-less. They are mixed: part of the process has a clean endpoint, and the rest lives behind a login screen nobody ever modernized. Treating the whole thing as one workflow, rather than stitching together a separate RPA tool alongside your Power Automate flows, is the actual value proposition here, not the novelty of an AI agent clicking buttons.

Where the economics genuinely hold up

Computer-use agents consume Copilot Credits on a per-step, consumption-based model that behaves differently from the message-based billing most finance teams are used to budgeting for a chatbot or a Copilot assistant. A short, well-scoped task, four or five steps to submit a form and confirm a result, costs relatively little. A long, branching process with dozens of steps run at volume compounds that cost quickly, and it compounds faster than most stakeholders expect the first time they see a monthly bill next to the pilot’s success metrics. Before approving a production rollout, finance and IT should jointly model the cost of the highest-volume scenario at expected transaction counts, not just the demo scenario that sold the project internally.

The honest framing for a CFO is this: computer use is not a general substitute for API integration. It is a tool for the specific and fairly common case where an API genuinely does not exist, the vendor has no near-term plan to build one, and the manual alternative already costs real headcount hours. A carrier rate portal, a government filing site, an old third-party benefits administrator, or an internal legacy application from a prior ERP era are the kinds of targets where the math works. Where an API does exist, even a mediocre one, direct integration through Power Automate or a custom connector will almost always be cheaper per transaction than UI automation, because every additional screenshot and reasoning step adds cost that a direct API call skips entirely. Teams that reach for computer use as a default integration pattern rather than a fallback tend to discover this the expensive way, usually around the second or third month of production volume.

Abstract illustration of an AI agent cursor navigating connected software interface panels

The success-rate numbers that should set expectations

Microsoft’s own documentation is candid about current performance limits, and CIOs evaluating this for anything beyond a narrow pilot should read those numbers before committing a budget line. Web-based tasks succeed at roughly 80 percent, which sounds reasonable until you consider what a one-in-five failure rate means for a process running hundreds of times a day. Desktop application tasks succeed at closer to 35 percent, a gap wide enough that any deployment targeting a legacy Windows client, rather than a browser, should be scoped as an assisted process with human review built in from day one, not a lights-out automation. Dropdowns, date pickers, and custom UI widgets remain a known weak point, along with the tendency for an agent to loop when the screen state does not match what it expected.

None of this makes the technology unusable. It makes it a tool that needs the same production discipline any automation project requires: define what “success” means precisely, measure it against a real baseline rather than a demo, and build an escalation path for the failures you know are coming rather than treating them as edge cases to handle later. Microsoft’s own guidance recommends exactly this, pointing customers toward least-privilege service accounts, restricted execution environments, and human-in-the-loop review for lower-confidence steps as standard practice rather than optional hardening.

Governance decisions to make before the first production run

Three controls matter most for a finance or IT leader signing off on this. First, audit logging: computer-use sessions can send activity to Microsoft Purview under a dedicated operation type, independent of the standard Dataverse logs the agent keeps by default, and that Purview trail is what most compliance teams will want to see before approving a process that touches financial data or customer information. Second, session visibility: every run generates a step-by-step activity map with screenshots, timestamps, and a list of exactly which credentials and which sites or applications were accessed, which gives an auditor something concrete to review rather than a black box. Third, and easy to overlook, the allow-list that restricts which sites an agent can act on does not fully prevent navigation to sites outside that list, only actions on non-allow-listed pages. Organizations with strict data-boundary requirements should layer network-level controls, such as browser policies through Microsoft Intune, on top of the Copilot Studio allow-list rather than treating the allow-list as a complete boundary on its own.

Administrators who decide the risk profile is not yet acceptable for a given environment can disable computer use entirely at the environment level, or disable the hosted browser specifically at the tenant level, through the Power Platform admin center. That toggle is worth knowing about even for organizations planning to adopt the feature, since it gives a clean way to pilot in one environment while keeping it off everywhere else until the governance model is proven.

What this means for the next integration decision

The distributor with the fifteen-year-old carrier portal does not need to choose between a $160,000 custom build and doing nothing. A scoped computer-use pilot against that single portal, with success measured honestly against the current 80 percent web success rate and a human reviewer catching the rest, is a legitimate middle option that did not exist eighteen months ago. The mistake would be extending that same logic to every integration gap on the roadmap without first checking whether each one is genuinely API-less or just under-prioritized. For organizations already running Dynamics 365 Finance and Supply Chain Management or Business Central alongside a Power Platform footprint, the practical next step is an inventory: which manual, screen-based processes actually lack an API path, which have one nobody built yet, and which are high-enough volume that the per-step credit cost changes the calculation entirely. Routeget Technologies has been walking clients through exactly that kind of inventory as computer-use agents move from a curiosity into a line item finance actually has to approve, and the pattern holds across industries: the technology is real, the cost model rewards precision over enthusiasm, and the governance controls exist, but only for the teams who turn them on before the first production run rather than after an incident.


#CopilotStudio #ComputerUseAgents #AgenticAI #RPAGovernance #EnterpriseAutomation #DynamicsFinanceOps

Dataverse’s Recycle Bin Restore Reached GA. Your Business Logic Isn’t Included.

Solution architect reviewing a data recovery and system administration dashboard on a large monitor in a modern office

A bulk delete job runs at 2 a.m. against the wrong view filter. By the time anyone in operations notices, eleven thousand account records are gone, and the only recovery plan anyone can point to is a nightly export sitting in a storage account nobody has tested restoring from in two years. That scenario is why Microsoft spent nearly two years moving deleted record recovery in Dataverse from public preview to general availability in late April 2026. For solution architects and Dynamics 365 technical teams, a native Dataverse recycle bin restore capability closes a gap that has existed since the platform’s earliest days: there was never a supported, in-product way to undo a delete. Now there is one. The problem is that plenty of teams will configure it, assume it behaves like the Recycle Bin on a Windows desktop, and discover the gap between what it restores and what they actually needed restored only during a real incident.

The feature’s actual behavior is narrower and more procedural than its name suggests, and the places where it falls short map directly onto the customizations most F&O, Business Central, and Customer Engagement implementations already carry.

Solution architect reviewing a data recovery and system administration dashboard on a large monitor in a modern office

What the Dataverse Recycle Bin Restore Actually Covers

The capability itself is straightforward to enable. From the Power Platform admin center, under an environment’s Settings, Product, Features, there is a “Keep deleted Dataverse records” toggle with a retention window configurable from one to thirty days. Turn it on, and Dataverse begins tracking rows that get deleted so a System Administrator can view them under Data management, Deleted Records, and issue a Restore request against the ones worth recovering. The setting lives at the environment level, not the tenant level, so a sandbox and its corresponding production environment can carry entirely different retention windows, which matters if you’re testing destructive changes in a lower environment that doesn’t need the same thirty-day buffer production does.

The detail that trips up almost every team on first contact is that the feature is not retroactive. Only rows deleted after the setting is enabled and has finished propagating, which the documentation notes can take up to thirty minutes, become recoverable. A record deleted an hour before someone flips the toggle is gone exactly as it always was. If you’re reading this and haven’t enabled retention on a production environment yet, that thirty-minute propagation window is the argument for doing it now rather than after the incident that makes you wish you had.

Restoration happens through the Restore message, available in the SDK for both early-bound and late-bound entities, or as an action call through the Web API. The request takes a full target record rather than a bare reference, so you can override specific column values as part of the restore rather than being forced to bring back an exact snapshot. Deleted rows are also queryable directly: a FetchXml query with datasource='bin', or a QueryExpression with its DataSource property set the same way, returns rows sitting in the bin rather than the live table, which is enough to build a lightweight internal tool that surfaces what’s recoverable without routing every check through the admin UI.

The Tables That Never Show Up in the Bin

The exclusion list is where the feature’s real limits show up, and it is long enough that assuming universal coverage is a mistake worth catching before an incident rather than during one. Virtual tables are excluded entirely: if a record surfaced from an external system through a virtual table disappears, there was never anything in the bin to restore, since that row was never really “deleted” from Dataverse’s perspective so much as it stopped resolving. Elastic tables, increasingly common for high-volume telemetry, IoT-style logging, or activity history where standard table row limits become a constraint, are excluded as well. So are solution component tables, and so is any table that has grown past six hundred attributes, a ceiling that heavily customized standard entities in mature Dynamics 365 implementations can approach faster than teams expect.

Beyond those structural exclusions, Microsoft maintains a list of roughly two hundred and fifty system tables that don’t support deleted-record retention regardless of configuration: async operation records, background operation records, bulk delete failure logs, Power Automate flow run and flow log tables, solution and solution component tables, plugin assembly tables, and the full family of msdyn_ and mspp_ prefixed tables tied to first-party Dynamics 365 apps and Power Pages. None of that is arbitrary; those tables tend to be high-volume, system-managed, or tightly coupled to processes where a stale restored row could reintroduce more problems than it solves. But it does mean that if your disaster recovery narrative for a Power Pages portal assumes the recycle bin has you covered, it’s worth checking the actual exclusion list against your table inventory before that assumption ends up in a postmortem.

Abstract illustration of glowing data records being restored from an archive bin into an active data grid

Cascade Deletes Restore in Order. Custom Logic Doesn’t.

Where this feature gets genuinely interesting for anyone who has built out relationship cascading behavior is how it treats dependent records. Rows removed because of a configured cascade delete relationship, the kind set up through standard relationship behavior rather than custom code, are restorable, but not independently. You have to restore the parent record first; attempting to restore a cascaded child before its parent throws RefCannotBeRestoredRecycleBinNotFound, and the platform expects you to work back up the dependency chain in the correct order rather than picking records to restore arbitrarily.

Custom logic is a different story, and it’s the part of the feature architects need to internalize before promising anyone a one-click recovery story. If a plugin or a Power Automate flow deletes related records as a side effect of deleting the primary record, none of that custom-triggered deletion is automatically reversed by a Restore call. The recycle bin captures what Dataverse’s own relationship engine did, not what your business logic did on top of it. That means any implementation with plugins that clean up child records, cancel related cases, or cascade status changes on delete needs a mirrored restore path: a plugin registered against the Restore message, in the PostOperation stage specifically since the restored record isn’t available yet during PreOperation, that re-creates or re-links whatever the delete-time logic tore down. Skip this step and a team restores the parent record, then discovers days later that none of the related activity history, case associations, or downstream integration records came back with it, because nothing ever told them to.

A handful of other failure modes are worth knowing before you hit them live. Restoring a record whose ID has since been reused by a new record throws DuplicateExceptionRestoreRecycleBin, since Dataverse preserves the original primary key on restore rather than generating a new one. If a deleted record referenced an option set value that has since been removed from the choice definition, the restore fails with PicklistValueOutOfRangeRecycleBin. Both are recoverable situations, but only if whoever is running the recovery understands what the error is actually telling them instead of treating it as a generic restore failure and giving up.

Building the Restore Path for Real Incidents

None of this argues against enabling the feature. It argues for treating it as infrastructure that needs its own runbook rather than a switch you flip and forget. A reasonable rollout enables retention on every production environment now, sets the window to match your actual incident response SLA rather than defaulting to the maximum thirty days without weighing the storage tradeoff, and documents exactly which tables in your specific implementation fall outside the coverage: your virtual tables, any elastic tables you’ve adopted, and anything near the six-hundred-attribute ceiling.

The more valuable investment is building and testing the restore path before you need it: registering the mirrored Restore-stage plugin logic anywhere delete-time custom logic exists, confirming cascade restore order against your actual relationship map rather than assuming it will be intuitive mid-incident, and running a deliberate test delete-and-restore cycle in a sandbox so the first time anyone executes this procedure isn’t during a live outage. It’s also worth being explicit internally that this is record-level recovery, not a replacement for environment-level point-in-time restore, which remains the right tool for a broader corruption event or a bad deployment rather than a scoped accidental deletion. Teams that conflate the two end up with a false sense of coverage in exactly the scenario where they can least afford one.

The recycle bin is a genuinely useful addition, and it’s the kind of foundational reliability work that doesn’t generate much attention next to agent and Copilot announcements but matters more day to day for the teams operating these environments. Routeget has walked several clients through exactly this kind of gap analysis between what a new platform capability claims to cover and what a specific implementation’s customizations actually need, and the pattern holds here too: the feature is only as good as the runbook built around it. Treat this GA date as the trigger to write that runbook, not as the moment the problem quietly solves itself.


#Dataverse #DataverseRecycleBin #DataRecovery #PowerPlatformGovernance #ITDisasterRecovery #CloudArchitecture

Power Pages Client APIs Replace jQuery Guesswork With a Real Object Model

Developer working at a dual-monitor desk with code editors open, illustrating Power Pages Client API development

A Power Pages developer spends an afternoon chasing a bug that only appears for some site visitors. A dropdown built on the Select2 jQuery plugin renders correctly for administrators previewing the site, but silently fails to initialize for anonymous visitors. After an hour of console logging, the cause turns out to be timing: jQuery itself loads from an auto-generated bundle file buried deep in the page, its filename changes with every publish, and the plugin code that depends on it sometimes runs before jQuery is actually available. Nothing in the markup changed. Nothing in the deployment changed. The site just behaves differently depending on exactly when the browser finishes fetching a script nobody on the team explicitly referenced.

This is the kind of problem that has quietly defined custom scripting on Power Pages for years. Developers have never had a real contract with the platform’s client-side behavior. They have had a page that eventually finishes loading a set of libraries in an order that Microsoft controls and can change, and a convention of dropping jQuery-dependent code into a web template and hoping the sequencing holds. Power Pages Client APIs, introduced in public preview in November 2025 and slated for general availability in August 2026 according to Microsoft’s own release plan, are the first attempt to replace that convention with something closer to an actual API surface. For technical teams still writing DOM-selector scripts and crossing their fingers, this changes the calculus on how much custom logic belongs in the browser at all.

What Power Pages Client APIs Actually Provide

The Client APIs expose a single global object, conventionally named $pages, that becomes available once the page signals readiness through Microsoft.Dynamic365.Portal.onPagesClientApiReady(). That function can be called with a callback for teams that need broad browser compatibility, or awaited directly in modern code:

let $pages = await Microsoft.Dynamic365.Portal.onPagesClientApiReady();
let form = $pages.currentPage.forms.getFormById('contact_form');

Once initialized, the object model covers most of what custom scripting on Power Pages has traditionally been used for. Forms expose their controls, tabs, and sections through typed methods rather than CSS selectors, so a script that used to search the DOM for an input with a fragile, auto-generated ID can instead call form.controls[].getValue() and setValue() directly against a named control. Multistep forms get their own navigation methods, hasNextStep(), goToNextStep(), and their counterparts, which replace the button-click interception that multistep customizations previously required. Lists expose visibility controls and a flag indicating whether a given list is rendering in the newer “modern” mode or the legacy one, which matters because the two have historically needed separate customization approaches.

The more consequential addition is $pages.webAPI, which gives scripts a direct, promise-based path to Dataverse through createRecord, retrieveRecord, and retrieveMultipleRecords, each accepting standard OData query options. A developer building a custom submission flow, or pulling related records into a page without a full form postback, no longer needs to hand-roll authenticated fetch calls against the portal’s web API endpoints. There is also a narrower but useful addition in $pages.agent, which lets a page send activities to and receive responses from a Copilot Studio agent embedded in the site, a capability that previously required custom iframe and messaging work to approximate.

Abstract 3D illustration of a structured network of connected data blocks representing an API object model

Where This Actually Sits: Preview Language Versus a GA Date

Here is where technical teams evaluating this feature should slow down rather than take Microsoft’s release plan at face value. The 2025 release wave 2 plan lists August 2026 as the general availability date, and that date has now passed. But as of this writing, Microsoft’s own client API reference documentation still describes the feature as being in preview, states that production use is not recommended until general availability, and points to supplemental terms of use that govern preview functionality. That is not a contradiction so much as a reminder that release plan dates are commitments, not guarantees, and that documentation updates do not always land the same week a feature’s status changes internally. The practical implication is straightforward: before writing a client API dependency into anything customer-facing, check the actual status shown in your own tenant’s Power Pages management app rather than assuming a date on a release plan page reflects where things stand today. If a site is public-facing and the API is still governed by preview terms, that changes the support and SLA conversation with whoever owns the relationship with the business stakeholder, not just the engineering timeline.

This is also a case where “automatically enabled for all users” cuts both ways. Microsoft’s release documentation states the feature is enabled automatically rather than requiring an administrator or maker to turn it on, which means client API availability is not something a governance team can gate the way they might gate a new connector or an AI Builder model. Any site already running on a current Power Pages runtime has access to it now, whether or not anyone on the team has deliberately adopted it yet.

What Actually Changes in Practice

The comparison worth making is not “old JavaScript versus new JavaScript.” It’s the difference between code that depends on the current shape of rendered markup and code that depends on a documented interface. A script that finds a form control by walking the DOM breaks the moment Power Pages changes how it renders that control, a form layout is redesigned, or a plugin update alters class names. A script that calls form.controls[0].getName() and setValue() against the client API object model keeps working across those changes because the API, not the markup, is the contract. That is the same argument that pushed the broader industry away from jQuery over the last decade, and it is arriving on Power Pages roughly ten years after most greenfield web development moved on from DOM-selector-driven scripting as a default.

For teams migrating existing customizations, the realistic approach is incremental rather than wholesale. Forms and multistep wizards with heavy custom validation logic are usually the highest-value targets, since they are where fragile selector-based code causes the most support tickets. A reasonable sequence is to rebuild form-level show/hide and validation logic against the client API first, since that logic tends to be self-contained within a single web template. Web API calls that currently go through hand-authenticated fetch requests to the portal’s REST endpoints are the next candidate, since $pages.webAPI handles the authentication context automatically and the OData query syntax is nearly identical to what most Dataverse developers already know. List customizations and any Copilot Studio agent embedding are reasonable to defer until GA status is unambiguous, given that both are newer additions to the API surface with less production mileage behind them.

One performance detail is easy to miss and worth calling out directly to anyone building against $pages.webAPI: every retrieve call should specify a $select clause. Omitting it returns every column on the entity, which on a wide table like Contact or a custom entity with dozens of fields adds real, measurable latency to what should be a lightweight in-page data fetch. Teams coming from Dataverse plugin or Power Automate development already have this habit; teams whose Power Pages experience is mostly front-end JavaScript may not, since the old web API patterns didn’t make the cost as visible.

The Practical Takeaway

Client APIs won’t retire jQuery from Power Pages overnight, and teams shouldn’t treat the GA date on a release plan page as a green light without checking their own tenant first. But for any organization that has accumulated a pile of DOM-selector scripts held together by convention and hope, this is the first credible alternative Microsoft has shipped, and it is worth prioritizing a pilot on one troublesome form rather than waiting for a big-bang rewrite. Routeget Technologies has walked several clients through exactly this kind of incremental portal modernization, and the pattern that works is consistent: pick the customization causing the most support tickets, rebuild it against the documented API, and let the results make the case for the next one.


#PowerPages #PowerPagesClientAPI #LowCodeDevelopment #PortalCustomization #PowerPlatform #DynamicsDeveloper