Preventing Unintended Blocks: Implementing Data Loss Prevention Policies Without Paralyzing Your Power Platform

Data Loss Prevention governance dashboard with security controls and policy checkpoints

Data Loss Prevention (DLP) policies in Power Platform sit at an uncomfortable intersection: they’re necessary for governance, but they’re easy to misconfigure so that your first draft breaks legitimate business workflows. Most organizations learn this the hard way, after a DLP policy ships and silently blocks connector calls in production automations. A finance team’s approval workflow mysteriously stops routing to Slack. A sales process can’t write leads to an external data warehouse. Nobody notices until something breaks on a Tuesday afternoon.

The challenge is structural. DLP policies operate at the connector level, not at the individual action level, so a single overly restrictive rule can disable entire classes of integrations across your tenant. The organizations that avoid catastrophic blocks are not the ones that build the most restrictive policies first. They’re the ones that start with a clear map of what data actually needs protection, then craft policies targeting that specific risk rather than trying to lock down anything that looks suspicious.


Understanding DLP in Practice

A Data Loss Prevention policy defines which connectors can share data with each other. You classify connectors as Restricted Data (like SQL Server, Dataverse, SharePoint), Limited Business Use (like Slack, Teams), or General. The policy enforces rules like “data from Restricted connectors cannot flow to Limited Business Use connectors.”

The critical point most organizations miss: these classifications are tenant-wide and apply to all environments unless you create specific overrides. A policy blocking Slack from receiving SQL Server data blocks it everywhere, for everyone. That sounds straightforward on paper, but most organizations have at least a dozen legitimate integrations that move data between categories that look “risky” in isolation. A financial reporting automation sending a Slack summary of daily sales. A customer service workflow pulling account data from Dataverse to an external ticketing system. A sales tool reading opportunities from Dynamics 365 for pipeline visibility.

None of these are data leaks. All would be blocked by an overly broad DLP policy.


Common DLP Mistakes

The first mistake is auditing too aggressively. Many organizations activate DLP in Audit mode to collect data on actual usage patterns without blocking anything. The theory is sound. The practice is crushing volumes of alerts, most false positives or unavoidable business integrations. Teams see 10,000 violations in a month with no systematic way to separate real concerns from critical workflows. They either give up on enforcement or ship a policy based on highest-volume alerts, which usually fails.

The second mistake is confusing audit alerts with actual risks. Not every data flow represents a security problem. A sales team’s external deal tracker is not a breach waiting to happen just because it reads from Dataverse. An approval workflow sending Teams notifications is not exposing proprietary information just because Teams is classified as Limited Business Use. Organizations conflate appearance of complexity with presence of risk, then tighten policies to zero out complexity. This transfers risk to shadow IT. People still move the data they need. If official integrations are blocked, they’ll build their own via Excel and manual uploads.

The third mistake is shipping policies without environment-level testing. DLP policies are tenant-scoped by default, so a broad policy breaks production systems across business units before validation in staging. The correct pattern is testing in specific environments, monitoring real workflow impact, then rolling out to the entire tenant. Executives want company-wide governance immediately, but breaking multiple workflows costs more than a phased rollout.


Building a Working DLP Policy
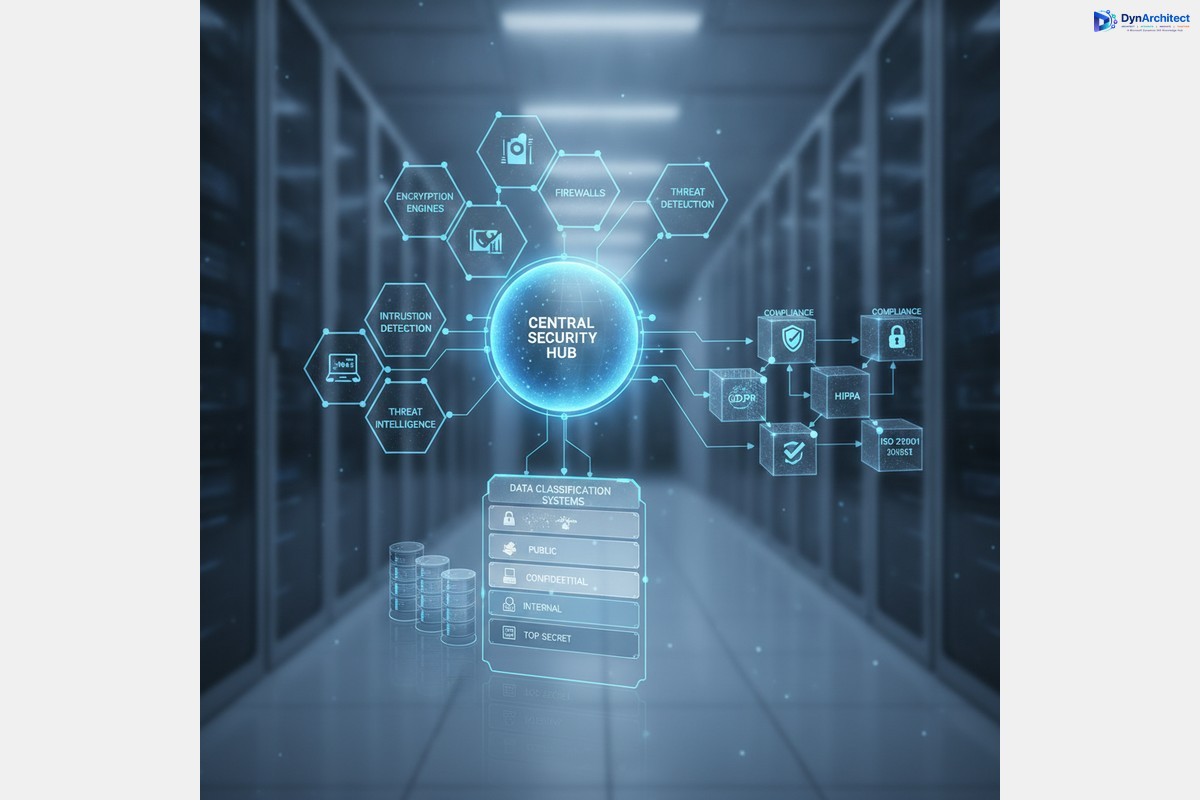
Enterprise security infrastructure showing data governance and compliance controls

Start with an actual inventory of your integrations, not a theoretical one. Go through your most business-critical Power Automate flows (approval automations, financial data movements, sales processes) and document which connectors they use and what data moves between them. Don’t ask business owners what they think is critical. Inspect the flows. You’ll find integrations that look risky but are actually essential. A manufacturing team’s work order system pulling from Dataverse and posting to an external MES system. A finance team’s journal import flow reading CSV from a web service and loading into Dynamics 365. These would fail under restrictive DLP, and stakeholders will fight when they break.

Second, classify connectors based on actual data sensitivity, not theoretical risk. Dataverse and SQL Server carry genuinely sensitive data and warrant strong controls. SharePoint carries mixed content and needs nuance. Slack and Teams are low-sensitivity by themselves but become sensitive only when receiving restricted data. The mistake is classifying Slack as Limited Business Use, then treating any flow from SQL Server to Slack as violation. That blocks the finance team’s daily sales summary, sales team’s pipeline snapshot, and customer service team’s alert automation. These aren’t leaks, they’re operations.

A better approach is classifying Slack as General for normal use, then building specific policy exceptions for flows that legitimately move summarized data from restricted systems. This requires identifying those flows in advance.

Third, build your initial policy at the environment level, not tenant-wide. Create a restrictive policy for sandbox and development environments. Test your business-critical flows in staging with your proposed tenant-level DLP policy before shipping. You will find your policy breaks something unexpected. Refine the policy, create flow-specific exceptions, or move that flow to a dedicated environment with looser rules. All beat discovering your policy broke production automations.

Fourth, document every policy exception and why. When carving out exceptions for flows moving data between connector categories, write down the business reason, data classification, and approval stakeholder. This prevents exceptions from becoming a free-for-all over time. Each exception should have a clear owner and documented security rationale. Quarterly audits will make sense of your policy instead of inheriting blackbox carve-outs.


Monitoring and Maintenance

Finally, review your DLP policy every quarter. Power Platform gets new connectors regularly. Integration patterns change as teams adopt new tools. A policy from Q1 might be outdated by Q3. Quarterly review catches new patterns, adjusts classifications as you learn more about actual data flow, and retires unnecessary exceptions. Organizations that ship a policy and never touch it end up either too restrictive (silently blocking workflows) or too permissive (defeating the point).

Set up Power BI reporting against Power Platform audit logs. Create dashboards showing DLP violations over time by connector pair, environment, and flow. Most organizations find 80 percent of violations come from a handful of flows or connector combinations. For each, decide: Is this legitimate and needs exception? Is it shadow IT to replace? Or is it misconfigured? Document the decision.

Engage with solution architects and flow owners before violations happen. After quarterly reviews, share audit logs with teams owning business-critical integrations. This conversation prevents surprises and keeps teams aligned rather than feeling DLP is something done to them.


DLP policies are not set-and-forget security controls. They’re part of ongoing governance between your security team, platform team, and business stakeholders. Organizations implementing DLP successfully are not enforcing maximum-security policies. They start with a clear picture of what they’re protecting, build policies addressing that specific risk, and refine them as their integration landscape evolves. That approach is slower than dropping maximum-security on the entire tenant, but it’s the only approach that works in organizations where Power Platform ties directly to business operations.


#PowerPlatformGovernance #DataLossPrevention #DLPPolicy #PowerAutomateIntegration #MicrosoftCloudSecurity #EnterpriseGovernance

Dynamics 365 Omnichannel for Customer Service: Real Service Management Starts After Configuration Ends

Omnichannel Customer Service Featured

Omnichannel for Customer Service in Dynamics 365 promises a single, unified workspace where agents handle customer interactions from email, chat, social media, and phone without context switching. The promise is compelling: less time hunting between systems, faster resolution, better customer experience.

Omnichannel customer service dashboard in Dynamics 365

The reality is more complicated. Configuration is one thing. Operating omnichannel at scale—where fifty agents handle thousands of interactions daily across five channels—is another. Many organizations configure Omnichannel correctly in a test environment, deploy to production, and then discover that the system they built doesn’t match how work actually flows in a busy contact center.

Omnichannel’s Foundational Premise: Unified Workload Management

Customer service routing and queue management system

Omnichannel organizes customer interactions into a queue-based model. Every incoming chat, email, email-to-case conversation, social message, and phone call flows into a work item. That work item contains the customer context, conversation history, and metadata. Agents see a unified interface and pick up work items in order of priority, assignment rules, or routing logic.

The configuration itself is straightforward: define queues by channel or by business function, set up routing rules based on agent skills or availability, configure notification behavior, define service-level targets (SLA), and establish escalation paths. Most organizations complete this within a few weeks.

But here’s where the gap appears: once omnichannel starts processing real customer interactions at real volume, several operational realities emerge that no configuration screen fully prepares you for.

Issue One: Routing Logic Doesn’t Always Match Channel Behavior

Omnichannel supports skill-based routing, where work items are assigned to agents with matching skills. In theory, a chat about billing goes to agents tagged with “billing-expert,” and a social-media complaint about shipping goes to “escalations.”

In practice, skill tags accumulate overtime. Agents get tagged with more skills than they actually have capacity for, either because they once handled a specialized case and never got the tag removed, or because managers add skills to broaden an agent’s available work. The routing logic then becomes unreliable. A chat that should go to the most experienced agent instead goes to whoever technically has the skill but happens to be first in the queue.

Solution architects often respond by tightening the skill-assignment process and educating managers about the cost of skill inflation. But the underlying issue is that most organizations lack a systematic way to audit skill usage or enforce skill standards once omnichannel is live.

Issue Two: Phone Channel Integration Isn’t Truly Integrated

Omnichannel’s phone integration exists, but many organizations find it works best when phone calls are treated as a special case, not as peers to chat and email within the same routing logic.

Here’s why: phone interactions move at voice speed. An agent picks up a call, and the customer is already speaking. There’s no 30-second window to pull up customer records, like there is with an incoming email or chat. Phone calls also cannot wait in a queue the way digital channels can; the interaction starts immediately or the customer hangs up and calls a competitor.

Many organizations end up running phone as a parallel system within Omnichannel rather than truly integrated. Phone calls route to a dedicated phone team with their own skills, queues, and SLAs, and only occasionally transfer into the main omnichannel workspace for escalations. This defeats much of the “single workspace” promise, but it’s operationally simpler and more stable than trying to force voice into the same queue-driven model.

Issue Three: SLA Compliance Becomes Unpredictable at Scale

Omnichannel supports Service Level Agreements (SLAs) that measure, for example, “first response within 2 minutes for chat” or “resolution within 4 hours for email.” Configuration is simple: define the metric, set the target time, and choose what happens when it’s breached (notification, escalation, priority boost).

But at volume, SLA behavior becomes hard to predict. If your agents are handling 300 chat interactions per day and you have a service-level target of “first response within 2 minutes,” that means approximately 99% of your agents need to be available and responding to new chats within that 2-minute window. Missing that threshold by a few percentage points means dozens of chats violate the SLA daily.

Organizations often respond by tightening thresholds—maybe “first response within 1 minute” for very high-urgency chats—but this can paradoxically worsen agent satisfaction and error rates, because agents are constantly interrupted and switching context between work items.

The operational reality is that SLA targets need to account for actual agent capacity, not theoretical capacity. A team of 50 agents cannot sustainably respond to every chat within 2 minutes if they’re also handling email and other channels. The configuration screens don’t flag this contradiction; it surfaces only in production data.

Issue Four: Routing Rules Create Silent Failures

Omnichannel allows conditional routing rules. For example, “if the customer’s account is flagged for fraud review, route to the fraud team” or “if sentiment analysis detects high emotion, escalate to a supervisor.” These rules are powerful when they work.

They often don’t, silently. A rule might fail to fire because a prerequisite data field is empty (the customer record has no sentiment score yet), or because the rule’s condition was written too narrowly (it looks for exactly “fraud” but the account is flagged as “review-fraud-pending”). When a routing rule fails to fire, the work item doesn’t escalate and doesn’t get reassigned; it just continues down the default path.

The agent never sees a warning. The system doesn’t flag a rule failure. The work item eventually gets handled, maybe late, maybe incorrectly. Discovering these failures requires audit logs and data queries, not standard Omnichannel reporting.

Issue Five: Historical Context Fades Faster Than You’d Expect

One of Omnichannel’s core selling points is customer context. Every conversation thread, every case history, every previous interaction is visible in the unified workspace. An agent can see that a customer has contacted support three times this month about the same issue.

But in a high-volume contact center, historical context can degrade quickly. If a customer’s issue remains open for 72 hours without resolution, the record might accumulate 15 different interactions, notes, and case reassignments. A new agent picking up that conversation needs to scroll through all of that history to understand where the issue stands.

Many organizations respond by enforcing a maximum context retention policy—say, “only show interactions from the last 48 hours”—but this can mean losing important information. A customer might say, “This is the same issue I reported last week,” but the agent cannot see that previous week’s conversation because it’s been archived.

Operational Frameworks That Actually Work

Organizations that run Omnichannel successfully tend to implement several practices that don’t come out of the box:

**Skill Audit Cycles**: Quarterly (at minimum) audits of agent skills, removing skills that are no longer relevant and tightening the rules for when a skill can be assigned. This is a governance task, not a configuration task, and it requires someone’s time every quarter.

**Phone as a Managed Exception**: Accept that phone calls don’t fit the same queue model as digital channels. Establish phone as a dedicated workstream with its own routing, escalation, and SLA targets. This isn’t a failure of Omnichannel; it’s an acknowledgment of how voice works.

**SLA Targets Based on Capacity, Not Theory**: Before setting an SLA target, calculate what it actually requires. If you have 50 agents, each handling an average of 5 concurrent chat interactions, with 40 seconds average handling time, then you can sustain a 2-minute first-response target for roughly 70% of inbound chats. Set your SLA to that realistic threshold, not to an aspirational one.

**Routing Rule Validation**: Implement a monthly process to validate that routing rules are firing as expected. This means querying Omnichannel analytics to confirm that “fraud-flagged” accounts are actually reaching the fraud queue, and that sentiment-escalation rules are working. Fix silent failures as you find them.

**Context Management Policy**: Define what counts as “relevant context” for agents. Decide how far back conversation history should display (48 hours? 30 days?). Document which data fields agents need to see immediately versus which can be found in a related case. Enforce this consistently so agents know where to find what they need.

The Operating Model Matters More Than the Configuration

Many organizations approach Omnichannel as a technical implementation problem: install it, configure it, test it, go live. In reality, Omnichannel’s success depends far more on the operating model around it.

A mature Omnichannel deployment has a defined governance structure, regular audits of routing and skill assignments, SLA targets that reflect real capacity, and someone accountable for keeping it all working. Configuration is the easy part. Operations is where most organizations struggle.

If your organization is considering Omnichannel, or if you’re already running it but seeing unpredictable behavior, the first question isn’t “Is our configuration wrong?” It’s “Do we have the operational discipline to keep Omnichannel working correctly at volume?” The answer determines whether Omnichannel becomes a competitive advantage or a source of recurring complaints.

Business Central Virtual Tables Eliminate the ETL Job Between BC and Dataverse. They Also Eliminate Half Your Filter Options.

Solution architect reviewing a real-time data integration visualization between enterprise systems

A solution architect scoping a Dynamics 365 Sales rollout for a distribution client recently asked a straightforward question: does the sales team need to see live Business Central order and inventory data inside their CRM records, or is a nightly sync job good enough? The honest answer took longer than it should have, because Business Central virtual tables, the feature Microsoft built specifically to answer this question, solve it only for a narrower set of scenarios than the AppSource listing and most walkthroughs suggest. The core mechanism works exactly as advertised. Where it falls short is rarely covered in the getting-started guides, and that gap is exactly where a scoping conversation needs to happen before anyone commits to an architecture.

Virtual tables have been positioned, correctly in most cases, as the end of a certain kind of integration project: the one where someone builds a scheduled job to copy Business Central records into Dataverse so Power Apps and Dynamics 365 Sales can read them. That job needs error handling, a schema that drifts every time BC gets a service update, and someone on call when the sync silently stops. Virtual tables remove that job entirely for read-heavy scenarios, just not for every scenario, and the difference is worth planning around before it’s discovered mid-build.

How Business Central Virtual Tables Actually Work

The Business Central Virtual Table plugin, published on AppSource, gives Dataverse a way to read and write Business Central records without copying that data into Dataverse storage. Under the hood, it consumes the Business Central API (v2.0), turns each endpoint’s response properties into virtual table columns, and maps the API’s own relationships into table relations that Power Apps and Power Automate can traverse like any native table. None of that translation happens on a schedule. Every query against a Business Central virtual table becomes a live OData call back to the Business Central tenant the moment a user opens a form, loads a subgrid, or a flow condition evaluates.

That real-time behavior is the actual selling point, and it’s a legitimate one. A Dynamics 365 Sales rep looking at an account record sees the customer’s current balance and open orders as they exist in Business Central right now, not as of last night’s sync window. There’s no data duplication to reconcile, no field mapping table to maintain as BC’s schema evolves, and no separate storage cost in Dataverse for records that already live somewhere else.

What Setup Actually Involves

Getting virtual tables running is a Power Platform admin task more than a developer task, which is worth knowing before anyone estimates the work. The solution installs from AppSource into a target Power Platform environment. Inside Business Central, an administrator enables the corresponding Microsoft Entra application, listed on BC’s own Entra applications page as the option for virtual tables. In Dataverse, the Business Central Virtual Data Source Configuration table needs the target BC environment name and a default company, since every request has to resolve to a specific company context.

Microsoft ships this as a set of managed solutions rather than one package: a company reference table every request depends on, the core plugin support, a catalog of tables available from the connected BC environment, and the generated virtual table definitions themselves. Because that catalog reflects the full breadth of Business Central’s OData surface, tables aren’t visible in Power Apps by default. An admin has to open the Business Central Configuration app and mark each table an app will use, a sensible governance control once you know it’s coming, and a confusing missing-table problem the first time you don’t.

Developer workstation displaying live data flow dashboards representing database integration

The Tenant Requirement That Ends Some Projects Before They Start

The detail worth checking on the first scoping call, not discovering three weeks into a build, is that the Business Central environment and the Dataverse environment must sit in the same Microsoft Entra tenant. For an organization that has run its Dynamics footprint under one tenant from the start, this is a non-issue. It becomes a real blocker for companies that grew through acquisition and still operate a separate Business Central tenant for a subsidiary, and it comes up constantly on engagements where a client’s CRM and ERP environments were provisioned years apart, sometimes by different vendors, under different tenants.

When that’s the situation, virtual tables aren’t an option regardless of how well everything else fits, and the project falls back to a conventional integration built on Power Automate flows against the Business Central API, or a dedicated integration platform between the two systems. Confirming tenant alignment costs a few minutes of checking admin center settings. Discovering the mismatch after a Power Apps screen is already designed around virtual tables costs a redesign.

Where the Filtering Restrictions Actually Bite

Because every virtual table query is a live OData call, the filtering grammar available to a Dataverse view or an advanced find is exactly as expressive as OData’s filter syntax, and no more. Predicates like does not equal, does not contain, does not begin with, and does not end with aren’t available. A view can’t combine AND and OR groups across different columns the way a native Dataverse table allows, and filtering on related tables or calculated fields isn’t supported either, nor are charts, attachments, images, or any BLOB-backed multiline text field built on a virtual table.

None of that shows up in a basic demo, which is the actual problem. A subgrid or gallery built against a virtual table for a first pass usually works, because the first pass rarely tests anything more demanding than “show me the open orders.” The gap surfaces once a real user asks for something like “show open sales orders where the requested ship date isn’t blank and the customer isn’t on credit hold,” a query needing a does-not-equal check on one column joined with an AND against a second. A native Dataverse table handles that without anyone thinking twice. A virtual table view can’t express it, and the fix ends up being either a purpose-built custom API on the Business Central side shaped for that exact query, or pushing the filtering logic into a Power Automate flow or a canvas app formula instead of the view. Either workaround is manageable, but only if someone anticipated it, and the tutorials rarely mention it exists.

Synthetic Relationships Connect the Models, But Only One Way

Virtual tables can also link to native Dataverse tables through what Microsoft calls synthetic relationships, letting a record like a Dataverse Account display related Business Central sales orders in a subgrid without custom plugin code. Building one means creating a foreign key on the native table first, then defining the relationship in the Business Central Configuration app’s Table Relations screen, mapping the native table’s key columns to the matching virtual table columns.

The relationship, once created, isn’t editable. Changing which columns participate means deleting it and rebuilding from scratch, and refreshing the underlying virtual table’s metadata while a relationship depends on it tends to throw errors rather than update quietly. The practical implication is to stabilize the Business Central side of the schema first: it’s far cheaper to adjust a Dataverse foreign key than to reconstruct several relationship mappings after a field gets renamed on the BC side. It’s also worth knowing upfront that relationships between two virtual tables aren’t supported at all, only between a native table and a virtual table, so an architecture chaining two Business Central entities purely through Dataverse relationships needs a custom API instead.

When Virtual Tables Are the Right Call

Virtual tables fit read-heavy scenarios well: a Power App or Dynamics 365 Sales form that needs current item availability, order status, or account balance without anyone owning a sync pipeline, where the filtering the business needs stays inside basic equality and straightforward AND logic. They’re a poor fit for anything involving attachments or images tied to BC records, analytics that need to chart or aggregate BC data directly, filter logic needing negation or mixed AND/OR groups, and any architecture spanning two Entra tenants.

The habit worth building into every Business Central to Dataverse integration scope is prototyping the specific filter and subgrid scenarios the business will actually use, not a generic list view, before the architecture is locked in. Almost every gap covered here only shows up once a real filter requirement meets OData’s grammar, and that’s cheap to test in the first week and expensive to discover after Power Apps screens are already built around the wrong assumption. Teams we’ve helped scope this kind of integration get the most value out of virtual tables when the tenant check and a short filter-requirements workshop are treated as the first two deliverables, not something left until a screen doesn’t do what the demo implied it would.

Virtual tables genuinely remove a maintenance burden that used to be permanent: the sync job nobody wanted to own, the schema drift nobody wanted to chase down. What they don’t remove is the need to know, before the architecture is set, exactly which filters, which tenant, and which record types the integration actually has to support.


#BusinessCentral #DataverseIntegration #VirtualTables #PowerPlatform #ERPIntegration #DynamicsConsulting

Dynamics 365 Tax Calculation Migration Gets an Automated Tool. It Still Needs a Reviewer.

Finance systems analyst reviewing Dynamics 365 tax configuration data on a monitor

A finance solution architect I spoke with recently put the choice in blunt terms: her team’s Sales Tax configuration has worked reliably for nine years, and nobody wants to touch it, but Microsoft has made it clear that Advanced Tax Calculation, not the legacy Sales Tax module, is where indirect tax functionality in Dynamics 365 Finance is actually heading. That tension shows up in nearly every conversation about a Dynamics 365 tax calculation migration: teams know the destination, but re-keying years of tax codes, tax groups, and jurisdiction rules by hand is not a project anyone volunteers for. With the 2026 Wave 1 release, Microsoft shipped a preview feature aimed at closing that gap, and it deserves a close technical look before anyone assumes it turns migration into a one-click event.

What the Tax Calculation Migration Tool Actually Moves

The feature, officially called “Automate tax feature creation based on tax master data,” lives in Globalization Studio under Tax Calculation, and it is activated through a Feature Management flag rather than being on by default. Once enabled, it reads a legal entity’s existing sales tax master data (tax codes, sales tax groups, and item sales tax groups) and builds an equivalent Tax Calculation feature version from it, reusing the reference data rather than asking anyone to redefine it from scratch. It also maps general ledger parameters that previously lived at the legal entity level, reverse sales tax on cash discount, whether cash discount is deducted before tax calculation, and whether cash discount is calculated on an amount including tax for both customers and vendors, onto their equivalent Tax Jurisdiction Parameters in the new model. Tax code origin settings translate as well: percentage of gross amount becomes “By Gross Amount,” percentage of net amount becomes “By Net Amount,” percentage of margin becomes “By Margin,” and so on through amount-per-unit and tax-on-tax origins.

Finance systems analyst reviewing Dynamics 365 tax configuration data on a monitor

That mapping table matters more than it looks. Anyone who has manually stood up Advanced Tax Calculation before knows that recreating tax jurisdiction parameters and origin rules correctly, across dozens of tax codes, is where most implementation hours actually go. Automating that translation, even in preview, removes a meaningful chunk of the grinding part of the work.

Where the Automation Runs Into Real Constraints

The tool is scoped to one legal entity at a time, and it requires the operator to be signed into the correct legal entity before starting the process from the Tax Data Migration button in Globalization Studio. It is also explicitly unavailable for Brazil and India legal entities, so multinational rollouts will need a separate manual path for those jurisdictions regardless of how well the automated tool performs elsewhere.

Two hard limits are worth flagging before anyone schedules migration work around this tool. Tax code names are capped at ten characters in the target model, and when a naming conflict forces the tool to create a variant, it truncates the original name and appends a numeric suffix, so “Test123456” becomes “Test1234_1.” Separately, if the combined character length of the tax codes attached to a single tax group or item tax group exceeds 1,000 characters, the migration for that group fails outright with an explicit error rather than a partial or degraded result. Neither limit is exotic for a small implementation, but a legal entity that has accumulated hundreds of tax codes over a decade (which describes a fair number of established Dynamics 365 customers) can hit the 1,000-character ceiling without anyone realizing it was a live risk until the process stops.

Reading the Variant Logic Correctly

Tax code variants deserve particular attention because the tool’s behavior here is deterministic in outcome but not in labeling. When the same tax code is assigned to more than one tax group with different parameters, for instance a code marked Exempt in one tax group and configured with Use Tax enabled in another, the migration creates separate variants, such as Test10, Test10_1, and Test10_2, to preserve both configurations rather than collapsing them into one and losing data. The parameter mappings themselves come through correctly, but which suffix lands on which variant is not something to assume from naming alone. Microsoft’s own documentation notes the suffix order isn’t guaranteed to follow a predictable pattern. A reviewer needs to open each variant and check its assigned tax group and parameters directly, rather than trusting that _1 always corresponds to the first tax group alphabetically or chronologically. Skipping that verification step is the most likely way a migration looks clean in testing and then produces a wrong tax determination on a specific transaction type in production.

Cash discount handling is the other area that needs a second look rather than a rubber stamp. Because the legacy model sometimes allowed cash discount settings to diverge between the general ledger parameters and individual sales tax groups, the migration surfaces a warning wherever it detects that discrepancy instead of silently picking one value. That warning is not cosmetic. It flags a real business decision, specifically which cash discount behavior should win going forward, that the automation correctly declines to make on its own.

Two enterprise IT professionals reviewing a tax migration report and dashboard

What This Means for a Dynamics 365 Tax Calculation Migration Project Plan

None of this changes the fundamental recommendation: this is a preview feature, and Microsoft’s own guidance is explicit that it is not intended for production use yet. Treat a run of the tool as generating a strong first draft of the target configuration, not a finished migration. The realistic project plan looks like importing the latest tax configuration through Electronic Reporting, enabling the preview flag in Feature Management, running the tool against a non-production legal entity, and then working through a defined review checklist. That checklist should confirm every tax jurisdiction parameter actually matches current business intent rather than just what the legacy setup happened to contain, trace every tax code variant back to its correct tax group assignment, resolve every cash discount warning as a deliberate decision, and check the default rounding method, which the tool sets to Ordinary regardless of what a given legal entity may actually need. There is also no incremental sync: if master data changes after a feature version is created, that version does not update itself, and the team has to decide whether to regenerate a new version or maintain the delta by hand.

For a solution architect scoping this work, the honest framing is that the tool changes where implementation hours go rather than eliminating them. It removes most of the manual re-entry burden and replaces it with a structured, checklist-driven review, which for a data set of any real size is still a substantially better trade than doing both the entry and the review from a blank slate. Firms that have run tax configuration projects on both the legacy and Advanced Tax Calculation models, Routeget Technologies among them, tend to build that review checklist into the statement of work up front, specifically because the tool’s own limitations (character caps, entity-by-entity scope, and the Brazil and India exclusions) are exactly the details that get missed when a migration is treated as a single automated step instead of a reviewed one.

Teams planning a Dynamics 365 tax calculation migration over the next few Wave releases should watch for this feature’s move from preview to general availability, since GA typically brings expanded country coverage and, ideally, an incremental update path. Until then, the tool is genuinely useful for what it is: a way to stop re-keying tax codes by hand and start reviewing a generated draft instead. That is a real improvement in a project that used to have no shortcut at all, even if it is not yet the fully automated migration some teams are hoping for.


#TaxCalculationService #DynamicsFinanceOps #GlobalizationStudio #ERPTaxCompliance #TaxAutomation #FinanceTransformation

The Power Apps Per-App Plan Is Retiring. It’s Forcing Overdue Power Platform License Optimization.

IT director and finance director reviewing a Power Platform license usage dashboard on a large office monitor

An IT director at a distribution company got her Power Platform renewal quote back in August and the per-app line item had a note attached: new purchases under that SKU were no longer available through her Enterprise Agreement’s normal channel. She had eleven apps running on per-app capacity packs, covering everything from a driver check-in tool to a rebate approval workflow, and nobody on her team had ever audited whether those apps still needed dedicated capacity or whether half their users had moved to other roles. The renewal conversation, which was supposed to be a formality, turned into a scramble to figure out what she was actually paying for, and into the kind of overdue Power Platform license optimization exercise most IT organizations keep putting off until a contract forces it.

IT director and finance director reviewing a Power Platform license usage dashboard on a large office monitor

That scramble is becoming common. Microsoft ended new sales of the Power Apps per-app plan on January 2, 2026, and the way that retirement plays out depends entirely on which purchasing channel an organization uses: Enterprise Agreement customers can keep renewing and adjusting counts through their normal true-up process, MPSA customers lose access to the SKU when their current agreement expires and get sixty days to move to something else, and CSP customers were largely unaffected, with the plan returning to availability there in early April. Three different outcomes for the same retirement, depending on how procurement happens to be structured, is exactly the kind of detail that gets missed until a renewal quote forces the question.

The timing matters because it coincides with something genuinely useful: Microsoft has finally shipped a way to see what a Power Platform license estate is actually being used for, instead of relying on procurement records and institutional memory. Getting that visibility in place before the next renewal cycle is the difference between a defensible Power Platform license optimization decision and another round of guessing.

Why Power Platform License Optimization Has Been Mostly Guesswork

Until recently, an organization trying to right-size Power Apps and Power Automate licensing had to stitch together the answer from several disconnected places: the Microsoft 365 admin center for what was purchased and assigned, PowerShell exports like Get-AdminPowerAppLicenses for a point-in-time snapshot, and whatever the CSP or EA reseller could pull from their own systems. None of those sources actually answered the question a CFO cares about, which is how many of the licenses being paid for are being used by someone doing real work in a given month.

The license consumption experience now available (in preview) inside the Power Platform admin center closes that gap. Under Licensing, administrators can pull up Power Apps and see, side by side, per-user licenses purchased against per-user licenses actually consumed by someone who launched an app in the last 90 days, per-app licenses allocated to environments against what was purchased, and any pay-as-you-go billing plans linked in the same view. It breaks down by environment as well as organization-wide, and it will export a CSV of active users, their last app launch, and which license type they used to get in. For an IT director trying to answer “do we actually need eleven per-app packs,” that is the first time the honest answer has been sitting in one screen rather than scattered across three systems and a spreadsheet someone built two years ago.

There is a companion version of this reporting for Dynamics 365 Finance and Operations environments connected through the Power Platform admin center, and it is worth calling out separately because F&O licensing carries its own compliance exposure that per-app and per-user Power Apps licensing does not. That report maps security roles to license requirements and flags users who are under-licensed for the roles they hold, over-licensed relative to what they actually use, or missing a license entirely despite having role access. For a finance organization worried about a true-up or compliance review turning up unlicensed F&O access, that role-to-license breakdown is arguably more valuable than the Power Apps consumption view, because F&O license gaps carry direct compliance risk rather than just wasted spend.

Two enterprise IT professionals reviewing a printed license usage report and laptop dashboard during a renewal discussion

What This Changes About the Renewal Conversation

None of this reporting makes the decision automatically. It gives a CIO or CFO the input needed to make a real one, and there are three moves worth having on the table before the next renewal.

The first is treating the per-app retirement as a forcing function to re-evaluate whether per-app capacity was ever the right model for those specific apps in the first place, rather than assuming the goal is simply to find a like-for-like replacement. An app used constantly by a stable group of forty employees usually still makes sense on a capacity or per-user model. An app used sporadically by three hundred people across the organization, the kind of low-frequency, wide-distribution use case Microsoft explicitly points pay-as-you-go at, is often cheaper and administratively simpler on a consumption model tied to an Azure subscription, where there is no license procurement cycle at all and the organization pays only for sessions that actually happen.

The second is using the consumption report before, not after, the renewal negotiation. A vendor conversation about right-sizing an estate is a different conversation when the buyer walks in with an export showing which per-app allocations have had zero active users in the trailing ninety days versus one built on assumptions. That data also gives Finance a defensible basis for the true-up number instead of an estimate carried forward from the prior year.

The third is recognizing that pay-as-you-go billing plans allow granular cost allocation that traditional licensing does not. Because a billing plan links specific environments to an Azure subscription, and because Azure’s own cost management and resource tagging can then split charges by team or department, an organization running Power Platform across multiple business units can get a real chargeback model instead of a Power Platform budget line that IT absorbs and never breaks down by consumer. That is a meaningfully different conversation for a CFO than “the Power Platform bill went up again this year.”

What to Do Before the Next Renewal

For an organization anywhere in the Power Platform per-app transition, the practical sequence is straightforward even if the underlying decisions are not. Pull the license consumption report for Power Apps and, if applicable, the F&O consumption report, before assuming a renewal quote reflects actual need. Segment the app portfolio by usage pattern rather than by however licenses happen to be allocated today, since a capacity pack purchased three years ago for a pilot may now be covering an app that either died quietly or scaled to a very different usage profile. Confirm which purchasing channel governs the organization’s contracts, since an EA customer facing no disruption and an MPSA customer facing a sixty-day migration window are working against very different timelines, and the MPSA customer in particular should not wait for the renewal notice to start that conversation. And treat pay-as-you-go as a genuine option for the specific subset of apps that fit its profile, rather than a fallback only considered after per-user and per-app options are exhausted.

None of this requires a platform migration or a change to how the apps themselves work. It requires pulling data that, for the first time, is actually sitting in one place, and using it to make a licensing decision on facts rather than habit. Organizations that have gone through a Power Platform license optimization exercise with us tend to find the same thing: the spend was rarely wildly wrong, but it was almost never right, and the gap between those two states is usually worth the afternoon it takes to run the report.


Routeget Technologies works with IT and finance teams on Power Platform governance and licensing reviews as part of broader Dynamics 365 and Power Platform engagements.


#PowerPlatformLicensing #LicenseOptimization #PowerAppsPerApp #PayAsYouGo #PowerPlatformGovernance #ITCostGovernance

Dynamics 365’s Free Sentiment Analysis Has a Blind Spot. AI Builder Sentiment Analysis Can Close It, at a Cost.

Customer experience team reviewing a sentiment analytics dashboard on a large monitor

A customer experience director at a mid-market distributor recently asked her Dynamics 365 partner for something that sounded simple: one ranked list of accounts trending toward churn, built from every piece of customer feedback the company already collects. Support conversation transcripts, service case notes, post-delivery satisfaction surveys, and the freeform comments account managers leave on Opportunity records all already exist somewhere in her Dataverse environment. She assumed the sentiment analysis her team had seen in Customer Service demos would simply read all of it. It doesn’t. Dynamics 365’s built-in sentiment analysis is real, it works well, and it costs nothing extra to use, but it only sees what happens inside a case or an email thread. Everything else on her list, the surveys, the account notes, the reseller complaints logged in a spreadsheet, sits entirely outside its reach. Closing that gap means turning to AI Builder sentiment analysis, a separate tool, and that is a deliberate build, not a setting an admin flips on.

That distinction gets lost in a lot of planning conversations, because “Dynamics 365 has AI-powered sentiment analysis” sounds like one complete capability. It is actually two separate tools, the sentiment monitoring built into Customer Service and the standalone AI Builder sentiment analysis model, with different reach, different cost structures, and different governance obligations. Confusing the two is how a CX program either overpromises what a pilot will cover or underuses a tool that is already paid for.

What Dynamics 365 Already Gives You, Free

Native sentiment analysis in Customer Service is enabled by default and configured through the admin center’s Insights settings, where a supervisor can turn on real-time monitoring in a few clicks. Once it’s on, service representatives see a live sentiment reading during an active omnichannel conversation, with configurable alert thresholds ranging from “slightly negative” up to “very negative,” and supervisors get their own notification settings so they can step in on a conversation that’s deteriorating before it becomes an escalation. Historical scoring rolls up into Omnichannel Insights dashboards for after-the-fact analysis, and the feature covers more than forty languages out of the box. As of a May 2026 release, Microsoft extended the same underlying capability to email: incoming customer messages now get scored for tone before a representative drafts a reply, and that email-level sentiment rolls into a unified case sentiment score alongside conversation data. None of this requires AI Builder, a Power Automate flow, or a separate licensing conversation. It is part of the platform a Customer Service organization is already paying for.

Where the Built-In Tool Stops Seeing Customers

The scope of that native feature is narrower than most stakeholders assume. It is wired specifically to the Case, Conversation, and Email Message records inside Customer Service, and nothing that lives outside that data model gets touched by it. A satisfaction survey captured through a Power Pages portal or a Customer Voice form sits in its own tables. Freeform notes an account manager keeps on an Opportunity or Account record are just text fields, invisible to a sentiment engine that only looks at cases. A complaint a reseller emails to a partner manager, rather than filing through a support channel, never becomes a case at all. Social commentary or review-site feedback pulled in through a connector has no case or email record to attach a score to. In the distributor’s situation, most of the feedback her CX team actually cared about lived in exactly these gaps, which is why the demo she’d seen didn’t match the reality of her own data.

Solution architect building an automated sentiment scoring flow on a laptop

What AI Builder Sentiment Analysis Adds That the Native Tool Doesn’t

This is the actual role for AI Builder sentiment analysis, and it is worth being precise about what kind of tool it is. It’s a standalone prebuilt model, not a Customer Service feature, callable from a Power Automate flow or through a Power Fx formula in a canvas app, and it has no built-in awareness of cases or email at all. It accepts up to 5,120 characters of text per call and returns a document-level classification of positive, negative, neutral, or mixed sentiment, along with a confidence score and, if needed, a sentence-by-sentence breakdown. It supports a solid set of languages, including English, Spanish, French, German, Italian, Portuguese, Dutch, Japanese, Korean, Chinese, Hindi, Turkish, and Norwegian. Because it’s just a callable action with no opinion about where its input comes from, a flow can point it at a Customer Voice survey response table, a custom “Account Note” column, a SharePoint list, or an inbox that never turns into a formal case. That flexibility, not any difference in accuracy, is the actual reason to reach for it: it lets an organization build the one unified sentiment signal the CX director wanted, rather than settling for whatever slice of the customer relationship happens to fall inside a Case record.

The Rate Limit and Credit Shift Worth Budgeting For

Two constraints deserve attention before anyone commits a rollout date. The first is technical: the sentiment analysis, language detection, and key phrase extraction prebuilt models share a single throttle of 400 calls per 60 seconds within an environment. That ceiling is comfortable for scoring cases and emails as they trickle in throughout the day, but it gets hit fast the moment someone tries to backfill a year of Opportunity notes or process five thousand quarterly survey responses in one overnight batch. This is usually the first thing that breaks when a “score everything” mandate meets real data volume, and it should shape the flow design from the start, through pacing, delay steps, or triggering only on new and changed records instead of reprocessing history, rather than getting discovered during a failed pilot.

The second constraint is financial, and it connects to a transition already underway across AI Builder. Sentiment analysis is now billed under Microsoft’s “text and generative AI tools (Basic)” capability, and its licensing is migrating from AI Builder credits to Copilot Studio credits, with AI Builder capacity add-ons and any seeded credits in premium licenses reaching end of life on November 1, 2026. Any budget built for a sentiment-expansion project running into next year should be modeled against Copilot Studio credit consumption, not against a credit pool that Microsoft has already scheduled to stop selling.

A Practical Pattern for Extending Coverage

The build itself is not complicated once the source data is identified. A Power Automate flow triggers on new or changed rows in whichever table holds the text, whether that’s a survey response, a custom account-note table, or a Power Pages-submitted complaint form, calls the AI Builder sentiment action, and writes the resulting classification and confidence score back to a column on that record. From there, a condition branch can raise a Dataverse task for the account owner when a result comes back strongly negative above a chosen confidence threshold, and a Power BI report can rank accounts by a rolling sentiment average pulled from every connected source, not just cases. That report is what actually answers the CX director’s original request. The one governance step teams tend to skip is consent: because this reaches customer-identifiable text outside the flow Customer Service already governs for case and email sentiment, legal and IT should extend the same notice-and-consent practice to whatever new source gets added, rather than assuming existing sentiment monitoring approvals already cover it.

What to Confirm Before Committing

Three things are worth verifying before committing. The inventory of where sentiment-bearing text actually lives outside the Case and Email Message tables determines whether this is a two-week Power Automate build or a multi-source integration project, so it belongs at the start, not mid-pilot. Realistic call volume needs to be estimated against that 400-call, 60-second shared limit before a rollout date gets promised to a business sponsor, because a mismatch there turns a promising pilot into an incident in its first week of production use. And finance should weigh whether the Copilot Studio credit model makes sense at the organization’s expected volume compared with calling Azure AI Language directly through a custom connector, since at higher volumes the direct route sometimes costs less and gives more control over batching, even though it takes more setup than the point-and-click AI Builder action.

Dynamics 365’s native sentiment analysis, especially now that it reaches into email as well as live conversations, already covers most of what a typical service organization needs, and it’s worth using as it stands before building anything on top of it. The gap only becomes a problem when an organization wants one sentiment signal spanning every channel a customer actually uses, most of which never turns into a case. AI Builder sentiment analysis is the right tool for that expansion, but it comes with a real throughput ceiling and a licensing model mid-transition, not a checkbox next to a feature Microsoft already includes. Teams at firms like Routeget Technologies that have wired sentiment scoring into Dataverse tables outside the standard Customer Service model tend to start with that inventory step, because it’s usually where the real scope of the project gets decided, before anyone opens Power Automate.


#AIBuilder #DynamicsCustomerService #PowerAutomate #ChurnPrevention #CustomerExperience #EnterpriseAI #Dataverse

Power Apps Delegation Limits Don’t Throw an Error. They Just Give You the Wrong Answer.

Solution architect reviewing a data table dashboard on a large monitor, illustrating enterprise data query review

A finance team at a mid-size distributor built a canvas app to flag overdue receivables. It worked perfectly in every demo. Then it went into production against a SharePoint list that had grown past 4,000 rows, and the “overdue balance” total the app displayed started coming in a little low every week, never wildly wrong, just quietly off by a shrinking or growing margin depending on how the underlying data happened to sort. Nobody got an error message. Nobody got a warning banner in the running app. The gallery rendered, the total summed, and the number was simply incomplete, because Power Apps had silently stopped looking at the data after the first 500 records.

That is the practical shape of a delegation problem, and it is one of the more consequential gaps between how canvas apps behave in the maker’s testing environment and how they behave once real data volume shows up. Power Apps delegation limits determine whether a formula gets pushed down to the data source, which processes it server-side and returns only the matching rows, or whether Power Apps has to pull a bounded chunk of records locally and evaluate the formula against that chunk alone. When delegation fails and the underlying table is larger than the configured limit, the app does not stop working. It keeps working, on a subset of the data, without saying so.

Why Power Apps delegation limits fail silently instead of crashing

A crash gets fixed immediately because someone notices. A silently truncated query gets fixed only when someone happens to reconcile the app’s output against the source system and finds a discrepancy, which in the receivables example took several weeks. For a technical team supporting Dynamics 365 or Power Platform deployments, this is the argument for treating delegation as an architecture decision made at design time, not a performance tweak applied after a slow gallery gets noticed.

The default data row limit in a canvas app is 500 records, adjustable up to a hard ceiling of 2,000 in the app’s Settings under General. Raising that number is a common instinct and a bad one to rely on as a fix, because it just moves the cliff edge further out rather than removing it; a table with 50,000 rows behaves identically whether the limit is set to 500 or 2,000; it only changes how much data has to grow before someone notices something is wrong. Microsoft’s own guidance for this reason recommends the opposite move during development: set the limit down to 1 in a test environment, which forces every non-delegable formula to reveal itself immediately with obviously wrong results, rather than leaving that discovery to production data volume.

What actually gets delegated, and what does not

Power Fx delegates a meaningful set of operations against supported data sources, including Dataverse, SharePoint Online, SQL Server, and Salesforce. Filter, Search, LookUp, and First all delegate, as do the standard comparison operators, And, Or, Not, StartsWith, EndsWith, and the core aggregates: Sum, Average, Min, Max, CountRows, and Count. Sort and SortByColumns delegate as well, with an important caveat covered below for SharePoint. The In operator delegates too, but only against a column on the base table; the moment a formula tests In against a related or lookup column, delegation breaks and the query falls back to local evaluation.

Developer typing Power Fx formula logic on a laptop with a monitor showing abstract code in the background

The non-delegable list is longer and easier to trip over than most makers expect. FirstN, Last, and LastN do not delegate. Neither does If, which means embedding conditional logic inside a Filter predicate is a common way a formula that looks delegable quietly is not. String manipulation functions including Left, Mid, Len, Lower, and Upper are non-delegable, along with Concatenate and the & operator, GroupBy, Ungroup, and type-casting functions like Text and Value. Collect and ClearCollect are non-delegable by nature, since they materialize data locally rather than querying it. A formula like Filter(Fruit, Mid(FruitName, 1, 1) = “A”) looks reasonable and reads cleanly, but because Mid cannot be pushed to the data source, it only ever evaluates against the first page of records pulled locally, meaning a record named “Pineapple” sitting past row 500 will never match a search for names starting with “P,” not because the logic is wrong, but because the function never sees that row.

SharePoint makes this worse than Dataverse does

Anyone who has built canvas apps against both SharePoint lists and Dataverse tables has felt the difference in how forgiving each source is, and the gap is documented, not just anecdotal. SharePoint does not delegate relational comparison operators (less than, greater than, not-equal) on plain text fields at all, only equality. IsBlank does not delegate against text fields either, and the commonly suggested workaround, comparing to Blank() directly, does not behave identically for genuinely empty strings versus null values, which is a subtle correctness gap worth documenting in code review rather than discovering in production.

The bigger gap sits in SharePoint’s complex column types: Choice, Lookup, Person, Group, Task Outcome, Managed Metadata, and External Data. None of these support delegated sorting, so Sort or SortByColumns against a Choice or Person field will silently fall back to sorting only the locally retrieved page. StartsWith does not work against subfields of Choice or Lookup columns. Person and Group fields only delegate on their Email and DisplayName subfields, not on other properties. A set of SharePoint system fields, including ContentType, ModerationStatus, VersionNumber, and several path-related fields, do not delegate under any function at all. UpdateIf and RemoveIf against SharePoint are handled through a batching simulation bounded by the same 500/2,000 record limit rather than a true server-side delegated operation, which matters for any flow that bulk-updates list items from within the app rather than through Power Automate.

Dataverse does not eliminate delegation limits, but it closes most of these specific gaps: relational operators work against text columns, In delegates on base-table columns consistently, and sorting against lookup and choice columns behaves as makers expect. For any canvas app expected to scale past a few thousand records with complex filtering or sorting, that difference is a legitimate factor in the SharePoint-versus-Dataverse decision, not just a licensing or governance one.

Designing around it instead of hoping around it

The most reliable pattern is to push complexity toward the data source rather than the formula bar. Where a filter needs to test a derived value, calculated columns created in Dataverse (or, with more limitation, in SharePoint) let the comparison happen against a pre-computed, delegable field instead of a runtime string function the client has to evaluate locally. Where a search needs to match across multiple text fields, Search() itself delegates and is usually a better first attempt than a hand-built Filter with concatenated conditions, since it is one of the few functions built specifically to delegate substring matching.

For teams supporting these apps in production rather than just building them, the practical safeguard is process, not just formula discipline: run the app with the row limit forced to 1 during test cycles, review any gallery, dropdown, or KPI tile driven by a filter or sort against a table that could plausibly exceed a few hundred rows in production, and treat a yellow delegation warning triangle in Power Apps Studio as a defect ticket rather than a cosmetic nag to dismiss. The warning is not a suggestion about performance. It is Power Apps telling the maker, in the only language it has, that the number on screen may not represent all of the data.

We’ve walked enough Dynamics 365 and Power Platform clients through exactly this kind of discovery, usually during a post-go-live support engagement rather than a planned architecture review, to treat delegation as a first-week design conversation on every canvas app project involving a table that is expected to grow. It is a cheap conversation to have early and an expensive one to have after a finance report has been quietly wrong for a month.


#PowerApps #PowerFx #CanvasApps #Dataverse #SharePointOnline #EnterpriseArchitecture #LowCodeDevelopment

Your Field Service Techs Are Getting Blank Screens Offline. The Mobile Offline Profile Is Probably Why.

Field service technician reviewing a mobile app on a rugged tablet at a remote service site

A field technician pulls into a rural service site with one bar of signal, opens the Dynamics 365 Field Service mobile app to check the work order, and gets a blank booking screen. No linked asset. No contact history. No parts list. The dispatcher, sitting in an office with full connectivity, sees the record perfectly. By the time anyone traces the problem, three more technicians have hit the same wall in three different territories, and the rollout that was supposed to cut truck-roll callbacks is instead generating help desk tickets.

Nine times out of ten, this isn’t a connectivity problem. It’s an offline profile problem, and it’s almost always self-inflicted during setup rather than caused by anything Microsoft shipped broken. The mobile offline profile is the single control surface that decides what data a technician’s device downloads before it goes dark, and getting it wrong doesn’t throw an error message. It just quietly leaves data out.

What the Mobile Offline Profile Actually Controls

Every Field Service mobile deployment starts from a default profile, “Field Service Mobile – Offline Profile,” preloaded with the tables most implementations need: bookable resource bookings, work orders, and the handful of related entities technicians touch in the field. Each table in the profile carries its own filter and its own sync frequency, and the defaults are conservative on purpose. Bookings, for instance, are filtered out of the box to only those starting within the next seven days, which keeps the initial download small but also means a technician who needs to glance at next month’s schedule offline simply can’t.

The part that trips up most implementations isn’t the top-level filters. It’s item association: how child tables inherit scope from their parent. When a table is configured with a “related rows only” filter, it doesn’t get its own independent rule, it borrows whatever the parent table’s filter already decided. If a work order filter is scoped to status equals Scheduled, and the contact table beneath it is set to related rows only, technicians lose visibility into every contact tied to a work order that isn’t currently in Scheduled status, including ones they closed out an hour ago and now need to reference for a warranty callback. This is rarely intentional. It’s usually the byproduct of an admin extending the default profile with a new custom table, applying “related rows only” because it’s the fastest configuration path, and never testing what happens once a record moves out of the parent filter’s scope.

Where FetchXML Earns Its Place

Point-and-click filters cover a lot of ground, but they run out fast once the business logic gets specific: technicians who should only see assets under an active maintenance contract, or work orders filtered by a custom priority field that doesn’t map cleanly to the standard filter builder. That’s what the FetchXML editor built into the offline profile experience is for. It sits underneath the same table configuration screen as the standard filter UI, and it lets an admin or developer write the actual query logic that determines what gets pulled down, rather than settling for whatever combinations the visual filter builder happens to expose.

Two details matter here that don’t show up until you’re debugging a slow sync in production. First, table relationships in an offline profile are capped at fifteen linked tables, counting the downstream relationships each linked table pulls in, so a profile built by repeatedly adding “just one more related table” to solve an edge case will eventually hit a wall that has nothing to do with data volume and everything to do with query complexity. Second, several standard tables never make it into offline mode at all regardless of how the FetchXML is written, among them purchase orders, agreements, and return-to-vendor or return-merchandise-authorization records. If a workflow depends on a technician checking RMA status from a job site with no signal, that has to be redesigned around the platform’s boundaries rather than configured away.

The Update Trap Almost Nobody Reads About Until It Bites

Microsoft updates the default offline profile periodically as part of ongoing Field Service releases. That sounds like a convenience, and for tables you haven’t touched, it is: their sync filters get refreshed automatically, though the updated version lands unpublished, waiting for an admin to review and accept it rather than going live silently. The trap is on the other side. The moment you edit a table’s sync filter yourself, that table is permanently excluded from future automatic updates to its filter logic. Your customization sticks, which is usually what you want, but it also means nobody upstream is going to quietly fix a filter you configured eighteen months ago if Microsoft later improves the default logic for that table. Teams that treat the offline profile as a set-and-forget configuration item, rather than something reviewed on the same cadence as the rest of their Field Service solution, tend to find this out the hard way when a filter that was reasonable at go-live has quietly become wrong as the business changed around it.

Rugged tablet showing a sync status dashboard inside a field service van

Sync Behavior and the Conflict Question Nobody Asks Until It Happens

Sync intervals per table can be set anywhere from five minutes to a full day, and a related table with a shorter interval than its parent will pull the parent’s sync cadence down to match, which is a reasonable default but one worth knowing about before you tune a slow-changing table to sync once daily and then wonder why it’s still refreshing every few minutes. The conflict scenario that actually matters operationally is what happens when a technician edits a record offline while a dispatcher edits the same record online before the technician’s device reconnects. Dynamics resolves this at the table level, not the field level, meaning it can’t merge a technician’s parts-used update with a dispatcher’s status change on the same booking if both touched the record. By default, the technician’s offline change wins when the sync finally reconciles; that behavior can be flipped so the dispatcher’s online change takes precedence instead, but it’s a system setting, not something either side of that conflict controls in the moment. Organizations that run high-volume dispatch operations with technicians frequently going in and out of coverage should decide which side should win deliberately, rather than discovering the default behavior mid-incident.

Building a Profile That Holds Up in Production

The practical guidance that actually prevents the blank-screen scenario starts with resisting the urge to filter on “all records” for any table technicians don’t strictly need in full. A technician-scoped view like “my recent bookings” instead of the full bookings table, paired with tight date-range filters, keeps the initial download fast and avoids syncing data nobody in the field will use. For custom logic that needs to run without a network connection, offline-capable JavaScript on the form is the right tool, not a Power Automate flow, since cloud flows simply don’t execute until the device reconnects, which means any process depending on one won’t fire while the technician is actually offline. When custom commands query offline data directly, keeping concurrent database calls to two or three at a time avoids performance degradation on lower-end field devices, and using FetchXML paging with a page cookie rather than pulling an entire table in one request keeps large tables from stalling initial sync. Finally, testing a profile against a realistic data volume, not a clean sandbox with a handful of sample records, is what actually surfaces the fifteen-table ceiling and the related-row inheritance trap before a rollout, rather than after one.

None of this is exotic configuration. It’s closer to data modeling than app administration, and it rewards the same discipline: understand what each table’s filter actually inherits, know where the platform’s hard limits sit before you design around them, and revisit the profile as a living part of the solution rather than a one-time setup task. Teams we’ve worked with on Field Service rollouts consistently find that the offline profile, more than any other single configuration piece, determines whether the mobile app earns trust in the field or becomes the thing technicians route around.


#FieldServiceMobile #DynamicsFieldService #FetchXML #OfflineDataSync #EnterpriseMobility

Business Central Doesn’t Ship a Visual Production Scheduler. Manufacturers Need to Budget for One.

A production scheduler pointing at a large touchscreen displaying a colorful Gantt-style production schedule in a factory control room

A finance director at a contract manufacturer we spoke with recently put it plainly: her company had spent seven figures moving off an aging NAV instance and onto Business Central, and the go-live checklist covered chart of accounts mapping, inventory valuation, and tax setup in exhaustive detail. Nobody on the project had asked how the shop floor supervisor would actually build tomorrow’s schedule. Three weeks after cutover, that supervisor was back to a whiteboard and a spreadsheet, because the production order list Business Central shipped with told him what needed to happen, not when it would fit around the machines he actually had.

That gap catches a lot of SMB manufacturers off guard, and it is worth naming directly: Business Central does not ship a visual production scheduler. It has a capable manufacturing module underneath, with production orders, routings, work and machine centers, and both finite and infinite capacity calculations. What it does not have, out of the box, is a Gantt-style planning board where a scheduler can see every order across every work center at once and drag one into a different slot. For a make-to-order or configure-to-order shop where the schedule changes twice before lunch, that missing piece is not cosmetic. It is the difference between planning and reacting.

What Business Central Actually Gives You Natively

It helps to be precise about where the native functionality stops, because vendors on both sides of this conversation tend to blur the line. Business Central’s core manufacturing app calculates capacity using calendars assigned to work and machine centers, supports forward and backward finite loading, and will flag overloads through capacity planning worksheets. A planner can run a capacity availability report, look at a load percentage by resource, and reschedule a production order’s dates through the order card. All of that is real, and for a job shop running a handful of routings with predictable sequencing, it can be enough.

Where it breaks down is visualization and speed of adjustment. The native screens are list-based: rows of orders, rows of capacity figures, filtered views that require a planner to hold the whole picture in their head. There is no single canvas that shows Order 4021 sitting on the CNC line from 2:00 to 6:00 while Order 4033 is queued behind it, waiting on a changeover. When a rush order lands, or a machine goes down mid-shift, the planner is reconciling several list views rather than looking at one board and dragging a block. That reconciliation work is exactly what visual scheduling tools were built to remove, and it is why the category exists as a distinct add-on market inside the Business Central ecosystem rather than a feature Microsoft has folded into the base product.

Where a Visual Production Scheduler Actually Fits

Search AppSource for Business Central manufacturing extensions and you will find several purpose-built scheduling tools, the most established being Netronic’s Visual Production Scheduler and its more advanced sibling, Visual Advanced Production Scheduler, alongside other entrants like Graphical Scheduler and MxAPS. These are not replacements for Business Central’s manufacturing data model; they sit on top of it, reading and writing directly to the same production order and capacity tables so nothing has to be exported to Excel or re-entered anywhere. What they add is the missing visual layer: a Gantt-style board that typically splits into two views, one answering “will I hit my delivery dates” by laying out orders against the calendar, and a second showing utilization by work or machine center so a scheduler can spot an overloaded resource before it becomes a missed shipment.

A shop floor worker holding a tablet showing a drag-and-drop visual production schedule next to CNC machining equipment

The interaction model is the actual value. Instead of opening a production order, changing a date field, and re-running a capacity check, a scheduler drags an operation block to a new slot and sees the conflict, or the lack of one, immediately. Reassigning an order from one machine center to another equivalent one takes the same drag-and-drop motion. Vendors in this space report meaningful gains in on-time delivery from customers who adopt this pattern, though as with any vendor-published figure, it should be treated as directional rather than a guaranteed outcome for every shop floor, since the actual result depends heavily on how disciplined the underlying routing and work center data already is.

The Decision a CFO or IT Director Actually Has to Make

None of this means every Business Central manufacturer needs a scheduling add-on on day one. A shop with two or three work centers and a stable, low-mix production schedule may genuinely be fine with the native capacity worksheets, and adding a third-party module there would be solving a problem that does not yet exist. The decision point is usually mix and volume: once a plant is juggling more than a handful of concurrent orders across multiple resources, with routing changes, rework, or expedites showing up weekly rather than monthly, the native list-based tools stop scaling with the complexity of the floor.

The practical mistake we see during Business Central selection and implementation projects is treating visual scheduling as something to revisit after go-live, almost as an afterthought bolted on once the finance and inventory modules are stable. That ordering gets the cost and the change-management burden backwards. Licensing a scheduling add-on is a separate line item, typically priced per named user or per environment, and it needs its own implementation time to map routings and work centers correctly, since the visual tool is only as good as the underlying capacity data it renders. Building that into the original project budget and timeline, rather than treating it as a post-go-live patch, avoids a second wave of user training and a second change request against a system that finance already considers “done.”

There is also a governance dimension worth flagging to IT: because these add-ons write directly back into core manufacturing tables, they need the same change-management scrutiny given to any other extension touching production data, including how they behave during version upgrades and whether the vendor maintains compatibility with the current Business Central release cadence rather than lagging behind it.

What to Ask Before You Buy

For a decision-maker evaluating this category, a few questions cut through most of the vendor marketing. First, does the tool read and write directly to standard Business Central production order and capacity tables, or does it maintain a shadow schedule that has to be reconciled back into the ERP, since the latter reintroduces exactly the synchronization risk the tool is supposed to eliminate. Second, does it support both finite capacity visualization and the specific constraint types your floor actually deals with, such as sequence-dependent changeovers or shared tooling across machine centers, rather than a generic Gantt view that looks good in a demo but cannot represent your real constraints. Third, what does the implementation actually involve beyond installing the extension, since the value of any visual scheduler depends entirely on routing and work center data being accurate before the drag-and-drop layer goes on top of it.

Getting this right is less about picking the “best” scheduling tool in the AppSource marketplace and more about being honest, early in a Business Central project, about whether the plant’s actual scheduling complexity requires this layer at all. Routeget has walked several manufacturing clients through exactly this evaluation during Business Central selection, and the pattern holds: the shops that budget for scheduling visibility from the start avoid the whiteboard relapse that pulls a supervisor back to manual planning three weeks after a system they were told would solve this problem for them.


#BusinessCentral #ManufacturingERP #ProductionScheduling #ShopFloorVisibility #ERPImplementation #DigitalTransformation

IoT Intelligence Is Out in Dynamics 365 Asset Management. Sensor Data Intelligence Moves the Azure Bill to You.

IT operations manager reviewing an asset health and sensor monitoring dashboard in a manufacturing control room

An IT director running Dynamics 365 Supply Chain Management for a mid-size manufacturer recently got a message she wasn’t expecting: the IoT feature her maintenance team had been quietly piloting inside Asset Management was being replaced. Not patched, not extended. Replaced, with a new name, a new architecture, and a new owner for the Azure infrastructure underneath it. Microsoft’s own documentation is blunt about it: “Do not start any new projects based on the existing IoT Intelligence feature.” The successor, Sensor Data Intelligence, is where new work is supposed to go instead.

This isn’t a minor renaming exercise. It’s a genuine shift in who is responsible for the cloud plumbing behind predictive maintenance in Dynamics 365, and it lands squarely on any organization that has connected sensors, meters, or PLCs to Asset Management, or has been planning to. For CIOs and IT directors weighing whether to invest in condition-based maintenance on the Dynamics 365 platform, the mechanics of this transition matter more than the rebrand suggests.

What Actually Changed

IoT Intelligence was the original bridge between physical assets and Asset Management inside Dynamics 365 Supply Chain Management. Sensor readings, whether from a vibration monitor on a pump or a temperature probe on a cold-storage unit, flowed into Azure IoT Hub and then into Supply Chain Management, where they could trigger alerts, feed maintenance plans, or update asset condition records. Critically, Microsoft managed much of that Azure infrastructure on the customer’s behalf. It worked, but it was rigid: limited room to customize the data pipeline, and friction when a customer wanted to bring in sensor data from a system that wasn’t a clean fit for the prebuilt model.

Sensor Data Intelligence, now in preview and documented as an updated, renamed version of IoT Intelligence, rebuilds that pipeline with a different deployment philosophy. Instead of Microsoft hosting and managing the Azure components, the organization deploys them into its own Azure subscription. Setup runs through an onboarding wizard rather than the manual configuration in Lifecycle Services that IoT Intelligence required. On paper, that is a usability improvement. In practice, it also means the Azure resources involved, connecting sensors through Azure IoT Hub and the broader industrial IoT ingestion pattern Microsoft points customers toward, now belong to the customer’s tenant, not Microsoft’s.

Wireless industrial sensor mounted on factory equipment with a technician viewing vibration data on a tablet

Why Microsoft Restructured It This Way

The stated reasons are customization and integration. A Microsoft-managed pipeline is easy to stand up but hard to bend. Organizations that wanted to route sensor data through an existing Azure Digital Twins model, apply their own retention and encryption policies, or connect equipment from a vendor whose telemetry format didn’t match the built-in assumptions were working against the platform rather than with it. Moving deployment into the customer’s own subscription removes that ceiling. It also happens to align with a broader pattern across the Dynamics 365 and Power Platform ecosystem this year, where more of the underlying Azure footprint is being handed to customers to own and configure directly, rather than abstracted away entirely.

That tradeoff is worth naming plainly, because it changes who needs to be in the room for this decision. Adopting Sensor Data Intelligence is no longer purely a Dynamics 365 configuration project that a functional consultant can carry alone. It is an Azure architecture decision, and it needs a cloud engineering resource involved from the start, someone who can make calls about network isolation, subscription structure, and how sensor telemetry ingestion fits into the organization’s existing Azure governance model.

The Six Scenarios Sensor Data Intelligence Is Built Around

Microsoft’s documentation frames the preview around six specific business scenarios, and each one maps to a different maintenance or production pain point rather than being a generic “connect your sensors” pitch. Asset downtime tracking uses sensor readings to measure actual machine efficiency against expected performance, giving maintenance planners a real-time efficiency signal instead of relying on manually logged downtime events after the fact. Asset maintenance ties incoming sensor readings directly to the goal of reducing maintenance cost, which in practical terms means condition data can inform when a maintenance plan should actually trigger rather than running purely on a fixed calendar schedule. Machine status notifications alert production planners the moment equipment goes down, cutting the lag between a physical failure and a scheduling response. Product quality scenarios compare live sensor readings against defined quality thresholds, catching drift before it turns into a batch of rejected output. Production auto-reporting uses sensor thresholds to automatically report finished quantities, removing a manual data-entry step from the shop floor. And production delay tracking compares actual cycle time against planned cycle time, surfacing bottlenecks that would otherwise only show up after the fact in a variance report.

None of these six scenarios require a from-scratch build. They come as templates within the new model, which is a meaningful head start for organizations that don’t have the internal bandwidth to design an IoT-to-ERP data pipeline from first principles. But a template is not the same as a finished solution, and each one still needs to be mapped against the specific sensors, thresholds, and maintenance workflows already in place at a given plant.

What Belongs on a Decision-Maker’s Checklist

The preview status is the first thing worth sitting with. Microsoft’s own terms are explicit that preview features aren’t meant for production use and carry restricted functionality, so any organization currently relying on IoT Intelligence for live maintenance decisions is not looking at a drop-in replacement they can adopt today. They are looking at a migration to plan for, on a timeline Microsoft has not published in its formal deprecation schedule. Checking Microsoft’s removed and deprecated features documentation for Supply Chain Management shows plenty of other retired capabilities listed with version numbers and dates; IoT Intelligence, as of this writing, is not one of them. That gap between “don’t build new things on this” and an actual scheduled retirement date is exactly the kind of ambiguity that should push a cautious organization toward an early conversation with Microsoft or its implementation partner rather than a wait-and-see approach.

Budget conversations need to happen earlier than usual, too. When Microsoft manages the Azure components behind a feature, the cost of that infrastructure is effectively invisible to the customer, folded into the overall service. Once the deployment sits in the customer’s own subscription, IoT Hub throughput, storage, and any downstream compute for the sensor data pipeline become line items the organization has to provision, monitor, and pay for directly, governed by whatever cost management and tagging discipline already applies to the rest of its Azure estate. That is not necessarily a bad outcome. Full ownership of the infrastructure also means full visibility into what it costs and full control over where it runs, which matters for organizations with strict data residency or network segmentation requirements that a Microsoft-managed black box never let them satisfy cleanly.

Finally, this is a good moment to audit what IoT Intelligence usage already exists in the environment, even informally. A maintenance team that connected a handful of sensors as a proof of concept two years ago may not have flagged that project to IT as a dependency, and a preview migration is the wrong time to discover a shadow deployment that nobody owns.

The Bigger Pattern Behind the Rename

Sensor Data Intelligence is a small feature in the context of the broader Dynamics 365 Supply Chain Management platform, but it is a clear example of a decision Microsoft is making more often across the ecosystem: put the Azure infrastructure in the customer’s hands and trade managed simplicity for architectural control. That is generally the right long-term direction for organizations with mature cloud governance. It is a heavier lift for organizations that treated Dynamics 365 as a self-contained ERP system and never built out the Azure engineering capability to match. Teams at Routeget Technologies that have supported Asset Management deployments through platform transitions like this one typically start by mapping the existing sensor footprint and the target Azure subscription model before touching the Sensor Data Intelligence onboarding wizard itself, since getting that architecture right the first time avoids a second migration a year later.


#AssetManagement #SensorDataIntelligence #IoTinERP #PredictiveMaintenance #AzureGovernance #SupplyChainAutomation