Building Enterprise AI Plugins for Copilot Studio: When Prompt Engineering Stops Working

Your Copilot Studio instance has been live for three months. The generic responses work fine for routine customer questions. Finance users can ask about invoice status, support teams can access knowledge articles, and operations can trigger basic workflows. Then a regional finance controller asks the system to calculate cross-border tax liability on a specific transaction type, and the Copilot returns something confidently wrong. You prompt-engineer for two weeks, add retrieval augmented generation, feed it more context documents. The Copilot still hallucinates because the business logic you need is not in any training data and cannot be reliably expressed as plain-language instructions. This is the moment you need custom AI plugins.

Copilot Studio has become the dominant interface for enterprise AI in Microsoft’s ecosystem. It handles conversation orchestration, knowledge integration, and basic AI coordination reasonably well. But enterprises running this platform often discover a hard boundary: Copilot’s core language models and retrieval pipelines, however well-prompted, cannot reliably execute business logic that requires domain-specific reasoning, real-time calculation, or proprietary algorithms. At that point, the architecture choice is clear. You build a custom plugin that encapsulates your logic, expose it to Copilot through the API, and let Copilot handle the conversation while your code handles the reasoning.

The boundary between prompting and programming

The first question teams ask is practical: when should we stop refining prompts and start building a plugin? The answer depends on measurability and consistency. If the Copilot’s output accuracy has reached a plateau after refinement, and accuracy is below your business threshold, a plugin is justified. If the required logic involves calculations, date arithmetic, multi-step conditionals, or reference data lookups (like product pricing, tax rates, or inventory counts), those belong in code, not prompts. If the same request returns different answers depending on minor variations in phrasing, or if the Copilot sometimes invents plausible-sounding answers rather than admitting it cannot answer, those are signals that the language model is not the right tool for that part of the workflow.

Consider a typical scenario: a Dynamics 365 Finance user asks Copilot about available cash in a specific cost center, accounting for committed purchase orders and pending payroll. The Copilot needs to query Dynamics, aggregate real-time data, apply business rules about what counts as committed, and return a specific number. Prompting the Copilot to do this might work in a demo. In production, with thousands of daily queries across different cost centers, exchange rates, fiscal calendars, and policy variations, a language model will eventually return incorrect numbers, usually with complete confidence. A plugin solves this by running the exact query and calculation logic every time, leaving the Copilot to handle the conversation and formatting.

Plugin architecture in Copilot Studio

Copilot Studio plugins connect to external APIs. That external API can be anything you build: a cloud function, a containerized service, a Logic App with Power Automate, or a .NET Azure Function. The Copilot describes what it wants to do (based on the conversation context), the plugin action is triggered, your code executes, and the result is returned to the Copilot for further conversation.

The simplest architecture is a single Azure Function or cloud function (AWS Lambda, Google Cloud Functions) that accepts a JSON request from Copilot and returns a JSON response. The function can call Dynamics 365 APIs, query a database, call third-party services, or execute business logic. From Copilot’s perspective, it simply sends a request and gets back structured data.

For enterprise scenarios, though, you need to think about authentication, rate limiting, audit logging, and error handling. Copilot can send requests at high volume during peak usage. Your plugin needs to handle this without degrading Copilot’s response time or running up costs. You should implement proper logging of what Copilot requested, what your code returned, and any failures, so you can debug issues later. You should also plan for security: the plugin is exposing business logic and potentially sensitive data (cost center balances, tax calculations, procurement data). Access should be restricted to authenticated users, requests should be validated, and responses should be filtered by role so users only see what they are authorized to see.

Real-world plugin implementation patterns

A common pattern is the data enrichment plugin. Copilot receives a user’s question about a purchase order. The Copilot extracts the order ID or vendor name from the conversation, calls your plugin, and the plugin queries Dynamics 365 Supply Chain Management to return order status, delivery dates, budget allocation, and any policy exceptions. The Copilot then uses this structured data to answer the user’s question accurately. Without the plugin, the Copilot might guess or confuse details from different orders.

Another pattern is calculation and validation. Finance teams often need to validate transaction proposals before they are committed. A user might ask Copilot whether a specific expense is compliant with policy, and Copilot needs to check the expense amount against the cost center budget, the employee’s spending tier, the transaction category, and any special approvals in place. This logic is too complex and too sensitive for a language model to handle. A plugin runs the exact validation rules and returns yes or no with an explanation of which rule applies.

A third pattern is workflow initiation. Copilot can receive a user’s request to approve a contract, create a purchase requisition, or escalate an issue. Instead of trying to directly modify systems, Copilot calls a plugin that creates a structured request in your workflow engine (Power Automate, Logic Apps, or a custom orchestration service), which then handles the actual business process with proper audit trails, notifications, and approval chains.

Failure modes and production lessons

The most common failure in production is latency. A Copilot session timeout is usually 30 seconds. If your plugin takes 15 seconds to execute (because it is doing multi-step Dynamics queries or waiting for external services), Copilot will time out before your plugin even returns. You need to either cache data, run asynchronous jobs, or redesign the plugin to return partial results and update the Copilot UI after the full result arrives. Teams that skip this step often end up with Copilot sessions that fail silently or time out repeatedly in production.

A second failure mode is incomplete error handling. A plugin fails (database is down, Dynamics is temporarily unavailable, an API call returns an unexpected error). The plugin should catch this, log it, and return a clear error response to Copilot, not crash or hang. Copilot should then explain to the user that it could not retrieve the data and suggest alternatives (like checking the system status page or contacting support). Without this, users see broken Copilot sessions with no explanation.

Authorization is a third area. Your plugin receives a request from Copilot that includes the user’s identity. Your plugin must verify that this user is actually authorized to see the data they are asking about. If your plugin does not check authorization, users can escalate privileges by asking Copilot for data they would not normally have access to. This is a security and compliance issue, especially in regulated industries like finance and healthcare.

Choosing between custom development and pre-built AI services

Microsoft’s AI Builder sits between pure prompting and custom plugins. AI Builder lets you build models that can do optical character recognition, sentiment analysis, or predictive scoring, and expose these as Copilot actions. For some use cases (document classification, customer sentiment analysis, basic prediction), AI Builder is sufficient and faster to build than a custom plugin. But for complex business logic, multi-step reasoning, or calculations with regulatory requirements, a custom plugin is necessary because you control exactly what the code does and can audit every decision.

Deployment and monitoring

Once a plugin is built, it should be versioned and deployed through your standard application lifecycle management pipeline. Changes to plugin logic should go through testing and approval before hitting production. You should have monitoring in place: track response times, error rates, and plugin usage patterns. Set up alerts if response times exceed thresholds or error rates spike. Log every request and response (at an appropriate detail level, respecting privacy) so you can audit what Copilot asked, what your plugin returned, and whether the result was accurate.

This monitoring becomes particularly important when Copilot’s behavior changes. If Copilot suddenly starts calling your plugin more frequently or with different inputs, your plugin needs to handle it gracefully. If a new version of Copilot changes how it describes requests, your plugin should either adapt or return a clear error rather than silently misinterpreting the request.

Conclusion

Copilot Studio is effective at conversation and orchestration, but it is not a replacement for business logic. Custom AI plugins let you draw a clear line: Copilot handles the conversation and user interaction, while your code handles the reasoning, calculation, and access control. This division of labor produces systems that are both more accurate and more maintainable than trying to encode all business logic as prompts. The engineering effort to build a plugin is real, but for any enterprise scenario involving calculations, multi-step reasoning, or regulated data access, the plugin approach is the right architecture choice.

#CopilotStudioAI #AIPlugins #EnterpriseAI #PowerPlatform #CustomAIPlugins #Dynamics365AI #CloudArchitecture #PluginArchitecture

AI Builder Document Intelligence: Why Your Finance Team Still Manually Keys 2,000 Invoices a Month

AI Builder Document Intelligence: Why Your Finance Team Still Manually Keys 2,000 Invoices a Month

For most large enterprises running Dynamics 365 Finance, accounts payable looks straightforward on paper: invoices arrive, they get matched to purchase orders, approvals happen, payments post. In practice, the first step is where the actual work lives.

An average mid-market organization processes 2,000 to 5,000 invoices per month across dozens of vendors. Each arrives in a different format, with fields in different positions, sometimes with missing data. A finance team that tries to automate this early usually concludes it is not worth the engineering effort. The result is a process that remains almost entirely manual: an AP clerk opens an email, scans an attachment, reads the invoice line by line, and keys data into the ERP by hand.

The financial impact compounds invisibly. A clerk processes around 30 to 50 invoices per day. That is 8 to 10 minutes per invoice of pure data entry, plus rework for errors. Across 2,500 monthly invoices at an average of 40 minutes per invoice, you have roughly 1,667 labor hours per month, or 8 to 10 full-time equivalent staff just feeding data into your ERP. The opportunity cost is real: those people are doing work machines could do better.

Intelligent document processing has existed for years, but it historically demanded custom machine learning expertise or vendor lock-in to specialized platforms. AI Builder changes that. It is a low-code intelligent document processing engine built directly into the Power Platform and accessible through Microsoft Dataverse. Using AI Builder’s document intelligence model, you can teach a system to extract data from invoices, POs, or receipts, and have that extracted data automatically flow into Finance and Operations as journal entries, vendor invoices, or line items, without custom code or a separate platform.

The catch is that most implementations get the architecture wrong, deploy too early, or do not think through the business case clearly enough to justify the investment.

What AI Builder Document Intelligence Actually Does

AI Builder’s document intelligence model learns patterns from example documents. You supply 5 to 100 sample invoices, mark the specific fields you want extracted (invoice number, date, line item amounts, vendor name, cost center), and AI Builder trains a model. Once trained, it processes new invoices and extracts those fields with a confidence score for each value.

The extraction outputs structured data as JSON, which flows into Power Automate, passes to Dynamics 365 through REST APIs, or writes directly to Dataverse tables. You can build an approval workflow where extracted data is reviewed by humans, corrections are made if confidence scores are low, and once approved, the invoice posts without manual rekeying.

The critical limitation: AI Builder solves data entry, not the entire AP transformation. It does not solve the three-way match or reconciliation of discrepancies between invoice amounts and actual receipts. If invoices regularly have billing errors or missing line items, AI Builder will extract those discrepancies accurately, but human approval workflows are still required to investigate.

AI Builder also assumes reasonably stable vendor populations. If vendors send different invoice formats month to month, or you have 200 vendors across five countries with different field positions, you may need multiple models or a more flexible extraction architecture.

The Actual Implementation Costs

The common mistake is to assume that because AI Builder is “low code,” implementation cost is proportionally low. It is not.

Training a single AI Builder model requires deciding which fields are worth extracting, building a training set, and determining how much format variance the model needs to handle. You cannot build a generic model across all vendors. You have to scope it precisely. Multiple vendor formats require multiple models or accepting lower confidence scores and higher downstream rework.

The real cost sits in the integration layer. You need a Power Automate flow that ingests documents, calls the AI Builder model, handles extracted data, performs validation and enrichment (cost center lookups, amount threshold checks, purchase order verification), and posts data into Dynamics 365 Finance. That flow needs error handling, logging, and exception routing for human review. You also need to decide where documents come from: email, OneDrive, a vendor portal. Each source requires a different ingestion pattern.

A medium-complexity invoice processing automation project involving 5 to 10 major vendors, one AI Builder model, and robust Power Automate orchestration typically runs 6 to 12 weeks, roughly 300 to 600 professional services hours. At 200 USD per hour fully loaded, that is 60,000 to 120,000 USD. AI Builder licensing is usage-based at roughly 0.01 to 0.02 USD per page. An organization processing 2,500 invoices per month with 3 pages each processes 90,000 pages annually, costing 900 to 1,800 USD in consumption.

But labor savings are substantial. Saving 1,667 hours per month at 45 USD per hour fully loaded equals 75,000 USD monthly, or 900,000 USD annually. Even if net savings are 70 percent of that due to exception handling and ongoing overhead, you still have 630,000 USD in annual labor savings against a 120,000 USD implementation cost. Payback happens in 2 to 3 months.

Those numbers are achievable if, and only if, you have a focused vendor population, reasonably consistent invoice formats, and a clear baseline for how much time the manual process actually consumes. Many organizations skip that baseline measurement, build the system anyway, and then cannot measure whether it actually saved time.

Common Failure Modes

The most common failure is misalignment on scope. Finance wants to automate “all invoices.” Engineering builds one model for all vendor formats. The model trains on 50 random invoices from 20 different vendors. When it encounters a new vendor invoice, confidence scores are low, and the entire pile ends up in the exception queue. The fix: scope tightly. Start with 3 to 5 major vendors representing 40 to 60 percent of volume. Get those working first. Add additional vendors only after the core extraction pipeline is mature and stable.

The second failure is underestimating validation and enrichment workload. Once you extract data, you need to validate it. Does the date make sense? Is the vendor in the master list? Is the amount within normal range? If any check fails, the invoice needs review. Without a validation layer, you have not saved labor; you have shifted it from data entry to exception handling.

The third failure is publishing to Dynamics 365 without handling master data dependencies. A vendor invoice requires valid vendor master records, cost centers, and often purchase order references. Incomplete or inconsistent vendor master data means extraction works perfectly but posting fails because the vendor cannot be resolved. This shows up as an AI Builder problem when implementation teams do not plan for data quality prerequisites upfront.

When AI Builder Works

The use cases with clear ROI are relatively specific.

The strongest case is a company with a stable vendor population where the top 10 to 20 vendors represent 70 percent of invoice volume and use consistent invoice formats. Train one or two models for those top vendors, automate their extraction entirely, and you have converted 70 percent of invoice volume from manual to automated. The remaining 30 percent stay manual, but you have cleared the decks of high-volume repetitive work.

The second strong case is an ERP migration where the existing system has data entry backlogs. Using AI Builder to accelerate historical invoice loading during migration can meaningfully shorten timelines. Post-migration, you keep the system running for ongoing automation.

The third case is significant localization requirements, where invoices come from subsidiary companies in multiple countries and languages. AI Builder’s multilingual capabilities handle non-English documents, so you can build a single orchestration layer that routes invoices by language, extracts data consistently, and maps that data to the right cost centers based on geography.

Measuring Before Committing

Before starting, measure three things.

First, measure current invoice processing with precision. How many invoices per month? Average time per invoice from receipt to posting, broken down by task (data entry, validation, research, approval, posting)? Error rate and rework volume? These numbers should come from actual time tracking, not estimates.

Second, identify scope. Which vendors represent the top 50 percent of volume? Are their formats consistent month to month? If you extracted 20 sample invoices from your top 10 vendors, how much variation would you observe in field positions? This informs whether you need one model or multiple models.

Third, confirm you have people and tools in place. AI Builder handles extraction, but you still need a Power Automate designer, a Dynamics 365 developer, and ongoing operational ownership for the flow. If you would need to hire these resources, that cost belongs in the implementation budget.

With those measurements, the business case becomes concrete. You can calculate labor savings per month against implementation cost and decide with confidence whether the project pencils out.

AI Builder document intelligence is not a panacea for AP efficiency, but in focused scope with stable vendor populations and consistent invoice formats, it solves a real problem that costs most large enterprises hundreds of thousands of dollars per year in pure human labor. The implementation requires clarity on scope, attention to data quality, and realistic expectations about exception handling. But for the right use case, the ROI is compelling enough to build into your Dynamics 365 Finance roadmap.


Hashtags: #AIBuilder #DocumentIntelligence #InvoiceProcessing #DynamicsFinance #FinanceAutomation #DynamicsFinanceOps #RPA #PowerPlatform

Power Apps Canvas App Performance: Why Complex Apps Freeze When Users Scale

Power Apps canvas app performance optimization dashboard

“

Your production Power Apps canvas app works fine in your test environment. It handles three users, fifty data sources, and a complex UI with nested galleries and inline filters without breaking a sweat. Then, on day one of rollout, fifteen users log in simultaneously, and the app becomes unusable. Forms take twelve seconds to load. Button clicks hang for five seconds. The gallery that renders customer records falls back to client-side filtering because the data query timed out.

\n\n

This is not a platform limitation. Power Apps canvas apps can handle production workloads at meaningful scale. What you are seeing is the collision between how Power Apps executes client-side logic and how most teams design their applications without accounting for that execution model.

\n\n

The Root Cause: Client-Side Rendering and Serialization

\n\n

Canvas apps run fundamentally differently from web applications or model-driven apps. Every formula, every query, every filter logic executes on the user’s client device, not on a server. That architecture means your app’s performance depends directly on the client’s machine and network.

\n\n

When you add a data source to a canvas app, Power Apps does not just connect to Dataverse. It establishes a live connection that allows every formula in your app to query that source on demand. If you have a gallery that displays customers, a dropdown that filters by region, a text input that searches by company name, and a form that shows order history, those are potentially four independent data queries running every time the app loads or a user interacts with a control.

\n\n

The performance breakdown happens during what the platform calls \”serialization\”. Before Power Apps can display a record or filter a dataset, it must convert the data from Dataverse’s native structure into a format the client-side runtime can work with. For datasets with thousands of rows, that conversion takes time. More critically, every formula that touches a data source triggers its own serialization cycle. If your app has ten formulas that all reference the same Dataverse table, Power Apps must serialize that data ten times unless you use specific optimization patterns.

\n\n

\"Technical

\n\n

Where Filtering Fails: Server-Side vs. Client-Side Logic

\n\n

Here is where most performance problems originate: teams build apps that look correct, pass testing, and then collapse under real-world usage patterns because filtering happens on the client side instead of the server.

\n\n

Suppose you build a canvas app that displays a gallery of orders. Your gallery formula looks like: Filter(Orders, Status = DropDownStatus.Value). This appears efficient. You are filtering by a user selection. In reality, Power Apps first retrieves every order record from Dataverse, serializes the entire dataset on the client, then applies the filter in the browser. If your Orders table has 50,000 records, the app must pull all 50,000 records, serialize them, then filter to the 200 that match the selection. At that scale, this takes seconds, and if multiple users do this simultaneously, their network connections and client machines are all fighting for bandwidth and processing power.

\n\n

The solution is straightforward but requires changing how you structure your data queries. Instead of filtering after retrieval, you build the filter into the query itself using Power Apps’ connector syntax. A Dataverse connector formula that incorporates a filter directly into the retrieval statement looks like: Search(Orders, DropDownStatus.Value, \”Status\”). Power Apps sends this as a query to Dataverse, not to the client. Dataverse performs the filter before returning data. The app receives only the matching records, serializes only what it needs, and displays results in milliseconds even at scale.

\n\n

The difference is not marginal. The gap between client-side filtering and server-side filtering on a table with 10,000 records is the difference between a three-second load and a sub-second load. At 50,000 records, it is the difference between a hung interface and a responsive one.

\n\n

Data Sources and Query Optimization

\n\n

Canvas apps allow you to connect to multiple data sources simultaneously. Dataverse, SharePoint, SQL Server, Excel, external APIs through connectors. The flexibility is valuable; the performance cost of misusing it is severe.

\n\n

Each data source connection adds to the app’s startup cost. When the app loads, Power Apps must establish connections to every source you have used, even if the user does not navigate to a screen that uses that source. If your app has connections to six data sources and only uses four on the initial screen, those two unused connections still add latency to the first load.

\n\n

Worse, if your OnStart formula attempts to preload data from multiple sources, the load time becomes the sum of every query. If each query takes one second, your app takes five seconds to become usable. Add a ten-second timeout for a slow network connection, and your users wait that duration before seeing anything.

\n\n

The optimization approach is specificity. Load data only when needed, not on startup. Use button press events to trigger data retrieval rather than formulas that run when the app initializes. If you need data available immediately, implement a background load that fetches data after the initial interface renders, so the UI becomes interactive faster.

\n\n

Another common mistake is using the same data source connection for multiple independent queries. Suppose you have a single Dataverse connection and three different galleries on the same screen, each with a different filter. Power Apps may queue those queries or attempt to execute them in parallel, depending on the platform load. Under load, they serialize, and each waits for the previous to complete.

\n\n

Split this into three distinct queries using View filters or connector-level filtering, so each query is independent and the platform can optimize execution. The number of queries matters less than their independence and specificity.

\n\n

Nested Controls and Rendering Complexity

\n\n

Canvas app performance also degrades with UI complexity. Galleries within galleries, nested containers, forms with dozens of fields, and conditional visibility logic across multiple controls consume client-side resources quickly.

\n\n

Consider a gallery that displays a list of customers. Inside that gallery, each row contains a nested gallery of orders for that customer. When the outer gallery renders 20 rows, and each row triggers a nested gallery query, the app is running 20+ queries simultaneously. If each query takes 500 milliseconds, the nested galleries take ten seconds to fully render. Users see a partial interface, then fields populate gradually as nested queries complete.

\n\n

The performance cost of nested galleries is compounded by the fact that each nested gallery runs queries independently. Unlike server-side joins, which a SQL database performs as a single operation, nested galleries in Power Apps are a series of sequential and parallel queries on the client.

\n\n

The mitigation strategy depends on your scenario. If you truly need nested data, consider using a model-driven app instead, which executes queries server-side and handles nested relationships more efficiently. If a canvas app is required, limit nesting to one level, implement pagination so only visible rows query their nested data, and use delegation-aware formulas that tell Power Apps to push the nested query logic to the data source instead of executing it on the client.

\n\n

Testing at Scale

\n\n

Testing a canvas app with three users and 1,000 test records tells you nothing about its performance with 30 users and 100,000 production records. Teams often discover performance problems on launch day because they did not test at realistic scale.

\n\n

Before rolling out a production app, stress-test it with the expected peak concurrent user load and the actual data volume. If you expect 25 concurrent users and your Dataverse table has 50,000 records, your test environment must reflect that. This means populating test tables with production-scale data and asking multiple testers to log in and use the app simultaneously.

\n\n

Pay attention to what happens during those peak loads. Which operations slow down. Which queries time out. Whether the app becomes unresponsive or degrades gracefully. These observations guide your optimization priorities.

\n\n

Practical Optimization Checklist

\n\n

Apply these patterns to avoid the most common performance pitfalls. First, push filtering and sorting to the data source, not to the client. Use connector-level query parameters instead of post-retrieval formulas whenever possible. Second, minimize startup data retrieval. Load only what is necessary on app start, and defer everything else. Third, avoid nested galleries. If nested data is unavoidable, implement pagination and lazy loading. Fourth, limit the number of data source connections and preload only the data you actually use. Fifth, test at production scale, not at test scale.

\n\n

Most canvas app performance problems are not platform bugs. They are design choices that work at small scale and break at large scale. Understanding the difference between client-side and server-side execution, and designing your app around that reality, is what separates apps that work and apps that scale.

\n\n


\n\n

About Routeget Technologies

\n\n

Routeget Technologies helps enterprises architect and implement scalable Power Platform solutions. If your Power Apps performance problems are holding back a rollout or affecting user adoption, our team can help you redesign and optimize your apps for production workloads. Reach out for a consultation.

\n\n

#PowerAppsPerformance #CanvasAppOptimization #PowerPlatformDevelopment #ClientSideRendering #DataverseOptimization #PowerAppsGalleries #EnterpriseApplications #Dynamics365Integration

\n”

Project Profitability in Dynamics 365 Project Operations: Why Your Project Margins Fail Without Proper Accounting Setup

Dynamics 365 Project Operations financial dashboard showing project profitability metrics

A professional services firm running Dynamics 365 Project Operations pulls its monthly margin report and finds something that doesn’t match reality on the ground. One fixed-price engagement shows a 60 percent margin despite the delivery team saying they’ve been slammed for weeks. Another time-and-materials project shows a loss even though every hour logged was billed. Nobody misused the system. Nobody entered a wrong number. The transactions are all correct, and the margins are still wrong, because project profitability in Dynamics 365 Project Operations is decided by the accounting setup behind those transactions, not by the transactions themselves.

Dynamics 365 Project Operations financial dashboard showing project profitability metrics

Two Price Lists, One Easy Mix-Up

Project Operations resolves cost and revenue through separate price lists, and the distinction matters more than the name suggests. A cost price list resolves the rates used on cost-type estimate and actual transactions, essentially what a resource actually costs the business. A sales price list resolves the rates used on the billed and unbilled sales side, essentially what gets charged to the customer. Each is set to a context, Cost or Sales, and that context governs how the system looks the record up. Set a list to the wrong context and price resolution simply fails to find a rate where one should exist.

Sales price lists carry another constraint cost lists don’t: they’re locked to the currency defined on the list header, while cost price lists can hold role prices in other currencies through user setup overrides. That asymmetry catches multinational firms more often than it should, particularly when a role price gets added to a sales list in the wrong currency and the transaction silently falls back to a default rate instead of erroring out. Sales price lists also have to be explicitly attached, to a customer’s project price list, a project quote, or a project contract, before they apply to anything; a rate sitting correctly configured but never attached to the contract in play won’t be used. Add date ranges into the mix, since price lists apply based on start and end dates, and a gap between two lists means a stretch of transactions with no applicable rate at all.

Where Margin Actually Gets Decided

Price lists set the numbers going into a transaction. What happens to those numbers on the ledger, which is what actually produces a margin figure, is governed by a separate configuration object: the project cost and revenue profile, found under Project management and accounting, Setup, Posting. This is the part of the setup that gets underinvested in relative to how much leverage it has over reported profitability.

The ledger settings on a profile decide, transaction type by transaction type, hour, expense, item, whether costs post straight to the profit and loss statement or sit on the balance sheet as work in progress until someone runs a separate posting step. They also decide whether on-account, milestone-based invoicing lands in a balance account or a P&L account, and whether unbilled revenue gets accrued to the general ledger at all. None of these settings are visible on the transaction itself. A time entry looks identical whether its hours are configured to post immediately or to wait in WIP, which is exactly why a wrong setting here doesn’t throw an error. It just quietly changes what shows up as margin.

Finance professional reviewing project accounting and cost allocation data

Fixed-Price Work Needs Its Own Logic

Time-and-materials projects recognize revenue roughly as work happens, so the profile settings above cover most of what matters. Fixed-price projects need an additional layer, because the billing schedule and the actual delivery pace are two different things, and the whole point of the accounting setup is to keep them from contaminating each other. Project Operations offers three methods here. Completed contract holds all revenue and cost recognition until the project finishes, carrying everything as WIP in the meantime. Completed percentage accrues revenue periodically based on how much of the project is actually done, using cost templates to group transactions for the percentage-complete calculation and period codes to set how often that calculation runs. No WIP skips the deferral entirely and is meant for short engagements where invoicing and cost recognition happen close enough together that deferral adds nothing but complexity.

A firm running long, milestone-heavy fixed-price engagements under a “no WIP” setup, because that was the default nobody revisited, will see revenue and cost recognized in whatever period the invoice happens to fall in rather than the period the work actually happened in. Margins swing from project to project not because delivery efficiency is inconsistent, but because the accounting method assumes short-cycle work being applied to long-cycle contracts.

Five Specific Ways This Goes Wrong

A handful of misconfiguration patterns show up repeatedly enough to be worth naming directly. A billing method mismatch, where time is set to fixed-price logic on what’s actually a time-and-materials engagement, or the reverse, throws off exactly when hours or expenses hit revenue relative to when they’re billed. A missed manual step is just as damaging: when hour or expense costs are set to post to a balance account rather than profit and loss, someone has to run the “post costs” function to move them into P&L, and if that step is skipped, costs simply never show up against revenue, producing a margin that looks better than it is. A mismatched revenue recognition method does similar damage from the other direction, completed contract selected on the profile while revenue is somehow still being accrued on a monthly cadence, which mismatches costs and revenue by period and makes margins swing without any real change in delivery.

The accrual settings create a subtler trap. Revenue accrual turned on for a time-and-materials engagement whose cost posting is set to “no ledger” produces transactions where revenue is recognized but the matching cost is never posted anywhere, which can show as a margin approaching 100 percent on paper. And on-account invoicing routed to a profit and loss account instead of a balance account recognizes milestone billings as revenue immediately, ahead of the delivery they’re meant to represent, front-loading margin into whichever period the invoice happens to land in.

Getting Project Profitability Right Before the Numbers Matter

None of this is complicated once it’s named, but it has to be checked deliberately rather than assumed. Start by confirming which billing method, time-and-materials or fixed-price, is actually assigned to each active profile, and cross-check that against how the contracts using that profile are actually structured. Walk the ledger settings for each transaction type and confirm someone owns the recurring job of running the “post costs” function if any type is set to balance posting, since that step doesn’t run itself. For fixed-price work, match the recognition method to the actual shape of the engagement rather than the platform default, short and simple work can reasonably use no WIP, but anything spanning multiple billing cycles needs completed percentage with cost templates that actually reflect how the project’s cost mix is structured. Finally, verify that profile assignment rules, by contract, project group, or individual project, are actually routing each engagement to the profile that matches how it’s billed, since a firm running several contract types often has profiles that were configured correctly once and then silently misapplied as the portfolio grew.

Routeget Technologies has walked in behind project-based businesses whose delivery teams were being blamed for margin problems that turned out to live entirely in the posting configuration, not the work. Reconciling that gap usually takes a focused audit of the profile settings against a sample of actual contracts, not a re-implementation, and it tends to be one of the highest-leverage half-days a Project Operations environment can spend.


#ProjectProfitability #ProjectAccounting #ProjectOperations #RevenueRecognition #WIPAccounting #CFOStrategy

Distributed Order Management Date Logic in Dynamics 365: Why Your Order Promise Dates Don’t Match Fulfillment Reality

Distributed Order Management dashboard showing fulfillment network optimization

A CFO at a mid-market distributor implemented Distributed Order Management in Dynamics 365 Supply Chain Management expecting it to automatically optimize which warehouse fulfilled each order. Six weeks after go-live, order promise dates started slipping consistently beyond what the fulfillment network could actually deliver. The system promised customers Friday delivery, but warehouse capacity and transit times said Tuesday was realistic. The DOM configuration looked correct on paper, but something in the date calculation logic wasn’t aligning with how the fulfillment network actually worked.

This scenario repeats across Dynamics 365 implementations. Distributed Order Management is powerful, but the interaction between order promise date logic, inventory allocation, and fulfillment location rules creates a complexity that most teams underestimate. The system doesn’t fail loudly; it simply generates commitments that the supply chain can’t keep.

How DOM Calculates Order Promise Dates

Distributed Order Management dashboard showing fulfillment network optimization

Distributed Order Management in Dynamics 365 uses a specific sequence when evaluating whether an order can be fulfilled. First, DOM checks inventory availability across fulfillment locations based on allocation rules you configure. Then it calculates a delivery date by adding transit time from the selected warehouse to the delivery address. Finally, it compares that calculated date against your order promise date policy. If the fulfillment location can deliver within the promised window, the order is allocated there. If not, DOM tries the next location in the rule priority sequence.

The order promise date itself is typically set during order entry, usually based on a default lead time from your Sales module or a customer-specific agreement. That date becomes a hard constraint in DOM’s allocation logic. If no warehouse can deliver by that date, DOM marks the order as unallocated, and a manual intervention becomes necessary.

The problem emerges when your order promise date policy doesn’t account for the actual distribution network topology. Many teams set promise dates based on what customer expectations are, not what the fulfillment network can physically deliver. You might promise Friday delivery in all cases, but your nearest warehouse to a particular delivery address is two days away by standard transit. DOM will correctly refuse that allocation, but the order is already in the system with a date you can’t keep.

Common Date Logic Failures

Transit time configuration is the first place this breaks. Dynamics 365 allows you to define transit times between fulfillment locations and delivery addresses using distance-based or location-based rules. If your transit time matrix is incomplete or uses broad assumptions (for example, assuming all addresses in a state can be reached in one day), DOM will calculate delivery dates that don’t match reality. A customer in a remote area might be assigned a warehouse that’s technically capable of shipping, but the transit time estimate is wildly optimistic.

Inventory allocation sequencing compounds the issue. DOM prioritizes fulfillment locations based on rules you define, often weighted toward nearest warehouse or lowest cost. If your highest-priority warehouse has zero inventory but a high promised delivery date policy, DOM may skip it and try a lower-priority location further away. That second location might have inventory, but if its transit time exceeds your order promise date, the order goes unallocated. Your first-choice warehouse would have delivered on time, but it was out of stock.

Lead time inclusion creates another layer of complexity. Some organizations include a buffer in their order promise dates to account for order processing and picking time at the warehouse. Dynamics 365 allows this through the delivery date offset configuration in DOM rules. If that offset is set incorrectly (too small or too large), the system either promises dates that include warehouse processing time that doesn’t exist, or it excludes processing time that’s actually required, causing fulfillment failures when the order reaches the warehouse and needs to be queued.

Customer-level promise date overrides can also break assumptions. You might configure DOM with a global 5-day promise window, but a contract with a specific customer guarantees 3-day delivery. If that override isn’t captured in your fulfillment location rules or priority weighting, DOM will allocate to a warehouse that can deliver in 4 days, violating the contract.

Diagnosing What’s Actually Happening

Modern warehouse fulfillment center with inventory management operations

The DOM allocation trace in Dynamics 365 is your primary diagnostic tool. When an order fails to allocate, you can review the detailed trace that shows which fulfillment locations were evaluated, in what order, and why each was rejected or selected. This trace will show you if DOM was considering a warehouse that’s 800 miles away when one 50 miles away was available, or if it rejected a capable warehouse because of a date mismatch.

Run a date audit on recent orders. Compare the promised delivery date in the order against the calculated fulfillment date from the allocating warehouse. If most discrepancies are 1-2 days, your promise date policy is probably out of sync with network capability. If discrepancies are random and larger, your transit time matrix or delivery date offset configuration needs review.

Test your fulfillment location rules under load. DOM’s behavior changes when multiple orders are competing for the same inventory. Create test orders representing different geographic regions and order volumes, then check whether DOM’s allocation recommendations make sense. A warehouse that looks ideal in isolation may become bottlenecked when handling actual volumes, and DOM doesn’t account for capacity constraints in its date calculations, only inventory availability.

Fixing the Fundamental Mismatch

Start by establishing what your supply chain can actually deliver. Map your fulfillment locations, typical inventory levels, and genuine transit times (not best-case, but realistic). Document customer-specific commitments and contract terms separately from default policies. This foundation is non-negotiable.

Configure DOM’s promise date policy to match this reality. If your farthest delivery address is 4 days by ground from your nearest warehouse, your default promise date can’t be 2 days. If you want to offer 2-day delivery, you need inventory positioned closer to that customer or expedited shipping available. The promise date is a hard constraint in DOM’s logic, and you can’t configure your way around physics.

Use delivery date offsets intentionally. Set offset values to match actual warehouse processing and handling time, not to pad margins or squeeze perceived cost. A 1-day offset means that when DOM calculates a delivery date, it subtracts 1 day from the available time window to account for warehouse operations. If your actual processing time is 1 day, use 1 day. If you set 2 days to add safety margin, you’ll miss valid allocation opportunities and generate unallocated orders.

Test with real order patterns before relying on DOM for critical orders. Run a pilot allocation cycle using your actual customer set and geographic distribution. Let DOM run without overriding individual allocations, then measure how many orders allocate successfully and how many miss their promise dates. That result tells you whether your configuration is grounded in supply chain reality or wishful thinking.

Implementation Considerations

DOM becomes more valuable when it’s working with accurate constraints, not fighting against them. The system will allocate orders optimally, but only within the bounds you set. If those bounds don’t match physical reality, you’re asking DOM to solve an impossible problem, and the system will fail in ways that look like bugs but are actually configuration problems.

Many teams discover this only after going live and watching order dates slip. By then, you’re rewriting promise date policies, adjusting transit times, and managing customer expectations, all while DOM continues to make allocation decisions based on outdated assumptions. The cost of getting this wrong extends beyond supply chain operations into customer service and revenue recognition, where promise dates become contractual commitments.

The solution isn’t complex, but it is foundational. Your Dynamics 365 implementation needs to start with an honest assessment of what your fulfillment network can deliver, then configure DOM to work within those constraints. When you do, the system’s optimization capabilities become genuinely valuable. When you don’t, you’re managing conflict between a system trying to allocate optimally and a supply chain that can’t deliver on what it’s promising.


#DynamicsSupplyChain #DistributedOrderManagement #DOM #SupplyChainOptimization #D365SCM #FulfillmentLogistics #InventoryAllocation #OrderManagement #SupplyChainTechnology

AI-Powered Lead Scoring in Dynamics 365 Sales: Turning Raw Data Into Revenue Priority

Your sales team has access to thousands of leads. The problem is not finding prospects; it is identifying which ones are worth the time of your most expensive salespeople. Most organizations still rely on a combination of manual CRM notes, email volume, and gut feel to determine which leads get attention. The result is predictable: sales reps work randomly through their pipeline, cold accounts consume their bandwidth, and opportunities grow stale while tier-two prospects wait.

Dynamics 365 Sales, combined with AI Builder and Power Automate, offers a practical alternative: automated lead scoring that continuously evaluates prospect behavior and intent signals, surfacing the highest-probability deals to your team. This is not a generic tactic; it is a specific system that assigns numerical scores to every lead based on your own historical conversion data, and then uses those scores to automatically route, prioritize, and stage deals. For many midsize and enterprise sales organizations, implementing this correctly compresses sales cycles, improves win rates, and frees your team to focus on closing rather than hunting.

Why Scoring Beats Instinct (And Why Dynamics 365 Is the Right Platform for It)

Lead scoring rests on a simple premise: your best leads look like your past best deals. If you can identify the early signals that characterized your won deals, you can apply those same signals to your pipeline in real time.

In practice, scoring requires three things. First, you need historical data: a clean set of opportunities that closed as won, complete with the lead source, company size, industry, engagement pattern, and other attributes that came before the win. Second, you need an algorithm that maps those attributes to probability. Third, you need a system that applies that scoring continuously, updates scores as new activity arrives, and feeds the results back to your sales team in a way they actually use.

Dynamics 365 Sales provides all three. The platform already holds your historical opportunity data and your lead attributes. AI Builder, Dynamics’ no-code machine learning tool, can ingest that historical data and generate a scoring model without requiring you to hire data scientists or build a custom pipeline. Power Automate can then apply that model to every new lead and opportunity, and can automatically update scores as activity accumulates. The result is a lead scoring system that lives inside the CRM where your team already works, rather than in a separate tool that requires them to toggle between windows.

For a sales leader, the advantage is clear. A scoring model trained on your own data will reflect your unique sales motion, your typical deal cycle, and the specific attributes of your market. An off-the-shelf scoring engine, by contrast, is built on generic B2B assumptions that may not match your business at all. When you train your model on your own closed deals, your salespeople are more likely to trust the scores, and they are more likely to act on them. That trust translates to adoption, and adoption translates to impact.

The Lead Scoring Workflow: How It Works in Practice

Setting up automated lead scoring in Dynamics 365 requires clear thinking about what you are trying to score and how you will use the scores once they are calculated.

Start with definition. Decide whether you are scoring leads (unconverted prospects) or opportunities (qualified leads that have entered your formal sales process), or both. Most organizations score at the opportunity level, because that is where actual revenue potential becomes measurable. Define your target variable: are you predicting whether a deal will close, or are you predicting deal size, cycle length, or the probability of a specific outcome?

Next, assemble your training data. Go back through your closed opportunities for the past 12 to 24 months. For each closed opportunity, document the attributes that were visible early in the deal: company industry, company size (headcount or revenue), whether they came from inbound or outbound marketing, how many email interactions occurred before the first sales conversation, whether a technical evaluation took place, how many stakeholders were involved. Then add the outcome: did the deal close? For closed-won deals, record the deal size and the time from initial contact to close.

This is the dataset that AI Builder will learn from. The more historical data you assemble, the more reliable the model. If you have fewer than 50 closed-won deals in your history, scoring will be difficult; if you have 200 or more, you have strong signal.

Upload that dataset into a spreadsheet or a Dataverse table, or connect AI Builder directly to your Dynamics 365 opportunity list. AI Builder’s automated machine learning will ingest the historical data, identify which attributes most strongly correlate with closed-won outcomes, and generate a scoring model that assigns a probability to new opportunities based on their current attributes.

Once the model is trained and validated, use Power Automate to apply it. Create a cloud flow that triggers whenever a new opportunity is created or whenever an activity is recorded against an existing opportunity. The flow calls the AI Builder scoring model, collects the predicted score, and writes it back to the opportunity record in a custom Score field. You can also set up automatic actions triggered by score thresholds: when an opportunity crosses above 70% probability, automatically assign it to your top sales rep and send a summary email to the sales manager.

The Business Case: Impact You Can Measure

The value of lead scoring shows up in three areas, all measurable.

First, sales team efficiency. When leads are scored and routed based on probability, your best salespeople spend their time on high-probability deals rather than randomly working through a queue. In practice, this often means a 20 to 30 percent reduction in the time spent on early-stage qualification, and a corresponding increase in the number of high-value conversations happening per week. You are not changing headcount; you are redistributing where existing salespeople spend their effort.

Second, pipeline velocity. Deals that are accurately scored tend to move through your pipeline faster. Sales reps focus on moving high-probability deals to close, rather than keeping stalled opportunities open indefinitely. Early action on low-probability deals (either aggressive qualification or formal disqualification) clears the pipeline and keeps your forecast clean. For a $10 million sales organization, even a modest acceleration of your average deal cycle by 10 to 20 percent can add millions of dollars to annual revenue.

Third, forecast accuracy. When leads are continuously scored based on consistent criteria, your sales managers can forecast pipeline with much greater confidence. Instead of relying on a subjective assessment of deal status, managers can look at the aggregate score distribution of their pipeline and predict with reasonable accuracy what will close. This precision becomes particularly valuable if you operate with quota management, revenue recognition, or board-level reporting that requires predictability.

Common Mistakes and How to Avoid Them

Most organizations do not fail to deploy lead scoring; they fail to deploy it correctly, and then they abandon it.

The most common mistake is training a model on data that is too thin or too old. If your training set includes only 20 closed opportunities, or if those opportunities closed more than three years ago, the model will perform poorly on new data. Build your training dataset deliberately. If you have a young sales organization with limited historical data, start with a smaller set of attributes that you are confident are predictive (perhaps company size, industry, and sales motion source), and plan to retrain the model every six months as you accumulate more closed deals.

The second mistake is treating the score as a rank. Sales reps sometimes interpret a lead with a 65% score as inferior to one with an 80% score, and deprioritize it accordingly. In reality, both are valuable; the difference is risk profile. A 65% score means the deal has a reasonable chance of closing, but with more uncertainty. A 80% score means the deal is more likely to close, but may be smaller or further away. Train your team to interpret scores as probability, not hierarchy, and to view all scores above your qualification threshold (typically 50 to 60%) as worthy of active pursuit.

The third mistake is deploying the score without changing your process. Simply displaying a score in Dynamics 365 will not change behavior; salespeople will ignore it if it feels disconnected from the way they work. Instead, wire the score into your sales process. Use it to trigger automatic task assignments, to rank leads in your daily view, or to flag deals that have stalled despite a high score. Make the score a structural part of your daily work, not a novel data point that sits on the side.

Getting Started: The First 90 Days

If you decide to implement lead scoring, plan for a three-month project. Weeks one and two focus on data assembly. Work with your finance and sales operations teams to pull together your closed opportunity history, verify data quality, and prepare the training set.

Week three covers modeling. Upload your data to AI Builder, train a scoring model, and validate it against a holdout sample of historical data. Most models will achieve 70 to 80% accuracy on historical data; that is expected.

Weeks four through six focus on integration. Build the Power Automate flow that applies the model to new opportunities and activities. Set up automatic actions. Write a short guide for your sales team explaining what the scores mean and how to use them.

Weeks seven through 12 are deployment and refinement. Roll out scoring to your team. Collect feedback. Monitor which leads are being acted on and which are being ignored. Refine your thresholds. After 90 days, pause and evaluate: did sales cycle compress? Did revenue increase? Did forecast accuracy improve? Use those results to decide whether to expand the model or refine it further.

Conclusion

AI-powered lead scoring in Dynamics 365 Sales is not a futuristic concept; it is a practical system available to any sales organization with 50 or more closed deals and the willingness to spend 12 weeks implementing it. The payoff is significant: freed-up sales time, faster deals, and more predictable revenue. For sales leaders tasked with improving efficiency without adding headcount, or for IT leaders evaluating how to deliver business value from Dynamics 365, a lead scoring implementation offers measurable, defensible ROI.

At Routeget Technologies, we have built lead scoring systems for dozens of Dynamics 365 organizations. The implementation patterns we have learned apply to most sales organizations: start with clean historical data, train a model conservatively, integrate it into your daily sales process, and refine over time based on real results. If your sales team is currently managing leads by feel or by gut, a data-driven approach to prioritization will likely produce immediate impact.


#Dynamics365Sales #AILeadScoring #SalesEnablement #AIBuilder #SalesOptimization #CRM #LeadManagement #SalesAutomation

Designing Dynamics 365 for Enterprise: Why Customization Strategy Decides Success, Not Implementation Speed

Enterprise architecture diagram for Dynamics 365 customization strategy

Designing Dynamics 365 for Enterprise: Why Customization Strategy Decides Success, Not Implementation Speed

Your implementation partner is confident they can deploy Dynamics 365 Finance in 16 weeks, on budget, with minimal customization. Your CIO is skeptical. What everyone is missing is that 16 weeks of deployment velocity means nothing if the system cannot flex to meet the specific financial workflows, reporting requirements, and exception-handling logic that actually run your business. This article walks through the decision-making framework that separates Dynamics 365 implementations that maintain competitive advantage from those that lock you into inflexible process conformity.

Enterprise architecture diagram for Dynamics 365 customization strategy

The Cost of Standardization Without Strategy

When large organizations adopt Dynamics 365, they encounter a genuine constraint that smaller implementations never face. Standard Dynamics 365 processes are designed to handle typical transactional patterns: create a sales order, post inventory, record journal entries, close a period. These processes work well in companies where financial and supply chain operations follow recognizable routines. For organizations with complex subsidiaries, multiple legal entities, specialized revenue recognition requirements, or consolidated financial structures, the gap between standard functionality and operational reality can be substantial.

The temptation is to close that gap quickly. Customize first, ask questions later, implement the feature, move on. Partners and consultants work under schedule pressure; executives care about go-live dates. But what you are actually deciding during that 16-week window is whether Dynamics 365 will grow with your business or become a limitation on it. Quick customization often leaves a system that works once but breaks when operational volumes increase, subsidiary structures change, or new products with different financial characteristics are introduced.

The alternative, often recommended as the responsible path, is to conform your business processes to Dynamics 365’s out-of-the-box design, accepting some operational inefficiency as the cost of system stability and supportability. In many cases this is the right choice. But conformity also has costs that don’t appear on project budgets. Your finance team works longer hours to reconcile Dynamics 365’s assumptions against reality. Your reporting becomes a collection of workarounds rather than a source of truth. And when the next acquisition brings new compliance requirements or new product portfolios, the system lacks the extension points to accommodate them without a redesign.

What does decide success is a third path: designing your customization strategy during the planning phase, before implementation begins. That strategy takes into account which aspects of your business must remain flexible and which can safely conform to industry standards. It identifies the specific extension points within Dynamics 365’s architecture where customization will add the most value for the least technical risk. And it builds a system that can absorb change without constant rearchitecture.

Where Customization Creates Value Versus Where It Creates Debt

Enterprise Dynamics 365 implementations typically divide customization work into three categories. The first, which most organizations handle well, is creating reports and dashboards that show business leaders what is actually happening in the system. Power BI integration has made this category straightforward and low-risk. The second category is integrating Dynamics 365 with adjacent systems: supply chain planning, human capital management, third-party analytics, specialized industry platforms. This category is partially standardized through common APIs, but it still requires engineering effort to match data semantics and handle edge cases.

Enterprise architecture dashboard with analytics and workflow components

The third category is where implementation strategy becomes critical. This is the customization of Dynamics 365’s own business logic: approval workflows, financial period close sequences, consolidation logic for multi-entity structures, asset depreciation rules, tax calculation approaches. This category is where quick implementations often stumble. An approval workflow that works during initial deployment may become a bottleneck once volume increases. A period-close automation that works for a single legal entity with straightforward inter-company transactions becomes fragile when the organization acquires a subsidiary with different accounting standards.

The decision-making framework starts here: before implementation begins, your enterprise architects and finance leaders should identify which of these processes are truly core to competitive differentiation and which can safely standardize. A manufacturing company with a proprietary approach to cost allocation across multiple production facilities needs flexible and sophisticated costing logic. It is worth customizing Dynamics 365 to accommodate that approach because it is a source of actual competitive advantage. A company that follows standard industry costing practices might adopt Dynamics 365’s defaults and apply engineering effort elsewhere. The distinction seems obvious once stated, but most implementations conflate two different questions: “What does our business need?” and “What can we afford to build?”

Building Sustainable Extensibility Into Your Architecture

Once you have identified where customization creates value, the question becomes how to build those customizations in a way that survives the company’s evolution. This is the point where many implementations fail, not because the customizations are poorly written, but because they are designed for a static set of requirements rather than a dynamic business landscape.

Sustainable Dynamics 365 customization relies on a small set of architectural practices that most standard implementations skip. The first is establishing a clear boundary between custom logic and core system behavior. Dynamics 365 provides multiple layers where you can extend functionality: metadata-driven configuration, business process flows for structured automation, plugins for deep system logic, and custom APIs for discrete operations. Each layer has appropriate use cases, and mixing them creates brittle systems that become impossible to maintain as requirements change. Your architecture should establish which customization layer you will use for each category of logic, and it should enforce that decision consistently across the implementation.

The second practice is designing for data portability and reporting independence. The most consequential decision you make during implementation is how custom data structures interact with standard Dynamics 365 tables. Custom tables often make sense for capturing business-specific information, but they need to be designed from the start as if they might need to move to Power BI, external data warehouses, or downstream systems. This means using consistent naming conventions, avoiding gratuitous denormalization, and exposing data through defined APIs rather than direct database access. This sounds like overhead during implementation, but it becomes the difference between a system that can evolve and one that becomes increasingly brittle.

The third practice is establishing a plugin and API governance model before the first line of custom code is written. Plugins in Dynamics 365 give you profound power to intercept and transform business logic, but they also create opportunities for cascading failures if not managed carefully. A plugin that modifies financial data should have well-defined preconditions and should fail safely rather than partially. This requires treating plugin logic as mission-critical software, with corresponding standards for error handling, logging, and monitoring. Many organizations discover this requirement only after a plugin failure causes data corruption or blocks period close.

The Timeline Problem: Speed Versus Sustainability

The financial incentive structure in most implementations creates pressure to prioritize speed over sustainability. Consultants are paid for hours, not for long-term system stability. Partners succeed when projects go live on schedule, not when systems remain flexible three years later. This creates an alignment problem between what consultants build and what enterprises actually need.

The remedy is to invest in architectural review and governance at the beginning of the implementation, not at the end. This means dedicating time during planning to document which Dynamics 365 capabilities will be used as-is, which will be customized and why, and which are being bypassed in favor of external systems. It means establishing plugin standards and API governance before the technical team begins coding. It means creating a small architecture review board that reviews major customization decisions and blocks implementations that do not align with the agreed strategy.

This sounds like adding overhead to an already-complex project, and in terms of pure calendar time, it does. But the payoff is in the years that follow. When your organization expands into new markets and needs to onboard a subsidiary with different accounting structures, a well-designed Dynamics 365 foundation can usually accommodate that through configuration and targeted customization. A poorly-designed one requires rearchitecture. When regulatory requirements change and you need to modify financial period-close logic, a system built on clear customization boundaries can adapt. One without those boundaries often cannot.

Deciding What to Do Right Now

If you are in the early stages of Dynamics 365 planning, the most valuable action is to bring your architects and business leaders into the conversation about customization strategy before implementation begins. Do not let this decision be made implicitly by consultants optimizing for schedule. If you are mid-implementation and realizing that customization decisions are being made tactically rather than strategically, it is not too late to step back and establish architecture governance.

The enterprise that succeeds with Dynamics 365 is not necessarily the one that goes live fastest. It is the one that understands, before implementation, which parts of its business need to remain flexible and builds a system architecture that protects that flexibility. That requires more planning, more discipline, and more serious engagement with technical architecture decisions. It also results in a system that still works years later when your business has changed in ways you could not have predicted during implementation planning.

This is not a problem that faster implementation or lower-cost consulting can solve. It is a problem that requires CIOs and enterprise architects to make genuine strategic choices about where customization creates value and where it creates technical debt. The organizations that make those choices deliberately are the ones that get long-term value from Dynamics 365. The others end up managing the consequences.

Topics: #Dynamics365Architecture #EnterpriseCustomization #Dynamics365Strategy #CustomizationStrategy #EnterpriseERP #Dynamics365Implementation

Dynamics 365 Finance Month-End Close: Why Manual Review Processes Eat Three Weeks of Your Finance Team’s Time

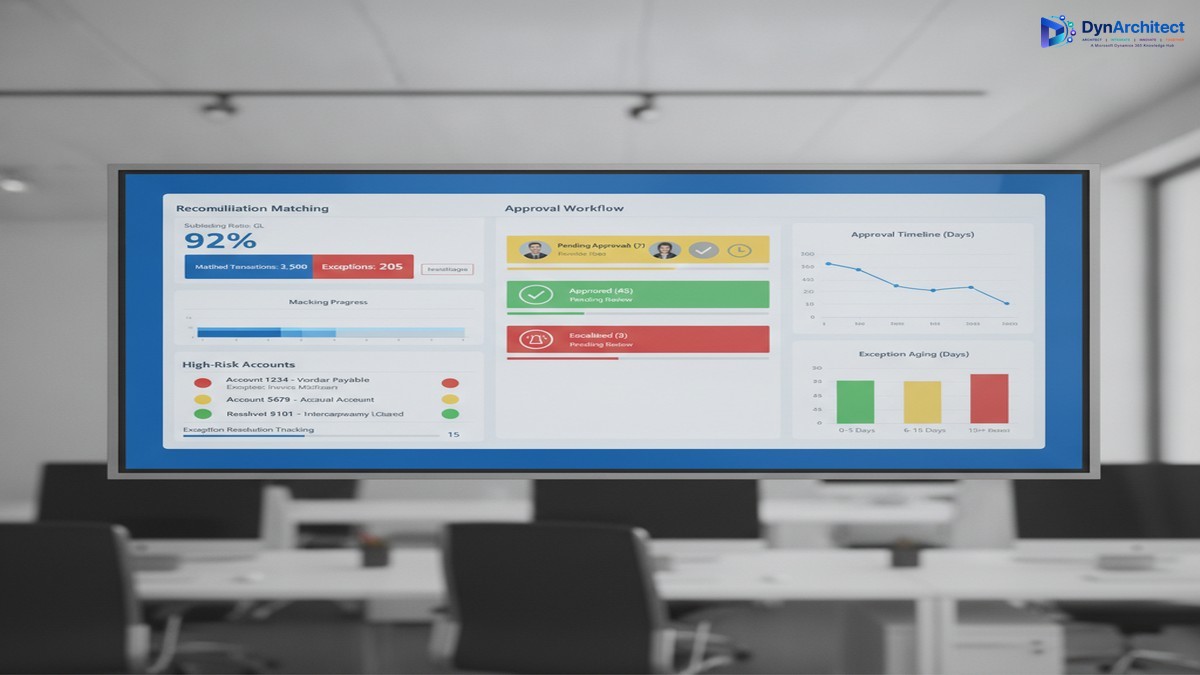
Dynamics 365 Finance month-end close dashboard with reconciliation and approval workflows

Your CFO expects the month-end close to take five business days. Your finance team knows it will take at least three weeks, if nothing breaks. Neither estimate is wrong, but the gap between them exposes a concrete operational problem that Dynamics 365 Finance can address—if you design the close process deliberately rather than simply importing Excel workflows into a new system.

The root cause isn’t Dynamics 365 Finance’s fault. It’s that most organizations have never mapped the actual work their finance team performs during month-end close, and they transfer that unmapped work directly into D365 Finance, where the same manual reviews and exception-handling steps consume the same time, just now in a new interface. This article walks through the hidden work that extends close cycles and the specific D365 Finance capabilities that can compress it without sacrificing control.

The Hidden Work in Month-End Close

Finance teams perform three categories of work during month-end close: transactional, reconciliation, and review and approval. The first category moves quickly in Dynamics 365 Finance because transactional posting, reversal, and period closing are automated. The second category, reconciliation, is where most organizations find that D365 Finance has given them new tools but not a fundamentally different process. The third category, review and approval, is where the real bottleneck sits.

Reconciliation requires matching subledger balances to the general ledger and resolving differences. In Excel, this meant exporting general ledger data to a spreadsheet, exporting subledger data to another spreadsheet, and then manually or with crude formulas, finding and categorizing exceptions. In Dynamics 365 Finance, you have automated reconciliation matching, but it still requires manual exception review if a transaction doesn’t auto-match due to timing, rounding, or data misalignment. Many organizations don’t implement the reconciliation matching engine at all, and instead build custom reconciliation reports that they then export and manually review in Excel. That defeats the purpose. Organizations that do implement reconciliation matching still need a process to review and approve the remaining exceptions. If your exception resolution process is ad-hoc (email threads, informal approvals, updates made directly to the database by whoever has time), month-end close becomes a game of whack-a-mole where resolving one exception creates new work elsewhere.

The review and approval stage is where time collapses. At this stage, the close is technically complete from a system perspective—all journal entries have posted, all subledgers have been reconciled, and all accounts have been reviewed—but finance leadership has not yet signed off. This is where your CFO’s five-day close hits the wall. The approval process usually means compiling reports, distributing them via email, waiting for responses, and manually tracking who has signed off and who is still reviewing. If a reviewer finds an error, the journal entry gets reversed, the approver list gets longer, and the cycle starts again. If multiple reviewers work simultaneously without a structured change-control process, they may unknowingly create conflicting updates.

Dynamics 365 Finance month-end close dashboard with reconciliation and approval workflows

Why Dynamics 365 Finance’s Tools Don’t Automatically Solve This

Dynamics 365 Finance has features that address each of these stages. It has reconciliation matching for subledger-to-GL matching. It has a journal approval workflow that routes entries to approvers. It has role-based security so that only authorized users can post to specific accounts or cost centers. But implementing these features doesn’t automatically translate to a faster close if the underlying process is not designed first.

The most common implementation pattern is this: the team implements D365 Finance features directly as they exist, with minimal process redesign. The reconciliation matching engine gets enabled but with no workflow for resolving exceptions. The journal approval workflow gets configured but with a long approval chain that mirrors the existing email-based approval process—five to ten approvers in sequence, each seeing the full entry list and taking days to respond. The role-based security gets configured but not used strategically to separate data entry from approval, so reviewers still spend time wading through draft entries they didn’t create.

The result is that Dynamics 365 Finance executes the existing process more efficiently at the transactional level but doesn’t reduce the actual elapsed time, because the transactional work was never the bottleneck. The bottleneck is the manual review and approval stage.

Structural Changes That Compress the Close Without Cutting Corners

Three structural changes to your close process, combined with deliberate use of D365 Finance features, can reduce elapsed close time from three weeks to ten to twelve business days while improving control and auditability.

The first change is to separate data entry from approval. Assign data entry (journal posting, subledger reconciliation, exception resolution) to one team and approval to another team that has not touched the data being approved. This isn’t a new idea, but Dynamics 365 Finance makes it operationally feasible. Your reconciliation team can mark exceptions as resolved in the reconciliation matching workspace, but the approval team (the controller, the finance director, or a designated approval group) can see which exceptions were resolved and review them before the general ledger is locked. By structuring permissions so that data entry users cannot post approved entries directly, and approval users see only high-level summaries plus exceptions, you cut the time approvers spend searching for relevant data. A 30-minute approval review of 500 transactions becomes a 10-minute review of 12 exceptions.

The second change is to compress the approval chain. Instead of sequential approval (entry review by the subledger owner, then the cost center manager, then the controller, then the finance director), design approval stages in parallel when possible and in short sequence when approval must be serial. Most organizations can reduce approval stages from five to three without sacrificing control. The subledger owner approves their subledger reconciliation in the reconciliation workspace. The controller approves all entries and reconciliation exceptions at once, using a dashboard that shows high-risk accounts and exceptions flagged by the reconciliation matching engine. The CFO reviews a summary and sign-off letter rather than individual entries. This parallel-where-possible, serial-only-where-necessary structure typically reduces approval cycle time from eight to ten days to two to four days.

The third change is to automate exception escalation. If an exception is not resolved within a specific time window (for example, three days after period end), Dynamics 365 Finance can send an automated alert to the responsible approver. This prevents exceptions from sitting in a queue and blocking closure. The escalation alert also creates an audit trail—it records when the exception was identified, when the alert was sent, and when it was finally resolved. This audit trail is exactly what your auditors want to see, and it removes the need for a manual exception log that has historically been built in Excel and updated sporadically.

The Realistic Implementation Timeline

These changes require careful process design before the configuration work begins. A typical implementation that adds close-process automation to an existing D365 Finance deployment takes three to four months. The first month is spent mapping current close processes, identifying where exceptions occur most often, and defining the data risk thresholds that trigger approval. The second month is spent building the reconciliation matching rules, configuring the approval workflow, and setting up the exception escalation alerts. The third month is spent running parallel close cycles (the old manual process running alongside the new D365 Finance process) so your finance team can validate that nothing is being missed. The month-end close itself becomes faster immediately, but the real efficiency gain comes in the fourth and fifth close cycles, after your team is comfortable with the new workflow.

The cost of this implementation is not primarily in configuration—it’s in the time your finance team spends away from month-end close activities while the process is being redesigned and validated. Expect to allocate one senior accountant and one finance operations person for two to three months. Expect also that your close process will feel slower for the first month or two after go-live, because your team is learning new workflows and validating that every exception has been captured and resolved. This is normal, and it is not a sign that the implementation has failed.

Making the Business Case to Leadership

The case for process redesign around month-end close is straightforward for a CFO: it frees up your most experienced team members from manual review work so they can focus on analysis, forecasting, and planning. It compresses the time it takes to close the books, which gives leadership three extra weeks per quarter to make decisions based on actual financial results rather than waiting for the close to complete. It creates an audit trail for month-end close activities, which strengthens your internal control environment and simplifies external audits. It reduces the error rate in close processes because exception resolution is now tracked and validated rather than handled ad-hoc.

The cost is three to four months of implementation effort plus the finance team’s time during the redesign phase. The benefit is a close process that runs three to four days faster and a finance team that spends ten to twelve fewer days per month on manual reconciliation and approval work. Over the course of a year, that’s enough time for your finance team to take on strategic work that they couldn’t fit before.

Month-end close doesn’t have to be a three-week sprint every month. It can be a structured, partially automated process that your finance team completes in two to three weeks while also having time to analyze variances and support the business. The tooling exists in Dynamics 365 Finance. The missing piece is usually a deliberate process design that aligns the close workflow with your organization’s risk tolerance and approval structure.


About Routeget Technologies: Routeget Technologies helps mid-market and enterprise organizations streamline financial operations with Dynamics 365 Finance. If your finance team’s close process is consistently running longer than expected, contact us for a process assessment that identifies where Dynamics 365 Finance can reduce manual work without cutting corners on control.

#DynamicsFinance #MonthEndClose #FinanceTransformation #FinanceOperations #CFOStrategy #DynamicsImplementation

Power BI Financial Dashboards for Dynamics 365 Finance: Building the Business Case Without Overcommitting Resources

Power BI financial dashboard with budget variance analysis and cash flow metrics

Your Dynamics 365 Finance implementation is live. You saw a beautiful demo six months ago showing real-time cash flow forecasts, interactive budget variance analysis, and executive dashboards that updated daily. The vendor closed by saying, “You can build this in Power BI in a few weeks.”

Now, three months into your Power BI financial analytics initiative, your internal team is debating whether to hire a permanent analytics hire, your costs have tripled, and you’re six weeks behind on the first dashboard. That demo didn’t account for your Chart of Accounts structure complexity, your subsidiaries’ separate accounting policies, or the fact that your finance team still reconciles GL accounts in a spreadsheet no amount of automation can entirely replace.

This gap between demo and reality is not unusual. It is the norm. Finance organizations that understand this gap upfront build realistic programs that deliver value in 18 to 24 months. Those that don’t end up with abandoned dashboards, frustrated finance teams, and justifiably skeptical CFOs.

What Power BI Actually Brings to Finance

Power BI is a visualization and analytics tool. It is not magic, and it is not a substitute for good financial process discipline. What it does extremely well is surface patterns and relationships in data that spreadsheets obscure, refresh reporting faster than month-end manual consolidations, and give finance teams access to their own analysis without waiting for IT to run scripts.

For Dynamics 365 Finance specifically, Power BI connects directly to your financial data through Dataverse, Power BI’s native Dynamics 365 connector, or Azure Synapse Link for larger datasets. This means your dashboards can show live GL balances, budget variances, or cash flow trends without your finance team building and maintaining ETL jobs in Excel. That alone is valuable. It also means your governance and data accuracy problems do not disappear; they become visible much faster.

The Real Cost of Financial Analytics

Most finance organizations underestimate three cost categories when planning Power BI dashboards.

First: Data Preparation and Model Building. Your chart of accounts is not flat. Your GL transactions include reversals, accruals, and period-end corrections. Your budget data lives in multiple systems (ERP, planning tools, legacy spreadsheets). Your actuals do not reconcile automatically to budget because your organization budgets differently than you post GL transactions. Building a semantic model that surfaces truth instead of confusion requires someone (or a team) to understand your financial processes deeply enough to build that logic in Power BI’s data model.

A consultant or senior analyst can build a basic cash flow dashboard in two weeks. Building a GL variance analysis dashboard that your business partner actually trusts because they understand where the numbers came from requires six to eight weeks of data modeling, testing, and refinement. Multiply this by five to ten dashboards, and you are talking about 10 to 15 person-months of skilled analytical work before you have a production-grade Power BI program.

Second: Governance, Security, and Access Control. Power BI’s row-level security (RLS) model is powerful and flexible. It is also complex. If you need controller-level access to consolidated GL but division heads to see only their own GL, and you want budget managers to compare actual to budget within their business unit, you need a well-designed RLS strategy built on top of your Dynamics 365 security roles.

Adding RLS after dashboards are built is expensive. Building it from the start means taking time to model your organizational hierarchy, decide how P&L responsibilities map to GL structures, and test that every user sees exactly what they should. In large organizations, this is not a week-long project. It is often three to six weeks of iterative testing, edge-case resolution, and alignment with your controller’s office.

Third: Change Management and Training. Your finance team has used the same reports for five years. A new dashboard that shows variance differently, calculates metrics in an unfamiliar way, or requires them to self-serve analysis instead of calling the accounting department will be questioned. Finance organizations move slowly because accuracy matters. Spending time to train your finance team, document assumptions in your dashboards, and let them develop confidence in new analytics before expanding access is essential. Organizations that skip this step often see adoption stall after the initial roll-out.

Timeline showing 24-month implementation roadmap for Power BI financial analytics

Timeline Reality for Finance Dashboards

A realistic timeline for a production-grade Power BI financial analytics program looks like this:

Months 1 to 3: Planning, Architecture, and Foundation Building. You define which dashboards matter most. You audit your GL structure and data quality. You design your semantic model. You plan your security model. You do not build dashboards yet. This period is invisible to executives but essential to avoid rebuilding everything later.

Months 4 to 6: First Dashboards and Pilot Testing. You deliver one to two core dashboards (GL overview, budget variance, or cash flow) to a pilot group of power users. You iterate based on their feedback. You refine the data model. You document assumptions. You do not declare victory.

Months 7 to 12: Scale and Governance. You build three to five additional dashboards based on lessons from the pilot. You harden your security model. You establish SLAs for data refresh (daily, hourly). You set up processes for your finance team to request new analysis without recreating dashboards.

Months 13 to 24: Optimization and Organizational Adoption. Your dashboards are live for most of the organization. You optimize performance, add forecasting or predictive capabilities, and integrate with planning tools. Real adoption happens here, not during launch.

Eighteen months is a conservative estimate for a mid-market organization. If you are larger or your GL is more complex, add six months. If you try to compress this to nine months, you will compromise on governance or data quality, and you will pay for it later.

Realistic ROI and Business Case Framework

Financial analytics ROI is real but indirect. You should not expect Power BI alone to reduce headcount. What you should expect is that your finance team spends less time on manual reporting and more time on analysis, and that finance leaders can answer ad hoc questions faster.

For a CFO building a business case, frame the ROI around three levers:

Time Savings. If your month-end close takes ten days and two weeks of follow-up reporting questions, and Power BI cuts that to eight days with faster ad hoc answer time, quantify that. At a typical all-in cost of $200 to $250K annually for a finance analyst, saving 10 to 20 percent of their time across the team is meaningful.

Decision Velocity. Finance leaders who can answer a business partner’s variance question in hours instead of days make better decisions. Quantify this carefully (it is subtle), but it is real. Include it in your business case as a strategic benefit, not just cost savings.

Risk Mitigation. Faster visibility into GL accuracy, budget performance, and cash flow trends reduces surprises at board meetings. This is hard to quantify but worth naming in your business case, especially if you have had historical GL variance issues or cash flow forecasting failures.

Pragmatic Next Steps

Before committing to a large Power BI investment, take these steps:

Start with a pilot. Pick one financial process (GL variance analysis or monthly cash flow forecasting) and build a proof of concept with one to two analysts over 8 to 12 weeks. Spend one week on planning. Spend six weeks on data modeling and development. Spend one week on pilot testing. Use what you learn to scope the larger program.

Assess your data quality. If your GL balances don’t reconcile to your trial balance, or your budget data lives across five systems, fix that first. Power BI will not solve data quality problems; it will highlight them.

Define governance upfront. Decide who owns the semantic model. Decide how often dashboards refresh. Decide how users request new analysis. These decisions are boring but essential.

Budget realistically. A multi-dashboard financial analytics program for a mid-market organization costs between $200K and $500K over 18 to 24 months, including internal team time, consulting, and platform licenses. If your CFO is not comfortable with that range, you are not yet ready for the program.

The Business Case That Actually Works

Power BI for financial analytics delivers real value. The organizations that see that value are those that plan for 18 months, budget realistically, and recognize that the real cost is not the software license or the initial implementation. It is the investment in data quality, governance discipline, and finance team capability that makes analytics actionable.

The demo you saw six months ago was real. You are just building the foundation to support it.


Routeget Technologies helps organizations build data-driven financial organizations through Dynamics 365 Finance implementations and Power BI analytics programs that actually fit your organization’s reality. Reach out to discuss your financial analytics roadmap.

#PowerBIFinance #FinancialAnalytics #DynamicsFinance #BusinessCaseAnalysis #CFOStrategy #FinancialReporting

Building Approval Loops in Power Automate That Don’t Fall Apart

Enterprise approval workflow dashboard with timeout and escalation management

Approval workflows sound simple in theory. Send a request, wait for response, move forward based on outcome. But somewhere between the proof of concept and production reality, approval loops accumulate failures so quietly that six months pass before anyone notices half your approvals never closed, escalations silently vanished, and the finance team is manually reworking approvals that should have auto-completed.

The gap between what you design and what survives in production typically opens in three places: timeouts on waiting responses that get no notification when they expire, escalation logic that triggers but assumes someone is actually paying attention to a hand-passed email, and no mechanism to detect an approval that was submitted but never reached the assigned approver. Each failure is small enough to dismiss as a one-off, but they compound quickly enough that the flow looks broken even when it is technically working.

This isn’t a flaw in Power Automate itself. Approval loops are possible and reliable at scale. But they require specific configuration practices that most documentation glosses over because they fall outside the “happy path” that gets written up in tutorials. The actual production implementation involves setting constraints, monitoring for stuck states, and building reminders and escalations that stay responsive even when people are unavailable.

The Three Failure Modes in Approval Workflows

Power Automate approval workflow state transitions showing timeout and escalation paths

The first and most common failure mode is the timeout without escalation. By default, an approval waits forever for a response. In production, this means a request sits in someone’s inbox for days while they’re in meetings, on vacation, or simply overwhelmed. The approver eventually rejects or approves, but by then the original requestor has stopped watching and other parts of the process have already stalled or errored out. Better practice: set an explicit timeout on the approval action itself. Don’t wait indefinitely. Use a 48 or 72 hour window depending on your business, and when the window closes without a response, trigger an escalation workflow instead of just abandoning the request.

The second failure mode is silent escalation that nobody actually sees. When a primary approver times out, many designs hand off to a backup approver or manager using a simple email notify step. But email is not a reliable alert mechanism inside workflows. The backup approver doesn’t get a red flag in their task management system. The approval request lands in a folder with two hundred other emails. Three days later, the request is still pending, nobody knows why, and you discover by accident that the backup approver never saw it. Better practice: when escalating, create an explicit escalation record in a tracked system, assign it directly to the backup approver through Power Automate’s assignment or Outlook task creation, and log the escalation so you can report on it later.

The third failure mode is the orphaned approval that disappears from tracking. An approver response can fail for reasons outside your control: the response email is misrouted, the approval action times out before the response is processed, or the flow logic that handles the response encounters an error and doesn’t retry. In many cases, there’s no notification that the approval failed, so it simply stays pending forever. The requestor has moved on, the approver thinks they responded, and your audit log shows a request that was submitted but never resolved. Better practice: attach a completion deadline to every approval, separate from the timeout. If the approval has not resolved by that deadline, automatically resolve it with a fallback decision, and send a notification that escalation occurred.

Implementing a Production-Ready Approval Loop in Power Automate

Start with an approval request that includes a deadline. Use a scheduled cloud flow as a failsafe trigger that runs daily or every six hours and checks for approvals that have been pending longer than expected. If one is found, resolve it by creating a comment on the original record and moving the process forward with a fallback decision (typically approval, pending manager review). This sounds like it adds complexity, but it prevents the entire workflow from silently stalling.

The approval action itself should have a timeout set explicitly, measured in hours rather than days. In Power Automate’s approval action settings, set “Time Out In” to a value between 24 and 72 hours depending on your business rhythm. When that timeout is reached, the flow should not just stop. Instead, trigger an escalation workflow that routes to a backup approver, creates an escalation record, and sends an alert through a more reliable channel than email, such as a Teams message or a specific task in a project management system.

The escalation workflow should include logic that detects whether the backup approver is available. If the backup is out of office, the flow should identify an additional escalation level and continue upward. This requires maintaining a clear escalation path in a configuration table or SharePoint list, but it is the only way to ensure approvals don’t stall when a single person is unavailable.

Every approval flow should also log its state transitions to a tracking table. Each time an approval is requested, assigned, escalated, responded to, or timed out, write a record to a SharePoint list or a database table that includes the approval ID, the approver name, the action taken, the timestamp, and the outcome. This log is what makes it possible to audit the flow later, identify patterns of missed approvals, and debug failures when they occur. Without logging, you’re flying blind.

Error Handling and Retry Logic

Approval flows should not fail silently. Every step that might fail, particularly the send approval action itself, should have an error handler configured. If the approval action fails, the flow should retry once or twice before escalating. Use the retry policy built into cloud flows to automatically retry transient failures without adding extra steps.

The response handling section is where most approval flows fail operationally. The flow waits for a response, the response arrives, and then the flow tries to parse it or use it in a downstream action. If the response object is malformed or the downstream action fails, the approval is left in an inconsistent state. Configure error handling around the response processing step, and if it fails, log the failure, notify an administrator, and set the approval to a manual-review state so it can be handled by a human.

Avoiding the Common Pitfalls

Many approval flows make the mistake of embedding the approval timeout in a scheduled flow instead of setting it on the approval action itself. This doubles the complexity and introduces a race condition where the approval might respond after the timeout is checked but before the scheduled flow resolves it. Set the timeout on the approval action, not as a separate scheduled check.

Another pitfall is using the approval owner’s email address to send escalations. Escalations should be routed through the actual escalation workflow, not as emails copied to a backup. If the email approach is used, the escalation has no status tracking and no way to know whether the backup actually saw it.

A third pitfall is assuming that because an approval was sent, it was received. Always add a receipt confirmation step after sending the approval, using a follow-up flow or a scheduled check that verifies the approver’s status. Some organizations send a brief Teams message or Slack notification alongside the approval to ensure the approver knows to check their Outlook task.

Monitoring and Iteration

Once an approval loop is deployed, the real work begins. Run reports monthly on approval cycle times, timeout rates, escalations, and manual overrides. If escalations are happening more than 5% of the time, the timeout is too aggressive or the approval routing is misaligned. If timeouts rarely occur, you may be able to shorten the window to speed up the overall flow.

Track approvers who consistently miss deadlines and consider reassigning their responsibilities. Some approval routing that looks good on paper breaks down in practice because a particular approver is overloaded or rarely checks their tasks.

Approval loops are a reliable part of any organization’s workflow infrastructure when they are designed with production reality in mind. But that reality is messier than most documentation acknowledges. The difference between a working approval flow and one that silently breaks down is attention to timeouts, escalations, and monitoring from the start.

About Routeget Technologies: Routeget specializes in enterprise transformation across the Microsoft cloud ecosystem, including Power Automate automation and workflow optimization. Organizations looking to build production-ready approval systems that scale reliably can engage our consulting team to design governance frameworks, implement monitoring patterns, and optimize approval workflows for their specific operational needs.


#PowerAutomateApprovals #ApprovalWorkflows #EnterpriseAutomation #PowerAutomate #WorkflowOptimization #DynamicsIntegration