Omnichannel Contact Center Queue Management and Skill-Based Routing in Dynamics 365 Customer Service: Architecting High-Performance Multi-Channel Queues

Omnichannel contact center dashboard with queue management and skill-based routing

Contact center leaders say something that rarely appears in press releases: naive routing destroys customer satisfaction faster than most operational failures. When a customer’s chat hits a queue and lands with whoever happens to be least busy, not whoever can actually solve their problem, two things happen predictably. First, the first contact resolution rate drops. Second, the agent becomes frustrated trying to fake competence outside their domain. Neither outcome makes a financial case for digital transformation.

Dynamics 365 Customer Service addresses this with unified routing and skill-based assignment, a routing architecture that replaces simple round-robin with intelligence: it matches incoming work to the agent or AI assistant most likely to resolve it on first contact. This is not a marketing claim about “intelligent” features. It is a specific technical architecture that must be designed correctly during implementation or it becomes expensive theater.

The Architecture: Why Round-Robin Fails at Scale

Most contact centers start with simple queues. Work comes in, you assign it to the next available agent in rotation. This works until it does not. The moment you have agents with different language skills, product expertise, or capability profiles, pure round-robin creates a matching problem: a billing dispute comes to an agent who specializes in technical support. A complex integration question lands with someone trained only on account inquiries. Resolution time balloons. Transfers multiply. Customers experience delays they should not have experienced.

Unified routing in Dynamics 365 reformats this problem into a two-stage architecture. First, a classification stage adds metadata to each incoming work item: what skills does this conversation need? What customer segment? What channel did it arrive on? This happens through rules, through machine learning models trained on historical skill assignments, or through a combination of both. Second, an assignment stage actually distributes the work. The system finds agents whose assigned skills match the work item’s required skills, checks their current capacity across all channels they handle, considers their performance against defined SLAs, and assigns the work to the most suitable candidate.

This is the architecture. The implementation requires thinking about three distinct components: skills definition, workstreams and routing rules, and queue configuration with fallback logic. Miss any of these and the system either routes work inefficiently or leaves conversations unassigned.

Skills and Capability Mapping: The Foundation

Before any work item reaches an agent, the system must know what each agent can do. Dynamics 365 supports two approaches to skills: you can manually assign skills to each representative, or you can use AI Builder’s Intelligent Skill Finder to train a model on historical skill assignments and predict required skills for new conversations automatically.

Manual assignment is reliable but does not scale easily in organizations with hundreds of agents and dozens of skills. Every new hire, every skill gain, every change in capability requires administrative updates. What gets stale fastest is skill data when it depends on manual entry.

The machine learning approach trains on resolved work items: for conversations that went to specific agents and got resolved, the model learns which conversations typically require which skills. For an incoming ticket about Xbox support in Spanish, the model learns to classify it as requiring Xbox product knowledge and Spanish language capability. Once a model is trained, incoming conversations are automatically tagged with predicted skill requirements without administrative overhead.

In practice, most implementations use a hybrid approach: core skills are defined manually (product lines, supported languages, technical domains) and prediction models augment this with finer classification. For example, a billing conversation might be classified with the predicted skills billing-premium-customer and billing-high-dispute-risk in addition to the basic billing skill.

Workstreams and Classification Rules: Directing Traffic

The actual routing logic lives in workstreams. A workstream defines a channel or type of work, specifies how new work items flow through the system, and applies the rules that determine which queue should receive them. For a chat workstream, you configure things like: when a chat arrives, run these classification rules to tag it with required skills, then find a matching agent from these queues. For a voice workstream: when a call comes in, use speech-to-text to classify the caller’s intent, tag the call with required skills, and route to an available agent who has those skills plus appropriate language support.

Classification rules themselves can be simple or sophisticated. A simple rule might say: if the conversation mentions the phrase billing dispute, tag it with the billing skill and high priority. A more sophisticated rule uses custom attributes, related entity lookups (if this is an existing customer with account status, what does that signal about needed skills?), and even real-time API lookups to external systems that classify customer value or problem complexity.

The architecture decision here is about tradeoff. More rules and more machine learning classification means more accurate skill matching and better first contact resolution, but also more operational complexity to maintain the classification logic and retrain models. In contact centers with low call volume or narrow skill requirements, simple rule-based classification is more maintainable. High-volume centers with heterogeneous skill needs benefit from machine learning despite the operational cost.

Queue Configuration: Capacity and Fallback Strategy

Once work is classified and matched to required skills, it lands in a queue. Dynamics 365 supports three queue types: messaging queues (chat, SMS, social), record queues (cases, emails), and voice queues (phone calls). Each queue type has distinct configuration because the constraints are different. A voice queue must prioritize speed to answer. A case queue can tolerate slightly more delay if it finds a better-matched agent. A chat queue sits between both.

For each queue, configure the assignment method. Highest capacity assigns work to whoever is least busy, simple but ineffective at matching expertise. Advanced round robin rotates work among qualified agents while respecting their capacity across all channels, so if an agent is handling two chats and is at capacity, the next chat goes to the next available qualified agent rather than forcing overallocation. Least active routes to the representative who has handled the fewest conversations recently, useful when you need to spread load evenly. Custom methods use rulesets to define assignment priority: skill match first, then capacity, then response time to previous messages.

Overflow management is where most implementations fail. When a queue is saturated (all skilled agents at capacity), work items must go somewhere. Define an overflow queue that handles these situations: perhaps it routes to a higher-tier support queue, perhaps to an AI agent, perhaps to a human agent with adjacent skills who can attempt resolution. Without explicit overflow configuration, work items get stuck in queue, wait times climb, and the system looks broken even though routing logic is functioning correctly.
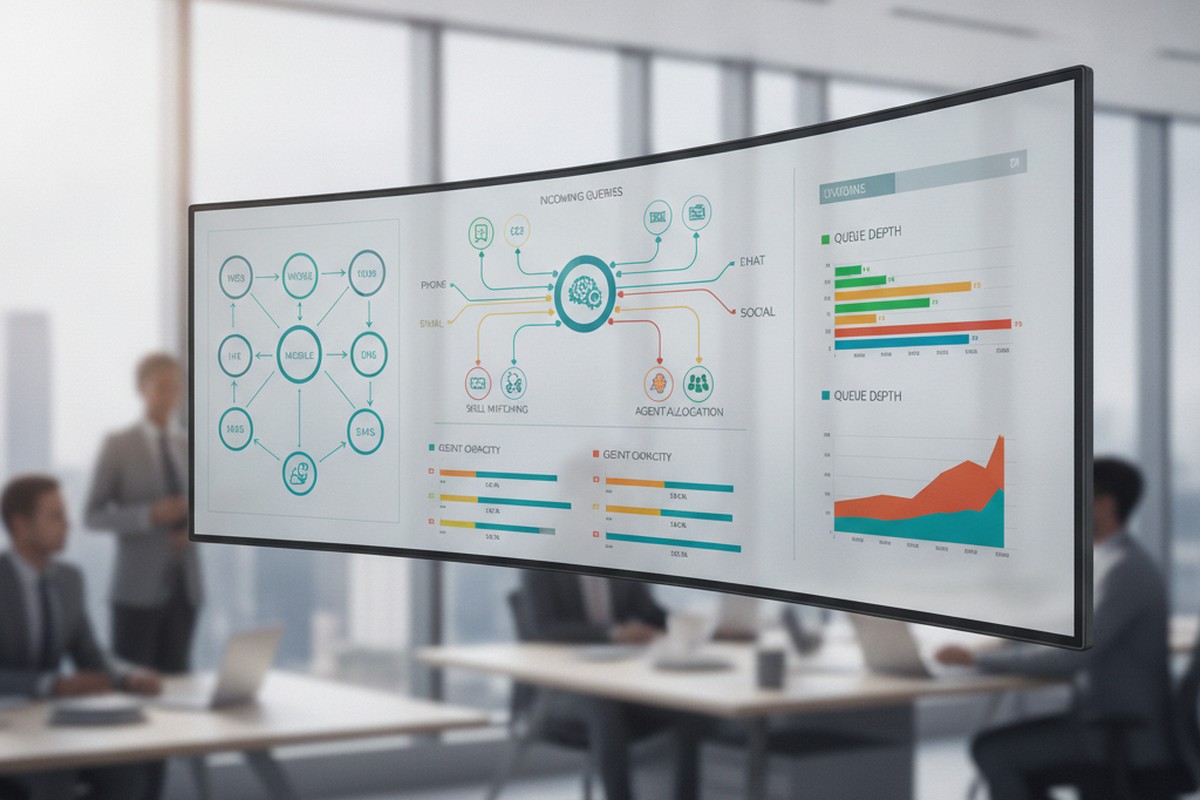
Enterprise queue management and omnichannel routing dashboard with skill-based assignment

Multi-Channel Scale: The Operational Reality

In practice, contact centers rarely run a single channel. A queue might receive work from chat, voice, and social simultaneously. An agent might be licensed to handle both chat and email. The routing system must track each agent’s capacity across all channels they handle, not just within a single channel. This is where advanced routing becomes complex: an agent with two active chats might have capacity for one email but not a voice call. The system must allocate work respecting the agent’s total workload across channels, not just within one.

Dynamics 365 supports this through workload balancing that checks capacity across channels before assigning work. Before assigning a new chat to an agent, the system checks: does this agent have capacity remaining across all their active channels? If not, it finds the next qualified agent with available capacity. This prevents the common failure mode where agents get swamped in one channel while remaining underutilized in another.

Performance and Scaling Considerations

For contact centers beyond a certain size, routing latency becomes a real factor. Classification and assignment happen in near-real-time, but with hundreds of agents and complex skill matching, the system must quickly identify which subset of qualified agents has available capacity. Dynamics 365 handles this through optimized queries and caching of agent capacity status, but implementation matters. If your classification rules are computationally expensive, or if your skill definitions are granular (hundreds of specific skills), querying for matches becomes a bottleneck.

The architectural consideration is skill dimensionality. Defining skills as a basic list (billing, technical, spanish, premium_account) is fast to query and scale-friendly. Defining skills as heavily-nested multi-attribute models (billing-premium-customer-churn-risk-phone-channel, etc.) becomes increasingly expensive to query at scale. Most implementations benefit from a primary skill set for routing (fast, broad categorization) and secondary attributes (stored separately) for analytics and quality management.

Similarly, machine learning-based classification has operational cost: models must be trained, validated, and retrained as your contact center’s needs evolve. Running classification inference on thousands of conversations daily against an active model has latency implications. Budget for this during planning.

Practical Implementation Path

Start with manual skill assignment and simple rules. Get the queue structure working, confirm that agents see work items appropriately, and validate that overflow queues catch edge cases. Once this baseline is stable, layer on machine learning classification if your volume and skill complexity justify the operational overhead. Monitor first contact resolution and average handle time before and after changes to validate that routing logic is delivering the intended outcome.

The technical reality of omnichannel routing is straightforward on paper: match skills to conversations, assign fairly, handle overflow. The implementation reality requires thinking through capacity management across channels, designing classification logic that is both accurate and maintainable, and building explicit fallback paths for conversations that do not match expected patterns. Contact centers that treat this as configuration find they have built a bottleneck. Contact centers that treat it as architecture find that their routing actually enables better customer outcomes.

About Routeget Technologies: Our contact center and customer service architecture practice specializes in designing omnichannel routing systems that balance first contact resolution with agent utilization. We help organizations build skill-based routing from the ground up, design classification rule sets, configure machine learning-based skill prediction, and establish monitoring that confirms routing effectiveness in practice. If you are evaluating or implementing Dynamics 365 omnichannel routing, we can help accelerate the architecture phase before you lock in configuration decisions that become expensive to change later.

#DynamicsCustomerService #OmnichannelRouting #SkillBasedRouting #ContactCenterArchitecture #QueueManagement #Dynamics365CRM #ServiceModules #CustomerServiceArchitecture

Multi-Company Consolidation and Intercompany Eliminations in Business Central: Building Predictable Financial Reporting for Multi-Entity Organizations

Multi-company consolidation architecture in Business Central

Most finance leaders in multi-entity organizations face the same uncomfortable question every quarter: when you’ve pushed the consolidation close button, how confident are you that the consolidated revenue number sitting in front of the board actually represents what happened across all your companies? Not the individual piece that’s typically reliable, but the consolidated picture? That’s where consolidation becomes less about compliance and more about survival.

Business Central’s consolidation framework is deceptively straightforward on paper. Transfer general ledger entries from subsidiary companies into a consolidated company, eliminate intercompany transactions, and generate a trial balance. The reality of getting there, especially across multiple environments, different chart of accounts structures, and hundreds of intercompany transactions, is where most implementations hit friction.

The Two Paths to Multi-Entity Financial Reporting

Business Central offers two fundamentally different architectures for consolidation, and choosing between them shapes your entire finance operation.

Native Business Central Consolidation handles multiple subsidiary companies within the same environment. Each subsidiary is a separate legal entity (company), and the consolidated company pulls general ledger entries from all of them into a single trial balance. This works well for organizations with moderate complexity: two to six subsidiaries, similar chart of accounts structures, and predictable intercompany volumes. The native approach requires no additional licensing and runs against your existing Business Central instance.

Cross-Environment Consolidation pulls data across separate Business Central environments, typically when subsidiaries operate independently or have separate implementations. This approach demands Azure app registration and explicit API configuration beyond what most implementations document upfront. It gains you geographic flexibility and organizational autonomy at the cost of architectural complexity that surprises most finance leaders when they discover it.

The decision between these architectures should happen before implementation begins, not halfway through configuration. A CFO running five subsidiaries with different revenue streams should make that choice explicitly based on reporting requirements, not stumble into cross-environment consolidation because someone recommended “a separate environment for that subsidiary.”

Why Intercompany Eliminations Break Without Architecture

Intercompany eliminations are not an accounting problem. They are an architecture problem masquerading as accounting.

A subsidiary books a $500,000 sale to its sister company. The buying subsidiary records a $500,000 purchase from that same sister. The parent company sees $500,000 of revenue and $500,000 of expense moving through its chart of accounts. In a consolidated trial balance, these numbers double-count the same economic transaction, distorting both the consolidated revenue line and gross margin.

Eliminating this intercompany transaction seems straightforward: enter an adjusting entry in the consolidated company’s general journal, reverse out the duplicate revenue and expense, and your consolidated numbers reflect the economic reality of what actually happened outside the company. In practice, this process fails for three reasons that surface repeatedly in multi-entity implementations.

First: Account mapping complexity. When subsidiaries maintain different chart of accounts structures, you cannot simply reverse a $500,000 revenue entry in Subsidiary A against a matching $500,000 purchase entry in Subsidiary B. The account numbers don’t align. You must maintain a separate intercompany chart of accounts and map each subsidiary’s accounts to that shared chart, then map back to the consolidated company’s structure. This creates bidirectional mapping rules that are easy to misconfigure and difficult to audit later.

Second: Dimension fragmentation. Subsidiaries may use different dimensions to slice data. One subsidiary tracks revenue by sales region; another tracks revenue by customer segment. Consolidated reporting demands that these dimensions reconcile or remain separately reportable. Without deliberate dimension strategy upfront, finance teams end up manually reconciling consolidated totals back to subsidiary detail because the consolidated trial balance doesn’t break down by the dimensions that matter to the business.

Third: Timing and currency mismatch. Intercompany eliminations assume the subsidiary’s books match. If the subsidiary records a $500,000 sale in December and the parent records a $500,000 purchase in January, the consolidation period matters. Similarly, when subsidiaries operate in different currencies, the exchange rate used to record the transaction must align with the rate used to record the corresponding entry in the other company, or the elimination fails to net perfectly and leaves a mysterious gain or loss on currency conversion that nobody can explain.

These technical details are finance operations details. They cascade directly into close speed, error rates, and the executive team’s confidence in the numbers.

CFO reviewing consolidated financial statements in Business Central

Practical Path: Right-Sizing the Consolidation Approach

A common failure mode in consolidation implementations is overengineering for tomorrow’s complexity. Organizations build elaborate cross-environment consolidation architectures when today’s requirements could run entirely on native consolidation.

For two to six subsidiaries with predictable intercompany volumes: Start with native Business Central consolidation. It requires no licensing premium, minimizes Azure complexity, and works against your existing environment. The Business Units page becomes your consolidation control center. Test data before running consolidation (the “Test File” or “Test Database” action flags account number and dimension mismatches before they corrupt your close). Generate the Consolidated Trial Balance report (Report 17) and the G/L Consolidation Eliminations report (Report 16) to preview elimination impact before posting adjustments.

For cross-environment requirements or complex subsidiary structures: Allocate implementation time explicitly to Azure app registration, API endpoint configuration, and cross-environment testing. Document which company data moves which direction, which chart of accounts mapping applies at each step, and which dimensions matter to consolidated reporting. This is not something a finance team should discover mid-close.

For intercompany transaction volume above 200 per month: Evaluate ISV extensions like Binary Stream MEM (Multientity Management) or equivalent tools. Native Business Central consolidation handles centralized intercompany payables and receivables adequately, but it is not optimized for mass journal entry processing when intercompany volumes exceed what native functionality was designed for. ISV tools are cost-justified if they reduce manual reconciliation by five to ten hours per close cycle.

Building Eliminations into Your Close Process

Intercompany eliminations work best when they become a defined step in your close calendar, not an afterthought when the numbers don’t match.

Pre-close phase: Publish a “no intercompany transactions after X date” deadline to all subsidiary controllers. Require them to settle open intercompany payables and receivables (the native Business Central Intercompany Transactions module makes this transparent). Running consolidation after that deadline eliminates the problem of transactions in flight.

Consolidation phase: Run the Consolidated Trial Balance report. Compare this to the prior quarter. Material variances should be investigated before finalization. Use the G/L Consolidation Eliminations report to preview the impact of pending adjustments. Only post elimination entries if the consolidated numbers reflect the economic reality the business expects.

Post-close phase: Publish the consolidated trial balance to Finance stakeholders (CFO, Board reporting team, external auditors). Confidence in this number determines trust in all downstream financial statements.

The Bottom Line

Business Central’s consolidation engine solves a real problem: bringing multiple legal entities’ financial data into a single, trusted view. But consolidation success depends entirely on architecture decisions made before implementation starts. Choose between native and cross-environment consolidation explicitly. Map your chart of accounts and dimensions upfront. Define your intercompany elimination rules in writing before you book a single subsidiary transaction.

When you do this work, consolidation becomes predictable. The numbers reconcile. Your close accelerates. The board sees financial statements that actually represent what happened across the organization.

When you don’t, you spend the last three days of every close cycle chasing mysterious variances and rebuilding eliminations by hand.

The difference between those two outcomes isn’t luck. It’s architecture.


About Routeget Technologies: Routeget specializes in Business Central implementations for mid-market organizations with complex multi-entity structures. Our approach begins with consolidation architecture design before any configuration touches the system, ensuring your finance team closes faster with higher accuracy.

#MultiEntityConsolidation #BusinessCentralFinance #ConsolidationAccounting #IntercompanyEliminations #FinanceOperations #CFOStrategy #BusinessCentralCFO

Building Custom Dataverse Plugins for Real-Time Business Logic: Architecture Patterns and Deployment Strategies

Custom plugins remain one of the most powerful yet misunderstood levers in the Microsoft Dataverse platform. While Power Automate handles lightweight workflows and Power Apps provides UI automation, plugins solve a different problem: they execute business logic in response to Dataverse operations with the performance and security model of server-side code.

The challenge most organizations face isn’t whether to build plugins. It’s determining which problems *require* plugins versus which can be solved with lower-code alternatives. When plugins are the right answer, the next challenge becomes: how do you design, test, and deploy them in a way that scales without becoming a maintenance nightmare?

**The Real-Time Constraint Problem**

Dataverse operations happen in a transactional context. When a record is created, updated, or deleted, plugins can intercept that operation at two points: pre-operation (before the database transaction) or post-operation (after commit). This matters because pre-operation plugins can modify the data before it’s saved, validate input with business rules, or prevent the operation entirely. Post-operation plugins can trigger downstream processes once the change is safely committed.

Many organizations treat these as interchangeable. They aren’t. A pre-operation plugin that makes an external API call can block the user’s operation for as long as that call takes. A 5-second timeout becomes a frozen user interface. Scale that across hundreds of concurrent users, and you’ve created a denial-of-service vulnerability in your own system.

The architecture decision here determines whether your plugin becomes a reliable part of the system or a bottleneck that gets disabled during peak load because it’s failing too many operations.

**Three Plugin Execution Patterns**

The first pattern is synchronous validation. Pre-operation plugins should validate, transform, and enforce business rules before data is saved. They should execute in milliseconds. Any operation that takes longer—external API calls, complex calculations on large datasets, cross-system lookups—should be moved to a separate execution path. This pattern prevents bad data from ever entering the system. A pre-operation plugin validating that a customer’s credit limit isn’t exceeded, or that a purchase order references an active supplier, should complete in 50-200ms. If your logic can’t hit that target, it belongs in an async plugin.

The second pattern is asynchronous post-operation actions. After a record is safely committed, a plugin can trigger downstream effects without blocking the user’s operation. Sending notifications, updating related records in other tables, integrating with external systems, or kicking off approval workflows all belong in post-operation async plugins. These execute outside the user’s transaction and can tolerate higher latency. A 5-second external API call in a post-operation async plugin is acceptable. The same call in a pre-operation plugin is a performance problem.

The third pattern is event-driven architecture. Rather than having plugins orchestrate complex multi-step processes, plugins emit events that external systems subscribe to. A change to an opportunity triggers a plugin that publishes the event. A separate microservice (Azure Function, Logic App, or external system) consumes that event and decides what happens next. This decouples your Dataverse plugins from downstream business logic and lets you evolve downstream systems without changing your Dataverse model.

Each pattern solves a different problem. Synchronous validation makes the data layer trustworthy. Asynchronous actions keep the user’s experience snappy while still triggering necessary side effects. Event-driven architecture makes the system resilient to change.

**Registration and Filtering Strategy**

A common mistake is registering plugins on every attribute change when only a few attributes matter. If your plugin only needs to react when the Status field changes, don’t register on “all attributes.” Instead, register specifically on the Status attribute. This cuts the plugin’s execution count dramatically and improves overall system performance.

Filtering also applies to message types. A plugin doesn’t need to fire on every Create, Update, and Delete. It can fire on Update only. Combine message filtering with attribute filtering, and you’re executing your logic only when it’s actually needed.

Stage selection matters too. Pre-operation runs before validation, so it’s useful for modifying data before validation rules apply. Pre-operation 10 (earliest) runs before pre-operation 20 (later). Post-operation runs after the transaction commits and is useful for downstream actions. Each stage has a purpose; using the wrong stage adds latency where it isn’t needed.

**Testing and Deployment**

Plugin code runs server-side, with access to the organization’s data and permissions. A poorly written plugin can corrupt data at scale. Testing is not optional.

Unit tests should cover the logic of your plugin independent of Dataverse. Integration tests should run the plugin against a Dataverse environment and verify it behaves correctly. Deployment should happen through an Application Lifecycle Management (ALM) pipeline: develop in a sandbox, test in a staging environment, deploy to production only after validation.

One pattern that simplifies testing is moving the core business logic out of the plugin class and into a separate, testable library. The plugin becomes a thin wrapper: extract the input from the Dataverse SDK, call your logic library, and apply the result back to the execution context. This makes unit testing trivial and keeps your plugin logic independent of Dataverse framework details.

**Common Mistakes to Avoid**

Unintended recursion is a classic issue. A plugin modifies a record, which triggers the same plugin again, which modifies the record again, and so on until the system reaches a depth limit and throws an error. Prevention requires tracking execution depth and skipping logic if the current execution is a plugin-triggered update rather than a user-initiated change.

Another mistake is sharing state across plugin executions. Plugin instances aren’t persistent; each execution creates a new instance. Trying to use static variables to pass data between plugin invocations leads to race conditions and unpredictable behavior.

Excessive synchronous API calls create bottlenecks. If your plugin makes 10 external API calls sequentially, and each takes 500ms, your plugin runs for 5 seconds. Users experience 5-second operations for record updates. Move those calls to post-operation async or to a separate integration service.

**Moving Forward**

Dataverse plugins are not obsolete. They’re essential for enforcing business logic at the data layer, but they’re not the only tool. Modern Dataverse implementations combine plugins for critical synchronous validation, Power Automate flows for multi-step post-operation actions, and external microservices for complex integrations. The plugin’s job becomes focused: validate and transform data in real time. Anything else should run asynchronously or outside the transaction.

Routeget Technologies’ experience scaling plugin architectures across large Dynamics 365 deployments shows that the teams that succeed are those that treat plugin development as seriously as they treat any server-side code—with rigorous testing, clear ownership, and architectural intent behind every decision.

#DataversePluginDevelopment #DynamicsArchitecture #CloudIntegration #ServerSideLogic #ALMPipeline #PluginArchitecture #EnterpriseDataManagement #Extensibility

AI-Powered Sales Forecasting in Dynamics 365 Sales: From Historical Data to Predictive Revenue Planning

The Forecast Nobody Trusts

Sales forecasts in enterprise organizations have a credibility problem. Sales leadership submits a forecast one month, management adjusts it downward out of habit, and by quarter-end everyone discovers that actual pipeline and close rates bore no resemblance to either number. The problem is not salespeople lying or poor spreadsheet discipline. It is that traditional forecasting relies on human judgment applied to datasets too large and complex for human pattern recognition to work reliably.

Dynamics 365 Sales with integrated AI and analytics capabilities changes this dynamic fundamentally. Rather than asking managers to estimate close rates and deal velocity based on their gut feel, organizations can build forecasts on the same historical data that actually predicts outcomes: past deal size, industry, pipeline velocity, sales rep experience, deal characteristics, and seasonal patterns. The result is not perfect, but it is consistently more accurate than traditional methods, and it gives sales leadership a fact-based foundation for revenue conversations with finance rather than negotiated guesses.

How Predictive Sales Analytics Work in Dynamics 365

Dynamics 365 Sales Premium includes a suite of analytics capabilities that power forecasting without requiring advanced data science skills or external platforms. The system automatically ingests data from opportunity records, activities, customer accounts, and deal attributes, then uses machine learning to identify the patterns that correlate with closed wins, lost deals, and extended cycles.

For an organization selling enterprise software with typical sales cycles of six to nine months, the system learns that deals from specific industries have different close rates, that proposals sent in month two (as opposed to month four) have higher win probability, and that opportunities touching more buying committee contacts are more likely to close. These patterns are statistically significant but often invisible to human judgment operating over dozens or hundreds of deals simultaneously.

The forecasting engine generates a confidence score for each opportunity: a prediction of the probability that deal will close within the target quarter. Rather than replacing the salesperson’s forecast with an algorithm, Dynamics 365 surfaces these predictions as a recommendation layer, allowing sales managers to keep the deal in forecast if they believe factors not in the data justify it, or to flag deals where the algorithm’s assessment contradicts the sales rep’s estimate. In practice, deals the system rates as low-probability but the rep insists will close become visible decision points, and forecasts weighted by these probabilities prove more accurate than unadjusted rep estimates.

Moving from Monthly Submissions to Continuous Intelligence

Traditional sales forecasting operates on a monthly or quarterly cadence. Sales leaders call a forecast meeting, reps submit their estimates, managers apply adjustments, and the number goes to finance. Three weeks later, when actual deals close or new opportunities surface, the forecast is already outdated.

AI-driven forecasting in Dynamics 365 Sales operates continuously. As pipeline changes, deal characteristics evolve, and close dates shift, the system recalculates probability scores in real time. Sales leadership can check accuracy at any point in the quarter rather than waiting for the official review, and can identify where actual progress is diverging from forecast early enough to adjust strategy or pipeline development.

This shift from periodic submission to continuous intelligence has operational consequences. Sales managers no longer spend two days in forecast-call meetings; instead they spend fifteen minutes reviewing a dashboard that shows which deals are tracking as expected and which have shifted risk status. Finance gets a more current picture of expected revenue. And sales reps see their opportunities scored fairly against consistent criteria rather than subject to manager judgment that varies month to month.

Building Revenue Predictability Across Market Segments

One of the highest-value uses of predictive sales analytics is building segment-specific forecast models. An organization selling both managed services and perpetual licenses may discover that customers purchasing managed services have a seventy-percent close rate while perpetual license deals close at forty-five percent, and that rep tenure affects close rates only for managed services, not perpetual deals. Once these segment-specific patterns are identified, forecasts weighted by segment become far more accurate than a single organization-wide model.

Organizations with international operations benefit further, as the system can identify which regions have different sales dynamics. A deal structure that works reliably in North America may have lower success in Asia Pacific due to buying patterns or competitive dynamics, and a forecast that does not account for that regional signal will consistently overshoot certain markets and undershoot others.

Building these segment models requires data discipline (opportunity fields must be filled consistently, sales stages must be defined clearly), but once that foundation is in place, the system automatically detects and incorporates segment-specific patterns. Sales organizations that have historically managed separate forecast models for different markets often find they can consolidate to a single system with segment-driven weightings, reducing forecast maintenance overhead while improving overall accuracy.

Common Implementation Mistakes

Organizations implementing AI-driven forecasting in Dynamics 365 Sales often make three systematic mistakes. First, they attempt to train the model on too little historical data. If the system only has two quarters of opportunity records, it cannot detect patterns that matter for a deal type with an eighteen-month cycle. Second, they do not invest in data quality upstream. If opportunity records lack consistent stage definitions, industry classifications, or customer size information, the model has no signal to work with. Third, they present the AI forecast as a replacement for human judgment rather than as a tool that surfaces patterns human judgment can integrate. Sales organizations that frame the system as “the computer will tell you who to trust” face adoption resistance; those that frame it as “the system flags patterns you should investigate” see adoption and engagement.

Next Steps for Sales Leadership

For organizations already using Dynamics 365 Sales, enabling predictive analytics is typically a configuration matter rather than a deployment project. Assess your historical opportunity data to confirm you have at least four quarters available and that field completion rates are reasonable. Review your sales stage definitions to ensure they are consistent with how deals actually progress. Then enable the analytics features and begin building segment-specific forecast models based on your business lines.

For organizations evaluating Dynamics 365 Sales or planning major system migrations, AI-driven forecasting should be part of the evaluation criteria. Whether your organization benefits from this capability depends on your sales model, your forecast accuracy needs, and your data discipline, but for enterprises where forecast accuracy directly affects financial planning and capital allocation, predictive sales analytics often justify the platform investment on their own.

The Forecast Everyone Uses

The strategic value of AI-driven forecasting extends beyond raw accuracy. When sales leadership and finance can trust a forecast because it is grounded in historical data rather than negotiation, conversations shift. Instead of debating the number, the conversation becomes, “What actions should we take to shift close rates or deal velocity?” Sales and finance become partners in building pipeline rather than adversaries in a forecast negotiation.

Dynamics 365 Sales with integrated AI analytics makes this shift possible. For sales organizations ready to move beyond spreadsheet-based forecasting, the capability is available today.


About Routeget Technologies: Routeget Technologies helps mid-market and enterprise organizations implement and optimize Dynamics 365 Sales, enabling teams to improve forecast accuracy, streamline pipeline management, and drive predictable revenue growth through data-driven sales practices.

#SalesForecastingAI #DynamicsSalesAnalytics #SalesRevenuePlanning #PredictiveAnalyticsD365 #SalesLeadership #EnterpriseAI #DynamicsSales

Extending Power Pages Beyond UI: Liquid Templates, Code Components, and JavaScript for Production Portal Requirements

Power Pages’ low-code interface makes building portals faster than traditional custom development. But every organization eventually hits the moment where the out-of-the-box form controls, basic table views, and standard workflows become constraints rather than features. The portal needs business logic that doesn’t fit the declarative model. Data needs to transform based on context. The user experience requires patterns Power Pages doesn’t provide natively.

At that point, technical teams face a critical decision. Many teams build custom portals in React or Vue, burning months of development and losing the Power Platform’s Dataverse integration layer. Others try to force every requirement into Power Pages’ declarative surface, resulting in fragile workarounds that break with each platform update. A third path exists: understanding how to extend Power Pages with Liquid templates, custom JavaScript, and code components without abandoning the platform’s operational advantages.

The Architecture Mismatch: Why Low-Code Hits a Ceiling

Power Pages’ strength is also its limitation. The platform provides configuration-driven portal building because that model works for the common cases: customer self-service forms, portal content, and basic lookup forms. The form engine optimizes for ease of use, not for the kind of sophisticated client-side behavior a production portal often requires.

Consider a realistic scenario. A financial institution needs a partner portal where finance directors can submit loan applications, see real-time pricing based on their organization’s profile, track application status through workflow stages, and export reports combining Dataverse data with external system information. The default Power Pages form control has no awareness of multi-step workflows. Table views don’t support the kind of conditional formatting and interactive filtering the business expects. The out-of-the-box experience feels incomplete.

This gap between what Power Pages provides by default and what production portals require is not a product limitation. It’s a signal that the team needs to step beyond configuration and into code. The opportunity is recognizing which layer to extend, which will determine the development complexity and maintenance burden of the resulting system.

Three Extension Points: Understanding When to Code

Liquid Templates are server-side templating that query Dataverse using FetchXML and render dynamic content before sending HTML to the browser. They excel at personalized content: showing customers only their records, displaying role-based form sections, or calculating KPIs in dashboards. Liquid queries run with elevated permissions, making it safe to expose read-only data that would be restricted through the client-side portal Web API. The limitation is clear: Liquid generates static HTML. Interactive behavior requires client-side code.

JavaScript and Portal Web API enable client-side interactivity. Custom JavaScript embedded in web templates can make asynchronous Dataverse calls for create, retrieve, update, and delete operations. This supports sophisticated portals: real-time filtered dashboards, search-and-filter experiences, and form interactions without page reloads. The portal Web API is constrained by design (specific tables and columns exposed, row-level security enforced), which means portals are secure by default. The tradeoff: teams sometimes discover in production that row-level security filters block the data they need. Performance matters here too. Portals making dozens of sequential API calls feel slow. Efficient implementations batch calls, cache data, and avoid redundant queries.

Code Components built with the Power Apps Component Framework (PCF) provide reusable custom controls that can be packaged and deployed independently. A data grid with sorting and filtering. A date picker with business calendar logic. A currency converter. Code components encapsulate complexity and can be versioned and reused across multiple portals. Power Pages supports a subset of PCF APIs (no device access, no multi-field components), but this covers most scenarios. The advantage over inline JavaScript is encapsulation and reusability; the cost is more formal development and packaging.

Combining Patterns in Production

Successful portals typically combine these extension points strategically. Liquid templates render personalized, read-only content server-side. JavaScript layered on top adds client-side interactivity like filtering, modal dialogs, and form submission without page reloads. Code components provide sophisticated interactive controls for scenarios too complex for inline JavaScript.

The principle is simple: use the least powerful extension point that solves the problem. Server-side logic stays in Liquid. Client-side behavior goes to JavaScript. Reusable controls become code components. This discipline keeps portals maintainable and reduces the surface area for bugs.

Common Implementation Mistakes

Teams building production portals frequently encounter predictable problems.

Overusing the portal Web API is the most common. Developers build portals that make dozens of sequential API calls to fetch related records, transform them, and populate sections of the page. The portal feels slow because it genuinely is slow: each API call adds 200-500ms of network latency. The solution is to rethink the architecture: can Liquid fetch the related records server-side? Can the JavaScript cache frequently needed data instead of querying it repeatedly? Can the form be restructured to avoid needing related data?

Neglecting row-level security testing is another common mistake. Developers build portals using a system administrator account and assume the portal Web API will return certain columns and records. In production, when row-level security rules are applied, the queries fail or return no data. Testing with non-administrator accounts during development prevents this category of surprise.

Security logic embedded in JavaScript is another pattern to avoid. A developer might write JavaScript that checks whether a button should be shown by verifying the user’s role. But if the role is determined by JavaScript on the client, an attacker can modify the browser’s DOM and show a button that should be hidden. Any security decision must be validated server-side, either through Liquid templates or through server-side plugins.

Moving Forward: When to Invest in Extension Architecture

The decision to extend Power Pages with code components, custom JavaScript, and Liquid templates should be made deliberately, not by accident. If the portal’s core requirements can be met with Power Pages’ declarative features, stay there. Configuration is faster to build, simpler to maintain, and survives platform updates with fewer breaking changes than custom code.

But if the portal needs personalized server-side content, client-side interactivity beyond basic form submission, or reusable custom controls, then understanding these extension points is essential. Teams that build with a clear architecture in mind, that understand which layer solves which problems, and that test thoroughly across use cases and user roles will build portals that feel native while leveraging the operational advantages of the Power Platform and Dataverse.

Organizations that struggle are often those that assume Power Pages is only for simple portals, then scramble to refactor when production requirements demand sophistication. By understanding the extension architecture from the start, teams can make intentional decisions about scope, complexity, and implementation approach rather than discovering these constraints partway through development.

Power Pages is capable of hosting sophisticated production portals. The key is recognizing what each extension point is designed to solve, and building with that clarity in mind.


About Routeget Technologies

Routeget Technologies helps enterprise organizations design, implement, and optimize Power Platform solutions including sophisticated Power Pages portals. Whether you’re planning a customer-facing portal, a partner collaboration site, or an internal employee experience, the difference between a successful portal and a frustrating one often comes down to architecture choices made early in the project. Our team works with organizations to understand their portal requirements, design an appropriate extension architecture, and guide implementation to ensure portals perform well, remain secure, and stay maintainable through their production lifecycle.

#PowerPagesCustomization #LiquidTemplates #CodeComponents #PortalDevelopment #PowerPlatform #EnterprisePortals #CustomJavaScript #WebAPIDevelopment #LowCodeExtension #PortalArchitecture

Automated 1099 Compliance and Vendor Management in Business Central: Eliminating Manual Year-End Reconciliation

Your accounts payable team is three weeks away from month-end close, and someone just discovered that twenty vendor records lack 1099 classification codes. Finding that error now means scrambling to update historical transactions and validating tax IDs, hoping the IRS forms you file in January match what accounting recorded in September. This pattern repeats annually, consuming weeks of Finance Controller time and introducing error risk.

For SMB organizations running Dynamics 365 Business Central, this annual firefighting is preventable. The problem is not that Business Central lacks 1099 functionality; it is that most implementations treat 1099 compliance as a year-end task rather than a continuous vendor management process. Organizations duplicate effort across systems, manually validate data that Business Central can track automatically, and discover compliance gaps too late to correct them cleanly.

Business Central’s native 1099 framework and its ecosystem of compliance integrations can transform 1099 from a month-end expense into a metadata attribute that flows through vendor records and payment transactions continuously, surfacing errors and compliance gaps in real time rather than in December.

The Year-End 1099 Crunch: Why Manual Processes Persist

Finance teams often view 1099 compliance as a specialized tax topic, distinct from day-to-day accounts payable operations. The logic is superficially sound: 1099-eligible vendors are a small subset of overall payables; validate them when 1099 preparation begins in Q4. In practice, this creates three interconnected problems.

Vendor master data drifts throughout the year. Businesses add new vendors opportunistically through email requests or procurement processes. Accounts payable staff focus on processing invoices, not classifying vendors by tax treatment. By October or November, dozens of relationships exist without 1099 metadata, and tracing which payments went to which vendors requires manual reconciliation against invoices.

Second, classification is not a one-time decision. IRS thresholds and vendor eligibility rules change, and business relationships evolve. A vendor at $4,000 annually in 2024 becomes a $7,000 relationship in 2025, potentially crossing reporting thresholds. Without continuous validation, this progression gets missed, and Finance discovers it only when reconciling December payments.

Third, legacy workarounds persist. Finance teams maintain parallel spreadsheets to track 1099 vendors, validation status, tax ID accuracy, and payment thresholds, duplicating data that belongs in the ERP system itself. This creates conflicting records and necessitates manual year-end reconciliation to determine which version is correct. The result: 1099 preparation consumes 60 to 100 hours of Finance Controller time per year, with most spent discovering and correcting errors rather than performing actual tax calculations or form generation.

Business Central’s Native 1099 Framework: More Capable Than Most Realize

Dynamics 365 Business Central includes native 1099 compliance functionality that most SMB implementations underutilize. The platform allows you to classify vendors by 1099 type (1099-NEC for nonemployees, 1099-MISC for miscellaneous income, 1099-K for payment cards), track tax identification numbers, maintain payment threshold metadata, and filter transactions by vendor tax classification. These capabilities are built into the vendor master record and the general ledger.

This matters because 1099 data flows through your accounting system continuously, not as an external extract at year-end. When you code a payment for a 1099-NEC vendor, Business Central knows both the vendor classification and the payment amount in a single system context. Year-end 1099 reporting becomes aggregation of data that has been accurate throughout the year, not reconstruction of historical payments.

The practical capability includes: vendor tax type classification, tax ID validation rules that flag missing or mismatched IDs during vendor creation, threshold monitoring that alerts finance teams when vendors cross reporting thresholds, and reporting that segregates 1099-eligible payments for year-end reconciliation. These features exist in the base system and require no custom development.

However, the gap between what Business Central can do and what most Finance teams actually implement is substantial. Many organizations activate 1099 fields in the vendor master but do not enforce classification at invoice entry or payment posting. They track tax IDs but do not validate them against IRS records. They set threshold alerts but do not connect those alerts to an escalation workflow. The result: 1099 metadata exists in the system but is not actively used to guide daily operations, and Finance still falls back to manual year-end reconciliation.

Closing the Gap: Integrations That Drive Continuous Compliance

The second layer of 1099 automation comes from integration platforms and specialist compliance applications built for Business Central. These tools fall into two categories: those that validate vendor master data continuously, and those that automate form generation and filing.

Continuous validation tools integrate with IRS databases and tax ID verification services, automatically checking vendor tax IDs against authoritative sources as vendor records are created or modified, flagging mismatches and expired IDs in real time. When a vendor record is missing a tax ID or the ID does not match IRS records, the system can block payment posting or flag the vendor as non-compliant. This shifts error detection from December to the moment the error occurs, when it is simplest to correct.

Form generation integrations automate the calculation of 1099 amounts, formatting of tax forms, and electronic filing with the IRS. Rather than exporting payment data from Business Central, importing it into Excel, manually categorizing amounts, and formatting forms by hand, these integrations read 1099-eligible transactions directly from the General Ledger, aggregate amounts by vendor and payment type, generate IRS-formatted forms, and file directly with the IRS. The typical workflow requires less than two hours of Finance input in January for form verification and signing, compared to 40-60 hours of manual data manipulation in a spreadsheet-based process.

The most effective implementations combine continuous validation with automation: vendor master data stays clean throughout the year via ongoing validation, threshold alerts keep procurement informed of vendor spend patterns, and year-end form generation is a 90-minute process rather than a three-week undertaking.

Avoiding Common Implementation Mistakes

Organizations implementing 1099 automation often encounter pitfalls. First, they activate 1099 fields in the vendor master but do not enforce them at transaction entry. The fix: mark 1099 fields as mandatory for certain vendor categories and configure invoice entry screens to prevent posting if required metadata is missing.

Second, they assume a single year-end validation pass is sufficient. Vendor data decays continuously: tax IDs change, addresses shift, business relationships evolve. Organizations that implement automated validation once per quarter catch and correct issues far more reliably and with less time pressure.

Third, they neglect the integration between 1099 compliance and procurement workflows. Finance often manages 1099 classification independently of procurement. Effective implementations tie vendor creation and 1099 classification together, with both teams seeing vendor compliance as a shared responsibility.

Fourth, they underestimate edge cases. One-time vendors, interim contractors, and international vendors blur the line between 1099-eligible and employee-equivalent arrangements. Automation works well for straightforward cases but needs human review workflows for ambiguous scenarios.

Putting 1099 Compliance Back in Scope

Year-end 1099 compliance does not have to consume weeks of Finance Controller time or introduce error risk every tax season. Business Central’s native 1099 capabilities, combined with integrations that extend those capabilities to continuous validation and automated filing, can reduce 1099 from an annual firefighting exercise to a metadata attribute that flows through your vendor master and payments continuously.

Finance teams that invest in configuring Business Central’s native 1099 framework and connecting it to vendor management workflows discover that 1099 compliance becomes a side effect of good vendor master data, not a specialized tax task. That shift from detective work to verification is what transforms 1099 from a cost center into operational infrastructure that actually supports finance and procurement partnership.

Routeget Technologies works with mid-market organizations to audit current 1099 compliance processes, design integration strategies that fit existing Business Central deployments, and execute vendor master remediation programs that bring 1099 data into alignment with IRS requirements. If your finance team is spending October and November managing 1099 reconciliation, the investment in continuous compliance automation typically pays for itself in the first year.

#Automated1099Compliance #BusinessCentral1099 #VendorManagement #1099Automation #SMBFinance #ERPCompliance #FinanceAutomation #TaxCompliance

Copilot Studio Custom Plugins and Data Connectors: Building Autonomous Business Agents with Real-Time Contextual Data

Your finance team has spent three weeks training a customer service agent in Copilot Studio. The agent understands policies, escalation rules, and even recognizes when a refund needs approval. But when a customer asks “what’s my account balance,” the agent returns nothing. It can talk about balance policies but has no access to customer data. The agent is conversationally complete but operationally useless.

This is the gap between conversational AI and autonomous business agents. Copilot Studio’s out-of-the-box connectors handle common scenarios: sending emails, posting to Teams, querying your knowledge base. For production agents that need to access real-time business data, resolve customer records in your ERP, or trigger workflows across your business systems, those built-in connectors become constraints. Custom plugins and data connectors transform Copilot Studio from a chatbot framework into a true autonomous agent platform, but building them requires understanding how agent context flows, how your agent manages token budgets, and where to capture data errors before they undermine agent decisions.

The Context Problem: Why Standard Connectors Fail at Scale

Most first-generation Copilot Studio implementations treat the agent as stateless. A customer asks a question, the agent formats a response, and the interaction ends. This works for FAQ-style use cases. But autonomous agents operate differently: they maintain context across multiple turns, make decisions based on customer data, and sometimes initiate actions without explicit user prompts.

Standard connectors (email, Teams, SharePoint) assume a request-response pattern. An agent sends a message, the connector executes, and returns a simple success/failure result. Real business data is rarely that clean. A customer might have multiple open orders, pending payments, or conflicting account statuses. Your agent needs to surface relevant context, reason about it, and sometimes ask clarifying questions before taking action.

This is where custom plugins become essential. Instead of the agent making separate connector calls for customer name, then order status, then payment history, a custom plugin can accept the customer ID and return a structured data object containing relevant account context. That single call reduces latency, keeps the agent’s reasoning clear, and prevents token bloat from multiple sequential API calls.

Designing Custom Plugins for Agent Reasoning

A custom plugin is an HTTP endpoint that your agent can call just like a built-in connector. The key difference is control: you define what data the agent receives, what context it needs to reason about, and how errors are handled.

Start by identifying the discrete business questions your agent needs to answer. Not “get all customer data,” but specific queries: Is this customer eligible for a refund? What is their current account balance? Are there open support tickets that might conflict with this request? Each question becomes a separate plugin endpoint, not because complexity is bad, but because focused endpoints make agent behavior predictable and testable.

The plugin endpoint should return structured JSON with fields relevant to the agent’s reasoning. If your agent is deciding whether to approve a refund, the response should include refund policy eligibility (yes/no), the customer’s refund history, any pending disputes, and the maximum allowable amount. Don’t include fields the agent doesn’t need to reason about. Noise in the response increases token consumption and can confuse the agent’s decision-making.

Error handling inside your plugin matters more in an agent context than in traditional API design. If a query times out or returns unexpected data, the agent should receive a structured error response that explains what went wrong and suggests recovery options. For example, if your ERP system is temporarily unavailable, don’t return a 500 error that breaks the agent flow. Return a structured JSON response indicating the system is unavailable and suggesting the agent offer to escalate or retry in a moment. The agent can then reason about recovery.

Integration Patterns: Real-Time Data Without Token Bloat

Once you have custom plugins defined, the architectural pattern determines whether your agent scales or bogs down. The worst pattern is sequential data fetching: the agent calls a plugin to fetch the customer record, then parses the response to extract the customer ID, then calls another plugin to fetch order status, then calls a third plugin to fetch payment information. Each call requires network latency, adds to the agent’s conversation history, and consumes tokens.

Instead, design plugin endpoints that return compound data structures. A single “Get Customer Context” endpoint returns customer basics, their recent orders, their payment status, and their support ticket count in one call. The agent makes one request, receives contextual depth, and proceeds with reasoning. This pattern is faster, cleaner, and uses far fewer tokens.

Pagination and large result sets present a different challenge. If your agent is querying a list of orders, you don’t want to return the last five years of transaction history. Use query parameters to scope the data: return only orders from the last 30 days, or only orders with a status of “pending” or “shipped.” Let your plugin do the filtering, not the agent.

Authentication between Copilot Studio and your custom plugins should use standard methods. API keys work but require secure storage. OAuth2 with service principals is stronger for production scenarios; the agent’s host application authenticates on behalf of the agent, and your plugin validates that token. This prevents agents from accidentally exposing customer data to unauthorized callers.

Managing Agent State and Conversation Context

Custom plugins change how you think about agent state. In stateless chatbot scenarios, the agent has no memory between conversations. But autonomous agents often need to carry information across multiple turns within a single conversation: the customer’s account status, the decision the agent made earlier, the action it’s waiting for approval to execute.

Copilot Studio stores conversation history in its context, and that history is sent to your agent (and to your custom plugins) with each call. This is powerful, but it has cost: longer conversations mean larger context payloads, which consume tokens faster and can hit context window limits on the underlying model. You need to design your plugins to be efficient with the conversation state.

One pattern is to have your plugin accept the conversation ID or session ID as a parameter. Your plugin stores intermediate agent reasoning (what decision it reached, what additional data it needs) in a database keyed by that session. On the next turn, when the agent calls the plugin again, it can retrieve what it learned earlier without re-transmitting that entire history through the conversation context. This pattern keeps conversation history lean while letting your agent maintain reasoning across multiple turns.

Common Implementation Mistakes

The most frequent mistake is over-fetching data. An agent asking “should I approve this refund” doesn’t need the customer’s entire account history for the past five years. It needs refund policy eligibility, recent return patterns, and any pending disputes. Plugins that return too much data waste tokens and sometimes confuse the agent’s reasoning by introducing irrelevant information.

The second mistake is poor error handling. If a custom plugin is down or returns a 500 error, and your agent doesn’t have instructions for handling that failure, the entire agent flow breaks. Every plugin call should have defined error responses and recovery instructions. Your agent should be able to handle temporary unavailability gracefully.

The third mistake is designing plugins without testing agent behavior. A plugin might work perfectly when called directly via an HTTP client, but behave unexpectedly when an agent calls it. Test your plugins with actual agent conversations, not just REST clients. The agent’s phrasing, context window, and token constraints create scenarios your unit tests won’t catch.

Building Toward Production Readiness

Autonomous agents succeed when they combine narrow, focused capabilities with reliable data access. Start by building one custom plugin that answers a specific business question well. Test it in a real agent conversation. Monitor the plugin’s response times, error rates, and whether the agent’s decisions improved compared to built-in connectors.

From there, add plugins incrementally. Each one should serve a specific function and integrate with your agent’s existing conversational flow. Design them for both speed and clarity, so your agent can reason about the data quickly without getting lost in irrelevant context.

The difference between a chatbot and an autonomous agent is data access and decision-making. Custom plugins provide the data; your agent design determines whether it reasons about that data effectively. Getting the plugin architecture right early saves months of iteration later.

Routeget Technologies has implemented custom Copilot Studio agents for finance teams, customer service operations, and supply chain coordination, each with specialized plugins connecting to ERP, CRM, and custom business systems. We work through the architectural decisions and integration patterns that let your agents scale to real production workloads.


#CopilotStudioPlugins #AIAgentArchitecture #DataConnectors #CustomIntegrations #AutonomousAgents #PowerPlatform #EnterpriseAI #AgentDesignPatterns

Global Payroll Consolidation in Dynamics 365 F&O: When Mandatory Upgrade Meets Your Legacy Salary System

CFOs and Finance Operations leaders managing global enterprises with Dynamics 365 Finance and Operations often inherit complex, multi-country payroll systems built over years of acquisition and consolidation. When Microsoft announces mandatory payroll module upgrades, the panic is real. Your current system handles salary processing across 12 countries in 9 currencies with legally binding tax rules in each jurisdiction. A forced upgrade risks disrupting payroll runs and triggering compliance violations that no CFO wants on their record.

The Payroll Module Upgrade Dilemma

Dynamics 365 F&O payroll has evolved significantly since its introduction. Earlier versions of the payroll module, built on older technology stacks, are being deprecated in favor of a modernized architecture that integrates more tightly with current Human Resources, General Ledger, and Tax Calculation Services. The upgrade is not optional. Microsoft has published end-of-support dates, and after those dates, support contracts expire, patches stop arriving, and your system becomes an orphan.

For most organizations, this timeline feels compressed. The payroll system is not something you can take offline for a two-week migration. Employees must be paid on schedule, tax filings must meet jurisdictional deadlines, and auditors expect clean transaction trails. A payroll upgrade failure doesn’t just hurt IT morale; it creates payroll delays, tax exposure, and employee relations issues that escalate to the CFO’s desk very quickly.

Where Consolidation Starts Making Financial Sense

Many organizations discover during upgrade planning that they have more payroll complexity than necessary. Legacy systems from acquired subsidiaries still run parallel payroll processes. Some countries process payroll in the legacy system and then manually reconcile into F&O. Others have built custom calculation engines in Excel or external tools because the standard payroll module didn’t handle local requirements at the time.

This redundancy is expensive. Each parallel system requires dedicated support, training, reconciliation labor, and audit oversight. When the F&O payroll upgrade forces a modernization moment, many CFOs find that consolidation becomes not just feasible but economical. Instead of re-implementing the old approach in the new payroll module, you can redesign payroll processing around what the modernized module actually does well, eliminate legacy workarounds, and reduce operational complexity in the process.

The question is not just “Can we upgrade?” but “Should we consolidate while we upgrade?”

Technical and Compliance Constraints

The payroll module redesign in Dynamics 365 F&O is substantial. The new architecture integrates more tightly with the Tax Calculation Service, allowing organizations to stay current with tax rule changes across jurisdictions without manual updates. It also supports real-time General Ledger posting, which means payroll accruals reflect in your books immediately rather than waiting for a month-end batch. These are genuine improvements, but they require careful mapping during migration.

Compliance constraints are real. Each country where you process payroll has specific requirements: statutory deductions must be calculated by law, tax filings must use government-mandated formats, and records must be preserved for audit. The payroll module upgrade must maintain compliance across every jurisdiction you operate in. Some countries have limited payroll capabilities even in the modernized module. If you rely on those capabilities, you cannot simply consolidate everything into F&O; you must maintain targeted parallel systems for those jurisdictions and carefully reconcile with F&O.

Currency conversion rules, withholding tax calculations, and pension contribution formulas all vary by country. The new payroll module handles this variability, but configuration is complex and requires deep knowledge of local requirements. Many organizations underestimate the effort needed to get country-specific payroll configurations right during upgrade, leading to post-go-live adjustments that cost more than front-loaded planning would have.

Planning the Consolidation Alongside Upgrade

A successful approach treats the payroll upgrade and consolidation as a single program, not as separate initiatives. Start by mapping every current payroll process: which countries are in F&O today, which are in legacy systems, which are in Excel or external vendors. For each, document the business rules (tax treatment, deductions, gross-to-net calculations), the data sources (HR system, time tracking, benefits), and the downstream processes (GL posting, tax filing, employee reports).

Then evaluate consolidation options. Full consolidation into the upgraded F&O payroll module is ideal from a system management standpoint but may not be feasible for all countries. Selective consolidation where F&O handles core operations and legacy systems remain for countries with limited module support is often more realistic. Some organizations design a hybrid model: F&O runs payroll in supported countries and serves as a hub that reconciles with legacy systems in other jurisdictions.

Build a detailed integration plan. The Tax Calculation Service in Dynamics 365 can handle many jurisdictions natively, but configuration effort is significant. Plan for tax configuration as part of the overall upgrade timeline, not as an afterthought. If you are consolidating from multiple legacy systems, plan for data reconciliation: will prior-year data come into F&O, or will legacy systems remain as historical record? What is the cutover date?

Avoiding Common Pitfalls

Many organizations make predictable mistakes during payroll upgrade and consolidation. First, underestimating configuration complexity. Payroll module configuration for even a single country requires weeks of effort. Global payroll with multiple countries and currencies requires months. Adding consolidation demands on top of upgrade demands extends the timeline further. Plan accordingly and resource adequately. Second, neglecting change management. Payroll teams, HR teams, finance teams, and employees all experience change when payroll migrates. Users accustomed to legacy system workflows will find F&O workflows different. Training and communication matter more than they seem to.

Third, skipping the parallel run. Running old and new payroll systems in parallel for at least one full cycle (monthly for most organizations) allows you to validate that the new system calculates payroll correctly and produces results that match the legacy system (or justify differences). Skipping this step and going live immediately risks discovering critical calculation errors after employees have been paid incorrectly, which creates compliance and employee relations damage.

Fourth, treating consolidation as a technical project rather than a business decision. Whether to consolidate particular countries is a business choice: it trades operational simplification against some loss of local autonomy. This decision should involve Finance Operations leadership and regional business leaders, not just the technical team. Without business buy-in, post-go-live support and change management will be harder.

Beyond the Upgrade: Continuous Improvement

After successful upgrade and consolidation, the payroll system is positioned for easier maintenance and evolution. The modernized module receives quarterly updates from Microsoft that include new tax rules, currency changes, and feature improvements. Organizations can adopt these updates more readily than they could with legacy systems, because the new architecture is designed for continuous change.

From a finance perspective, consolidated payroll also opens opportunity for better analytics. When all payroll runs through a single system and posts to the General Ledger in real-time, Finance teams can analyze labor costs, accruals, and headcount trends more easily and accurately. Payroll becomes less of a back-office compliance function and more of a finance analytics asset.

Next Steps for Finance Leaders

If your organization faces a mandatory F&O payroll module upgrade, the time to plan is now. Engage your Dynamics 365 technical partners early. Perform a comprehensive audit of your current payroll landscape: what systems do you have, what are the compliance and business requirements for each, and where is consolidation feasible? Build a realistic timeline and resource plan. Brief your CFO and business leaders on consolidation opportunities and trade-offs. And plan for adequate parallel-run validation before cutover, no matter how eager you are to decommission legacy systems.

The upgrade is mandatory, but consolidation is strategic. Making the right choice at this inflection point can simplify your finance operations for years to come.


Routeget Technologies helps finance-driven enterprises navigate Dynamics 365 F&O implementations, including payroll consolidation, global tax configuration, and upgrade program management. If your organization is planning a payroll module upgrade, our consulting team can help assess consolidation opportunities and design migration strategies that reduce risk and operational complexity.

#DynamicsFinanceOps #GlobalPayroll #PayrollIntegration #ERPModernization #FinanceOperations #MultiCountryPayroll #PayrollModuleUpgrade

Power Automate Error Handling: Building Resilient Cloud Flows That Don’t Fail Silently

Power Automate Error Handling Architecture Diagram

You launch a critical approval workflow into production, and for two months it runs without obvious issue. Then Finance calls: a vendor invoice sits stuck in limbo, and the escalation that should have fired never arrived. You check the flow history. The run shows “Succeeded,” but the approval task was never created, and no notification reached anyone. Silent failure, the kind that eats hours of investigation and delays payment cycles.

This scenario repeats across organizations deploying Power Automate at scale. The default error handling behavior in cloud flows is permissive and forgiving, designed to let flows complete even when individual actions fail. This is convenient during development but disastrous in production, where a missing HTTP response, a timing issue on an approval task creation, or an unexpected data format in a downstream system turns silent into undetected. The flow completes successfully by the application’s measure, but business logic never executes. Error handling in Power Automate is not a nice-to-have feature for robustness; it is the architectural foundation that separates production-ready automation from toy scripts.

Understanding Default Behavior and Why It Fails

By default, Power Automate treats a failed action like a skip. If an “Create an approval” action times out or receives an unexpected response, the flow continues to the next step. Conditional actions branch on the previous action’s status, but most flows don’t include that branching. An approval might never materialize, yet the flow proceeds as if it succeeded, sending payment confirmations or triggering downstream systems based on assumptions about work that never completed. Notification actions often sit at the end of a flow, so if an error occurs mid-stream and the flow halts before reaching the notification step, no one knows failure occurred. The inbox has no warning. The flow history shows green. Days pass before someone manually discovers the orphaned record.

This happens because Power Automate distinguishes between a failed action and a failed flow. A single failed action can leave the flow in a half-completed state that still reports success. Production systems need explicit acknowledgment of failure, not a default assumption of continuation. Scope actions, try-catch patterns, and notification strategies are the techniques that transform Power Automate from a convenient desktop automation tool into a reliable production system.

Scope Actions and Error Handling Tiers

The core building block for error handling in Power Automate is the Scope action, which wraps a logical group of steps and exposes four possible outcomes: Succeeded, Failed, Skipped, and TimedOut. A Scope action acts like a transaction container. If any step inside fails, the Scope itself fails, and you can then use the Configure run after property to branch on that failure state. Configuring a Scope so that downstream actions only run if the Scope succeeded is the first layer of error handling.

For critical workflows, organize Scopes into layers. A “happy path” Scope contains the main logic (create approval, send notification, update records). A “validation” Scope runs first and checks input data before attempting the main workflow. An “error handling” Scope runs only if the happy path fails, containing steps to log the error, notify a human, and roll back any partial state. This layering makes the flow’s intent explicit: if the happy path fails for any reason, the error layer kicks in. If the error layer itself fails (for example, the notification system is temporarily down), that failure is also visible and can trigger escalation.

Implementing Try-Catch Patterns

A try-catch pattern in Power Automate maps to a Scope (try) followed by a Configure run after rule (catch). After a critical Scope completes, even if it failed, configure the next action to run only if the Scope failed. Inside this catch block, add steps to capture what went wrong (log the error message and flow context), notify the appropriate person or system, and decide whether to retry or abandon. For approval workflows, a catch block might check if the approval was actually created (by querying Dataverse) before sending a notification. If the approval does not exist, log the specific error and notify a supervisor that manual intervention is needed.

The catch block should not attempt to continue the main business logic. Trying to recover by re-running the failed step or guessing at a default value introduces risk. Instead, catch blocks should focus on observation (logging), communication (notification), and escalation (routing to a person or alert system). This keeps the error path simple and auditable. When a catch block executes, someone should know about it, and the flow should stop rather than creating inconsistent downstream state.

Technical Team Reviewing Power Automate Error Handling Strategy

Handling Timeouts and Asynchronous Gaps

Timeouts are a class of failure distinct from logic errors. An action that calls an external API might exceed Power Automate’s timeout thresholds (2 minutes for cloud flows, 10 minutes for desktop flows) through no fault of the flow’s logic. A synchronous HTTP action to a slow third-party API will reliably timeout in production if that API experiences latency. Asynchronous patterns are the solution: instead of waiting synchronously, send an asynchronous request and poll for the result, with explicit limits on retries and elapsed time. A Scope action wrapping an HTTP POST followed by a repeat-until loop that polls for completion gives you control over timeout behavior.

Approval actions introduce similar asynchronous complexity. When you create an approval task, the action returns immediately, but the approval itself is time-consuming. If you try to check the approval’s response in the next step and the approver has not yet responded, your flow will either wait forever or timeout. Structure approval flows so that the approval creation is one Scope, any actions that depend on the approval response are in a separate step or flow triggered asynchronously (via a Power Automate Connector trigger or notification), and the main flow completes after the approval is created. This prevents the flow from blocking indefinitely and makes it clear which parts of the workflow are synchronous and which are asynchronous.

Notification and Escalation Strategies

An error that no one knows about is still an error. Every production flow needs explicit error notification. For non-critical flows, a daily digest of failed runs might suffice, sent to a service account inbox where admins can triage them. For critical workflows, errors should trigger immediate notification to an on-call engineer or supervisor through a dedicated notification system (Teams, Slack, email, or an alert system). Configure the notification to include the flow name, the step that failed, the error message, the affected record ID (invoice number, order ID), and a direct link to that flow run in the Power Automate admin portal so the engineer can investigate immediately.

For approval workflows, escalation is the second notification layer. If an approval sits unapproved for 24 hours, send a reminder to the approver. If it sits for 48 hours, escalate to the approver’s manager or a shared mailbox. Implement this using scheduled cloud flows that query the approval status in Dataverse and send conditional notifications based on elapsed time. This prevents approvals from silently stalling because someone’s mailbox was full or the approval notification was missed.

Testing Error Paths in Production

Error handling code that is never exercised is dead code. Most flow testing focuses on the happy path because that is where the visible business logic lives. But the error path is where reliability lives. Before pushing a critical flow to production, explicitly test failure scenarios: trigger an HTTP action to a nonexistent endpoint and confirm the error is caught and logged; simulate a timeout by adding a delay action and running it during off-hours; delete a required record midway through the flow to force a lookup failure; confirm that notifications fire and escalations trigger correctly. Production flows should have a pre-launch checklist that includes error path testing, not just happy path verification.

Common Architecture Mistakes

Avoid storing error handling logic in separate flows triggered by error notifications. Flows that handle errors should be part of the same versioned flow or called as child flows with explicit control flow. Separate error-handling flows that run asynchronously can miss new versions and become stale. Avoid generic retry logic that re-runs a failed action without understanding why it failed. Some errors are transient (network timeouts) and justify a retry; others are permanent (schema mismatch, missing data) and will retry indefinitely without fixing the root cause. Inspect the error message before deciding to retry. Finally, avoid logging errors to an unmonitored inbox. Logs that accumulate without review are useless. Use a proper telemetry system or a regularly tended shared mailbox so errors are actually seen and investigated.

Building Production Confidence

Error handling is not overhead added to a flow once it reaches production; it is the architecture that transforms automation from convenience to reliability. Flows that handle errors explicitly, notify on failures, and separate happy-path logic from error-path logic run predictably and build confidence with stakeholders who depend on them. The investment in error handling upfront, through scope actions, try-catch patterns, and notification strategies, is what separates a flow that your team trusts from a flow that your team monitors anxiously.


At Routeget Technologies, we architect Power Automate solutions that scale with production demands, building error handling and resilience into automation from the start rather than bolting it on after failures occur. If you’re deploying automation at enterprise scale and need guidance on error architecture or flow governance, our Power Platform specialists can help design systems your team can maintain and trust.

#PowerAutomate #ErrorHandling #CloudFlows #PowerPlatformDevelopment #ResilientAutomation #ApprovalWorkflows #PowerAutomateArchitecture

Dataverse Environment Strategy: Consolidation Versus Segregation

Dataverse consolidation vs segregation architecture comparison

When you first deploy Dataverse, the storage bill arrives as a small surprise. When you deploy your tenth instance, it arrives as a budget problem. This escalation is not accidental. It reflects a choice you likely did not consciously make: the decision to separate Dataverse environments.

Most organizations start with a single development environment, then add a staging environment for UAT, then a production environment for the main line of business. Six months later, there’s a second production environment for a parallel business unit. A year in, IT has provisioned separate Dataverse instances for finance, operations, customer service, and a pilot project that “just needed a sandbox space.” Each instance accrues storage costs, backup overhead, governance complexity, and security review burden. The organization paid for all of it. Few asked whether they needed to.

The question “Should we consolidate or segregate?” never came up because it felt obvious: production should be separate from development. But that clarity evaporates once you have multiple business units, overlapping data needs, and genuine compliance constraints. Consolidation looks cost-efficient until you calculate the management burden. Segregation looks secure until you realize your core customer data lives in four places and nobody knows which is authoritative.

The answer is neither pure consolidation nor pure segregation. It is strategy.

Understanding the Cost and Governance Tensions

Dataverse pricing ties directly to storage consumption and the number of instances you maintain. A 10 GB storage license costs roughly 100 USD per year. An organization with ten segregated Dataverse environments, even with light usage, pays backup, redundancy, and management overhead across each one. The cloud infrastructure beneath Dataverse (Azure) charges for compute, storage durability, and replication regardless of how full your instance is. A mostly empty Dataverse environment costs nearly as much as a full one.

Segregation creates what appears to be security clarity: production data stays in production, development in development, finance data in finance. This isolation has genuine value. A misconfigured Power Automate flow in a development sandbox cannot accidentally update live customer records. A security breach affecting one environment need not compromise all of them. But segregation imposes a hidden cost: data synchronization, duplicate records, inconsistent customer views, and reconciliation overhead. If customer records live in both a finance Dataverse and an operations Dataverse, which is the source of truth when they conflict? Who owns the resolution process?

Consolidation eliminates that duplication. A single Dataverse instance holding all enterprise data means one source of truth for customer records, one master file for products, one system of record for financial transactions. You skip the synchronization overhead, the reconciliation disputes, and the headache of knowing which Dataverse has the current information. The cost per record drops. But the security model becomes more complex. Consolidation means granting broader data access to more users and applications, requiring tighter role-based access control, field-level security rules, and auditing to prevent accidental or malicious data leakage. A single misconfigured permission model puts more data at risk than a segregated approach would.

Business team reviewing Dataverse environment strategy and cost metrics

When Segregation Makes Economic Sense

Segregation is the right strategy when regulatory compliance or data residency mandates isolation. A healthcare organization subject to HIPAA cannot store patient records alongside non-protected business data in the same system without additional access controls that approach the complexity of separate systems anyway. A financial services firm with customer data subject to SOX or PCI compliance, or an organization operating in multiple countries with GDPR or localization requirements, often finds segregation is mandated by policy rather than chosen for efficiency.

Segregation also makes sense when a subsidiary or business unit operates as a distinct legal entity with its own data ownership and governance. If your organization acquired a company and that company operates with its own finance department, separate Dataverse instances may be required during the integration phase and might remain appropriate long term to respect the subsidiary’s operational autonomy, even if they cost more.

Segregation further proves necessary when the organization lacks the governance maturity to enforce consistent security policies across shared data. If your Power Platform practice is young, permissioning discipline is inconsistent, and no one has ownership over a unified data governance framework, adding data to a consolidated Dataverse risks creating visibility into sensitive information that should remain restricted. In that case, segregation by business unit or application buys time for your governance practice to mature.

When Consolidation Reduces Total Cost of Ownership

Consolidation is strategically sound when you have multiple business units sharing core data, such as customers, products, and suppliers. The finance department’s customer master should be the same record your sales team references. The supply chain’s product master should be the source of truth for the pricing your finance team uses in invoicing. Consolidation eliminates the cost and risk of maintaining parallel records and reconciling discrepancies when they diverge.

Consolidation also makes sense when your organization has established governance discipline and a clear data stewardship model. If you have defined data ownership (finance owns the general ledger, supply chain owns inventory, sales owns opportunities), have role-based security groups mapped to those functional areas, and have audit mechanisms in place to catch permission violations, a consolidated Dataverse becomes a platform strength rather than a security risk. Your cost per record drops, your data consistency improves, and you simplify the user experience by giving people access to the unified information they need rather than requiring them to navigate to separate systems.

Consolidation further makes sense for organizations with mature ALM (application lifecycle management) practices. Consolidated Dataverse allows you to deploy solutions and flows to shared data layers without the release complexity of managing separate instances. Your development, staging, and production environments can all point to logically separated Dataverse spaces within a single instance, reducing provisioning overhead and backup complexity.

Hybrid Models and Environmental Separation Within a Single Instance

Many organizations land on a hybrid approach: one or two consolidated production Dataverse instances for the main business, with a separate development/test environment reserved for experimental solutions and non-production use.

This model recognizes that some segregation is necessary (development must be isolated from production), while consolidation of core business logic and shared data eliminates duplication and cost. Within a single Dataverse production instance, you use solution layers and environment variables to manage configuration differences for different business units or applications, avoiding the need for separate instances.

The Operational Complexity Multiplier

Many organizations underestimate the operational cost of managing multiple Dataverse instances. Each instance requires backup policies, disaster recovery testing, access control reviews, security patching coordination, and licensing reconciliation. Each instance needs monitoring for performance issues. Each introduces a potential point of data quality failure. If you have ten Dataverse environments with inconsistent master data definitions, ten different backup schedules, and ten separate access reviews, you have essentially maintained ten times the governance surface area compared to one consolidated instance.

Recommendations for Decision-Makers

Before you provision another Dataverse instance, ask whether the request stems from genuine compliance isolation or from organizational convenience. If it is convenience, consider whether investing in your governance model (clearer role definitions, field-level security policies, auditing) would be more cost-effective than the ongoing operational overhead of maintaining a separate instance.

If you already have multiple instances, analyze the actual data sharing patterns. Do core business entities (customers, products, suppliers) need to be synchronized across instances? If so, you are paying the cost of segregation while accepting the complexity of consolidation. A strategic consolidation project to merge those shared entities might cost less over three years than the recurring duplication and reconciliation overhead.

Document your environment strategy explicitly. Do not let instances accumulate by default. Routeget Technologies works with organizations to audit their existing Dataverse footprint, quantify the cost-benefit of consolidation versus continued segregation, and design transition plans that respect compliance constraints while reducing total cost of ownership. The difference between a well-planned environment architecture and an ad-hoc collection of instances often runs to hundreds of thousands of dollars annually for larger deployments.

Hashtags: #DataverseArchitecture #EnvironmentStrategy #PowerPlatformGovernance #EnterpriseDataManagement #DataverseCostOptimization #CloudGovernance #MicrosoftDataverse