Business Central’s Multi-Entity Consolidation: Automating Intercompany Eliminations and Accelerating Month-End Close Cycles

For finance leaders managing consolidated operations across multiple subsidiaries or business units, month-end close becomes exponentially more complex. Intercompany transactions multiply, elimination entries compound, and the coordination overhead among regional accounting teams can extend close cycles by days or even weeks. Business Central’s consolidation capabilities address this directly, turning what is traditionally a manual, error-prone process into a structured, repeatable workflow that reduces timeline pressure and audit risk.

The consolidation challenge in multi-entity environments stems from a fundamental accounting requirement: intercompany transactions must be eliminated from consolidated financial statements to avoid double-counting revenue, expenses, and balances. When subsidiary companies sell to each other, make loans, or share service costs, those internal transfers appear in each entity’s books but must net to zero at the consolidated level. Organizations relying on spreadsheets or manual journal entry processes spend days tracking down which transactions crossed between entities, calculating elimination amounts, and coordinating with multiple accounting teams to ensure each entity’s close is complete before consolidation can begin.

Business Central’s built-in consolidation engine simplifies this by allowing organizations to define intercompany relationships and elimination rules once, then apply them systematically across all monthly close cycles. The result is not just faster close timelines, but higher accuracy and auditability, since every elimination step is documented within the system rather than buried in email chains or spreadsheets.

Setting Up Multi-Entity Relationships

The foundation of Business Central consolidation is the ability to identify which company units participate in consolidation and how they relate to each other. In Business Central, each entity is typically a separate company database, though some organizations implement consolidation across multiple business units within a single company using dimension-based structures. The consolidation process begins by designating one company as the parent and establishing relationships with subsidiaries or operating units. This relationship structure becomes the roadmap for both data collection and elimination logic.

Business Central allows you to define these relationships through the Consolidation Setup and Elimination Rules interfaces. You specify which companies feed data into the consolidated view, whether transactions between those entities should be fully or proportionally eliminated, and what account mappings apply. For organizations with joint ventures or partially-owned entities, this flexibility matters: you can configure proportional consolidation so that an 80 percent-owned subsidiary contributes only its 80 percent portion of assets and liabilities to the consolidated balance sheet, while the minority interest appears as a separate line item.

The account mapping layer is critical because consolidated financial statements often require accounts from subsidiary companies to be remapped or reclassified before they roll up to the parent consolidated general ledger. Business Central’s mapping rules allow you to specify that subsidiary Account 1234 (Local Intercompany Revenue) should consolidate as Account 5001 (Consolidated Service Revenue) in the parent, which streamlines both data integrity and reporting consistency. Many organizations spend weeks manually reformatting subsidiary trial balances to fit corporate reporting structures, but Business Central eliminates that step by automating the mapping during consolidation.

Automating Intercompany Elimination Entries

The heart of the consolidation process is the elimination of intercompany balances. When subsidiary A sells goods to subsidiary B, both companies record transactions: subsidiary A books revenue and receivables; subsidiary B books an expense and payables. At consolidation, these must be eliminated so the consolidated income statement doesn’t overstate revenue or expenses, and so the consolidated balance sheet doesn’t carry duplicate receivables and payables for the same transaction.

Business Central automates this by allowing you to define elimination rules based on account pairs and dimensions. You can specify, for example, that any balance in Account 1200 (Intercompany Receivables) in the subsidiary should be eliminated against a matching balance in Account 2200 (Intercompany Payables) in the parent, or vice versa. The system can also handle more complex scenarios: if subsidiaries buy and sell from each other in a triangular relationship, you define rules that capture each pair of transactions and eliminate them systematically.

The elimination engine runs during the consolidation process, creating elimination entries that net intercompany balances. These entries are recorded within Business Central itself rather than exported to Excel or a separate consolidation tool, which means finance leaders can trace the elimination history, adjust individual eliminations if needed, and generate audit reports showing exactly which transactions were eliminated and why. For organizations that previously managed eliminations through manual spreadsheet reconciliation, this shift to system-based tracking eliminates one of the largest sources of month-end errors and audit concerns.

Consolidation Workflows and Timeline Acceleration

One of the most tangible benefits of Business Central consolidation is the ability to run a structured, repeatable close workflow. Instead of waiting for all subsidiaries to report their closes before beginning manual elimination work, the consolidation process can begin as soon as preliminary subsidiary data is available. Many organizations configure a two-phase close: in Phase One, subsidiaries submit preliminary closes and Business Central generates initial consolidation numbers and preliminary elimination reports. Finance teams review these and request adjustments if needed. In Phase Two, after final subsidiary closes are confirmed, the consolidation is rerun, and the consolidated financials are locked.

This two-phase approach compresses the overall timeline because you identify and resolve intercompany issues earlier rather than discovering them only after the subsidiary closes are supposedly final. It also gives finance leaders visibility into consolidated results days earlier, allowing them to brief the CFO or investor relations team on preliminary numbers while detailed reconciliation continues in the background. Organizations with complex consolidations frequently report that this visibility window alone justifies the consolidation system investment, as it reduces the stress of final-day scrambles to complete consolidated reporting.

Data Integrity and Audit Trail

A secondary but equally important benefit is the audit trail. Regulatory bodies and auditors expect to see documented evidence of how intercompany transactions were identified and eliminated. Spreadsheet-based consolidation processes generate no audit trail; changes are invisible, and it’s difficult to prove that eliminations were appropriate and complete. Business Central’s consolidation functionality records each elimination entry, the rule that triggered it, and the date and user who approved the consolidation run. This documentation directly supports financial audits and regulatory compliance, and it eliminates the common scenario where auditors request detail on a consolidation elimination, and the finance team must scramble to reconstruct the logic from scattered emails or deleted spreadsheet versions.

Implementation Considerations and Best Practices

Organizations moving to Business Central consolidation should anticipate a few practical decisions. First, does your consolidation structure map neatly to Business Central’s company model, or will you need to use dimensions or manual adjustments to capture some relationships? Second, do you have intercompany pricing disputes or approval workflows that must occur before eliminations are finalized? Third, what reporting format do regulators or corporate require, and does Business Central’s consolidation output generate the required schedules natively or with manual tailoring?

Most organizations find that consolidation savings justify a focused implementation effort. A three-subsidiary consolidation that previously took 8 to 10 days typically compresses to 4 to 5 days; larger multi-subsidiary operations see proportionally larger gains, especially as the consolidation becomes routine and refinements are made over the first two to three cycles. Performance improves even further when you build business logic that prevents intercompany transactions from being recorded incorrectly in the first place, such as using intercompany purchase/sales order workflows with built-in validation that ensures subsidiary A’s order to subsidiary B matches subsidiary B’s receipt and supplier invoice.

Practical Path Forward

For finance leaders evaluating Business Central or preparing for a consolidation implementation, the starting point is a clear map of your intercompany relationships and current elimination volumes. Work with your implementation partner to quantify the current cost of manual consolidation: time spent, error correction, audit workload, and management time resolving reconciliation issues. Model how Business Central’s consolidation features reduce that cost. Most implementations recover their investment within the first year through close timeline reduction and reduced month-end overtime. Beyond the first year, the ongoing benefit is consistent month-end cycles and improved visibility to consolidated results early in the close window, enabling faster strategic decision-making at the board and investor-communication level.


About Routeget Technologies: Routeget Technologies specializes in Dynamics 365 and Microsoft Power Platform implementations for mid-market and enterprise organizations. Our finance operations consultants have guided multi-subsidiary consolidation implementations across diverse industries, and we understand both the technical configuration and the change management required to shift from manual to system-driven month-end close processes.

#BusinessCentralConsolidation #MonthEndClose #IntercompanyElimination #FinanceOperations #MultiEntityAccounting #FinancialConsolidation

Building a Data Governance Framework for Dataverse: Compliance, Audit Trails, and Access Control in Enterprise Deployments

Organizations managing sensitive customer and operational data in Microsoft Dynamics 365 and Dataverse face an increasingly complex landscape of regulatory requirements, internal audit obligations, and stakeholder governance expectations. Compliance frameworks such as GDPR, HIPAA, SOX, and industry-specific standards place explicit demands on how data is accessed, modified, and retained. Yet many enterprise Dataverse deployments treat data governance as an afterthought, layered on top of an already-live system rather than architected from the start. This creates risk exposure and operational friction that audit teams and compliance officers spend months trying to remediate.

A deliberate data governance framework in Dataverse addresses this directly by establishing clear ownership, access control, and audit visibility before deployment rather than retrofitting governance months after go-live. The framework does three things well: it ensures that only authorized users can access or modify specific data sets, it creates a durable audit trail of who accessed what data and when, and it establishes accountability structures so that business leaders can quickly answer regulatory or audit inquiries about data handling practices.

Building this framework requires decisions across three dimensions: access architecture (who can see what data, and under what business conditions), audit and logging (what changes are tracked and who can access the audit trail), and data lifecycle management (how long data is retained and under what conditions it is purged). These are not purely technical decisions; they emerge from business governance policy and compliance requirements that should be clearly articulated by compliance, legal, and audit teams before implementation begins.

Access Control as the Foundation

Dataverse’s access control model starts with role-based security, where security roles define capabilities at a feature level (can a user create, read, update, or delete records of a given entity type) and share permissions (can a user see records owned by others). However, role-based control alone is coarse-grained: it does not distinguish between records within an entity type based on data sensitivity, business unit, or customer segment. Two users with the same security role can see all records in an entity, even if one should only see records for their own geographic region or customer vertical.

Dataverse adds two layers to refine access further: organization-owned versus user-owned record ownership, and team ownership structures that allow a set of records to be owned by a team rather than an individual. These features help, but they require discipline during implementation to be effective. A common mistake is to grant broad organization-level access to an entity because it feels simpler than setting up team-based ownership, then later realizing that users can see sensitive data they should not have access to.

A governance framework addresses this by establishing a clear access matrix during design: for each entity (or entity family such as customer records, financial transactions, or employee data), the framework defines which security roles can perform which operations, which records are owned by individuals versus teams, and whether sensitive fields within an entity require additional field-level access restrictions. Field-level security in Dataverse allows you to hide or restrict modification of specific fields to certain security roles, which is powerful for protecting sensitive columns like salary, medical information, or SSN without resorting to separate entities.

This mapping should be documented in a way that business stakeholders understand: a simple table showing entity type, record ownership model, security roles with access, and any field-level restrictions answers the question “who can see what” in business language rather than technical jargon. Once documented, this matrix becomes part of your governance baseline and a reference for onboarding new users or reviewing access during audit cycles.

Audit Trails and Change Tracking

Regulatory compliance often requires proof that sensitive data changes were made by authorized users and can be traced back to a business justification. Dataverse’s audit feature logs create, update, and delete operations on specified entities, recording the user who made the change, the timestamp, and the old and new field values. However, audit logs are only valuable if you know which entities to monitor and if you actively use the audit data to investigate access patterns or unusual changes.

A governance framework defines a “audit perimeter”: which entities are subject to audit logging, which fields within those entities are critical enough to track for compliance purposes, and how long audit logs are retained. For example, if you are handling customer payment information subject to PCI compliance, you would want to audit all access to payment card entities, even read-only access, and retain those logs for a defined period (often several years). In contrast, audit logging for a reference data entity such as product definitions might be less stringent.

The second component is audit access control: who is allowed to view audit logs, and can they be relied on as evidence of compliance? If system administrators can create, view, and delete audit logs at will, the audit trail loses credibility as a compliance artifact. A governance framework should separate the role that creates audit data (system operations, powered by Dataverse’s audit configuration) from the roles that access audit data for review (compliance, audit, and security teams). Ideally, audit logs are exported to a separate system (such as Azure Synapse, a data lake, or a SIEM) where they cannot be modified or deleted by user actions in Dataverse itself.

Audit Dataverse also provides change tracking, which is a lighter alternative to full audit logging: it records that a field changed but not the old value. Change tracking is useful for detecting unauthorized modifications to master data or configuration, even if you do not need the full audit trail for compliance purposes. Including change tracking in your governance framework for non-sensitive entities can help catch data quality issues or accidental overwrites without the overhead of full audit logging.

Data Lifecycle and Retention Policy

A complete data governance framework includes decisions about how long data is retained, what happens to data at end of life, and who is responsible for data purging. Many organizations default to infinite retention because deletion feels risky, but indefinite data retention creates compliance risk: GDPR’s right to be forgotten, for example, requires that personal data be deleted upon request unless there is a specific legal basis to retain it. Retaining data longer than necessary also increases the attack surface and creates unnecessary storage costs.

Establishing a retention policy within your governance framework requires collaboration between business (which teams use the data and for how long), legal and compliance (what regulations require), and IT operations (how to efficiently delete or archive data at scale). A retention policy might specify that customer contact records are retained for seven years after the last transaction, that employee data is retained for three years after termination, or that transactional logs are retained for five years. Each entity or data family should have a defined retention period and a corresponding deletion procedure.

Dataverse does not have automatic data purging built in, so a retention policy requires an operational process: either a scheduled flow that identifies records past their retention date and deletes them, or a manual review process where designated users approve deletion in batches. For sensitive data categories such as health information or financial records, requiring explicit approval before deletion adds an extra control layer. For high-volume, less-sensitive data such as transactional logs, automated purging based on the retention policy is more practical.

Governance in Practice: Implementation Guidance

Building a governance framework in practice means translating policy into configuration. Start with an access matrix workshop bringing together business owners, security leads, and compliance representatives to define who needs access to which data and under what business conditions. Document the decisions in a shared reference (ideally a wiki or shared document that evolves as policy changes).

Then configure Dataverse to enforce the policy: set up security roles matching the matrix, assign users to roles, configure team ownership for records requiring shared access, enable field-level security for sensitive columns, and enable audit logging for entities and fields subject to compliance requirements. Finally, establish operational procedures: a regular access review process (quarterly or annually, depending on risk tolerance), audit log review cadence, and a data purging schedule aligned with retention policies.

The configuration itself is less complex than the governance discipline: determining who should have access to what requires honest conversation between business and security teams about acceptable risk, and committing to a data lifecycle policy requires agreement on trade-offs between data utility and data minimization.

Conclusion

A well-designed data governance framework in Dataverse reduces compliance risk, strengthens audit readiness, and provides business leaders with confidence that data access and handling are under control. The framework is not a one-time deployment task; it is an ongoing practice of documenting policy, enforcing policy through configuration, and monitoring policy adherence through access reviews and audit trails. Organizations that treat governance as foundational from the start avoid the costly and painful remediations required when governance is bolted on after deployment.

Routeget Technologies’ consulting and implementation practice brings experience in designing and implementing governance frameworks across hundreds of Dynamics 365 and Dataverse deployments. Our approach combines regulatory expertise with hands-on Dataverse configuration to build governance models that are both compliant and operationally practical for your organization’s specific risk profile and business requirements.

#DynamicsDataverse #DataGovernance #ComplianceFramework #MicrosoftDataverse #EnterpriseGovernance #SecurityControls #DataPrivacy #ERPGovernance

—

#DynamicsDataverse #DataGovernance #ComplianceFramework #MicrosoftDataverse #EnterpriseGovernance #SecurityControls #DataPrivacy #ERPGovernance

Rethinking Field Service ROI: Optimizing Technician Productivity and Dispatch Efficiency in Dynamics 365

The Hidden Cost of Inefficient Dispatch

Field service operations face an acute contradiction. Labor represents 60 to 75 percent of operating costs, yet most organizations still measure field service success through a single metric: technician utilization rates. The problem is that optimizing for pure utilization masks the real business challenge: field service organizations are facing a simultaneous squeeze on two fronts. Technician shortages are forcing wages higher, while customer expectations for first-time resolution and rapid response have become table stakes. Traditional approaches to cost control focus on cramming more billable hours into each technician’s week. But that approach hits a ceiling quickly, and it misses what actually matters to the bottom line.

The industry is shifting toward a different framework. Forward-looking field service leaders are moving from “utilization” to what industry researchers call “absorption”—a measure of the value and revenue delivered relative to the total cost invested. This distinction changes the equation entirely. Instead of asking “how many hours did my technician bill this week,” the question becomes “how much customer value did my technician create relative to their loaded cost.” That shift reframes the role of scheduling, dispatch, and resource optimization as strategic business levers, not just operational conveniences.

Dynamics 365 Field Service, combined with intentional dispatch and scheduling practices, creates a foundation for this transition. The technology itself does not generate ROI. The ROI comes from how organizations use the platform to address three concrete business problems that field service leaders face every day: reducing the time technicians spend traveling between jobs, increasing the likelihood that jobs are completed correctly on the first visit, and accelerating how quickly new technicians reach full productivity.

Consider what happens in a typical field service organization without optimized scheduling

A dispatcher has ten open work orders scattered across a geographic territory. Three are in the north part of town, four in the south, and three downtown. The dispatcher assigns work based on availability and rough geographic intuition. Technician A gets jobs that take them from north to downtown to south and back north again. The result is not just wasted mileage and vehicle wear. It is also decision fatigue. Technicians spend cognitive energy managing routes instead of focusing on the technical problem in front of them. They arrive at some jobs stressed and rushed because they are already behind on the day’s schedule.

Predictive dispatch works differently. The Dynamics 365 Resource Scheduling Optimization capability considers not just geography, but real-time traffic patterns, technician skill sets, job complexity, customer priority, and historical completion time data. It then proposes an assignment that minimizes travel, ensures skill match, and sequences jobs in an order that balances workload throughout the day. The technician’s route is optimized before the day begins. They know exactly where they are going and in what order. The cognitive load drops, and focus returns to the technical work.

The business impact is measurable. Organizations that implement optimized dispatch typically reduce vehicle mileage by 15 to 20 percent. More importantly, they reduce overtime and call time variance. A technician whose route is optimized completes more jobs per day in regular hours, reducing the need for emergency overtime and the associated wage premiums.

First-Time Fix Rate and Customer Value

The most expensive field service call is the one that does not fix the problem. When a technician leaves a customer site without resolving the issue, the cost compounds: another technician must be dispatched, the customer’s downtime extends, satisfaction drops, and the business loses the opportunity to deliver the high-margin services and upgrades that typically come with satisfied customers.

Dynamics 365 Field Service provides technicians with integrated access to customer account history, prior service records, equipment configuration data, and step-by-step work instructions. This capability sounds straightforward, but it changes the economics of first-time fix rates. A technician arriving at a job with full context about the customer, the equipment, and the history of prior issues approaches the problem differently than one working from a work order alone. They ask better questions upfront. They anticipate potential failure modes based on history. They have decision trees and troubleshooting guides embedded in their workflow.

The impact on first-time fix rates is substantial. Organizations that implement integrated field service and CRM operations consistently report first-time fix rate improvements of 10 to 20 percentage points. That translates directly to reduced follow-up calls, lower cost of service delivery, and improved customer satisfaction scores. For a service-based business, first-time fix rate is a direct lever on both cost and revenue.

Accelerating Technician Productivity

Field service organizations are not only struggling with labor costs; they are struggling with skill gaps. The industry faces an acute talent shortage as experienced technicians retire. When a new technician is hired, the traditional path to productivity takes 18 months or more. The technician learns the products, the tools, the processes, and the judgment required to handle complex issues independently. During that ramp period, their productivity is a fraction of a fully trained technician’s output, yet their loaded cost (salary, benefits, overhead) remains fixed.

Dynamics 365 Field Service, combined with Copilot in Field Service, changes this trajectory. AI-assisted work order summaries, guided troubleshooting, and integrated knowledge bases allow newer technicians to approach complex jobs with structured guidance. The cognitive load of decision-making is distributed between the technician and the system. What might have required escalation or experienced technician involvement can now be handled by someone earlier in their career. Industry research suggests that well-implemented AI-assisted field service can compress the time-to-productivity from 18 months to nine months or less.

The ROI calculation on this capability is compelling. If a new technician’s fully loaded cost is $80,000 per year, cutting ramp time in half represents $40,000 in value per hire. In organizations that hire dozens of technicians annually, this compounds quickly.

From Cost Center to Value Driver

The shift from “utilization” to “absorption” requires a change not just in technology, but in how field service success is measured and managed. Utilization optimization focuses on squeezing more hours out of existing headcount. Absorption optimization focuses on the business value created per dollar spent on labor and operations.

Implementing Dynamics 365 Field Service with intentional dispatch optimization, first-time fix focus, and knowledge-based technician support addresses all three of these value drivers simultaneously. Optimized dispatch reduces travel costs. Integrated information and AI-assisted guidance improve first-time fix rates and customer satisfaction. Structured support accelerates new technician productivity. The compounding effect of all three is that field service shifts from being a cost center that leadership watches closely to contain to being an operations capability that actually drives customer satisfaction and loyalty.

For CFOs and operations directors, this reframing matters. Field service is no longer about staffing ratios and billable hours. It is about customer outcomes and the value created per unit cost. Organizations that make this transition gain a competitive advantage that is not easy to replicate through hiring or wage competition, because the advantage is embedded in operational discipline and decision-making, not just in resource count.

Making the Transition

Starting this transition does not require a complete overhaul of existing field service operations. Most organizations begin by implementing the Resource Scheduling Optimization capability and focusing on optimizing dispatch for the highest-volume service types. This creates visibility into what the current inefficiencies are and generates quick wins in mileage and overtime reduction.

The next step is typically integrating field service tightly with CRM so that technicians have full context about customers and prior service history at their fingertips. This is where first-time fix rate improvements materialize.

Finally, implementing AI-assisted guidance and structured troubleshooting processes drives technician productivity and accelerates onboarding of new staff. Each of these steps is incremental. Together, they reposition field service from a cost center requiring discipline to a value creator with measurable impact on customer satisfaction and retention.

The field service technician shortage is real, and it is not going to resolve by hiring more people. The organizations that thrive are those that deploy technology, process discipline, and intentional decision-making to get more value from the technicians they have. Dynamics 365 Field Service, deployed with predictive dispatch and customer context integration, is the foundation for that transition.


#FieldServiceOptimization #DynamicsFieldService #DispatchEfficiency #TechnicianProductivity #ServiceOperations #CustomerServiceROI #OperationsManagement

Integrated Demand Planning in Dynamics 365 Supply Chain: Reducing Holding Costs While Maintaining Service Levels

Three weeks into the fiscal quarter, your operations team discovers a $2 million gap between forecasted demand and what’s actually materializing. The warehouse is overstocked on items that barely move while fast-movers are starting to show stockout risk. Your supply chain director is now stuck between two uncomfortable choices: write down excess inventory that tied up cash all season, or rush-order replacements at premium freight costs to cover the shortfall.

This scenario plays out across industries, and it’s rarely solved by better guesswork. The tension between holding inventory to avoid stockouts and minimizing carrying costs is fundamental to supply chain operations. Most companies manage this through safety stock formulas, manual adjustments, and reactive expediting that keeps procurement teams firefighting rather than planning.

The core insight is that demand planning and inventory optimization cannot be separated. When demand forecasting is isolated from inventory decisions, planners generate accurate forecasts that operations teams can’t act on effectively. When demand planning is truly integrated with supply planning, inventory decisions are grounded in forecast accuracy, lead time realities, and explicit service level targets. Organizations using this integrated approach typically reduce inventory carrying costs by 10-20 percent while improving fill rates and reducing expedited shipments.

Dynamics 365 Supply Chain Management’s demand planning capabilities, enhanced in the 2026 release, provide this foundation for integration. The platform’s collaborative planning environment and AI-driven forecasting allow business leaders to shift from static safety stock policies to dynamic, responsive inventory optimization.

How Demand Accuracy Directly Impacts Your Inventory Equation

Safety stock levels are calculated from demand variability around a baseline forecast. If your forecast misses demand by 15 percent regularly, your safety stock multiplier must climb to protect service levels. That multiplicative effect on safety stock costs money directly.

When your forecasting model identifies demand patterns and external drivers accurately, variability tightens. Less variability means lower safety stock requirements. A supply chain director managing $500 million in inventory can recapture significant working capital by reducing safety stock from 30 days of supply down to 20 days if forecast accuracy improves from 70 percent to 85 percent. At typical inventory carrying costs of 20-25 percent annually, that recapture translates to $7-$10 million in freed capital.

Dynamics 365’s demand planning system uses machine learning to tune forecasting parameters across products and time periods. The system automatically evaluates multiple forecasting models, including promotional calendars, seasonality patterns, and pricing signals. For 2026, Microsoft introduced capabilities that explicitly model how pricing changes correlate with demand shifts, letting planning teams run unified pricing-and-demand scenarios rather than treating price and volume as independent variables.

This matters operationally because promotions and price changes are often your biggest demand drivers. If your forecasting system can account for the fact that a 10 percent price reduction typically drives 25 percent higher volume in a particular product line, your demand planner can propose more accurate promotional forecasts, and your supply planner can set inventory targets that reflect what the demand will actually be.

Collaborative Planning Reduces the Forecast-to-Execution Gap

Demand forecasting accuracy depends on algorithm sophistication and on human judgment applied at the right moment. Data scientists build excellent models. Supply chain practitioners know where the models will fail due to new customer wins, discontinued products, or market disruptions. The friction that kills many demand planning efforts is organizational: the people who understand demand nuances are not integrated into the planning process, and the forecast becomes outdated once it leaves the data team.

Dynamics 365 addresses this through Teams integration and in-product commenting that keeps demand planners, supply planners, and stakeholders in conversation throughout the planning cycle. A sales leader can flag that a major customer is launching a new product that will boost Q3 demand. That annotation feeds into the planning conversation immediately, and the system can adjust scenarios. Version history ensures you can trace forecast evolution and audit the decisions that shaped your inventory target.

This collaborative dimension accelerates plan consensus. Rather than demand planners publishing a forecast that supply planners discover months later had uncommunicated assumptions, both teams are reviewing the same data in the same worksheets, commenting on the same scenarios, and aligning on the rationale before numbers drive supply decisions.

Connecting Demand Plans to Inventory and Supply Decisions

Demand accuracy means nothing unless your supply planning system can act on it decisively. Dynamics 365 integrates demand plans directly into supply chain planning, where the system calculates replenishment orders based on the demand forecast, lead times, and specified service level targets. Rather than applying a fixed safety stock percentage across all products, the system calculates product-specific safety stock based on forecast variability, lead time variability, and your target fill rate.

For supply chain directors, this translates into explicit control: you specify the service level you are willing to commit to each product line or customer segment (for instance, 95 percent fill rate for critical spares, 98 percent for core products), and the inventory optimization engine calculates the inventory target to achieve that service level. When demand forecasts improve, variability tightens, and the system automatically recommends lower inventory levels. When forecast uncertainty rises, the system adjusts inventory targets upward to maintain your stated service level.

This dynamic adjustment is critical because it prevents the trap of static safety stock policies. Many supply chains operate with safety stock multipliers set five years ago, based on demand patterns that have since changed fundamentally. By anchoring safety stock to current forecast accuracy and explicitly to your service level targets, you maintain the performance you committed to without over-investing in inventory that no longer provides value.

From Insight to Action: Reducing Cost While Sustaining Service

The economic benefit of improved demand planning flows to multiple areas simultaneously. Lower inventory carrying costs are obvious. Reduced expediting and premium freight follows, because accurate demand plans allow procurement to place orders with appropriate lead times rather than correcting surprises with air shipments. Improved fill rates reduce operational cost and customer friction; fewer chargebacks from stock issues improve working capital.

The harder case for many organizations is the behavioral shift: moving from safety stock as always-purchased insurance to inventory levels continuously optimized based on demand intelligence. Dynamics 365’s scenario analysis and version history support this transition. Planners can run what-if scenarios to visualize inventory and service level impact of different forecast assumptions. They can review forecast version history and see, quantitatively, whether lower demand forecasts actually resulted in worse service levels or better performance with less inventory. Concrete evidence shifts mindsets more effectively than training presentations.

Why Integration Matters More Than Sophistication

The demand planning capabilities in Dynamics 365 are technically sophisticated. The no-code interface that allows 85 percent of demand planners to build models and run scenarios is significant. The AI parameter tuning and multi-model evaluation are valuable. But the real competitive advantage is integration: demand plans flow directly into supply planning, which updates inventory targets and replenishment orders, feeding back visibility to procurement and operations teams in real time.

Many organizations buy best-of-breed demand planning tools and then struggle to operationalize forecasts because they live in separate systems, updated monthly, with manual handoffs to the ERP that often break or lag. The cost of maintaining that friction often exceeds the value of incremental forecasting accuracy.

Dynamics 365 eliminates this friction. Demand and supply plans are in the same system, using the same data, on the same cadence. When a new forecast is published, the supply planning engine immediately recalculates replenishment orders and inventory targets. Procurement teams see updated requisitions without waiting for batch processes or manual imports.

For supply chain leaders, this integration is the difference between a demand planning initiative that delivers margin improvement and one that becomes a technical exercise with limited operational leverage.

Conclusion: Shifting from Static Buffers to Dynamic Optimization

Inventory optimization is a core lever for improving supply chain efficiency and working capital utilization. The transition from static safety stock policies to dynamic, forecast-driven inventory optimization requires better demand visibility, tighter integration between demand and supply planning, and the ability to translate improved forecasts into actual inventory reduction. Dynamics 365 Supply Chain Management, particularly with the 2026 enhancements to demand planning and pricing-demand correlation analysis, provides the platform infrastructure and collaboration features that enable this shift.

Organizations that effectively implement integrated demand and supply planning typically move from a reactive posture, where they are constantly correcting demand surprises with expediting and markdowns, to a predictive one, where inventory levels are right-sized to performance targets and planners spend time optimizing the plan rather than recovering from forecast misses. That shift frees working capital, reduces operational complexity, and builds a more resilient supply chain.


Routeget Technologies has extensive experience implementing demand planning and inventory optimization in Dynamics 365 Supply Chain Management for manufacturing and distribution organizations. Our consulting teams work with supply chain leaders to define service level targets, align demand and supply planning processes, and establish the governance structures that ensure forecasts translate into actionable inventory decisions. If your organization is looking to modernize demand planning and improve supply chain efficiency, connect with us to discuss your specific supply chain challenges.


#DemandPlanning #SupplyChainOptimization #Dynamics365SCM #InventoryManagement #SupplyChainStrategy #ERPSupplyChain #IntegratedPlanning #SupplyChainFinance

Building Enterprise-Grade Business Central Extensions: AL Language Best Practices, Dependency Management, and Performance Optimization

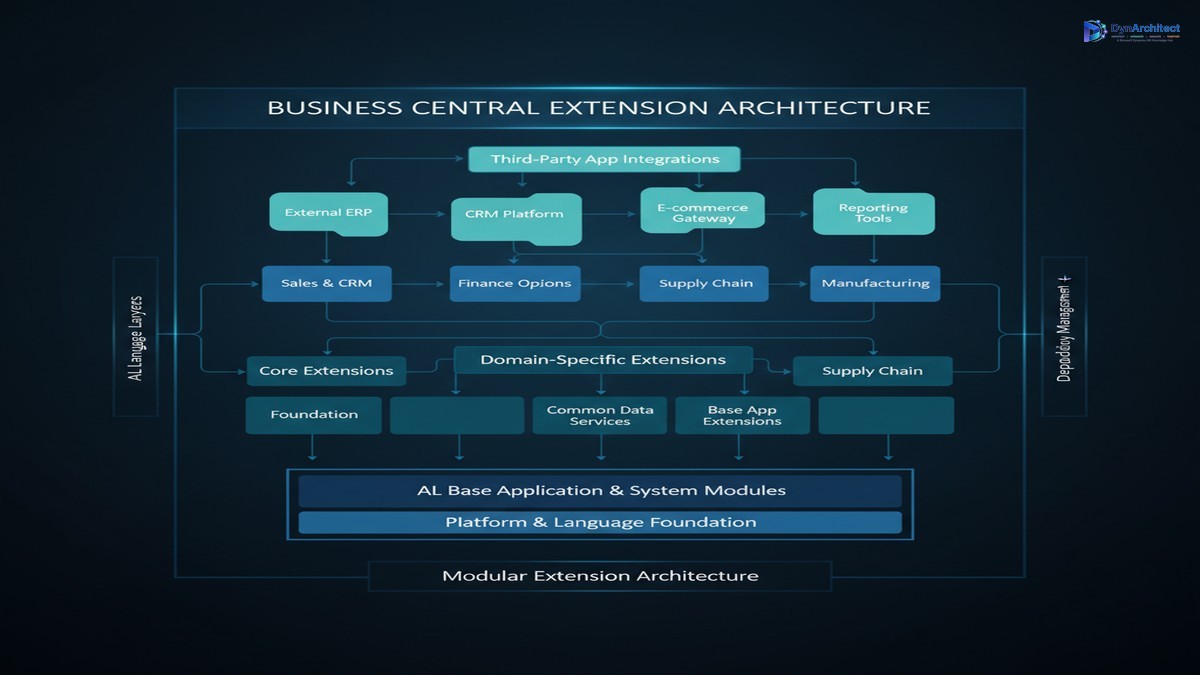
Business Central extension architecture and dependency management diagram with AL language layers and modular integration

The temptation to underestimate Business Central extension complexity is real, especially for teams migrating from legacy systems like Dynamics NAV or Dynamics GP. You get the cloud, you get the Azure-backed infrastructure, and suddenly extension development feels like the easy part. It rarely is. The AL language itself is modern and approachable, but scaling extensions across multi-tenant deployments, managing breaking changes across versions, and keeping runtime performance acceptable requires architectural thinking most teams discover too late.

Business Central extension architecture diagram with AL language layers and modular integration

## The AL Language Layer: Beyond the Syntax

AL is not a thin wrapper over familiar patterns. It is a type-safe, metadata-driven language designed specifically for Dynamics 365 Business Central’s event-driven architecture. This distinction matters. Writing valid AL code is different from writing maintainable extensions that survive updates, integrate with other extensions, and perform predictably under load.

Most teams encounter this when they begin mixing AL patterns across their own extensions. One team member uses procedural code for large batch operations, another chains event handlers expecting sequential execution, and a third builds data structures that clash with AL’s table metadata constraints. These choices do not fail immediately; they fail at scale, or during the next Business Central update, or when a customer deploys your extension alongside a third-party solution that makes similar assumptions.

The foundational discipline is understanding AL’s object model and metadata binding. Every AL object (table, page, report, codeunit) declares its intent at design time, not runtime. A table’s primary key structure is immutable once deployed to production; a field’s data type cannot be changed without data migration; relationships between tables are defined through foreign keys at the metadata level, not through application-level joins in procedural code. Teams that build to this model, treating metadata declarations as contracts, tend to survive updates and extensions conflicts far better than teams that treat AL as a generic imperative language.

## Dependency Management and Extension Composition

As your custom solutions grow, extensions accumulate. You likely have a base extension providing core business logic. You probably have domain-specific extensions for finance, supply chain, manufacturing. You may have third-party solutions from AppSource or custom integrations. Each one loads and runs within the same Business Central instance. Dependencies between them are not optional; they are architectural.

Many teams manage dependencies informally: a naming convention for tables, an unwritten rule about which extensions can call which, or careful manual testing to confirm no conflicts emerge. This works until it does not. You deploy an updated third-party extension, and suddenly your base extension’s event handlers no longer fire as expected because the third-party extension registers handlers on the same objects with different priorities. You add a new custom field to a table, and a report in an existing extension breaks because it makes assumptions about field structure. You rename an event in one extension and the dependent extension fails to bind at runtime because neither extension explicitly declares the dependency.

The right approach is treating extension composition as a design problem, not a deployment logistics problem. Each extension should declare its dependencies in its app.json file explicitly. Each extension should own a well-defined set of tables, pages, and events. Cross-extension calls should flow through clearly defined APIs (integration codeunits, events that other extensions are explicitly invited to subscribe to) rather than directly against tables or internal procedures. When an extension changes, dependent extensions fail to compile or at runtime hook registration fails, and you know immediately rather than discovering problems in customer deployments.

## Event-Driven Architecture and Handler Ordering

Business Central extensions operate in an event-driven model. You do not subclass objects or override methods; you subscribe to events that fire at defined points in the object lifecycle. This is powerful for extensibility and far less fragile than inheritance-based architectures. It is also deceptively easy to misuse.

A common mistake is assuming event handler execution order is deterministic. Two extensions both subscribe to the OnBeforeInsert event of a table. Which handler runs first? The answer is “undefined” without explicit priority declaration. If your logic depends on one handler running before the other, you are building a house of cards. A customer adds another extension, or AppSource releases an update, and handler order shifts. Your business logic breaks silently or produces incorrect results.

The principle is simple: make no assumptions about handler ordering unless you explicitly control it. If your extension depends on data being modified or events being raised in a specific order, declare that dependency. Use event priorities consciously. Consider whether a sequence of handlers can be reorganized into a single orchestration point rather than a chain of unordered event subscriptions.

Similarly, avoid performing long-running operations inside event handlers. Business Central event handlers execute synchronously within the transaction context of the triggering operation. A long-running SQL query, an external API call, or a batch data operation inside an event handler blocks the user interaction and risks transaction timeout. If you need to coordinate complex operations, use scheduled jobs, background tasks, or power integration orchestration outside the event handlers themselves.

## Performance Optimization and Query Patterns

Business Central extensions live in a multi-tenant cloud environment with resource governance. You do not own the database; you rent capacity. Query patterns that perform acceptably on a local single-tenant installation often stumble under load in production because of contention and resource limits.

The fundamentals are straightforward but often overlooked. Write efficient queries: use table keys for filtering, avoid unnecessary fields in SELECT projections, filter data at the database level rather than loading entire tables into AL variables. Use batch operations for bulk changes rather than loops with individual updates. Avoid queries inside event handlers that fire on every transaction. Profile your code using Business Central’s telemetry infrastructure to identify actual bottlenecks rather than optimizing on instinct.

One frequent pattern error is the “load all data then filter” approach. You write a report that loads every sales order in the company and then filters in AL code. This works fine with 500 orders; it fails when you have 500,000. The correct pattern is filtering at the database level using AL’s table filtering syntax, then loading only the rows you need.

Another is the N+1 query pattern. You loop through a set of header records and for each one, you run a query to load related detail records. With 1,000 headers, this becomes 1,001 queries. The correct approach is a single query that retrieves all headers and details in one operation, or two queries that load all data at once and correlate in AL code.

Business Central AL development environment showing code quality patterns and performance optimization

## Version Updates and Breaking Changes

Business Central updates every month. Your extensions must survive these updates. Microsoft maintains backward compatibility for the AL language and most APIs, but they do not guarantee that your custom logic will behave identically. Events might fire in different orders after an update. Performance characteristics might shift. New objects might shadow or conflict with your custom objects.

The practical answer is testing. You should regression test every extension after every Business Central update before deploying to production. Run your critical business flows, confirm that reports produce expected results, verify that integrations still function. This is not optional tooling; it is a requirement for stable production deployments.

You should also stay aware of deprecation announcements. Microsoft signals breaking changes well in advance. Review the release notes before each update. If your extension uses an API marked as deprecated, plan to migrate off it before support ends.

## Deployment Patterns and Lifecycle Management

How you package and deploy extensions matters. Most organizations start by deploying all custom extensions into a single App Package file, or worse, as a single sandbox solution from Visual Studio Code. This works at small scale. At scale, it becomes a bottleneck. A single developer making a small bug fix to one feature must rebuild and redeploy the entire package, potentially blocking deployments by other teams. A customer wants to selectively disable a feature without rebuilding the whole solution.

The mature approach is modular packaging. Core functionality lives in a base extension. Domain-specific logic lives in separate, focused extensions that depend on the base. Third-party solutions integrate through published events and APIs. Each extension is versioned, deployed, and updated independently. Customers can subscribe to updates or defer them based on their readiness, rather than being locked to a monolithic release cycle.

You should also have a clear Application Lifecycle Management (ALM) strategy. Version your extensions. Maintain a change log. Test updates in a staging environment before production. Have a rollback plan if an update causes issues. Business Central app upgrades are designed to handle schema migration and data transformation automatically in many cases, but only if you structure your deployments correctly.

## Path Forward

Building robust Business Central extensions is not about mastering AL syntax; it is about understanding the platform’s model, planning dependencies deliberately, avoiding common performance pitfalls, and treating versioning and deployment as architectural concerns rather than afterthoughts. Teams that succeed do this from the start. Teams that struggle usually discover these principles only after something breaks in production.

If you are starting extension development, adopt these practices early. If you are maintaining existing extensions, audit them against these principles. Refactoring to improve dependency management or performance optimization costs time upfront but pays back almost immediately in reduced support burden and faster deployment cycles.

Building enterprise-grade Business Central solutions requires discipline, but it is entirely achievable if you are intentional about architecture from the outset.

#BusinessCentralAL #DynamicsExtensions #ALLanguagePatterns #ExtensionArchitecture #BCPerformanceTuning #CloudERP

Building a Center of Excellence for Microsoft Cloud Governance: Establishing Control Without Stalling Innovation

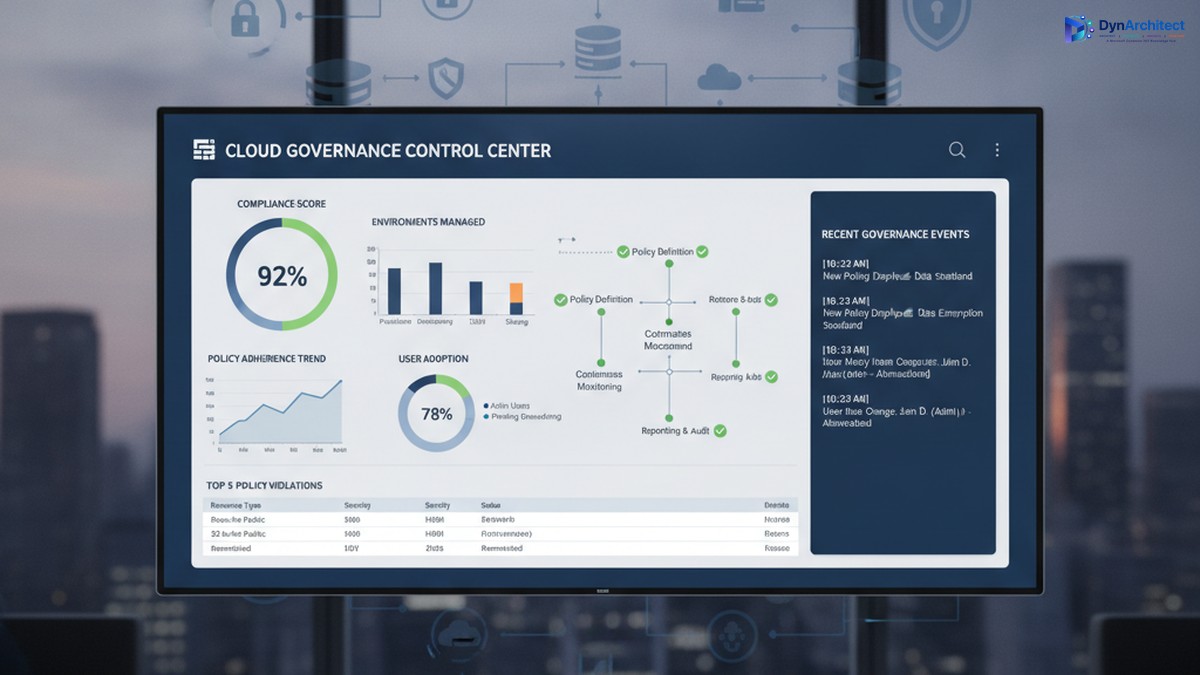
Enterprise cloud governance dashboard showing compliance metrics and governance control center

Building a Center of Excellence for Microsoft Cloud Governance: Establishing Control Without Stalling Innovation

The gap between Microsoft cloud adoption and cloud governance is widening. A CIO with three Power Platform environments deployed across finance, sales, and operations discovers, too late, that each environment has evolved its own authentication rules, data retention policies, and integration patterns. Consolidating them would disrupt active projects. Adding governance now feels like putting handcuffs on people who finally have the tools they need to move fast.

This tension is real, and it is solvable, but it requires a deliberate governance structure: a Center of Excellence (CoE). The purpose of a CoE is not to slow adoption or enforce rigid rules; it is to embed governance into the adoption process itself so that teams can move fast, safely, and with full visibility to leadership.

The Cost of Ungoverned Adoption

When organizations begin adopting Microsoft cloud services, Power Platform, Dynamics 365, Azure, Dataverse, adoption typically starts in one department or use case. A finance team builds a Power App to automate invoice processing. A field service team creates automations to dispatch technicians. Marketing builds a model-driven app to track campaigns. Each team solves a real problem immediately, with minimal delay.

Enterprise cloud governance dashboard showing compliance metrics and governance control center

The problem emerges months later, when three separate environments exist, each configured differently, each with its own data security settings, its own API connectors, and its own integration patterns. A security incident in one triggers questions about the others. A new compliance requirement (data residency, audit logging, export restrictions) means reconfiguring three environments instead of one. A developer leaves, and no one knows what custom logic lives inside automations in that environment. A connector expires, breaking integrations that no one is monitoring centrally.

The cost is not just technical debt. It includes regulatory risk (audit readiness, compliance violations), security risk (data exposure, unauthorized access), operational risk (outages affecting dependent business processes), and financial risk (unused licenses, redundant infrastructure, uncontrolled connector costs). For a mid-market organization, this hidden cost often runs to hundreds of thousands of dollars annually.

Governance after deployment is expensive and disruptive. Retrofitting compliance into three mature environments forces teams to rebuild their solutions or abandon them. Governance before deployment is far cheaper, but it requires structure and clarity on day one.

What a Center of Excellence Is (and Is Not)

A Center of Excellence is a team, function, or governance body responsible for establishing standards, providing guidance, and enforcing policies that keep cloud adoption secure, compliant, and architecturally sound. In the context of Microsoft cloud, a CoE typically has five core responsibilities:

IT leaders and cloud architects collaborating on governance and compliance framework planning

First, it establishes platform standards: which cloud services are approved for use, which are pilot-only, and which are off-limits; which authentication methods are mandatory; how data classification and sensitivity levels map to environments; where connectors can and cannot be used; which compliance frameworks apply (HIPAA, SOC2, PCI DSS, local data residency rules); and how disaster recovery and backup policies are configured.

Second, it onboards new teams and projects by providing reference architectures, reusable templates, and guidance so that new adopters do not have to invent their own governance solutions. A template might be a pre-configured Power Apps environment with the correct security role structure, DLP policies in place, and example connectors already approved and tested.

Third, it monitors ongoing usage and health. This includes license optimization (identifying unused environments and consolidating them), connector audits (catching deprecated or unapproved integrations), security scanning (checking for data exposure and overpermissioned roles), and performance monitoring (identifying resource-intensive automations that need optimization).

Fourth, it provides a feedback loop and governance review process. Teams that encounter a genuine need for a capability that current governance prohibits should be able to propose an exception, and the CoE should evaluate it against risk and organizational goals rather than simply saying no.

Fifth, it acts as an internal consulting function, helping teams plan migrations, optimize environments, troubleshoot problems, and adopt new capabilities safely.

What a CoE is not: it is not a gate that delays innovation. It is not a compliance police force that exists only to say no. It is not a one-person function managed as a side project by someone already stretched thin. These are common failure modes.

Establishing a Governance Foundation

A successful CoE begins with three foundational decisions.

First, secure executive sponsorship and clear governance scope. The CoE needs budget, staffing, and decision-making authority that comes from leadership. Without it, the CoE is a suggestion, not a standard. The scope should define: which Microsoft services the CoE governs (Power Platform, Dynamics 365, Dataverse, Azure, or all of the above); which organizational units must comply (divisions, departments, teams); and what governance decisions the CoE makes directly versus decisions it escalates.

Second, define governance principles that balance control with velocity. A principle might be: “Low-risk, read-only integrations can be self-service and pre-approved; integrations that modify business data require architecture review and security sign-off, but should be approved within two business days, not two weeks.” This principle gives teams clarity on what they can do immediately and what requires review, and it commits the CoE to a review timeline so governance does not become an indefinite bottleneck.

Third, build the governance infrastructure: identify which tools provide visibility and enforcement. This typically includes the Power Platform admin center (for environment management, DLP policies, and connector audits), Azure AD (for identity and access management), Microsoft Purview (for compliance and data governance), and possibly a custom CoE tracker (a Power Apps or Power BI dashboard that centralizes governance data across these tools and makes it visible to team leads and IT leadership).

Staffing and Operating a CoE

A CoE typically starts with a lead (dedicated, not a side project), supported by domain specialists: a Power Platform architect, a Dynamics 365 architect if applicable, a security engineer, and a compliance or risk specialist. For a mid-market organization, this might be three to five people. The CoE lead reports to the CIO or Chief Technology Officer and has direct access to business unit leaders.

The CoE should operate with a clear calendar: environment governance reviews happen monthly, new environment requests are triaged weekly, exception requests are evaluated within two business days, and a quarterly governance review presents data to leadership on usage, compliance status, security incidents, and license optimization opportunities.

Communication is essential. The CoE should publish governance policies in writing (not passed down verbally), maintain a knowledge base with FAQ and troubleshooting guidance, hold a monthly town hall for team leads to learn about new capabilities and governance changes, and send monthly status reports to IT leadership so adoption and governance metrics are visible.

Moving Forward: Quick Wins and Sustained Governance

A CoE need not be perfect from day one. An effective starting point is: document the current state of all cloud environments, establish a data classification standard and assign environments to classification levels, implement DLP policies in Power Platform to prevent data exfiltration, establish environment naming conventions and assign owners, and conduct a security audit to identify and remediate any immediate risks.

Longer-term, invest in automation: automated provisioning of new environments with governance policies pre-applied, automated security scanning and compliance audits, and automated license optimization recommendations. These investments pay off quickly through reduced manual work and faster compliance cycles.

The goal is not perfection. The goal is control: knowing what is deployed, who owns it, what data it contains, and whether it complies with organizational standards. Teams that have this clarity can innovate faster and with less risk, not slower.

Conclusion

A Center of Excellence is how organizations scale cloud adoption from experimental to strategic. It is not governance for governance’s sake; it is governance that removes risk so teams can move confidently. Building one requires executive commitment, clear principles, and sustained staffing, but the return comes quickly in reduced security incidents, faster compliance cycles, and more predictable project outcomes.

At Routeget Technologies, we have built and operated CoE functions for dozens of mid-market and enterprise organizations. We know what works: clear policies, strong automation, and leadership that understands that governance and innovation are not in conflict, they are prerequisites for each other.


#CenterOfExcellence #CloudGovernance #MicrosoftCloud #PowerPlatform #DLP #DataGovernance #ComplianceAutomation #CloudArchitecture #EnterpriseGovernance #DigitalTransformation

Hashtags: #CenterOfExcellence #CloudGovernance #MicrosoftCloud #PowerPlatform #DataGovernance #ComplianceAutomation #CloudArchitecture #EnterpriseGovernance #DigitalTransformation

AI-Powered Sales Forecasting in Dynamics 365 Sales: From Historical Data to Predictive Revenue Planning

The Forecast Nobody Trusts

Sales forecasts in enterprise organizations have a credibility problem. Sales leadership submits a forecast one month, management adjusts it downward out of habit, and by quarter-end everyone discovers that actual pipeline and close rates bore no resemblance to either number. The problem is not salespeople lying or poor spreadsheet discipline. It is that traditional forecasting relies on human judgment applied to datasets too large and complex for human pattern recognition to work reliably.

Dynamics 365 Sales with integrated AI and analytics capabilities changes this dynamic fundamentally. Rather than asking managers to estimate close rates and deal velocity based on their gut feel, organizations can build forecasts on the same historical data that actually predicts outcomes: past deal size, industry, pipeline velocity, sales rep experience, deal characteristics, and seasonal patterns. The result is not perfect, but it is consistently more accurate than traditional methods, and it gives sales leadership a fact-based foundation for revenue conversations with finance rather than negotiated guesses.

How Predictive Sales Analytics Work in Dynamics 365

Dynamics 365 Sales Premium includes a suite of analytics capabilities that power forecasting without requiring advanced data science skills or external platforms. The system automatically ingests data from opportunity records, activities, customer accounts, and deal attributes, then uses machine learning to identify the patterns that correlate with closed wins, lost deals, and extended cycles.

For an organization selling enterprise software with typical sales cycles of six to nine months, the system learns that deals from specific industries have different close rates, that proposals sent in month two (as opposed to month four) have higher win probability, and that opportunities touching more buying committee contacts are more likely to close. These patterns are statistically significant but often invisible to human judgment operating over dozens or hundreds of deals simultaneously.

The forecasting engine generates a confidence score for each opportunity: a prediction of the probability that deal will close within the target quarter. Rather than replacing the salesperson’s forecast with an algorithm, Dynamics 365 surfaces these predictions as a recommendation layer, allowing sales managers to keep the deal in forecast if they believe factors not in the data justify it, or to flag deals where the algorithm’s assessment contradicts the sales rep’s estimate. In practice, deals the system rates as low-probability but the rep insists will close become visible decision points, and forecasts weighted by these probabilities prove more accurate than unadjusted rep estimates.

Moving from Monthly Submissions to Continuous Intelligence

Traditional sales forecasting operates on a monthly or quarterly cadence. Sales leaders call a forecast meeting, reps submit their estimates, managers apply adjustments, and the number goes to finance. Three weeks later, when actual deals close or new opportunities surface, the forecast is already outdated.

AI-driven forecasting in Dynamics 365 Sales operates continuously. As pipeline changes, deal characteristics evolve, and close dates shift, the system recalculates probability scores in real time. Sales leadership can check accuracy at any point in the quarter rather than waiting for the official review, and can identify where actual progress is diverging from forecast early enough to adjust strategy or pipeline development.

This shift from periodic submission to continuous intelligence has operational consequences. Sales managers no longer spend two days in forecast-call meetings; instead they spend fifteen minutes reviewing a dashboard that shows which deals are tracking as expected and which have shifted risk status. Finance gets a more current picture of expected revenue. And sales reps see their opportunities scored fairly against consistent criteria rather than subject to manager judgment that varies month to month.

Building Revenue Predictability Across Market Segments

One of the highest-value uses of predictive sales analytics is building segment-specific forecast models. An organization selling both managed services and perpetual licenses may discover that customers purchasing managed services have a seventy-percent close rate while perpetual license deals close at forty-five percent, and that rep tenure affects close rates only for managed services, not perpetual deals. Once these segment-specific patterns are identified, forecasts weighted by segment become far more accurate than a single organization-wide model.

Organizations with international operations benefit further, as the system can identify which regions have different sales dynamics. A deal structure that works reliably in North America may have lower success in Asia Pacific due to buying patterns or competitive dynamics, and a forecast that does not account for that regional signal will consistently overshoot certain markets and undershoot others.

Building these segment models requires data discipline (opportunity fields must be filled consistently, sales stages must be defined clearly), but once that foundation is in place, the system automatically detects and incorporates segment-specific patterns. Sales organizations that have historically managed separate forecast models for different markets often find they can consolidate to a single system with segment-driven weightings, reducing forecast maintenance overhead while improving overall accuracy.

Common Implementation Mistakes

Organizations implementing AI-driven forecasting in Dynamics 365 Sales often make three systematic mistakes. First, they attempt to train the model on too little historical data. If the system only has two quarters of opportunity records, it cannot detect patterns that matter for a deal type with an eighteen-month cycle. Second, they do not invest in data quality upstream. If opportunity records lack consistent stage definitions, industry classifications, or customer size information, the model has no signal to work with. Third, they present the AI forecast as a replacement for human judgment rather than as a tool that surfaces patterns human judgment can integrate. Sales organizations that frame the system as “the computer will tell you who to trust” face adoption resistance; those that frame it as “the system flags patterns you should investigate” see adoption and engagement.

Next Steps for Sales Leadership

For organizations already using Dynamics 365 Sales, enabling predictive analytics is typically a configuration matter rather than a deployment project. Assess your historical opportunity data to confirm you have at least four quarters available and that field completion rates are reasonable. Review your sales stage definitions to ensure they are consistent with how deals actually progress. Then enable the analytics features and begin building segment-specific forecast models based on your business lines.

For organizations evaluating Dynamics 365 Sales or planning major system migrations, AI-driven forecasting should be part of the evaluation criteria. Whether your organization benefits from this capability depends on your sales model, your forecast accuracy needs, and your data discipline, but for enterprises where forecast accuracy directly affects financial planning and capital allocation, predictive sales analytics often justify the platform investment on their own.

The Forecast Everyone Uses

The strategic value of AI-driven forecasting extends beyond raw accuracy. When sales leadership and finance can trust a forecast because it is grounded in historical data rather than negotiation, conversations shift. Instead of debating the number, the conversation becomes, “What actions should we take to shift close rates or deal velocity?” Sales and finance become partners in building pipeline rather than adversaries in a forecast negotiation.

Dynamics 365 Sales with integrated AI analytics makes this shift possible. For sales organizations ready to move beyond spreadsheet-based forecasting, the capability is available today.


About Routeget Technologies: Routeget Technologies helps mid-market and enterprise organizations implement and optimize Dynamics 365 Sales, enabling teams to improve forecast accuracy, streamline pipeline management, and drive predictable revenue growth through data-driven sales practices.

#SalesForecastingAI #DynamicsSalesAnalytics #SalesRevenuePlanning #PredictiveAnalyticsD365 #SalesLeadership #EnterpriseAI #DynamicsSales

Business Central Inventory Valuation Methods: Why FIFO, LIFO, and Weighted Average Choices Reshape Working Capital and Tax Liability

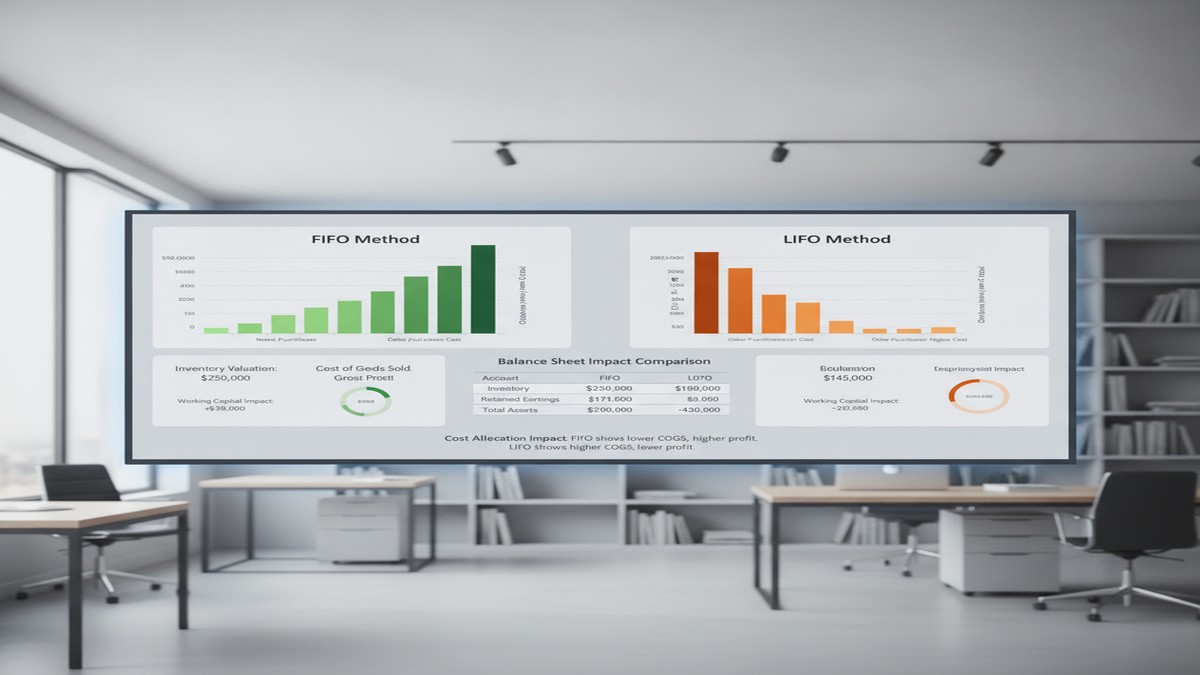
Business Central inventory costing methods FIFO vs LIFO comparison

When most finance teams implement Business Central, inventory costing defaults to FIFO. It’s the system default, it feels familiar, and no one on the implementation team flags it as a strategic decision. Then, 18 months into production, the conversation happens in the CFO’s office: your inventory balance sheet valuation has drifted significantly from what your tax accountant expected, your working capital metrics look different than they did under your legacy system, and your auditors are asking uncomfortable questions about whether the method you’re using actually aligns with your declared accounting policy.

This scenario repeats across organizations that underestimate the costing method decision as a finance strategy choice rather than a technical configuration. The truth is that your selection of FIFO, LIFO, weighted average, standard, or specific costing in Business Central ripples through your financial statements, your tax position, your working capital calculation, and your audit trail in ways that matter far more than most implementation teams realize.

## Why the Costing Method Choice Actually Matters to the Bottom Line

Business Central’s inventory costing method determines which purchase prices flow into your cost of goods sold and which prices remain sitting in inventory on your balance sheet. This distinction seems technical, but the financial impact is substantial. When prices rise, different costing methods produce radically different results: one method increases your reported profits and tax liability, another decreases both, and a third lands somewhere in between. The method you choose today locks in a path for your working capital metrics, your borrowing capacity, and your tax strategy for years to come.

Beyond the numbers, the costing method choice also determines how flexibly you can adjust costs after posting, whether you can back-date transactions without recalculating everything downstream, and how much discipline you need from your inventory and purchasing teams to keep the GL in sync with your ledger. Some methods are forgiving when you discover a $5,000 invoice weeks after posting; others force you to recalculate thousands of ledger entries and reconcile your entire inventory GL account.

## FIFO: The Default That Often Feels Wrong Under Inflation

First-In, First-Out assumes that the oldest items purchased are the first ones sold. When prices are stable or declining, FIFO produces intuitive results. When prices rise, FIFO increases your reported inventory value and profits, which sounds good until tax day arrives and your tax liability rises with it. In an inflationary environment, FIFO inflates your balance sheet. Your inventory looks more valuable, which helps you approach lenders and improves your current ratio. Your cost of goods sold stays lower, making gross margins look better. But your reported profit grows, and so does your tax bill.

FIFO is also straightforward to reconcile. Business Central tracks which purchase transactions were consumed in which sales, so tracing cost flows back to specific purchase invoices is relatively transparent. If you discover a cost error in a purchase invoice, you can correct it without triggering a cascade of recalculations across the entire inventory GL. These operational benefits make FIFO the path of least resistance for many finance teams.

The constraint worth noting: once you set an item to FIFO in Business Central, you cannot change to a different costing method if any ledger entries exist for that item. This lock-in effect means your initial FIFO choice is likely permanent for years, even if business conditions shift.

## LIFO: The Tax Advantage with Regulatory Complications

Last-In, First-Out assumes that the most recently purchased items are sold first, which produces the opposite financial effect of FIFO. In an inflationary environment, LIFO decreases your reported profits and tax liability, which is why LIFO became popular during high-inflation eras as a way to reduce tax burden. Your cost of goods sold rises faster, your gross margin shrinks on paper, and your reported profit falls, which lowers your tax bill.

The catch is significant: LIFO is disallowed in many countries and regions outside the United States. If your organization operates internationally or plans to expand outside the US, LIFO creates compliance complications and audit friction. Some jurisdictions view LIFO as a method that artificially depresses profit, and regulators restrict or disallow its use entirely. For this reason, LIFO is increasingly rare in global organizations, even though it retains tax appeal in the US market.

## Weighted Average: The Middle Ground for Volatile Costs

Weighted average costing calculates a single average unit cost at a defined interval (daily, weekly, monthly, quarterly, or per accounting period). Every item consumed during that period uses the same average cost. This method produces results that fall between FIFO and LIFO, making it a reasonable choice when your product costs are volatile or you have mixed, homogeneous inventory such as chemicals, raw materials, or commodities where tracing individual purchase costs to specific sales is impractical.

The operational trade-off with weighted average is important: if you back-date a transaction, Business Central must recalculate all affected ledger entries and inventory GL entries within that averaging period. A single invoice correction that appears weeks after posting can trigger a recalculation wave that touches hundreds of inventory transactions. This recalculation risk makes weighted average less attractive in environments where posting errors surface late or where regular transaction corrections are common.

## The Real Decision Framework: What Finance Leaders Should Actually Evaluate

Selecting your costing method should be driven by three distinct questions, not by which method your legacy system used or which option appears first in the setup wizard.

First, what is your product cost environment? If product costs are stable or predictable, FIFO is operationally clean. If your costs are volatile and inventory is homogeneous, weighted average is more defensible. For highly valued, easily identifiable items, specific costing gives you exact cost tracking.

Second, what is your tax and financial reporting strategy? If you want to minimize tax liability in an inflationary environment, LIFO appeals. If you want to maximize reported profits and borrowing capacity, FIFO serves that goal. If you want a neutral middle ground that doesn’t swing too far either direction, weighted average is stable. This decision is not a technical question; it is a finance strategy question that should involve your tax accountant and CFO.

Third, what are your regulatory and audit constraints? If you operate globally, LIFO creates complications. If your auditors have strong opinions about industry-standard methods, align with those expectations upfront. If your working capital and cash flow metrics are tightly monitored by lenders, verify that your costing method choice aligns with debt covenant calculations.

Once these three questions are answered, the technical choice becomes clear.

## Common Mistakes That Surface After Cutover

Finance teams frequently discover problems with their costing method choice only after cutover has been running for months. One common mistake is defaulting to FIFO because the implementation team knew no better, then realizing too late that your tax strategy would have favored weighted average or that your auditor expected a different method. Another frequent issue is underestimating the back-dating problem with weighted average, only to discover months later that regular cost corrections trigger massive recalculation waves that destabilize your GL.

A third mistake is failing to ensure that your Dynamics purchasing and inventory teams understand the costing method you selected. If your team does not know that you have chosen LIFO, for example, they may manage inventory in a way that contradicts LIFO’s assumptions, making your GL reconciliation substantially harder and your audit trail less defensible.

## Resetting the Choice Requires Planning

If you discover six months after cutover that you selected the wrong costing method, reversing the decision is expensive and disruptive. The technical constraint is absolute: you cannot change an item’s costing method if ledger entries exist. Resetting requires either creating new item numbers and migrating open inventory to those new items, or conducting a full inventory revaluation and GL restatement. Both paths are operationally messy and often require auditor involvement to ensure the transition is defensible.

For this reason, getting the choice right upfront is worth the investment of time and expert input before cutover.

## The Real Impact: Working Capital and Strategic Positioning

The costing method you choose in Business Central is not a technical detail to delegate to the implementation team; it is a financial strategy decision that affects your reported working capital, your tax position, and your balance sheet strength for years to come. FIFO inflates your inventory value and profits during inflation, making your balance sheet look stronger to lenders but increasing your tax bill. Weighted average cushions you against cost volatility but exposes you to recalculation risk. LIFO minimizes taxes but creates regulatory complications.

Organizations that treat the costing method choice as a strategic decision, led by their CFO and tax accountant rather than by the technical implementation team, avoid costly reversals after cutover and build a Business Central GL that supports their actual financial and tax strategy. Routeget Technologies helps finance and operations teams make this strategic choice before implementation, ensuring that your Business Central configuration aligns with your working capital goals and tax objectives from day one.

The choice you make now will shape your financial statements for years. Make it deliberately.

—

#BusinessCentralInventory #InventoryCosting #WorkingCapital #BusinessCentralFinance #FIFOvLIFO #CFOStrategy #DynamicsFinanceOps #FinancialAccounting #CostAccounting #BusinessCentralCore

Finance team analyzing Business Central inventory valuation in office

About Routeget Technologies: Routeget Technologies is a Microsoft Dynamics consulting firm helping enterprise and mid-market organizations implement, optimize, and extend their Microsoft technology investments. Our teams combine deep technical expertise with business advisory experience to deliver implementations that drive operational efficiency and financial impact.

Field-Level Security in Dataverse: Building Role-Based Permission Models That Scale

Dataverse field-level security and role-based access control dashboard

The Hidden Complexity of Dataverse Permission Models

Most Dataverse implementations begin with a straightforward role hierarchy: sales users get access to leads and opportunities, finance teams see accounts and invoices, support staff manage cases and contacts. But as your organization grows, the model breaks down. You accumulate teams with overlapping responsibilities, regions with different compliance requirements, and sensitive columns that only executives should see. The role count multiplies. Users end up in seven or eight roles just to get the right combination of privileges. Column-level security requests pile up with no clean way to grant access to one field without exposing others. This is where field-level security enters not as a bolt-on convenience, but as a structural necessity.

Understanding Dataverse Security Layers

Dataverse provides three distinct permission layers, and confusing their purposes is a common design mistake. Row-level security controls which records a user can view or modify. It operates at the record level and relies on ownership, team membership, or hierarchical queries over business unit relationships. Role-based privilege sets determine what actions a user can perform (create, read, update, delete, assign) and on which tables or attributes they can perform them. These are coarse-grained controls; a role grants update access to an entire table, not to specific columns within it. Field-level security fills the gap between these two layers. It restricts access to specific columns for users who hold particular security roles or field security profiles. A user might have full update access to an account record through their role privileges, but field-level security can prevent them from viewing or editing the account’s annual revenue or credit rating fields.

Understanding this hierarchy is crucial for design. Many organizations try to solve field-level problems by creating more roles or narrowing table privileges. The result is role bloat that becomes impossible to audit or maintain. Field-level security, by contrast, keeps the role structure lean while providing precise column-level control.

Designing Scalable Field-Level Security Profiles

The technical foundation of FLS in Dataverse is the field-level security profile. Each profile specifies which columns a user can read or write. Multiple profiles can be assigned to the same user, and they combine additively: if one profile grants read access to a column and another grants write access, the user can write. Profiles are assigned through user records, not through roles, which is a critical design distinction. A user’s role determines their overall table and action privileges. Their field-level security profiles refine that access to specific columns.

Effective field-level security design starts with an inventory of columns that require restricted access. Columns typically fall into tiers: public columns that everyone in the organization can see (account name, contact details), internal columns that only certain roles should access (cost structure, internal notes), and restricted columns that require executive-level or compliance-driven access (personal identifiers, audit flags, regulatory fields). Once you have this inventory, you design profiles that correspond to job functions or organizational units. Instead of a profile per user or role, create a smaller set of reusable profiles that can be applied broadly. For example, you might have a “Finance Manager” profile that grants access to cost and revenue columns, a “Support Specialist” profile that blocks access to pricing and margin data, and an “Executive” profile that includes all columns except those marked as not-for-distribution. Users then receive the profiles they need to do their jobs, often in combination.

Common Implementation Pitfalls and Performance Implications

Most field-level security failures stem from three mistakes. First, overpermissive profiles that grant access to columns without a clear business justification. A single broad profile defeats the purpose of FLS and creates audit risk. Second, inconsistently applied profiles: some users have field restrictions while others with similar roles do not, creating data access inconsistency that auditors and compliance teams discover during reviews. Third, forgetting that field-level security does not prevent access through APIs, mobile clients, or integrations. A user might be blocked from viewing a column in the web UI, but if your Power Automate flow or plug-in runs as that user, the flow can still read and modify the column. Restricting API-level access requires separate configuration in custom connectors and API permissions.

Performance implications are often overlooked. Field-level security adds overhead to queries, especially when many profiles are assigned to a user or when profiles access overlapping sets of columns on large tables. Microsoft’s telemetry shows measurable latency increases on tables with thousands of records and highly granular field-level security configurations. The impact is usually minor for interactive workloads but can become significant in batch operations or bulk imports. Test thoroughly with realistic data volumes before deploying complex FLS configurations to production.

Integration with Azure Active Directory and Role Mapping

In many organizations, field-level security profiles should map to Azure AD groups or job roles defined in your identity management system. If your organization maintains Azure AD groups for finance staff, support teams, and executives, you can automate field-level security profile assignment through Power Automate or Azure Logic Apps when users are provisioned or change roles. This prevents manual profile assignment from becoming a maintenance bottleneck. The automation also ensures that when a user moves to a different department, they gain access to the columns required for their new role and lose access to columns they no longer need.

Be cautious about assigning profiles in bulk based on role names. If an Azure AD group includes contractors or external partners in addition to full-time employees, those contractors inherit the field-level security profile along with everyone else. Audit your group memberships before automating profile assignment, and maintain a separate security group or naming convention for profiles that should apply only to internal staff.

Testing, Auditing, and Migration Strategies

Effective field-level security requires testing at both the feature level and the integration level. At the feature level, verify that users assigned to a profile cannot query, read, or update restricted columns, either through the UI or through API calls. Use test accounts assigned to each profile to validate access. At the integration level, test that your automated role mapping and profile assignment work correctly when users are added, removed, or moved between groups. A common failure point is assuming that removing a user from an Azure AD group automatically removes their field-level security profiles; depending on your automation, it may not. Build automated tests that validate both positive cases (users who should have access do) and negative cases (users who should not have access don’t).

Auditing field-level security requires capturing field access attempts, particularly for sensitive columns. Enable plug-in tracing for custom connectors and use built-in Power Platform security audit logs to review who accessed which columns and when. Tools like the Center of Excellence (CoE) starter kit include reports that surface inactive field-level security profiles, which can be candidates for removal.

If you are retrofitting field-level security into a mature system where users already have broad column access, plan a phased migration. Begin with read-only restrictions on the most sensitive columns: executives and finance staff can read certain fields, but no one can modify them outside of specific processes. Gradually restrict write access, and monitor user behavior to catch legitimate use cases that your initial FLS model did not account for. Communicate clearly with teams before restricting access so they understand the why and can flag business processes that would break under the new model.

Building for the Long Term

Field-level security in Dataverse is not a one-time implementation. As your organization evolves, columns that were once public may become sensitive, and sensitive columns may need broader access. Design your profiles to be maintainable: document which profiles are in use, which columns each profile restricts, and why those restrictions exist. Periodically review profiles against your current data governance policies and remove or consolidate profiles that have become redundant. Organizations that treat FLS as an afterthought find themselves managing dozens of overlapping profiles within a few years. Organizations that treat it as an intentional governance mechanism maintain clear, auditable permission models that survive organizational change.

DynArchitect helps organizations design and implement scalable enterprise technology solutions, including Dataverse governance, security architecture, and role-based access control strategies that grow with your business.

#DataverseSecurity #FieldLevelSecurity #DataverseGovernance #PowerPlatformSecurity #RoleBasedAccessControl #DataversePermissions #CloudArchitecture

Building Custom APIs in Business Central: A Developer’s Guide to Extending Integration Capabilities

Developer workspace with multiple monitors showing AL code and API documentation

# Building Custom APIs in Business Central: A Developer’s Guide to Extending Integration Capabilities

Business Central’s Power Automate connector and standard OData endpoints cover a wide range of integration needs. For a mid-market company syncing a handful of cloud services, these out-of-the-box capabilities are often sufficient. But the moment you need to expose Business Central data to a proprietary third-party system, enforce complex business logic at the API boundary, or build a consistent integration layer that multiple services depend on, you’ll quickly discover the limits of connector-based approaches.

Custom API endpoints in Business Central provide a way out. Unlike the Power Automate connector, which exposes a read-only view of standard entities, custom APIs let you control exactly what data flows into and out of your system, apply authorization rules at the endpoint level, and define the exact REST semantics your downstream systems expect.

Developer workspace with multiple monitors showing AL code and API documentation

## When Standard Connectors Stop Working

The Power Automate connector and OData endpoints both serve important purposes, but they operate under constraints that custom APIs remove. The Power Automate connector simplifies workflow automation by automatically discovering Business Central tables and fields, but this convenience comes with limited flexibility around response formats, pagination, and error handling. OData endpoints provide more control but still expose the underlying data model directly, which means any future schema changes can ripple into dependent systems.

A custom API, by contrast, sits between your Business Central data layer and external systems. It acts as a versioned contract that isolates external consumers from internal schema changes. If you add a field to a table, rename a lookup, or refactor your data structure, the API’s public interface remains stable as long as the underlying business logic does.

Cloud architecture diagram showing API gateway with multiple integrated systems

## Building Your First Custom API in AL

In Business Central, custom APIs are built using AL, the business application language. The core construct is an API page, which combines the declarative benefits of page design with REST exposure. Here’s the basic pattern:

A custom API page declaration specifies an entity name, which becomes the REST resource path (/api/custom/v1/orders, for example), and then maps AL fields to the underlying Business Central tables. Unlike a traditional page, which is designed for user interaction, an API page focuses on data structure and response shape.

“`
page 50100 OrderAPI
{
PageType = API;
EntityName = ‘Order’;
EntitySetName = ‘Orders’;
…
}
“`

From this declaration, Business Central automatically exposes a REST endpoint. A POST request creates a record, GET retrieves records, PATCH updates, and DELETE removes records, following standard HTTP semantics.

## Controlling the Request Surface

One of the key advantages of building custom APIs is control over the data you expose. You’re not forced to expose every field on a table. Instead, you explicitly declare which fields appear in the API, rename them if needed for compatibility, and define read-only vs. read-write properties.

This becomes essential when integrating with legacy systems or third-party services that expect a specific data structure. If your external partner’s API expects a field called `CustomerOrderID` but Business Central calls it `BillToCustomerNo`, the custom API layer translates between them. This translation insulates both systems from breaking changes on the other side.

Equally important is the ability to hide internal details. Not every field a Business Central user needs to see belongs in an external API. You can expose only order headers, hide internal cost allocations, and require that all modifications go through specific validation routines your custom API enforces.

## Authentication and Authorization at the API Level

All Business Central APIs, custom or standard, authenticate via Azure AD (Entra ID) OAuth. Your calling system requests a token using a service principal or delegated credentials, and Business Central validates the token before allowing access to the API.

However, custom APIs let you layer additional authorization logic on top of Azure AD authentication. You might check that the caller’s organization ID matches the data they’re requesting, or enforce that only a specific external system can modify orders within certain value ranges.

This can be implemented in the page’s trigger code, before any data is returned or modified:

The API code can inspect the authenticated caller’s identity, query Business Central tables to determine if access is allowed, and reject the request with a specific HTTP status and error message if not.

## Versioning Your API Without Breaking Clients

Over time, your API contract will evolve. You’ll add new fields, deprecate old ones, or change the structure of nested objects. Custom APIs handle this through explicit versioning.

The standard approach is to include a version number in the API path itself: `/api/custom/v1/orders` vs. `/api/custom/v2/orders`. This allows you to support legacy clients on the v1 endpoint while new clients use v2. You might even run both endpoints simultaneously, pointing v1 to an older page definition and v2 to an updated one, ensuring that existing integrations don’t break.

Alternatively, you can deprecate individual fields by keeping them in the response but marking them in documentation as no longer updated. This gives calling systems time to migrate to newer fields before you remove them entirely.

## Testing and Monitoring Your Custom API

A custom API is only as good as its reliability in production. Before deploying to a live environment, test the API endpoints thoroughly using tools like Postman or custom scripts that simulate your downstream systems. Verify that create, read, update, and delete operations all work as expected, that error responses include meaningful messages, and that rate limits and timeouts behave predictably.

Once deployed, monitor the API’s health through Business Central’s telemetry and logging infrastructure. Log each API call with caller identity, HTTP status, and execution time, so you can diagnose performance issues or unexpected errors after the fact. If an external system starts making requests at an unusual rate or fails repeatedly, your logs will reveal it quickly.

## A Practical Example: Order Sync Between Business Central and an ERP Partner

Consider a scenario where your organization uses Business Central as the primary system of record for financial data, but integrations with a warehouse management system (WMS) require real-time updates whenever an order ships. A custom Order API exposes the minimum fields the WMS needs: order number, line items, quantities, and ship-to address.

The API page includes trigger code that, on insert or modify, validates that quantities are non-negative, ship-to addresses are complete, and the order type is supported by the WMS integration. If validation fails, the API returns a 400 error with a message explaining what was missing or invalid. This prevents the WMS from receiving half-formed orders that it cannot process.

When the order is ready to ship, the WMS sends a PATCH request to the same endpoint with shipping carrier and tracking information. The custom API updates Business Central with those details, logs the update for audit purposes, and returns a 200 response confirming success.

## Common Pitfalls to Avoid

One frequent mistake is exposing too much data in a single API endpoint. A page that joins ten tables and returns dozens of fields might seem comprehensive, but it becomes slow, difficult to version, and hard to secure. Instead, design lean APIs that return only what the caller needs, and create separate endpoints for different use cases.

Another pitfall is inadequate error handling. If your custom API hits an exception in AL code and doesn’t catch it, the response will be a generic 500 error with a stack trace. External callers have no idea what went wrong. Always wrap business logic in try-catch blocks, translate exceptions into meaningful HTTP status codes (400 for bad requests, 409 for conflicts, 422 for validation failures), and include a human-readable error description.

Finally, don’t overlook throttling. If you don’t set rate limits on your API endpoints, a poorly behaved client or a denial-of-service attack can consume all available Business Central resources. Use Business Central’s built-in throttling policies to cap the number of requests per minute per caller.

## Moving Forward

Custom APIs transform Business Central from a closed system to an extensible platform. They enable you to control the shape of your data, enforce business rules at the boundary, and maintain a stable contract with external systems even as your internal architecture evolves.

If you’re currently wiring integrations together with Power Automate flows and OData endpoints, custom APIs might be the missing piece that gives you the control and clarity your architecture needs. At Routeget Technologies, we’ve helped organizations design and implement custom API strategies that streamline integrations and reduce long-term maintenance burden.

—

**#BusinessCentralAPIs #CustomIntegration #ALDevelopment #BusinessCentralExtensibility #APIDesign #IntegrationArchitecture #DevelopmentPatterns**

#BusinessCentralAPIs #CustomIntegration #ALDevelopment #BusinessCentralExtensibility #APIDesign #IntegrationArchitecture #DevelopmentPatterns